Command Palette
Search for a command to run...
ScienceBuddy: 재귀적 자가 개선을 통한 상호작용형 과학 에이전트
ScienceBuddy: 재귀적 자가 개선을 통한 상호작용형 과학 에이전트
초록
우리는 연구자들의 일상 업무에 지속적으로 개선되는 과학 에이전트를 도입하는 상호작용형 과학 연구 작업 공간인 ScienceBuddy를 소개하고 공개한다. ScienceBuddy는 연구자가 과학적 작업을 수행하는 것을 지원하면서, 그들의 요청, 피드백, 실행 증거를 지속적 학습을 위한 작업 및 평가 루브릭으로 변환한다. 그 핵심에는 재귀-내-재귀 자가 개선(recursive-in-recursive self-improvement)이라는 패러다임이 있으며, 이는 하네스 진화와 모델 강화 학습을 결합한다: 내부 재귀는 모델을 고정한 상태에서 하네스를 개선하고, 외부 재귀는 개선된 하네스 아래에서 모델을 훈련한다. 하네스 진화는 훈련 경험을 형성하고, 모델 학습은 하네스 적응을 위한 새로운 기회를 창출한다. 우리는 네 가지 과학 작업 계열에 걸친 벤치마크 사례를 통해 연구자 상호작용, 하네스 정제, 모델 학습의 사례 연구를 제시한다. ScienceBuddy를 연구 제품으로 공개함으로써, 우리는 이 패러다임을 과학 커뮤니티에 제공하고 연구자와의 지속적인 협력을 통해 발전하며 지원하는 연구와 함께 진화하는 과학 AI인 발견 지능(discovery intelligence)을 향한 한 걸음을 내딛는다.
One-sentence Summary
Researchers from phai-labs introduce ScienceBuddy, an interactive scientific workspace that enables continually improving agents through recursive-in-recursive self-improvement, coupling harness evolution with model reinforcement learning to transform feedback into tasks and evaluation rubrics, with case studies spanning four scientific task families and advancing discovery intelligence.
Key Contributions
- Introduces and releases ScienceBuddy, an interactive scientific research workspace that connects researcher dialogue, executable analysis, inspectable artifacts, and a pluggable harness, making the paradigm available to the scientific community.
- Presents recursive-in-recursive self-improvement, a co-design paradigm coupling evaluated harness evolution with rubric-supervised model reinforcement learning, where the reflector remains fixed to isolate each improvement mechanism.
- Case studies across four scientific task families show harness refinement improves first-response accuracy on feedback-accessible tasks, while model learning expands problem coverage under a fixed harness, with evidence of broader problem coverage and improved task execution.
Introduction
Scientific research relies on iterative analysis, inspection, and revision, and language model agents can support this by retrieving evidence, querying databases, and running computational workflows. However, while correcting answers within a conversation helps individual tasks, it does not systematically improve an agent’s broader procedures or capabilities. Prior work has explored reflection, harness optimization, and interaction-driven adaptation, but these methods typically treat procedural or model learning in isolation, leaving a gap in how collaboration itself can supply the tasks and assessment criteria for coordinated, sustained improvement.
The authors introduce ScienceBuddy, an interactive scientific research workspace that enables continual learning from researcher collaboration. The system separates an editable harness, which organizes behavior through instructions and skills, from the scientific infrastructure, making procedural changes explicit and evaluable. The key contribution is a recursive-in-recursive self-improvement paradigm: an inner loop uses a fixed auxiliary model to diagnose failures and propose bounded edits to procedures, while an outer loop trains the task model on fresh rollouts with rubric-based rewards. This bidirectional coupling allows harness revisions to shape training trajectories and model updates to alter procedure effectiveness, creating a cycle where improved systems return to researchers for further interaction. Case studies across four task families from LAB-Bench and Biomni-Eval demonstrate gains in first-response accuracy and problem coverage, releasing ScienceBuddy as a shared workspace for scientific assistance and capability evolution.
Method
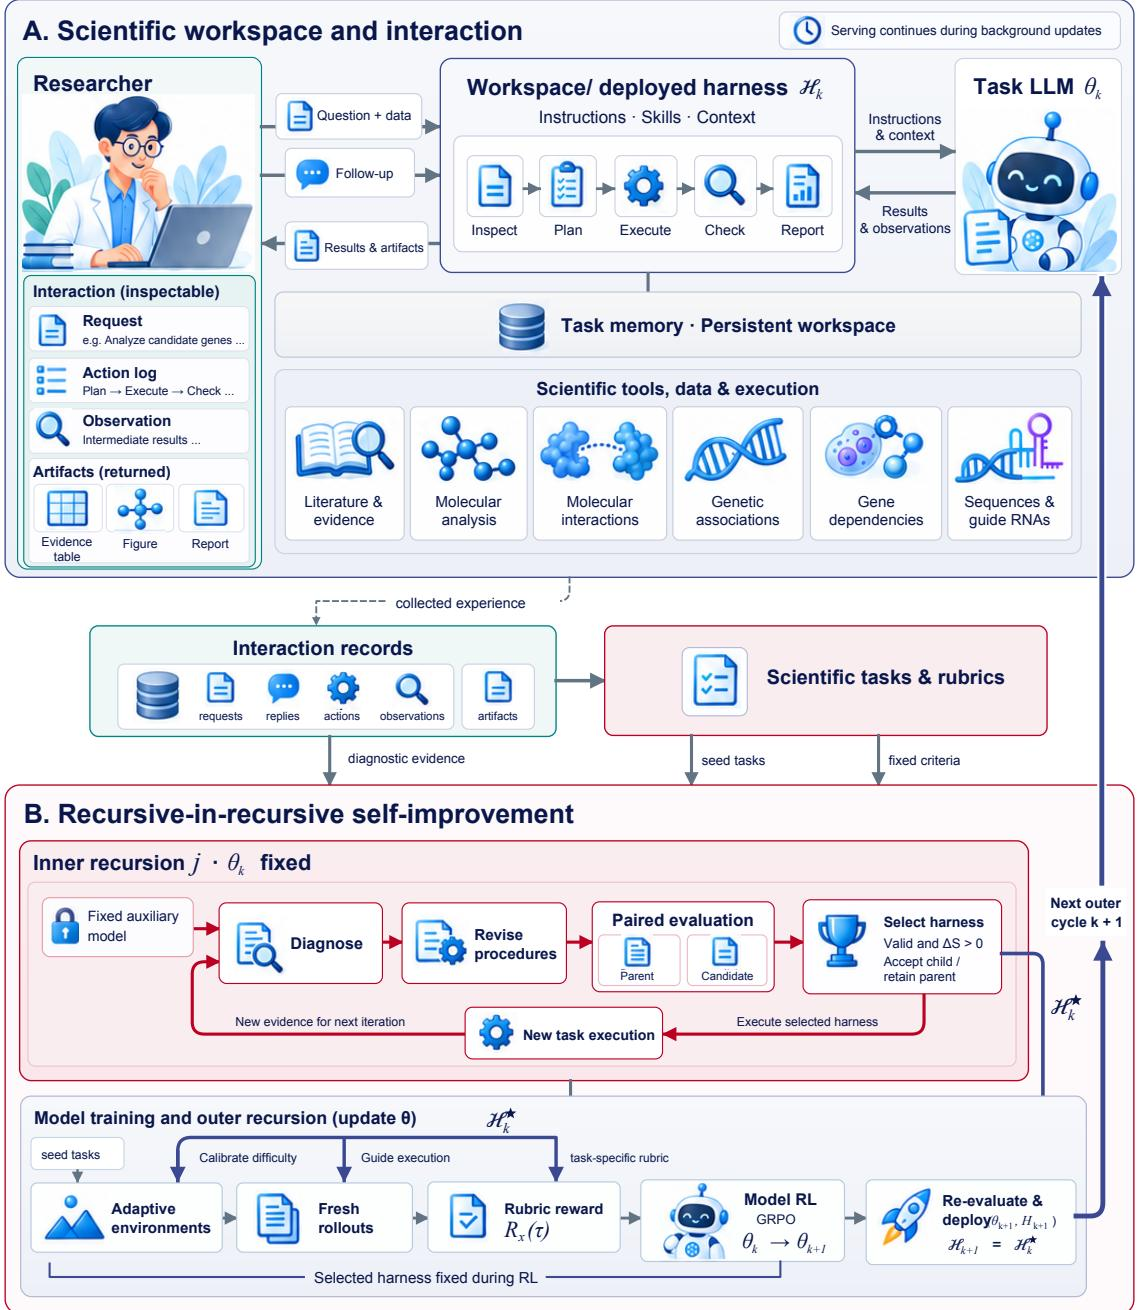
ScienceBuddy functions as an interactive scientific research workspace that integrates evidence access, computational analysis, and methodological guidance into a single conversational workflow. The system architecture separates the agent harness from the underlying infrastructure. The harness manages instructions, skills, and context management procedures, while the infrastructure handles researcher interactions, task execution, and persistent storage. This modularity allows the system to revise scientific problem-solving procedures explicitly while keeping the execution environment consistent.
As shown in the figure below, the workspace supports a recursive-in-recursive self-improvement process. Researchers submit questions and data, which the agent processes through a ReAct-style reasoning loop involving code execution and tool usage. The resulting trajectories and artifacts serve as diagnostic evidence for system updates.
The system formalizes researcher interactions to generate learning signals. Let x denote a research request, πθ the task model, and H the harness. The joint policy μθ,H determines actions at based on the history ht and harness context CH(ht).
μθ,H(a∣ht)={δdH(ht)(a),πθ(a∣CH(ht)),if a harness action is scheduled,otherwise,Collaboration records are transformed into self-contained Harbor tasks and evaluation rubrics. This process consolidates related turns into a scientific objective, deriving criteria for correctness and methodology from the full trajectory rather than relying solely on expert annotation.
Refer to the framework diagram illustrating the task derivation process.
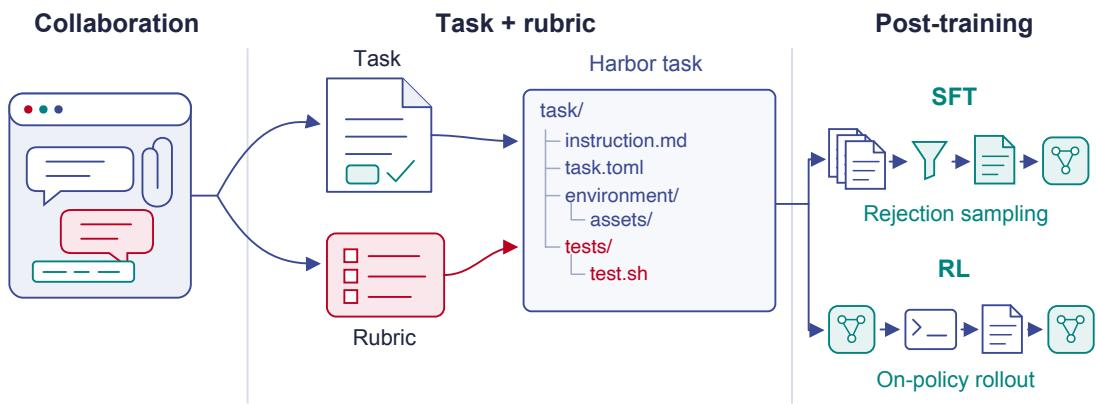
These tasks package instructions, assets, execution environments, and rubrics, supporting both Supervised Fine-Tuning via rejection sampling and Reinforcement Learning via on-policy rollouts.
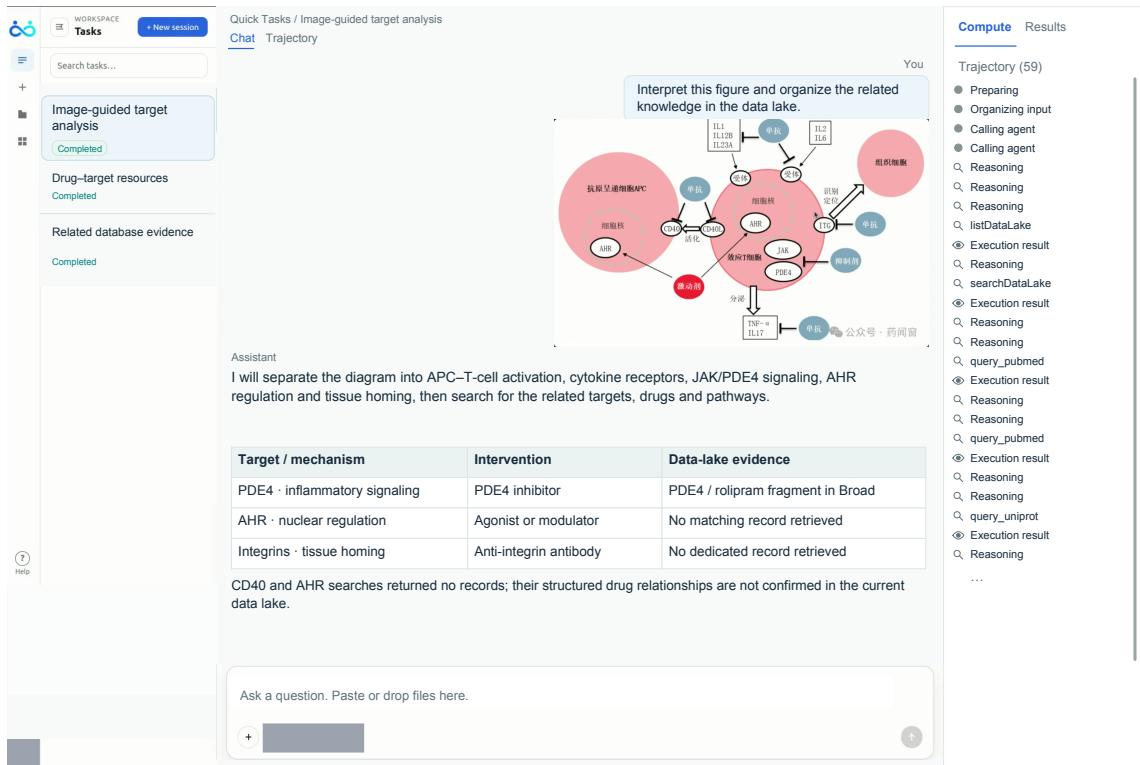
The workspace supports multimodal inputs, allowing researchers to supply documents, biological sequences, and images alongside natural language requests.
As shown in the figure below, an uploaded diagram can guide the identification of molecular targets and the organization of related knowledge, with the interface connecting visual interpretation to structured evidence tables.
The system facilitates long-context agentic reasoning, where successive image-based requests direct target analysis across a continuing session. The agent interprets images through reasoning and retrieval, resuming sessions with prior exchanges available.
Refer to the figure below demonstrating long-context reasoning.
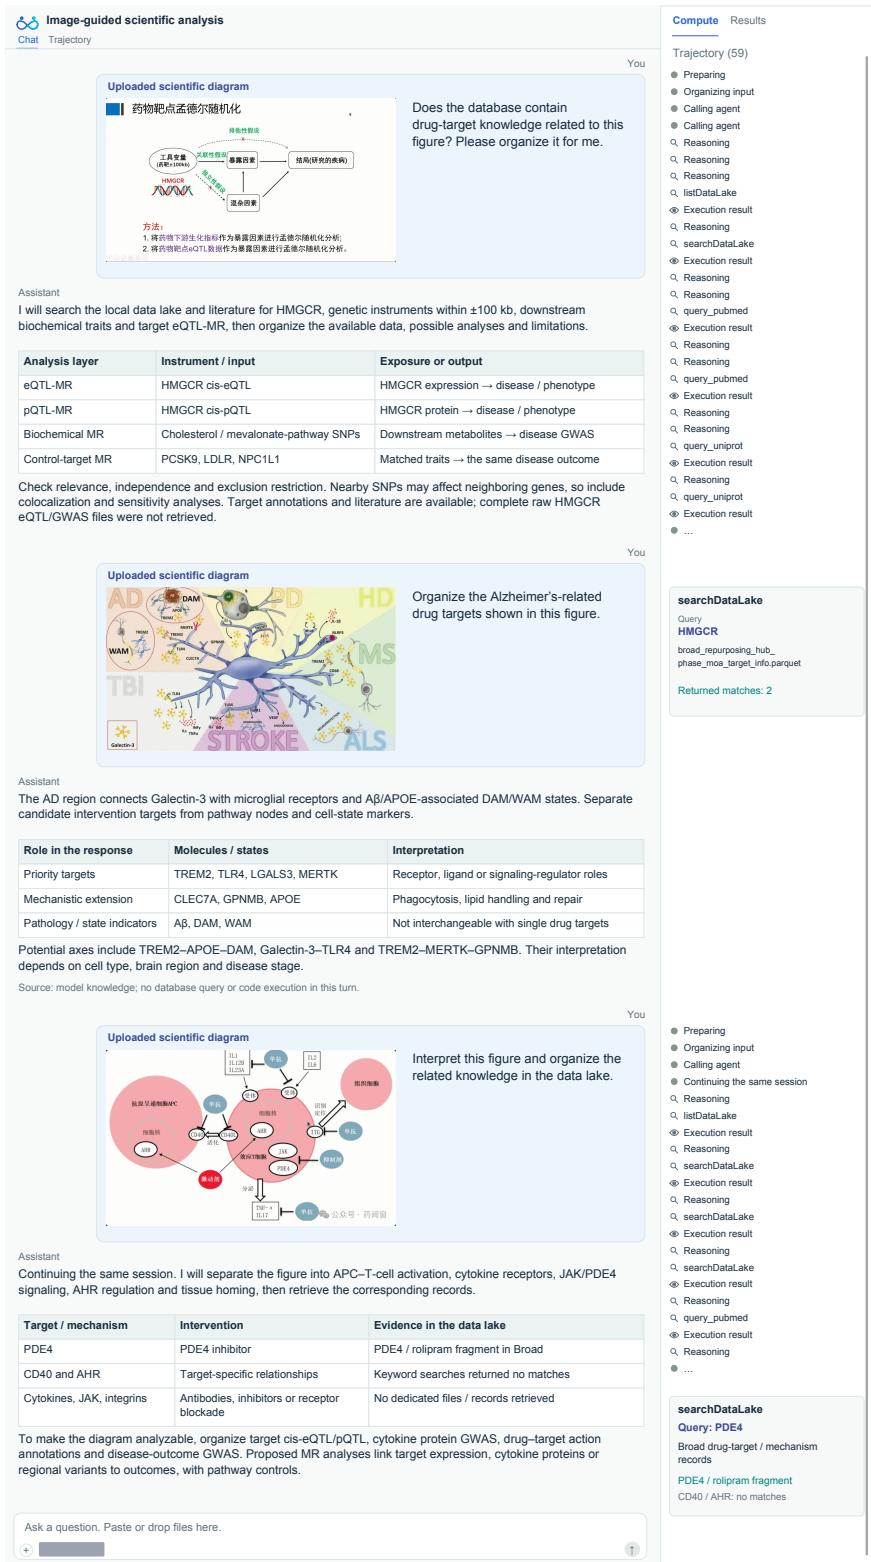
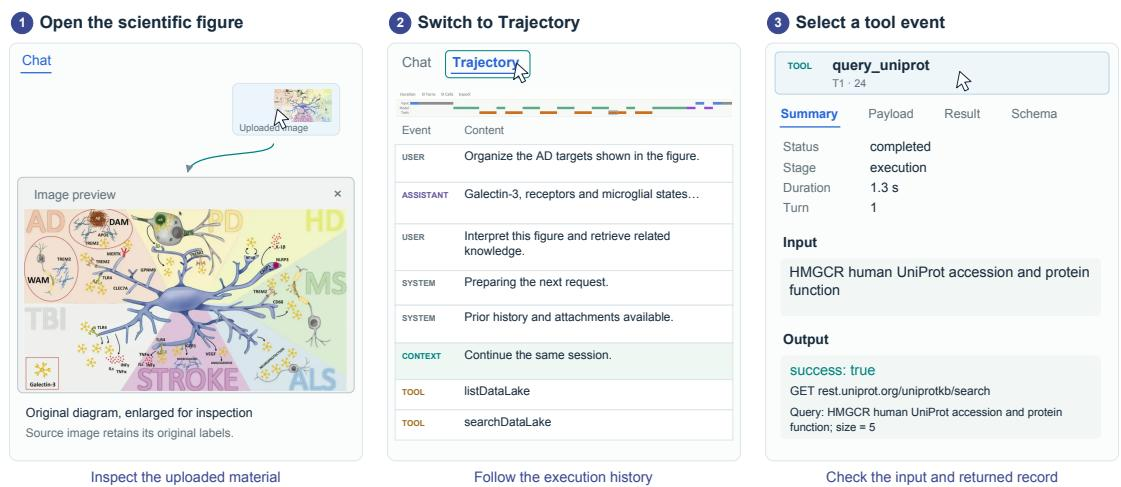
Researchers can also inspect the agent's work beyond conversational input. By switching to the Trajectory view and selecting specific tool events, users can examine metadata, inputs, and outputs to verify the basis of the agent's responses.
As shown in the figure below, these controls allow for detailed inspection of the execution history.
The training process couples harness adaptation with model updates through nested recursion. In the inner recursion, the task model parameters θk remain fixed. A fixed auxiliary model analyzes recent trajectories and rubric evaluations to identify unmet criteria. It proposes bounded procedural edits to the harness H, such as revising a skill or instruction:
Hk,j+1=U(Hk,j,Ek,j;θk)Candidates are accepted only if they satisfy edit constraints and improve the mean normalized rubric score Sˉk on development tasks:
Hk,j+1={Hk,j+1,Hk,j,Valid(Hk,j+1)∧Δk,j>0,otherwise.In the outer recursion, once a harness is selected, the system calibrates environment difficulty and generates fresh rollouts. The reward signal is derived from the task-specific rubric C(x):
Rx(τ)=∑c∈C(x)wc(x)∑c∈C(x)wc(x)vc(x,τ)The task model is updated using GRPO to maximize the expected trajectory reward:
θmaxJk(θ)=Ex∼qkEτ∼πθ,Hk⋆(⋅∣x)[Rx(τ)]After the model update θk+1, the harness and model are re-evaluated and deployed together, initiating the next cycle of researcher interaction and improvement.
Experiment
Four case studies evaluate ScienceBuddy through separate research questions: researcher interaction, coupled recursive-in-recursive improvement, harness adaptation, and model learning. Real researcher requests show how feedback translates into task objectives and evaluation criteria, enabling trajectory-derived rubrics. Across three co-evolution cycles alternating harness refinement and reinforcement learning, overall test accuracy rises from 42.2% to 73.3%, with gains across all task families and more previously incorrect problems becoming correct. Holding model weights fixed, harness adaptation improves validation accuracy by 20 percentage points; holding the harness fixed, model learning increases problem coverage from 48.3% to 67.8%, confirming both mechanisms independently broaden scientific task performance.