Command Palette
Search for a command to run...
Bellman Policy Optimization
Bellman Policy Optimization
Zhuoqing Song Haotian Xu Xikun Zhang Lidong Bing
초록
검증 가능한 보상을 사용하는 강화학습(RLVR)은 대형 언어 모델(LLM)의 추론 능력을 향상시킨다. 본 논문에서는 Policy Mirror Descent(PMD)에서 유도된 크리틱을 사용하지 않는 방법인 Bellman Policy Optimization(BPO)을 제안한다. 종단 보상을 가지는 자기회귀 생성에 대해 BPO는 벨만 방정식을 이용하여 PMD를 궤적 수준의 목적함수로 재구성한다. 이 재구성은 중간 상태에서 상태 가치를 추정하는 것을 피한다. 우리는 이 목적함수가 원래의 PMD 목적함수와 동일한 유일 최적해를 가진다는 것을 증명한다. 이 목적함수를 근사하여 실용적인 BPO 손실함수를 도출한다. 이 손실함수의 불일치 보정 가중치는 상보적인 토큰 확률의 평활화된 비율이다. 수학적 추론 벤치마크에서의 실험은 BPO의 효과를 입증한다.
One-sentence Summary
Researchers at Apodex US, Inc. and Princeton University introduce Bellman Policy Optimization (BPO), a critic-free method derived from Policy Mirror Descent (PMD) that reformulates PMD via Bellman equations into a trajectory-level objective for autoregressive generation with terminal rewards, avoiding state-value estimation and using a smoothed complementary-token-probability mismatch-correction weight, with demonstrated effectiveness on mathematical reasoning benchmarks.
Key Contributions
- Bellman Policy Optimization (BPO) is introduced as a critic-free reinforcement learning method derived from Policy Mirror Descent, using Bellman equations to formulate a trajectory-level objective that avoids estimating intermediate state values.
- The method proves that this trajectory-level objective has the same unique optimal solution as the original PMD objective on states reachable under the rollout policy, and derives a practical token-level loss with a smoothed mismatch-correction weight based on complementary token probabilities.
- On mathematical reasoning benchmarks, BPO achieves a peak average accuracy of 50.5% across AIME 2024 to 2026 with Qwen3-30B-A3B-Base, outperforming GRPO-ClipHigher, GSPO, CISPO, and DPPO by 3.1 to 11.0 percentage points, while ablations on Qwen3-4B-Base show similar performance across smoothing and truncation settings.
Introduction
Reinforcement learning with verifiable rewards (RLVR) is an important approach for improving reasoning in large language models, using outcome-level rewards from task-specific verifiers to guide training. Widely used methods such as GRPO normalize rewards within sampled groups and avoid a value model, but they rely on token-level importance-sampling ratios in PPO-style clipped objectives. Directly applying Policy Mirror Descent would require value estimates at intermediate states, and training a separate value model adds memory and computational costs while risking inaccurate estimates on reasoning tasks. The authors introduce Bellman Policy Optimization (BPO), a critic-free reformulation of Policy Mirror Descent that uses Bellman equations and policy likelihood ratios to convert terminal-reward advantages into a trajectory-level objective, thereby avoiding intermediate value or advantage estimation. The resulting practical loss replaces GRPO's importance-sampling ratio with a smoothed mismatch-correction weight, and BPO outperforms several baselines on mathematical reasoning benchmarks.
Method
The authors formulate Bellman Policy Optimization (BPO) as a critic-free policy optimization method for reinforcement learning with verifiable rewards. The method builds on group-based advantage estimation and policy mirror descent, replacing the importance-sampling ratio used in GRPO with a mismatch-correction weight derived from the PMD optimality condition.
For each prompt x, a group of G responses {yi}i=1G is sampled from a rollout policy μ. Given a terminal reward Ri=R(x,yi), BPO uses the same group-normalized advantage as GRPO:
A^i=std({Rj}j=1G)Ri−mean({Rj}j=1G).For a token yti in response yi, the BPO per-token loss is defined as
Li,tBPO(π)=−A^iMtimin{sg(ωti),C}logπ(yti∣x,y<ti),where C is a constant cap for stability, and Mti is a clipping mask. The main difference from GRPO is the weight ωti, which replaces the importance-sampling ratio rti. This mismatch-correction weight is defined as
ωti=1+ϵ−π(yti∣x,y<ti)1+ϵ−μ(yti∣x,y<ti),with additive smoothing controlled by ϵ. The mask Mti follows the same clipping rule as GRPO, but uses ωti instead of the importance ratio:
Mti=⎩⎨⎧0,0,1,A^i>0 and ωti>1+ϵhigh,A^i<0 and ωti<1−ϵlow,otherwise.Thus, BPO retains GRPO's per-token weighted log-likelihood form, while replacing the ratio rti by the truncated mismatch-correction weight min{sg(ωti),C}.
The derivation of BPO starts from advantage-based policy mirror descent. For each state st=(x,y<t), the PMD update is formulated as
π(⋅∣st)∈Δ(V)maxEyt∼π(⋅∣st)[Aμ(st,yt)]−η1DKL(π(⋅∣st)∥μ(⋅∣st)),where Aμ(st,yt) is the rollout-policy advantage function. The unique optimal policy has the form
π+(yt∣st)=Zμ(st)μ(yt∣st)exp(ηAμ(st,yt)).Direct implementation of this update would require estimating advantages at intermediate states, typically through a learned critic. BPO avoids this by deriving a critic-free reformulation.
The authors show that PMD can be equivalently expressed through a squared trajectory-level residual objective. For a prompt-dependent positive weight ϕ(x), the critic-free objective is
π∈ΠμminL(π)=Ex∼D,y∼Pμ(⋅∣x)[ϕ(x)⋅2ηδ(x,y;π,μ)2],where the trajectory-level residual is
δ(x,y;π,μ)=η(R(x,y)−Vμ(x))−t=1∑∣y∣(logμ(yt∣st)π(yt∣st)+DKL(μ(⋅∣st)∥π(⋅∣st))).This objective depends only on terminal rewards and the initial value function Vμ(x), not on intermediate state values. The equivalence between this critic-free objective and the original PMD problem is established by rewriting the PMD optimality condition, combining it with Bellman equations over the trajectory, and showing that the PMD solution zeroes the residual δ.
The practical BPO loss is obtained from this reformulation in four steps. First, the squared-residual objective is linearized around π=μ. Second, Vμ(x) is estimated by the group mean reward, and ϕ(x) is replaced by the inverse empirical reward standard deviation, yielding the normalized advantage A^i. Third, the full reverse KL divergence is approximated by a binary KL divergence, which produces the token-level ratio
∇(logπ(yti∣sti)+DKLbin(μ(⋅∣sti)∥π(⋅∣sti);yti))=1−π(yti∣sti)1−μ(yti∣sti)∇logπ(yti∣sti).Additive smoothing is then applied to this ratio to obtain ωti. Finally, GRPO-style masking and the cap C are applied, yielding the BPO gradient
∇Li,tBPO(π)=−A^iMtimin{ωti,C}∇logπ(yti∣sti),which corresponds to the BPO per-token loss in Equation (14).
Experiment
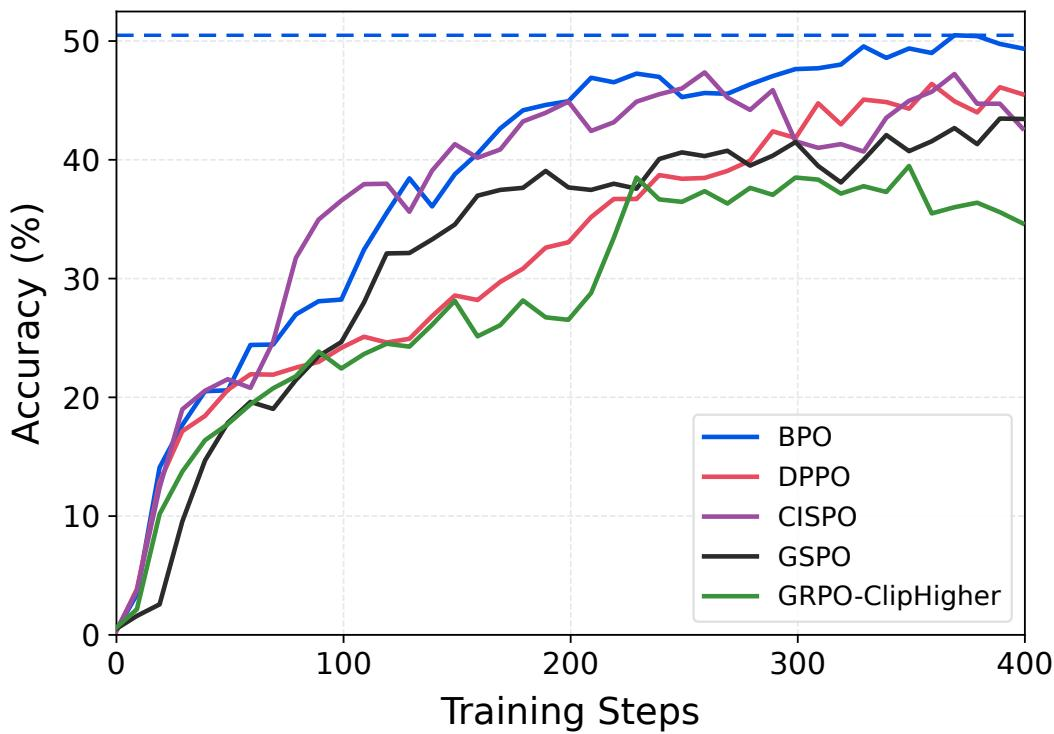
The experiments evaluate BPO for mathematical reasoning using Qwen3-30B-A3B-Base trained on the English subset of DAPO-Math-17k, with all methods sharing the same rollout and optimization settings except for the policy loss. Evaluation on AIME24, AIME25, and AIME26 using Pass@1 estimated through Avg@32 shows that BPO consistently achieves the highest accuracy across all benchmarks and at the end of training. The results indicate that BPO outperforms strong baselines including CISPO and DPPO, validating it as an effective policy optimization objective for improving mathematical reasoning.
BPO achieves the highest average accuracy and the highest score on each AIME benchmark among all compared policy loss methods. The strongest baseline at the best checkpoint is CISPO, and BPO outperforms it by 3.1 percentage points on average. At the end of training, BPO also exceeds the strongest final baseline, DPPO, in average accuracy. BPO leads all methods on AIME24, AIME25, and AIME26, as well as on the overall average. BPO improves over the strongest best-checkpoint baseline by 3.1 percentage points and over the strongest final baseline at the end of training.
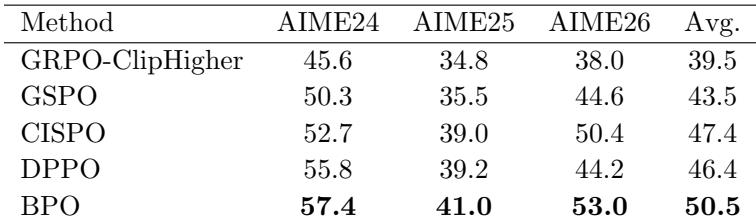
The evaluation compares policy loss methods on AIME benchmarks, considering both the best checkpoint and end-of-training performance. BPO achieves the highest average accuracy and the highest score on every AIME benchmark, outperforming the strongest best-checkpoint baseline, CISPO, and the strongest final baseline, DPPO. It leads all compared methods on AIME24, AIME25, AIME26, and the overall average, demonstrating consistently superior results.