Command Palette
Search for a command to run...
Atria Dawn: 에이전트 초지능의 여명—인간-AI 협업의 진화하는 역할에 관하여
Atria Dawn: 에이전트 초지능의 여명—인간-AI 협업의 진화하는 역할에 관하여
초록
AI 에이전트가 자신의 후속 세대 개발에 참여하게 되면서, 지능의 생산 방식과 인간 연구자의 역할이 함께 재편되고 있다. 우리는 실제 세계에서 에이전트 생산성의 지평을 확장하는 것을 목표로, 과학 연구 및 엔지니어링 워크플로우를 위해 설계된 기반 에이전트 언어 모델인 Atria Dawn Preview를 소개한다. 이 모델은 도구 매개 상호작용을 실행 가능한 환경 및 외부 검증 결과와 연결하는 검증 가능한 경험 파이프라인(Verifiable Experience Pipeline)을 통해 훈련되었다. 실제 연구, 엔지니어링, 디지털 작업을 포괄하는 16개 벤치마크에서 Atria Dawn Preview는 최첨단 에이전트와 경쟁력을 갖추며, 그중 5개에서 가장 높은 보고 점수를 달성했다. 단독 성능을 넘어, 우리는 이 모델 뒤에 있는 실제 연구개발 과정을 인간-AI 협업의 사례 연구로 검토하며, 56명의 참가자로부터 수집한 769개의 작업 기록과 에이전트 로그를 함께 분석한다. 참가자들은 유사한 조건에서 완료된 작업을 평가하도록 요청받았을 때, AI 지원으로 완료된 작업의 약 3분의 1을 AI 없이는 실행 불가능하다고 평가했다. 더욱 주목할 점은, 에이전트가 방법 제안과 수정 구현을 자주 수행하는 반면, 인간은 대부분의 최종 결정을 유지하고 판단과 피드백을 통해 탐색을 이끈다는 것이다. 이러한 관찰은 작업 수준의 실행에서 프로젝트 수준의 파트너십으로의 전환을 시사하며, 인간의 노력은 무엇을 추구할 가치가 있는지와 증거가 연구를 어떻게 이끌어야 하는지에 집중된다. 따라서 보다 자율적인 AI 연구로의 진전은 발견 능력과 의미 있는 인간 감독 능력을 동시에 향상시켜야 하며, 지속적인 개발의 위험과 방향에 대한 책임 있는 인간의 권한을 보존해야 한다.
One-sentence Summary
Researchers at Fudan University introduce Atria Dawn Preview, a foundation agentic language model for scientific research and engineering, trained via a Verifiable Experience Pipeline that links tool-mediated interactions to executable environments and externally verified outcomes, which matches frontier agents across 16 benchmarks, achieves the highest reported score on five, and, in a case study of 769 task records from 56 participants, reveals that agents frequently propose methods and implement revisions while humans retain final decisions and guide exploration, signaling a shift from task-level execution to project-level partnership that demands both enhanced discovery capacity and meaningful human oversight.
Key Contributions
- Introduces Atria Dawn Preview, a 744-billion-parameter mixture-of-experts agentic language model trained via a Verifiable Experience Pipeline that grounds tasks in executable environments and checks outcomes against external signals, achieving competitive performance across 16 benchmarks and the highest reported score on five.
- Presents a case study of human–AI collaboration during the model’s development, analyzing 769 task records and agent logs from 56 participants, finding that AI proposed 64.6% of methods and decisions while humans made the final choice in 85.5% of cases, and that human intervention advanced 76.0% of difficult tasks.
- Reports empirical evidence on oversight dynamics, showing that participants rated about one-third of completed AI-assisted tasks as infeasible without AI, and that the daily median agent actions per human prompt rose from 11.0 to 28.5 over four weeks, indicating a shift from task-level execution to project-level partnership with humans retaining final authority.
Introduction
As language-model agents take on sustained tool use in software engineering and research, a key question emerges: who decides what problems are worth solving, which methods to pursue, and how to interpret results in a real model-development project? Prior work focuses on task-level competence but does not clarify the division of responsibility between agents and humans, nor whether agents can strengthen the research process itself, not just execute tasks.
The authors introduce Atria Dawn Preview, a 744-billion-parameter mixture-of-experts agentic language model trained for scientific research and engineering workflows. It uses a Verifiable Experience Pipeline that links tasks and agent trajectories to externally checked outcomes. Evaluated on 16 benchmarks, the model achieves top scores on five, though performance varies. The authors also analyze the development of Atria Dawn itself as a case study, drawing on 769 task records from 56 participants. They find that agents proposed 64.6% of methods and decisions, while humans made the final choice in 85.5% of cases, and 76.0% of tasks advanced due to human intervention. This reveals a shift where agents initiate approaches and execute changes, while humans focus on evaluation, selection, and steering direction. The authors argue that sustained recursive self-improvement requires more than task-level competence, including identifying worthwhile directions, designing informative experiments, and deciding when to redirect effort, areas where human judgment remains consequential.
Method
The authors introduce Atria Dawn Preview, a 744-billion-parameter mixture-of-experts foundation model engineered for complex research and engineering tasks. The architecture emphasizes sustained reasoning, tool utilization, and dynamic interaction with external environments.
The core training methodology relies on a Verifiable Experience Pipeline. This framework tightly couples task objectives with tool-mediated reasoning and externally verified outcomes to foster generalizable behaviors. During a rollout, the agent observes the environment state, selects and invokes tools, inspects the resulting outputs, and iteratively revises its actions based on feedback.
Final outcomes are rigorously checked using domain-specific signals, including executable tests, experiment metrics, file and application states, geometric checks, and source support. Following execution, trajectory curation filters the data by removing incomplete, contradictory, duplicate, or behaviorally invalid examples. This ensures that only high-quality experiences linking tasks to their trajectories, artifacts, and verification evidence are integrated into the model's reusable capabilities.
The system employs continuous failure analysis to drive subsequent task construction and environment refinement. Recurring issues such as ineffective tool selection, incomplete verification, missing evidence, and unsuccessful recovery prompt the generation of additional tasks and quality checks. Failed runs are repurposed as diagnostic cases when their outcomes are independently established, teaching the model reusable behaviors for state inspection, feedback interpretation, and error recovery.
In practical deployment, the system design delineates a clear division of labor between human researchers and the AI agent. Humans retain responsibility for defining goals, supplying missing context for failed runs, and specifying necessary changes, while the agent generates options and produces the bulk of the code, text, and revisions. This collaborative dynamic is reflected in the operational metrics, where the ratio of agent actions to human prompts increases significantly as researchers delegate more execution tasks.
As illustrated in the figure below:
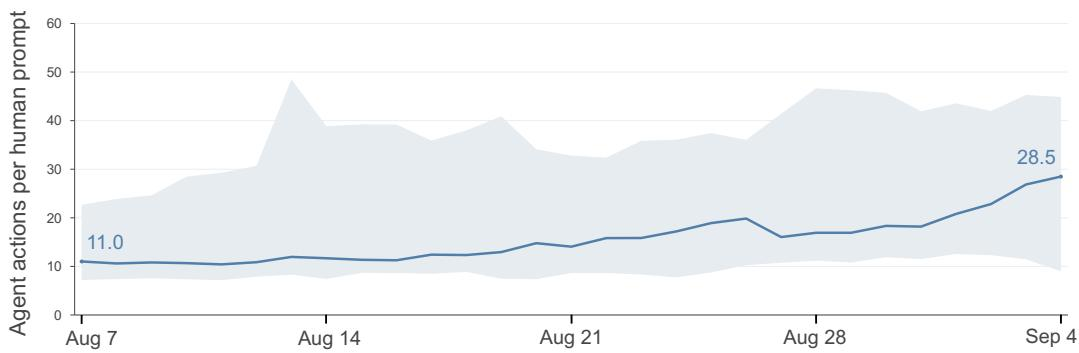
The rising ratio indicates that each act of human judgment now propagates through more agent actions, demonstrating a shift toward deeper execution delegation rather than growing autonomy.
Experiment
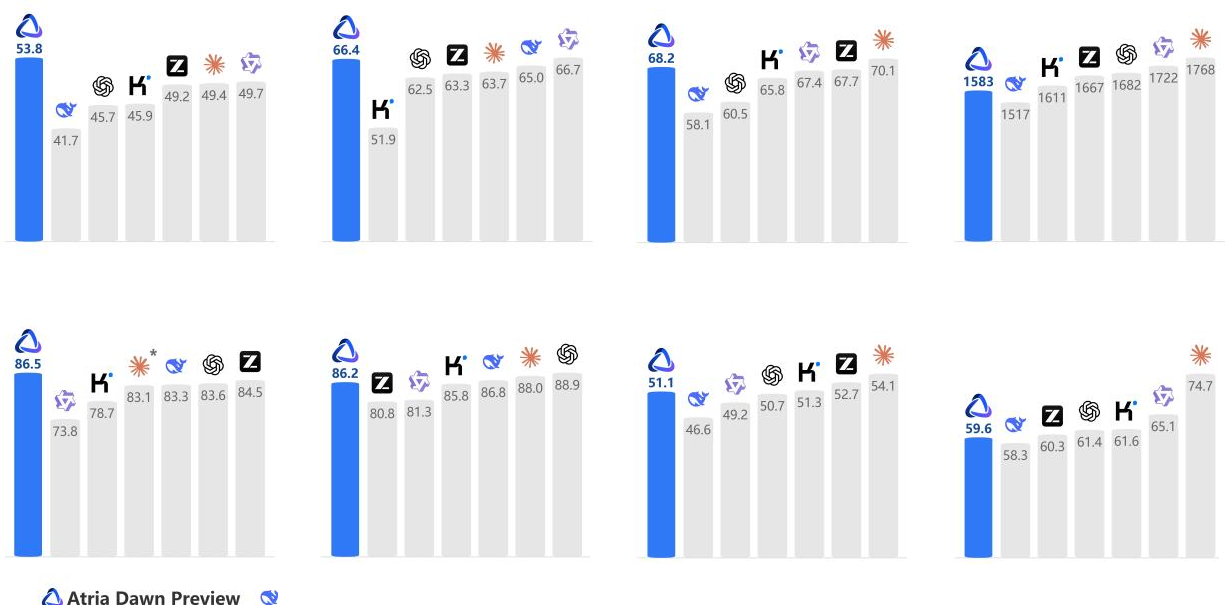
Atria Dawn Preview is evaluated across 16 benchmarks spanning tool use, search, research, workspace productivity, software engineering, and cybersecurity, achieving the highest reported score on five benchmarks and second-highest on three, with particular strength in general agentic tasks and security-related coding. Case studies demonstrate concrete capabilities across scientific research, software creation, report delivery, and vulnerability remediation, including building a MiniOS from scratch and training a large weather forecasting model. Analysis of human-AI collaboration during development shows that 96.5% of tasks involved AI, with 33.2% of AI-assisted tasks deemed infeasible without AI, while humans retained final decision authority in 85.5% of method or parameter choices and 95.4% of goals for the most AI-dependent tasks. When difficulties arose, human intervention was primarily informational, providing context or diagnosis rather than direct edits, and AI revised outputs after human feedback in 75.4% of substantively revised tasks.
Atria Dawn Preview leads or closely trails the best available models across a broad set of agentic benchmarks, with top scores in tool use, search, and cybersecurity. Its strengths are consistent across general agentic tasks, while in coding it shows particular security capability and competitive performance on software engineering and terminal tasks. Atria Dawn Preview achieves the highest reported score on five benchmarks, including AutomationBench, BFCL v4, DeepSearchQA, BrowseComp, and CyberGym. On three general agentic benchmarks (SkillsBench, Workspace-Bench, Workspace-Bench-Lite), it ranks second with gaps of less than two points to the leader. In cybersecurity (CyberGym), it leads by 2.0 points over the runner-up, indicating notable strength in vulnerability analysis and security tasks. On coding benchmarks, it is comparable to top models on SWE-bench Pro and Terminal-Bench 2.1, while leading on MLE-bench Lite among reported scores. Across remaining general tasks, it stays within the leading tier, often matching or surpassing several comparison models on search and professional benchmarks.
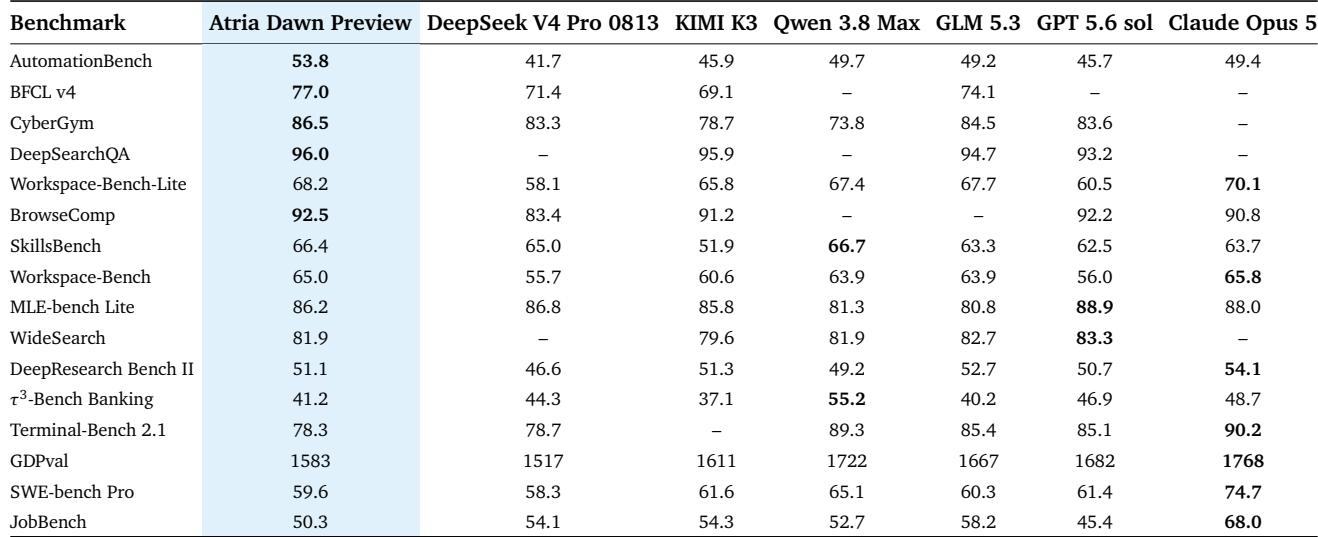
Atria Dawn Preview consistently matches or outperforms leading models across a wide range of agentic benchmarks, achieving top scores in tool use, search, and cybersecurity, and ranking first on five benchmarks including AutomationBench, BFCL v4, DeepSearchQA, BrowseComp, and CyberGym. It holds second place on three general agentic benchmarks with gaps under two points, and shows notable strength in vulnerability analysis. In coding, it is competitive on software engineering and terminal tasks, while leading MLE-bench Lite among reported scores, and remains in the leading tier across remaining general tasks.