Command Palette
Search for a command to run...
EvoOntology: 데이터 에이전트를 위한 자기 진화형 온톨로지 계층
EvoOntology: 데이터 에이전트를 위한 자기 진화형 온톨로지 계층
Meiduo Chong Shaolei Zhang Ju Fan Xiaoyong Du
초록
데이터 에이전트는 테이블, 파일, 데이터베이스 등 이질적인 데이터를 대상으로 자연어 지시를 수행하는 것을 목표로 한다. 그러나 데이터 에이전트는 에이전트-데이터 간극이라는 어려운 문제에 직면한다. 이질적 데이터는 에이전트 외부에 존재하며, 에이전트는 범용 도구를 통해서만 데이터(예: 열 이름과 파일 경로)에 접근할 수 있다. 기존 접근법은 에이전트가 원시 데이터 소스를 직접 탐색하게 하거나 수동으로 구축한 시맨틱 계층을 프롬프트에 주입한다. 그러나 두 방식 모두 대규모 이질적 데이터 소스로 확장하기 어렵고 서로 다른 에이전트 행동에 적응하지 못한다. 본 논문에서는 데이터 에이전트를 위한 자기 진화형 온톨로지 계층인 EvoOntology를 소개한다. EvoOntology는 온톨로지를 스키마 계층, 콘텐츠 계층, 도구 계층으로 구성된 MCP 서버로 캡슐화하여 에이전트가 런타임에 온톨로지를 능동적으로 질의하고 상호작용할 수 있게 한다. 이를 위해 자율적 온톨로지 구축을 위한 빌더 에이전트와, 기여도 기반 유형화 편집을 통해 온톨로지를 지속적으로 정제하되 백본 조건부 쌍 평가를 통과한 편집만 수용하는 자기 진화 루프를 제안한다. 4개의 LLM 백본을 사용한 3개의 널리 채택된 데이터 에이전트 벤치마크 실험에서 EvoOntology는 강력한 기준 모델과 기존 시맨틱 계층 접근법을 일관되게 능가하여 에이전트-데이터 간극을 효과적으로 해소하고 이질적 데이터와의 더 효과적인 상호작용을 가능하게 함을 보여준다.
One-sentence Summary
Researchers at Renmin University of China propose EvoOntology, a self-evolving ontology layer for data agents that encapsulates an MCP server with schema, content, and tool layers, in which a builder agent constructs the ontology and an attribution-guided typed-edit loop with backbone-conditional paired evaluation refines it; EvoOntology outperforms strong baselines and existing semantic-layer approaches on three well-adopted benchmarks across four LLM backbones.
Key Contributions
- EvoOntology introduces an interactive ontology layer for data agents, encapsulated as an MCP server with schema, content, and tool layers, enabling agents to query and interact with heterogeneous data at runtime.
- A builder agent autonomously constructs the ontology, and a self-evolution loop refines it through attribution analysis, targeted typed edits, and backbone-conditional paired evaluation on held-out validation data.
- Experiments on three data-agent benchmarks with four LLM backbones show that EvoOntology consistently outperforms strong baselines and existing semantic-layer approaches.
Introduction
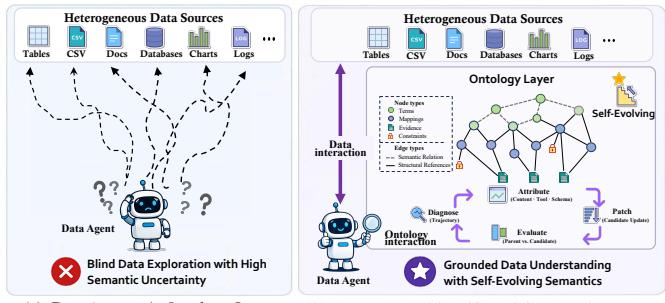
Data agents must answer natural-language tasks over heterogeneous structured and unstructured sources, but they typically access data only through generic tools such as SQL interfaces and file readers. Because the schema and content of those sources are not known in advance, agents resort to blind probing and inefficient exploration, creating a persistent agent-data gap. Prior raw-querying methods scale poorly to wide heterogeneous data, while semantic-layer approaches are often static, manually maintained, and too large to fit into agent context. The authors introduce EvoOntology, a self-evolving ontology layer exposed through a Model Context Protocol server that agents can query at runtime; it is constructed automatically, grounds ontology entries in observed data, and refines itself from agent interaction traces through attribution-guided edits and paired validation.
Method
To reduce manual semantic-layer authoring while adapting the layer to agent behavior, the authors propose EvoOntology, an agent-first builder-and-evolver framework. EvoOntology maintains a versioned ontology state comprising content, schema, and tool layers. A builder agent constructs an evidence-grounded initial state from the training workload and raw sources, while an evolution agent refines it from historical trajectories. The design is agent-first because the ontology is built around the workload, accessed through the tool interface, and adapted from execution history.
As shown in the figure below:
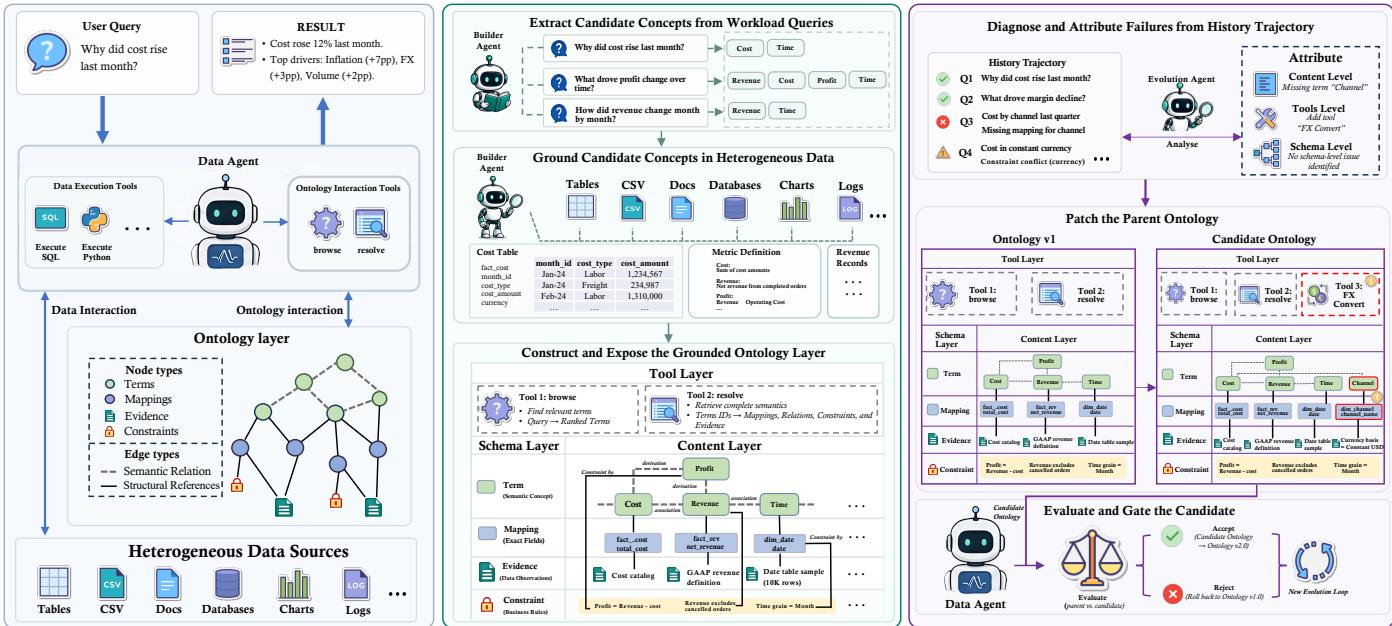
The framework represents the ontology state at evolution round t as Lt=(St,Γt,Rt), which separates semantic knowledge, its object model, and its runtime exposure. This separation allows the deployed agent to retrieve only the semantics relevant to the current step and enables the evolution agent to update a bounded part of the ontology state.
The Content Layer St is a typed semantic graph containing four node families (Terms, Mappings, Constraints, and Evidence) and two edge families (Semantic Relations and Structural References). Terms represent domain concepts, Mappings ground them to fields and linking paths, Constraints govern their valid use, and Evidence supports their semantic claims. The Schema Layer Γt defines the fields of the node families, the admissible Semantic Relation types, and the permitted reference patterns, allowing schema updates to extend representational capacity without altering instantiated content. The Tool Layer Rt exposes the ontology through two MCP tools and a session manifest. The function fbrowse(q,k,n) retrieves the top-n semantic matches for a query q and kind k, while fresolve(T,c) returns requested records and their linked objects. The manifest provides compact source and usage information at session initialization and is the only ontology content placed directly in the prompt.
For the initialization phase, the builder agent constructs an initial ontology from the training workload W and raw sources D without observing gold answers. Through workload-guided probing, the builder proposes candidate concepts C from recurrent entities, metrics, operations, and analytical conditions. For each candidate c∈C, it issues a probe to identify candidate fields and linking paths, inspecting their types, values, and semantic consistency. Through evidence-grounded commitment, only candidates supported by their probe results are committed to the initial Content Layer:
C+={c∈C∣verify(probe(c,D))=1},S0=construct(C+,D;Γ0)Verified candidates are instantiated under Γ0, with supporting records retained as Evidence, forming the initial state L0=(S0,Γ0,R0).
To ensure the ontology suits the specific agent, the evolution phase leverages historical trajectories as behavioral evidence. Given historical trajectories Tt and the current state Lt, the evolution agent extracts recurrent signatures Σt=analyze(Tt,Lt). Each signature summarizes an interaction pattern, the involved ontology objects, and observed outcomes. The agent attributes the signature to the Content, Tool, or Schema layer and states the expected behavioral effect of an update. For an attributed signature, the agent proposes a localized intervention that modifies only one level of the ontology. Content interventions add, remove, or revise instantiated semantic objects in St. Tool interventions modify existing tools or add and remove tools in Rt based on observed agent behavior. Schema interventions revise the object model in Γt.
Finally, the system employs backbone-conditional paired validation. For a backbone m, let ϕ(L,V;m) denote the score of ontology state L on validation set V. The candidate and its parent are evaluated on the same V with identical decoding and interaction budgets. The candidate is retained only when its improvement reaches a margin τ:
Lt+1={Lt′,Lt,ϕ(Lt′,V;m)−ϕ(Lt,V;m)≥τ,otherwise.Rejected candidates are not deployed, and their signatures, interventions, and evaluation outcomes are logged to avoid repeated ineffective updates. All backbones evolve independently from the same initial state L0, allowing accepted updates to reflect backbone-specific interaction patterns.
Experiment
EvoOntology is evaluated on DDR-Bench, InsightBench, and BIRD across six LLM backbones using a reciprocal two-fold setup, with comparisons against an ontology-free ReAct baseline, a static semantic-layer prompt baseline, and in some cases memory-based retrieval. The queryable ontology layer produces consistent gains, while the static prompt baseline yields mixed or negative effects and episodic memory remains weaker than the structured ontology. The builder-constructed ontology provides a strong initial improvement, self-evolution adds further convergent gains, and ablations show that the evolution gate and attribution steps, as well as Mappings and Evidence structures, are the most load-bearing components, with backbone-specific ontologies transferring best within their own backbone.
On the DDR-Bench 10-K scenario, EvoOntology improves trajectory-wise accuracy over the baseline for every evaluated LLM backbone, with an average gain near eighteen points and improvements varying across backbones. In contrast, injecting the semantic layer as a static prompt does not provide consistent gains and can sharply reduce accuracy on some backbones. The advantage comes from exposing ontology content through queryable tools rather than relying on a static prompt fragment. EvoOntology achieves consistent trajectory-wise gains over the baseline across all evaluated backbones. Baseline plus a static semantic layer occasionally underperforms the unmediated agent, including a large drop on one backbone. Active tool-based access to the ontology is the main source of the improvement over a static prompt. Accepted evolution rounds improve the score monotonically and stabilize in later rounds, indicating convergence rather than a single lucky patch.
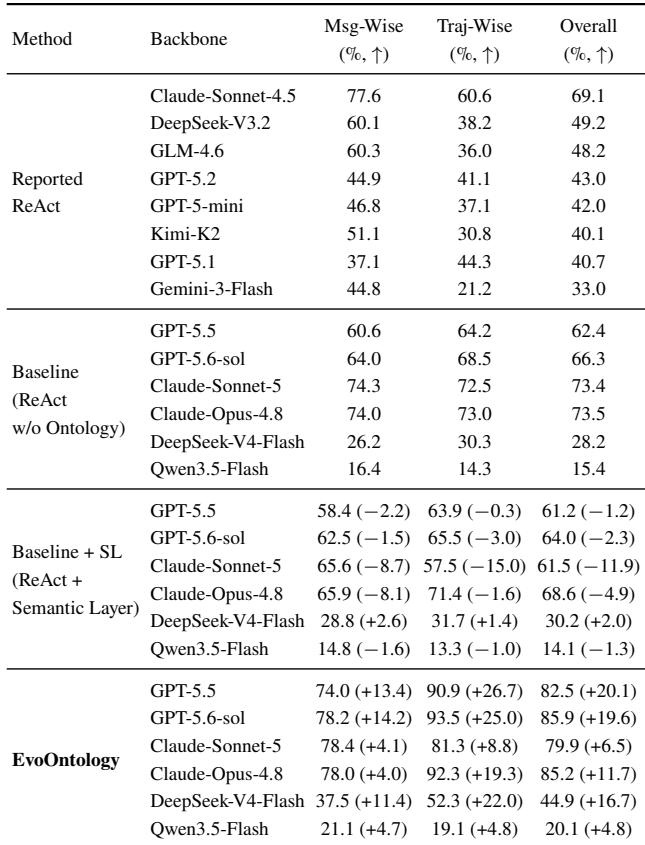
On DDR-Bench averaged across four backbones, storing past trajectories as retrievable episodes gives a modest lift over the base ReAct agent. EvoOntology produces a much larger Trajectory-Wise gain, clearly surpassing both the baseline and the memory-augmented variant. Adding a memory of past trajectories improves over the ReAct baseline, but only by a relatively small margin. EvoOntology achieves the strongest Trajectory-Wise improvement, substantially outperforming both the baseline and the memory-based persistence approach.
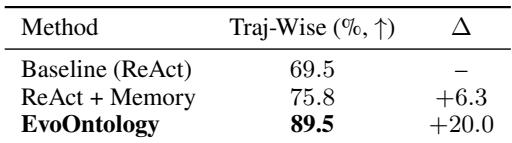
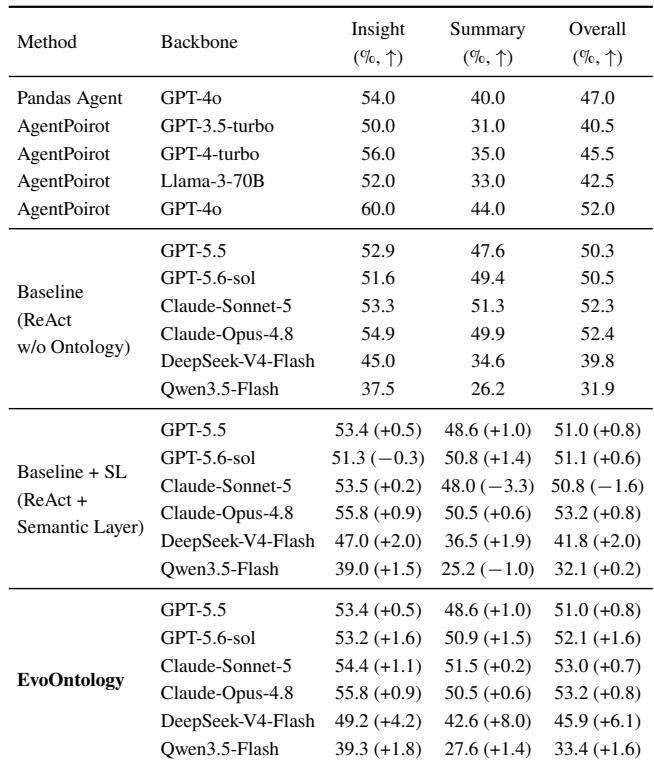
On InsightBench, EvoOntology improved overall performance across evaluated backbones, with modest average gains relative to baselines. The improvements are smaller than on retrieval-focused benchmarks because insight mining saturates once outputs match reference-style findings. Unlike a static semantic layer, EvoOntology improved both insight and summary metrics by exposing ontology content through queryable tools. EvoOntology achieved consistent overall gains on InsightBench across backbones, with the largest improvement on DeepSeek-V4-Flash. A static semantic layer recovered most of the insight gains but did not consistently preserve summary quality, including a drop on one backbone. EvoOntology improved both insight and summary scores, unlike the static semantic layer.
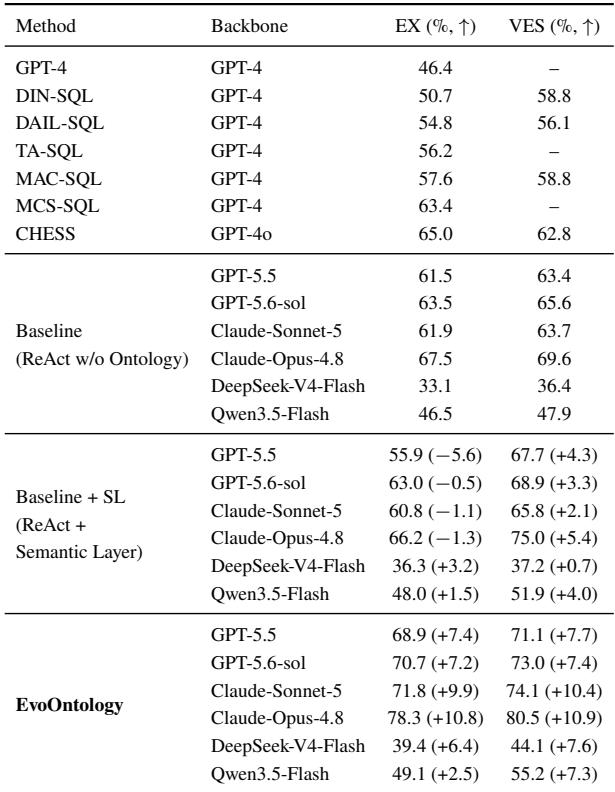
Under oracle knowledge on BIRD, EvoOntology improves both execution accuracy and efficiency across all evaluated backbones, with consistent average gains. A static semantic layer raises efficiency but can lower execution accuracy, suggesting it helps well-formed SQL while distracting from correct query generation. Exposing the same ontology through queryable tools and refining it via the evolution loop yields stable gains over baselines and prior text-to-SQL systems. EvoOntology improves execution accuracy and efficiency for every evaluated backbone. A static semantic layer improves SQL well-formedness but can reduce execution accuracy. Queryable, evolved ontology access recovers accuracy gains and outperforms prior text-to-SQL methods.
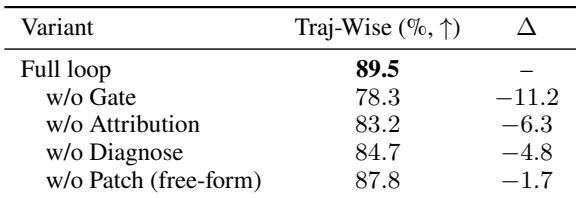
The full evolution loop achieves the highest average trajectory-wise score, and disabling any single step reduces performance. The gate step is the most critical, with filtering candidate patches preventing the largest regression. The patch stage has the smallest impact, while attribution and diagnosis contribute moderate gains. Removing the gate step causes the largest performance drop among the four evolution loop steps. Replacing the typed patch stage with free-form ontology rewriting has the least impact on final performance. The full loop outperforms every variant with one step disabled.
Across DDR-Bench, InsightBench, and BIRD experiments, EvoOntology consistently improves over base agents and memory-augmented variants on trajectory accuracy, insight and summary quality, and SQL execution accuracy and efficiency, while a static semantic layer often provides inconsistent gains or degrades performance. The main source of improvement is exposing ontology content through queryable tools within an iterative evolution loop, which converges and stabilizes across accepted rounds. Ablations show the full evolution loop outperforms every single-step-disabled variant, with the gate step being most critical and the typed patch stage least impactful.