Command Palette
Search for a command to run...
Dream-RSI: 진화하는 세계를 통한 재귀적 자기 개선
Dream-RSI: 진화하는 세계를 통한 재귀적 자기 개선
초록
재귀적 자기 개선은 자율 AI 에이전트에게 점점 더 중요해지고 있으며, 그 진전은 복잡한 도메인에서 고가치 솔루션을 발견하는 데 달려 있습니다. 이 과정의 동력은 효과적인 탐색이지만, 탐색 전략을 관리하고 개선하는 것은 여전히 주요 병목으로 남아 있습니다. 현재 시스템은 근본적인 딜레마에 직면해 있습니다: 고정된 전략은 검색 공간이 확장됨에 따라 적응하지 못하는 반면, 온라인 정책 최적화는 장기 롤아웃에서 지연되고 비용이 많이 드는 피드백 하에 방대한 메타 검색 공간을 탐색해야 합니다. 우리는 확장 가능하고 재귀적으로 자기 개선되는 탐색을 위한 프레임워크인 Dream-RSI를 소개합니다. 가벼운 오케스트레이션 계층은 탐색을 명시적이고 프로그래밍 가능하게 만들면서 기본 코딩 에이전트는 변경하지 않습니다. 우리의 핵심 통찰은 축적된 발견 이력이 실현된 검색 공간에 대한 리플레이 시뮬레이터 역할을 할 수 있다는 것입니다. 과거 발견 트리로 구축된 리플레이 시뮬레이터에서 꿈꾸기(dreaming)를 수행함으로써, Dream-RSI는 반복적이고 비용이 많이 드는 온라인 평가를 호출하지 않고도 탐색 정책을 평가하고 개선하기 위한 즉각적이고 저비용의 정책 외 피드백을 확보합니다. 개선된 정책은 이후 온라인에 재배포되어 추가 발견을 주도하고, 자기 개선 루프에서 시뮬레이터 풀을 지속적으로 확장합니다. 알고리즘 엔지니어링, 수학적 최적화, GPU 커널 엔지니어링 전반에 걸쳐 Dream-RSI는 경쟁력 있거나 개선된 발견 품질을 달성하면서 여러 설정에서 발견 비용을 상당히 줄입니다.
One-sentence Summary
Researchers from Google, University of Maryland, Google DeepMind, and University of Virginia introduce Dream-RSI, a framework for scalable recursive self-improvement in which a lightweight orchestration layer makes exploration explicit and programmable, and accumulated discovery history serves as a replay simulator to deliver immediate, low-cost off-policy feedback for refining exploration policies without repetitive online evaluations, yielding competitive or improved discovery quality at substantially reduced cost across algorithm engineering, mathematical optimization, and GPU kernel engineering.
Key Contributions
- Introduces Dream-RSI, a framework that makes exploration strategies explicit and programmable through a lightweight orchestration layer, leaving the underlying coding agent unchanged, and enables recursive self-improvement of exploration without modifying the agent itself.
- Converts accumulated discovery history into a replay simulator, allowing candidate exploration policies to be evaluated with immediate, low-cost off-policy feedback from stored outcomes rather than rerunning expensive online discovery rollouts, addressing the bottleneck of delayed and costly meta-level feedback.
- Across algorithm engineering, mathematical optimization, and GPU kernel engineering, Dream-RSI achieves competitive or improved discovery quality while substantially reducing discovery cost in several settings, demonstrating the effectiveness of the replay-simulator approach for scalable exploration improvement.
Introduction
Recursive self-improvement (RSI) in AI systems often relies on iterative discovery loops where agents generate, evaluate, and refine candidate solutions. As these loops scale to long-horizon exploration over vast search spaces, the ability to orchestrate exploration becomes critical, yet existing approaches typically use fixed, manually designed strategies that cannot adapt based on accumulated experience. Prior work that attempts to optimize exploration policies online faces two bottlenecks: feedback is delayed and expensive at the meta level, and the space of possible policies is vast, making each evaluation costly.
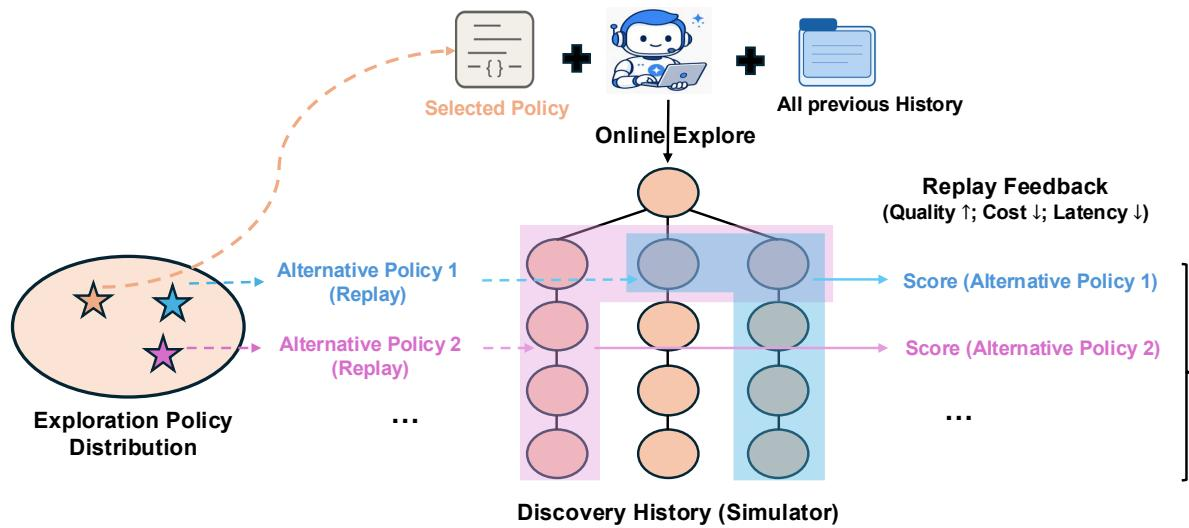
The authors introduce Dream-RSI, a framework that addresses these challenges by treating completed discovery histories as replay simulators. Instead of rerunning the underlying discovery agent, alternative exploration policies can navigate a pre-recorded discovery tree, reading stored outcomes to evaluate their effectiveness at negligible cost. This transforms meta-policy improvement from expensive online trial-and-error into a fast, simulation-based "dreaming" process. Dream-RSI establishes a closed-loop mechanism with three stages: online exploration, simulator construction from logged execution traces, and dreaming-based policy improvement, which then redeploys the upgraded policy to expand the simulator pool. Empirically, Dream-RSI demonstrates improved discovery effectiveness and efficiency across algorithm engineering, mathematical optimization, and GPU kernel engineering, reducing agent calls by up to 162x and achieving over 50x budget savings in some settings.
Method
The authors propose Dream-RSI, a framework that alternates between online exploration and offline dreaming to iteratively improve an executable exploration policy that allocates discovery computation. As shown in the figure below, the system operates in a recursive self improvement loop via three core stages: online exploration, constructing a replay simulator, and dreaming based policy improvement.
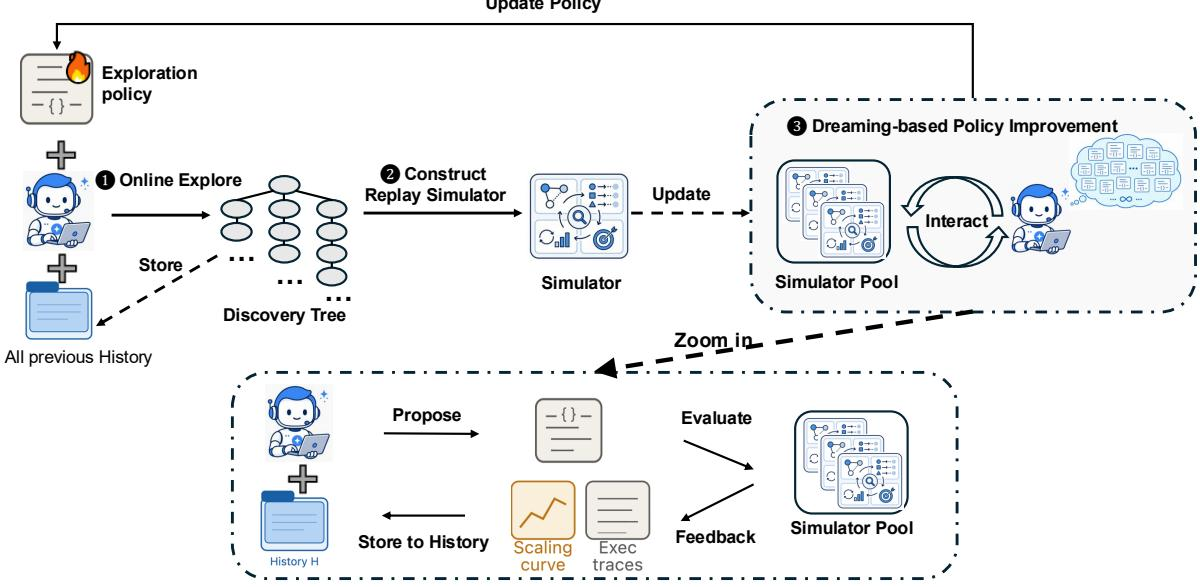
During the online phase, the current policy guides a fixed discovery agent to expand a discovery tree, while a fixed evaluator scores the resulting candidates and provides diagnostic feedback. The resulting discovery tree serves as a replay world in which alternative policies can be evaluated using recorded outcomes. A fixed LLM based policy development agent uses this feedback to revise the exploration policy code, and the best evaluated version is deployed for the next online rollout. Only the exploration policy code changes; the underlying models, evaluator, and execution interfaces remain fixed.
A discovery tree is rooted at r, representing the initial workspace state. Each non-root node ν has exactly one primary parent. This parent identifies where the attempt in ν begins: the discovery agent resumes the parent’s saved workspace and uses its accumulated observations as context to produce a new attempt. Node ν preserves this inherited history and records the outcome of the new generation and evaluation attempt, including the resulting filesystem snapshot, generated artifact, evaluation diagnostics, and score sν.
In both online execution and offline replay, the exploration policy observes a tree T, initially containing only the root, and selects the nodes from which to continue exploration. The eligible nodes form the set A(T)={r}∪{ν∈T:ν is a leaf}. Let W≥1 be the number of parallel workers. The exploration policy’s action is a batch C∈A(T;W), where A(T;W)={C⊆A(T):∣C∣≤W} is the feasible batch set. Each selected node specifies the starting point of one attempt, so the batch determines both where exploration continues and how many attempts are scheduled in parallel.
During an online rollout at iteration t, policy πt guides a new rollout with access to the completed discovery history Ht−1. Let Ttk denote the new discovery tree after k completed decision rounds. At round k, the exploration policy chooses a node batch Ctk∈A(Ttk;W) and each node ν∈Ctk is assigned to a worker. The discovery agent produces a new candidate, and the evaluator assesses the result. These attempts run in parallel, each producing one new child of its selected parent. The rollout ends when the policy selects an empty batch or completes K1 decision rounds. The final tree is recorded as Tt and appended to the history Ht=Ht−1∪{Tt}.
The method then enters the offline phase using this expanded collection of replay worlds. As illustrated in the framework diagram, a single expensive online discovery run can support many inexpensive evaluations of alternative exploration strategies. Within this replay simulator, alternative exploration policies induce different trajectories through the recorded discovery tree. Evaluating such a trajectory requires only revealing the outcomes already stored along the selected branches, rather than rerunning the underlying coding agent and evaluator.
During the offline phase of outer iteration t, the history Ht remains fixed while the method constructs and evaluates M≥1 policy versions πt0,…,πtM−1, starting with πt0=πt. For each policy tree pair, replay resets the policy’s per-rollout state and starts from Tim,0={r}. At each decision, πtm selects a batch Cim,k∈A(Tim,k;W) using the revealed observations. Unlike online execution, replay returns recorded children of the selected nodes deterministically rather than generating new candidates. Replay allows at most K2 decision rounds and terminates when the policy selects an empty batch, the round limit is reached, or all recorded nodes have been revealed.
The replay objective balances discovery quality, execution cost, and parallelism. Let Nim=∣Tim,kim,⋆∣−1 be the number of revealed non-root nodes. For fixed coefficients β1,β2≥0, the replay score is:
Vim=ν∈Tim,kim,⋆maxsν−β1Nim+β2max{1,kim,⋆}Nim.The first term measures the best solution quality attained during replay. The second penalizes the number of attempted generations. The third rewards the average number of attempts executed per decision round, favoring policies that batch useful continuations.
The evaluation score of policy version πtm is its average replay score across the fixed history, Vm=t1∑i=1tVim. The policy development agent examines the replay trajectories and scores of πtm, together with feedback from earlier revisions, to identify successful decisions and recurring failures. It then revises the executable policy code to produce πtm+1. After M revisions, the next online policy is selected from all evaluated versions as πt+1=πtm⋆, where m⋆∈argmaxm∈{0,…,M−1}Vm. The selected policy is then deployed online to collect Tt+1, expanding the history available for the next offline improvement phase.
Experiment
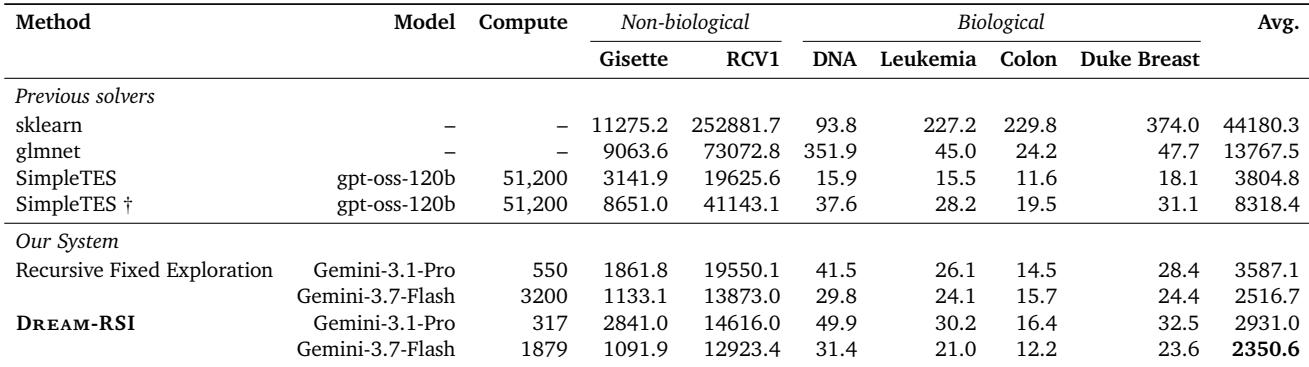
Dream-RSI is evaluated against a controlled baseline, Recursive Fixed Exploration, across algorithm engineering, mathematics optimization, and kernel engineering, using the same discovery agent, initialization, and per-round budgets. In Lasso regularization path discovery, Dream-RSI improves downstream quality-compute trade-offs over the baseline with fewer discovery-agent calls and outperforms standard solvers and SimpleTES. On three mathematical optimization tasks, it matches or exceeds existing systems with substantially lower compute. In GPU kernel engineering, it reaches comparable or higher performance with fewer generations, and further analysis shows that explicit semantic guidance from history underperforms, while the learned exploration policy adaptively adjusts compute allocation across rounds.
The proposed system consistently outperforms previous solvers and baselines across both non-biological and biological benchmarks, achieving substantially lower error scores on most tasks. It also demonstrates improved efficiency in kernel engineering, reaching comparable or higher performance with fewer generations or under similar budgets. The analysis suggests that adaptive exploration policies are more effective than explicit semantic guidance for long-horizon discovery. The proposed system achieves the lowest average error among all methods, with particularly large gains over prior solvers like sklearn and glmnet. On kernel engineering tasks, the system either matches final performance with fewer generations or achieves higher performance under comparable budgets. Explicit directional guidance from historical trajectories consistently underperforms unguided exploration, indicating that strong semantic biases can hinder discovery. The exploration policy adapts over rounds, reducing compute when progress is made and increasing effort again when performance plateaus.
Dream-RSI performs competitively across three mathematical discovery tasks, achieving the best Sum-Difference score among compared methods, matching the top Circle Packing result, and remaining competitive on Autocorrelation. Notably, it attains these results with far fewer generations than a state-of-the-art baseline, indicating strong efficiency and generalization. Dream-RSI achieves the highest Sum-Difference score among all compared methods. On Circle Packing, Dream-RSI matches the strongest reported result in the table. For Autocorrelation, Dream-RSI stays competitive with existing systems while using far fewer generations than the leading baseline.
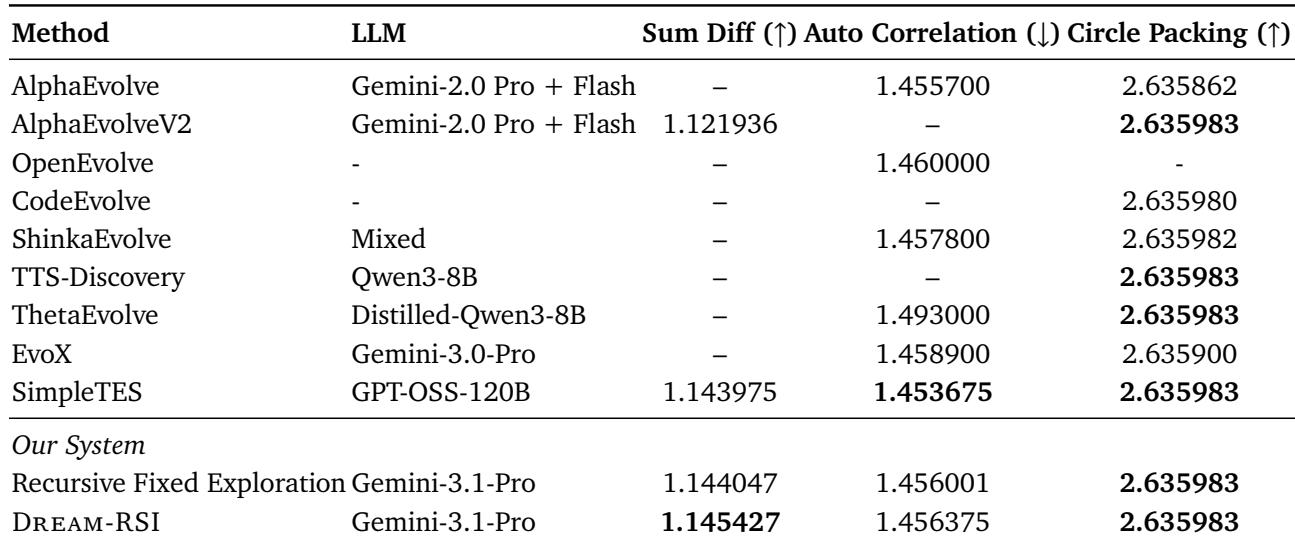
The proposed system outperforms prior solvers and baselines across both non-biological and biological benchmarks, achieving lower error scores on most tasks and improved kernel engineering efficiency, either matching final performance with fewer generations or exceeding it under similar budgets. Adaptive exploration policies prove more effective than explicit semantic guidance, as directional historical cues consistently underperform unguided exploration. On three mathematical discovery tasks, the system (Dream-RSI) achieves the best Sum-Difference score, matches the top Circle Packing result, and remains competitive on Autocorrelation, all while using far fewer generations than a leading baseline, indicating strong efficiency and generalization.