Command Palette
Search for a command to run...
DataFlex-RL: RLVR 데이터 정책을 위한 평가 플랫폼
DataFlex-RL: RLVR 데이터 정책을 위한 평가 플랫폼
Hao Liang Mingrui Chen Hengyi Feng Meiyi Qiang Wentao Zhang
초록
검증 가능한 보상을 사용하는 강화학습(RLVR)의 데이터 정책은 어떤 롤아웃을 사용할지, 가중치를 얼마나 강하게 부여할지, 또는 어떤 도메인이 다음 배치를 제공할지 변경한다. 본 논문에서는 동일한 GRPO 레시피 하에서 이러한 선택들을 비교하기 위한 평가 플랫폼인 DataFlex-RL을 소개한다. 주요 실험에서는 Qwen2.5-7B-base 모델과 12개의 수학, 논리, 과학 벤치마크를 대상으로 12개의 일치된 시드를 사용하여 13가지 구성을 평가한다. 균일 GRPO는 훈련되지 않은 체크포인트 대비 도메인 균형 평균 정확도(Overall)를 7.76포인트 향상시킨다. 8가지 선택 또는 재가중치 부여 방법 중 어떤 것도 균일 샘플링 대비 0을 제외하는 쌍체 95% 신뢰 구간을 갖지 못했으며, 3가지 적응형 혼합 방법 중 어떤 것도 해당 정밀도에서 고정된 균등 혼합 대비 개선을 보이지 못했다. 보정된 12-시드 Llama-3.1-8B-base 확장 실험에서는 추가 방법들을 원래 대조군과 동일한 점수 척도에 배치했지만, 관측된 평균에서 공통된 승자는 나타나지 않았다. 또한 수학 중심의 6개 벤치마크 요약(논리 벤치마크 없이 5개의 수학 벤치마크와 GPQA-Diamond로 구성)과 도메인 균형 12개 벤치마크 요약을 사용하여 9개의 Qwen2.5-7B-Instruct 실행 결과를 재계산함으로써 평가 민감도를 정량화한다. 이들의 순위는 음의 상관관계(ρ = -0.33)를 보이는 반면, 12개 벤치마크 전체를 유지한 요약들은 대체로 일치한다. 본 연구에서 조사된 통제된 설정 전반에 걸쳐, 데이터 정책을 변경하면 훈련 과정이 측정 가능하게 변화하지만 균일 훈련 대비 재현 가능한 개선을 가져오지는 않는다.
One-sentence Summary
DataFlex-RL, an evaluation platform for systematically comparing data policies for reinforcement learning with verifiable rewards under the same GRPO recipe, reveals that on Qwen2.5-7B-base across 12 math, logic, and science benchmarks, no selection, reweighting, or adaptive mixing policy significantly outperforms uniform sampling over 12 matched seeds.
Key Contributions
- DataFlex-RL is an evaluation platform that isolates and compares data-processing policies (selection, reweighting, mixture optimization) for reinforcement learning with verifiable rewards under a shared GRPO recipe.
- A controlled experiment on Qwen2.5-7B-base with 12 seeds and 12 math, logic, and science benchmarks shows uniform GRPO improves domain-balanced accuracy by 7.76 points, but none of eight selection/reweighting methods yields a paired 95% confidence interval excluding zero relative to uniform sampling, and none of three adaptive mixtures improves over a fixed equal mixture at that precision.
- Recomputing nine Qwen2.5-7B-Instruct runs with a math-heavy six-benchmark summary produces rankings negatively correlated (ρ = -0.33) with the domain-balanced 12-benchmark summary, while summaries retaining all 12 benchmarks largely agree, quantifying how benchmark composition affects conclusion stability.
Introduction
Reinforcement learning with verifiable rewards (RLVR) post-trains reasoning models by scoring multiple responses per prompt and constructing group-relative advantages, typically through Group Relative Policy Optimization (GRPO). This encourages diverse interventions that filter, reweight, or adapt the mix of training data to emphasize prompts near the policy’s decision boundary. The challenge is that prior methods are often embedded in custom recipe changes—varying base models, verifiers, or optimization settings—making it unclear whether the reported gains come from the data policy itself or from surrounding confounds. On-policy evaluation compounds this: the utility signal is noisy and shifts as the policy learns, and small evaluation benchmark differences or seed variation can reverse the apparent winner. The authors build DataFlex-RL, a controlled evaluation platform that holds the GRPO recipe fixed and compares 13 data policies (selection, reweighting, and mixture adaptation) under matched seeds and a unified benchmark suite. They find that none of these policies shows a reproducible improvement over uniform sampling at the achieved precision, and they document how benchmark coverage choices can change which method appears best.
Dataset
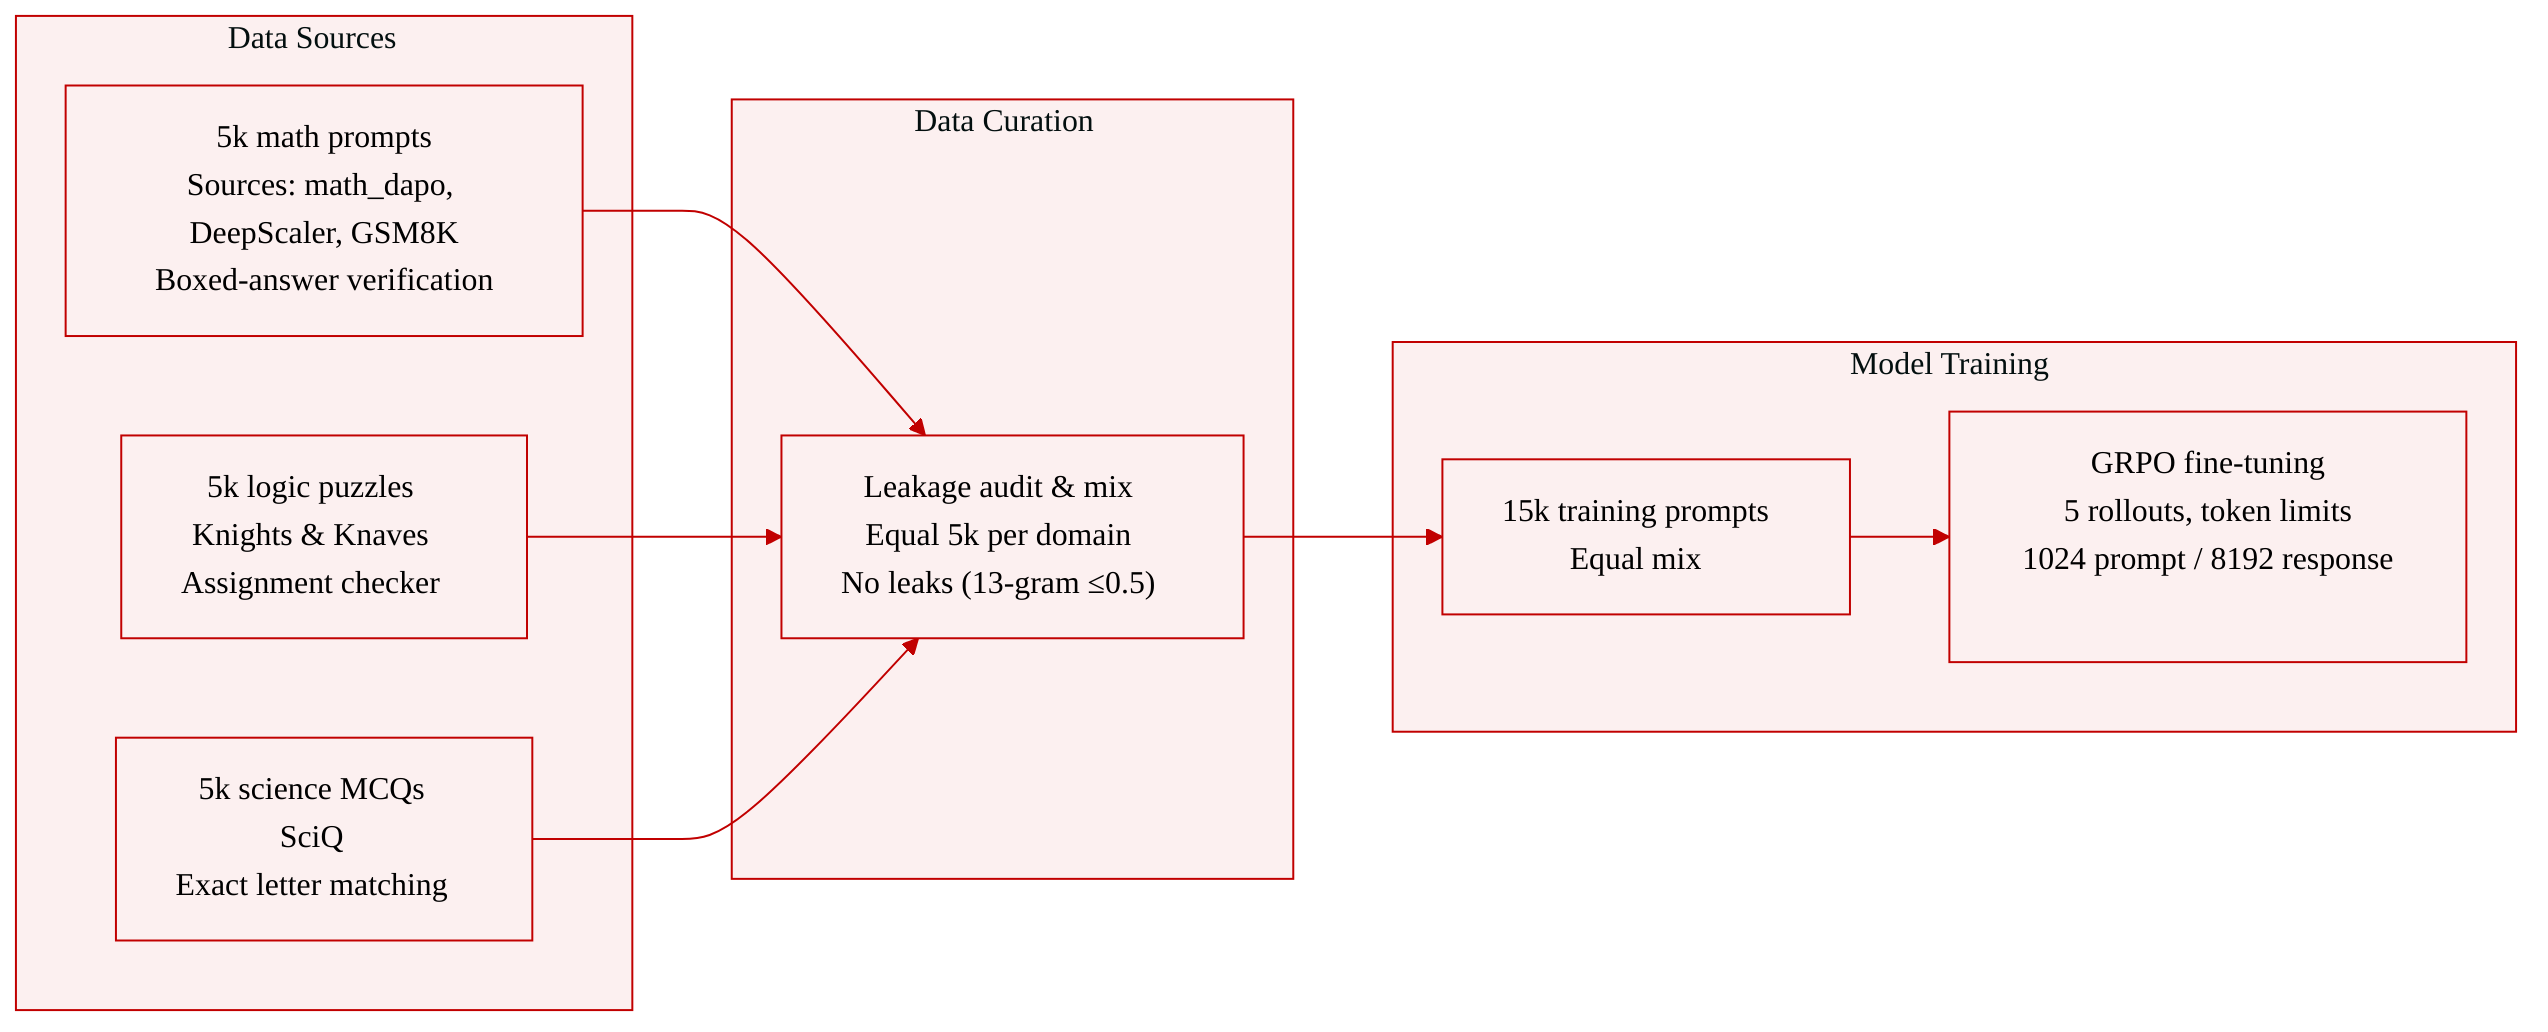
The authors construct a clean training corpus of 15,000 prompts spanning three domains, equally split among math, logic, and science. All prompts are verified to have no leakage into the evaluation benchmarks.
- Math (5,000 prompts): sourced from math_dapo, DeepScaler, and GSM8K. Every prompt is formatted with boxed-answer verification (the expected output is enclosed in
\boxed{}). - Logic (5,000 prompts): procedurally generated Knights & Knaves puzzles. Each puzzle comes with an assignment checker that validates the solution.
- Science (5,000 prompts): taken from the SciQ multiple-choice dataset. The verification relies on exact letter matching against the correct option.
Decontamination and metadata
- The training prompts were audited against all 12 evaluation benchmarks. No exact or normalized matches were found, and no pair had a 13-gram Jaccard similarity above 0.5.
- Every prompt record retains source and domain metadata for transparency.
Usage in training
- The full 15,000-prompt corpus is used as the training set for GRPO-based experiments.
- During training, each prompt is rolled out 5 times, and generation is constrained by a 1024-token prompt limit and an 8192-token response limit.
- The three subsets are mixed at equal proportions; no additional cropping or re-balancing is applied beyond the original equal split and the per-domain verification format.
Method
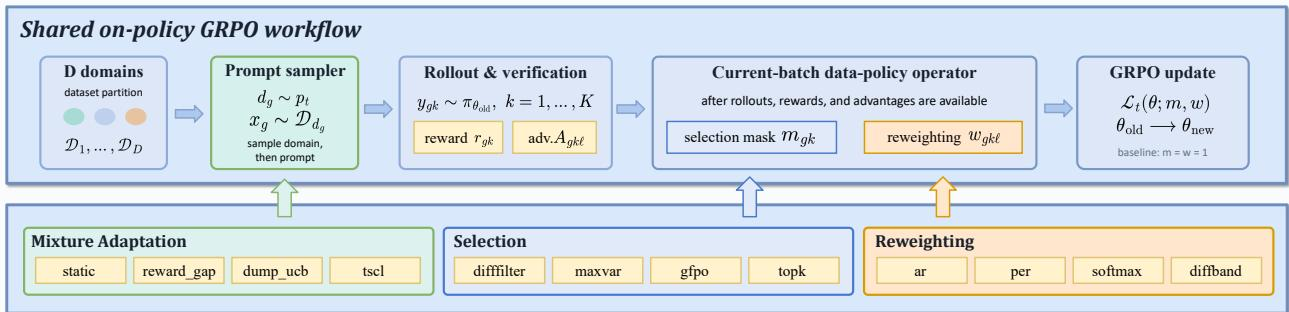
The authors introduce a flexible framework for RL with verifiable rewards (RLVR) training that breaks the standard GRPO update into three intervention points: selection, reweighting, and mixture adaptation. The baseline training procedure is straightforward: it samples math, logic, and science prompts with equal probability, generates K=5 responses per prompt, verifies their rewards, and applies the standard GRPO loss to every valid response token. Each intervention family changes a distinct part of this pipeline while leaving the rest intact, enabling controlled comparisons of how different RLVR data policies alter learning.
Selection decides which generated responses participate in the current update. After rollout and reward verification, a binary mask mgk∈{0,1} is assigned to each response k of prompt g; a zero mask removes that response from the loss computation. The selected loss is
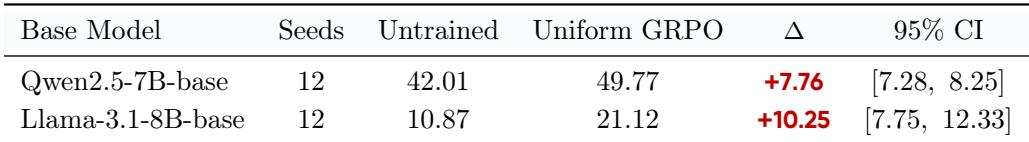
Lsel=GK1g=1∑Gk=1∑KLgkmgkℓ=1∑LgkℓgkℓGRPO,where Lgk is response length and ℓgkℓGRPO denotes the per-token GRPO loss. The baseline simply sets all mgk=1. Implemented selection variants include difffilter, maxvar, gfpo, and topk, which use different heuristics to decide which responses or entire prompt groups to keep.
Reweighting retains all generated responses but modulates their influence on the loss. A weight wgkℓ≥0 is assigned per token (or response-wide), and the reweighted loss becomes
Lrew=GK1g=1∑Gk=1∑KLgk1ℓ=1∑LgkwgkℓℓgkℓGRPO.In practice, weights are normalized to have mean one over the relevant batch units. This family covers methods like ar (Advantage Reweighting), per, softmax, and diffband, which convert a signal such as mean absolute advantage into a continuous importance weight instead of a hard keep/discard decision.
Mixture adaptation operates at a different temporal granularity: it does not alter the current update but instead adjusts the domain distribution from which future prompts are sampled. Let Dd be the prompt set for domain d (e.g., math, logic, science), and let pt(d) denote the sampling probability at step t, with ∑dpt(d)=1. The training objective under this mixture is
Lmix,t(θ)=d=1∑Dpt(d)Ex∼Dd,y1:K∼πθold(⋅∣x)[K1k=1∑KLk1ℓ=1∑LkℓkℓGRPO(θ)].The fixed baseline uses pt(d)=1/D throughout training, corresponding to a uniform (1/3,1/3,1/3) mixture over three domains. Mixture methods dynamically update pt based on domain-level signals computed over a rolling window of recent observations. For example, they may track the mean reward rˉt,d, mean absolute advantage aˉt,d, or the slope of reward st,d for each domain, and then reallocate sampling probability to favor domains where learning is still promising. Implemented mixture strategies draw inspiration from DoReMi, DUMP, and Teacher–Student Curriculum Learning.
The three intervention families are complementary: selection and reweighting act after rollout to filter or rescale the loss signal, while mixture adaptation operates before the next rollout to control which data the model sees next. This design enables the authors to compare, for instance, whether a signal like the mean absolute advantage agk is more effective when used for hard selection (topk) or for soft reweighting (softmax). The signals themselves are computed from readily available rollout statistics, such as the group solve rate qg=K1∑k=1K1[rgk>0.5], the response-level mean absolute advantage agk=Lgk1∑ℓ=1Lgk∣Agkℓ∣, or the rollout policy’s token probabilities. By systematically varying the intervention point while holding the signal fixed, the framework provides a controlled testbed for understanding how data-policy design shapes RLVR training.
Experiment
The evaluation compares data selection, reweighting, and adaptive mixture policies during GRPO training on base models using matched seeds and a multi-domain benchmark suite. The primary experiment, using Qwen2.5-7B-base with 12 seeds, finds that none of these policies yields a reproducible accuracy gain over uniform sampling or a fixed data mixture, even though GRPO itself is effective. Cross-model checks on Llama and various Qwen scales show no consistent winner, and an aggregation analysis reveals that the apparent best method depends heavily on which evaluation domains are included, cautioning against domain-omitted comparisons.
Thirteen configurations from three families—selection, reweighting, and mixture adaptation—show that no single method dominates. Relative performance flips with model scale and evaluation domain: a filter that underperforms the baseline on a small model can improve on a larger one, and the top-ranked method changes when evaluation coverage drops a domain. difffilter can fall below the baseline on 1.5B and 3B models but edges above it on 7B and 14B models. maxvar stays below the baseline at every model size tested. tscl lags behind a static mixture at 1.5B but outperforms it on larger Qwen models and on Llama-3.2-3B. A math-heavy benchmark suite ranks topk and diffband highest, while a domain-balanced suite ranks gfpo and difffilter highest, with negative rank correlation.
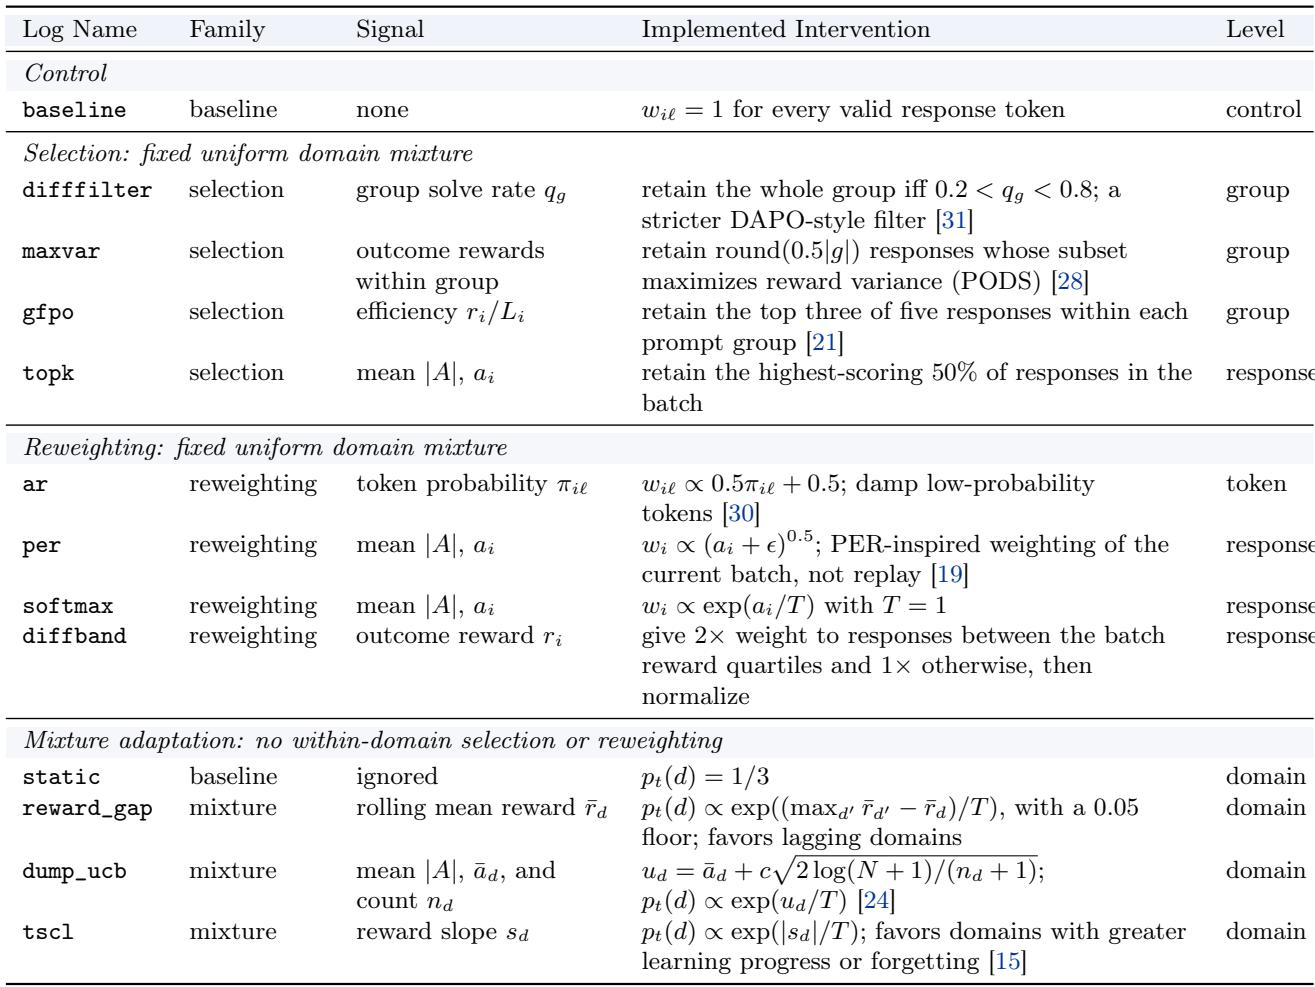
Uniform GRPO training substantially lifts performance over untrained checkpoints in both base models, confirming non-trivial training headroom. The improvement on Qwen2.5-7B-base is both large and precisely estimated, making it the primary inferential setting. These results rule out the possibility that the examined data policies show null effects simply because the model cannot learn. Uniform GRPO improves Qwen2.5-7B-base by over 7 points with a narrow 95% confidence interval, while Llama-3.1-8B-base improves by over 10 points but with a wider interval. Because the gain for Qwen2.5-7B-base is substantial and estimated more precisely than for Llama-3.1-8B-base, it serves as the primary test model for comparing data policies across the full set of methods and seeds.
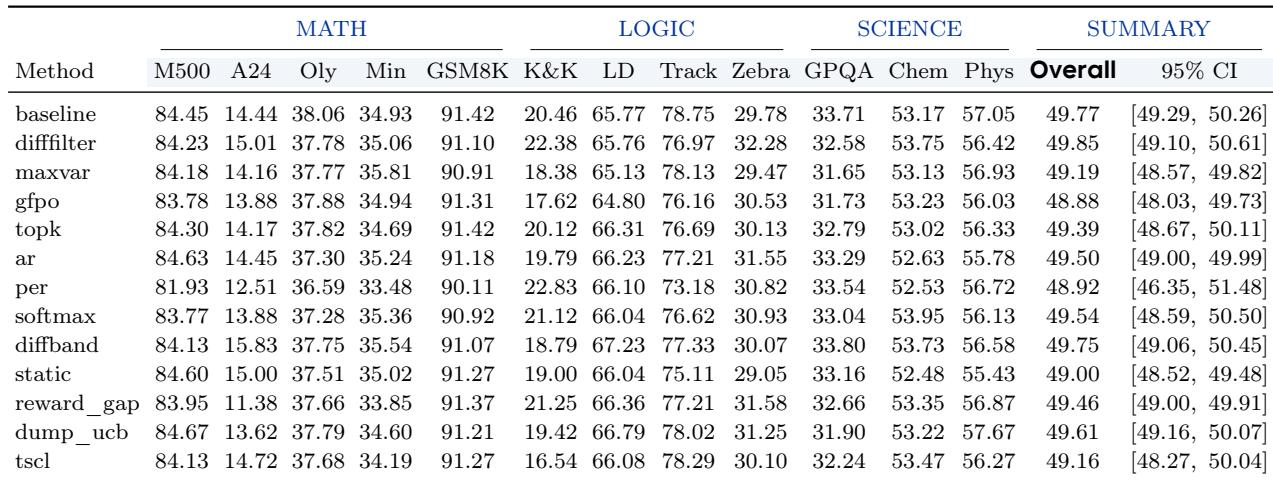
The six data-filtering methods achieve similar overall scores on Qwen2.5-7B-base, with small differences and broadly overlapping confidence intervals. Relative strengths vary across math, logic, and science domains, so no single method consistently excels everywhere. This domain sensitivity means that a summary omitting logic can rank methods differently than the full 12-benchmark comparison. Overall scores of all methods fall within a tight band (48.9 to 49.9) with 95% confidence intervals that overlap substantially. The best overall mean (difffilter, 49.85) is only marginally above the baseline (49.77), while maxvar and gfpo are slightly below it. No method is uniformly strongest across domains: relative strength on logic benchmarks does not predict relative strength on math or science. When logic benchmarks are excluded from the summary, the apparent leading method can change compared to the domain-balanced ranking.
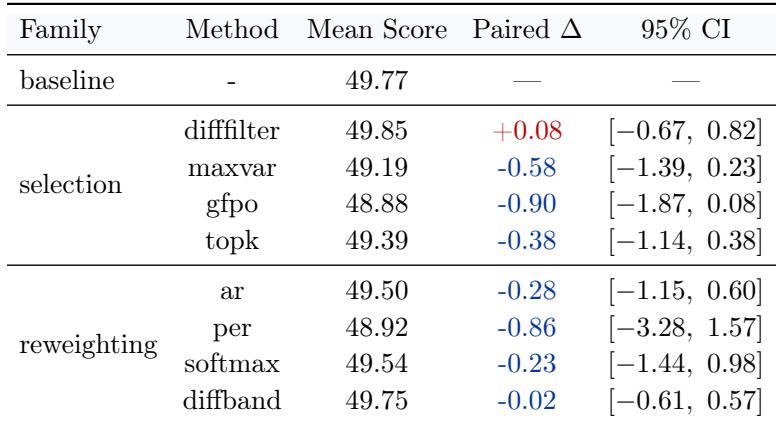
When evaluated with 12 matched seeds, neither selection nor reweighting methods yield reproducible gains over uniform sampling on Qwen2.5-7B-base. The nine policy means cluster within one point, a fraction of the large uniform GRPO improvement, and every paired confidence interval comfortably includes zero. All eight selection and reweighting differences relative to uniform sampling have confidence intervals that cross zero, so no method reliably outperforms the baseline. Policy means span only 0.97 points, while the gain from uniform GRPO itself is 7.76 points, showing that the choice of data filtering strategy adds negligible benefit. Extending the comparison from three to twelve seeds reversed the selector ordering: topk moved from first to below the baseline, and difffilter rose to the highest mean, though still not significant. Reweighting methods produced point estimates below uniform, ranging from roughly -0.9 to near zero, but none excluded a nil effect.
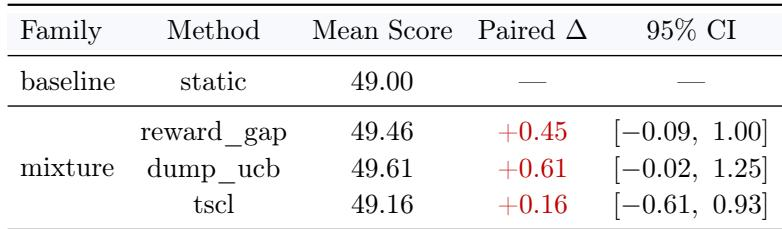
On a 7B base model, three adaptive mixture methods that varied the proportions of math, logic, and science prompts during training all produced slightly higher mean scores than a fixed equal mixture, but every paired 95% confidence interval includes zero and the means differ by at most 0.61 points. Changing the training-domain mix did not yield a reproducible accuracy improvement in this setting. All adaptive mixtures (reward_gap, dump_ucb, tscl) have positive point estimates relative to the static equal mixture, but none achieves statistical significance as every confidence interval crosses zero. The score differences are narrow: the adaptive methods' means span only 0.61 points, and the largest improvement is +0.61 with a confidence interval that includes no effect.
The study compares data selection, reweighting, and mixture adaptation strategies for GRPO training across math, logic, and science benchmarks. Although uniform training yields large improvements over base models, no filtering or mixture method consistently outperforms uniform sampling: performance differences are small, method rankings reverse with model scale and benchmark domain, and all pairwise confidence intervals include zero when tested with multiple seeds. The findings indicate that the examined data policies offer negligible and non-reproducible gains beyond uniform training in this setting.