Command Palette
Search for a command to run...
DriveZero: 인간 시연을 넘어서는 종단간 주행
DriveZero: 인간 시연을 넘어서는 종단간 주행
초록
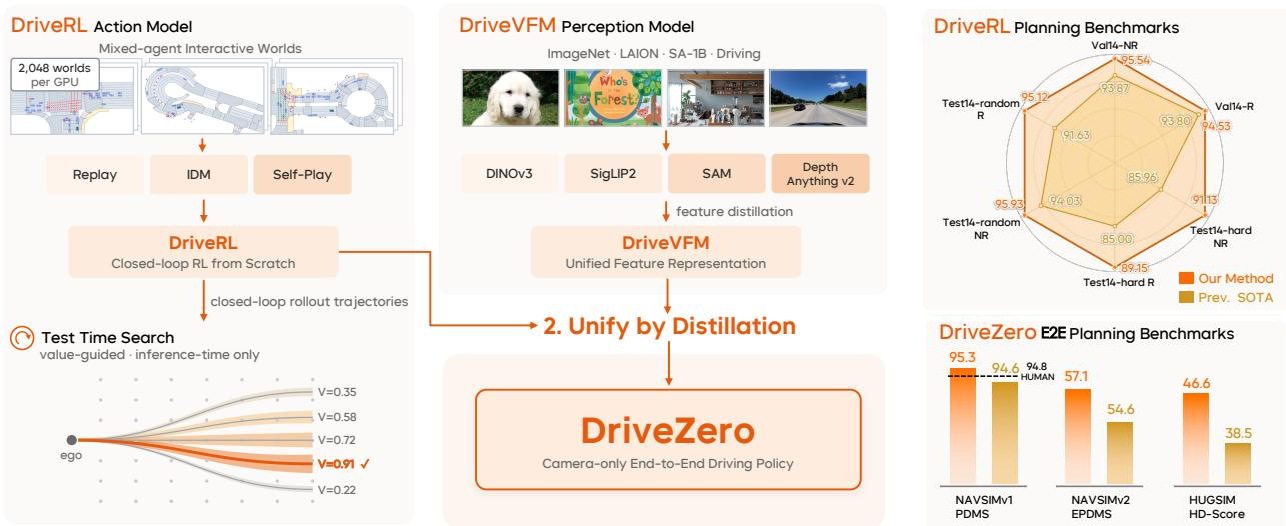
대부분의 종단간 자율주행 시스템은 인간의 주행 로그를 모방하여 학습하므로, 학습된 행동은 기록된 궤적의 품질과 행동 범위에 의해 제약을 받습니다. 본 보고서는 인간의 시연을 넘어서는 주행 행동을 학습하는 종단간 시스템인 DriveZero를 제시합니다. 이 시스템은 주행을 인식 모델과 행동 모델로 분해하고, 각각에 가장 적합한 방식으로 사전 학습한 후, 이를 하나의 종단간 플래너로 결합합니다. 두 모델은 서로 다른 학습 방식을 요구합니다. 인식은 세계를 이해해야 하므로 방대하고 다양한 시각 데이터의 이점을 얻으며, 행동은 세계와 상호작용해야 하므로 폐루프 피드백이 필요합니다. 행동 측면에서, 우리는 혼합 에이전트 폐루프 강화학습 프레임워크인 DriveRL을 소개합니다. 이는 실제 주행 로그를 상호작용 가능한 세계로 변환하고, 특권(privileged) 교사 정책이 폐루프 롤아웃을 통해 PPO로 학습됩니다. 인식 모델의 경우, DriveVFM은 DINOv3, SigLIP2, SAM, Depth Anything V2를 포함한 여러 동결된 비전 기반 모델을 원시 이미지에서만 단일 백본으로 통합하며, 작업별 주석이 필요 없습니다. 그런 다음 DriveZero는 이 둘을 통합합니다. 즉, 롤아웃된 궤적을 통해 동결된 DriveRL 교사를 증류하는 카메라 전용 플래너입니다. 목표 조건부 교사는 또한 증강된 주행 의도로 질의할 수 있어, 로그 데이터가 제공할 수 없는 다양하고 목표 일관된 감독을 생성합니다. nuPlan에서, 가치 기반 테스트 시간 행동 탐색을 사용하는 DriveRL은 비반응 및 반응 모드 모두에서 Val14, Test14-hard, Test14-random 커뮤니티 분할에서 평균 점수 93.57을 달성하여, 세 분할 모두에서 Log-Replay 전문가를 능가합니다. DriveZero는 인간 궤적 감독 없이 NAVSIMv1, NAVSIMv2 및 폐루프 HUGSIM 벤치마크에서 최첨단 성능을 달성합니다. navtest에서 95.3 PDMS로 인간 운전자(94.8)를 능가하고, navhard에서 57.1 EPDMS, HUGSIM에서 제로샷 46.6 HD-Score를 기록합니다.
One-sentence Summary
Researchers at Xiaomi EV present DriveZero, an end-to-end camera-only autonomous-driving system that surpasses human demonstrations by decomposing driving into DriveVFM, a perception backbone consolidating frozen vision models (DINOv3, SigLIP2, SAM, Depth Anything V2), and DriveRL, a mixed-agent closed-loop PPO teacher policy trained on interactive worlds and distilled via goal-conditioned rollouts, achieving state-of-the-art scores on nuPlan (93.57), NAVSIMv1/v2 (95.3 PDMS, exceeding the human driver’s 94.8), and HUGSIM (46.6 HD-Score) without any human trajectory supervision.
Key Contributions
- DriveZero decomposes end-to-end driving into a perception model (DriveVFM) and an action model (DriveRL), pretraining each in its best-suited regime and unifying them through trajectory distillation into a camera-only planner without human trajectory supervision.
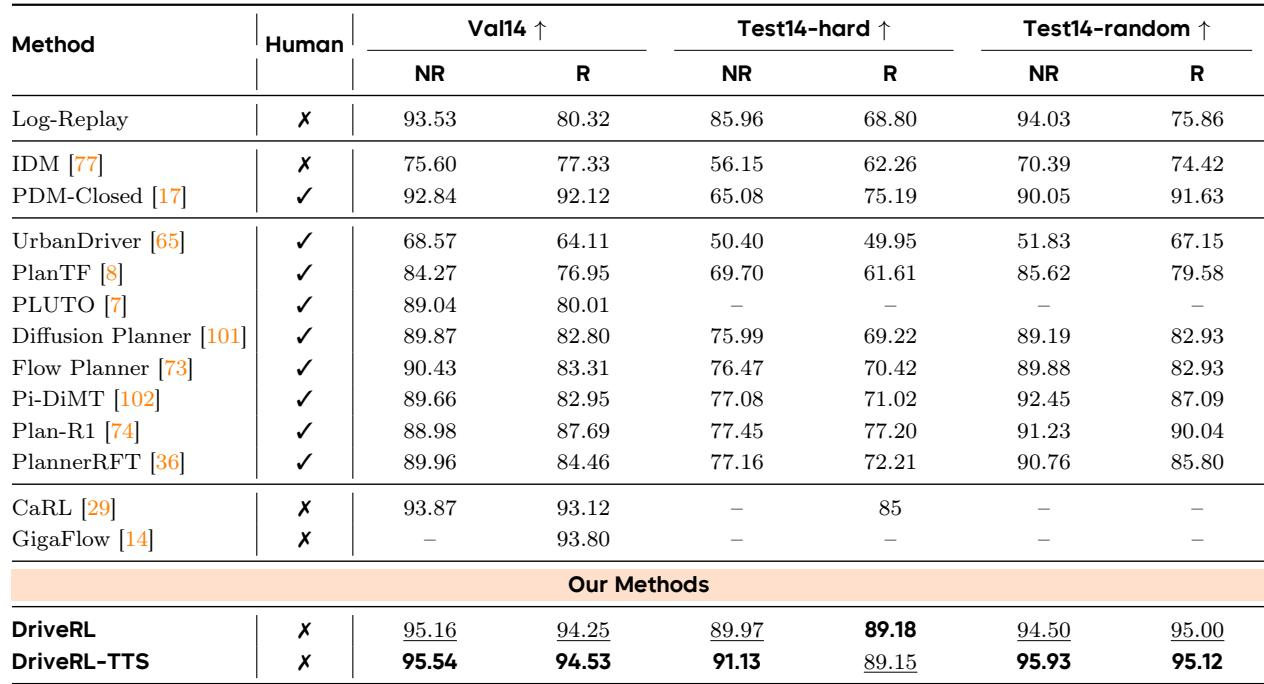
- DriveRL converts real driving logs into interactive worlds, trains a goal-conditioned privileged teacher with PPO, and uses value-guided test-time action search, exceeding the Log-Replay expert on all three nuPlan community splits in both non-reactive and reactive modes with a mean score of 93.57.
- DriveVFM distills frozen vision foundation models (DINOv3, SigLIP2, SAM, Depth Anything V2) into a single backbone from raw images alone, avoiding task-specific annotations, and DriveZero achieves state-of-the-art results on NAVSIMv1, NAVSIMv2, and HUGSIM, including 95.3 PDMS on navtest (surpassing the human driver at 94.8), 57.1 EPDMS on navhard, and 46.6 HD-Score zero-shot on HUGSIM.
Introduction
End-to-end autonomous driving systems typically learn to map sensor inputs and navigation goals directly to vehicle control by imitating human driving logs. This approach is scalable and stable, but it relies entirely on recorded trajectories as supervision, which limits behavior to the quality and coverage of the logs. Each logged scene captures only one possible future even when multiple actions are valid, safety-critical events and recovery maneuvers are rare, and states induced by the learned policy are absent from the offline data, causing errors to compound once the policy leaves the demonstration distribution.
Reinforcement learning (RL) offers an alternative by optimizing explicit objectives through closed-loop interaction, allowing a policy to observe the consequences of its own actions and learn from failures. However, prior work in this area faces challenges: scaling RL to real-world driving is computationally expensive, many methods require placing visual policies inside rendered closed-loop environments, and transferring behavior learned in privileged or vectorized simulations to camera-based policies often introduces domain gaps. Additionally, visual representations for driving are typically inherited from general-purpose backbones or trained with task-specific labels, which may not capture the full structure of driving scenes.
The authors propose DriveZero, an end-to-end driving system whose behavior is not bounded by human demonstrations. They decompose driving into a perception model and an action model, each pretrained in the regime that suits it. DriveVFM learns visual representations from raw images by distilling frozen vision foundation models (including DINOv3, SigLIP2, SAM, and Depth Anything), removing the need for task-specific perception labels. DriveRL learns driving behavior from scratch through closed-loop RL in log-initialized interactive worlds, without relying on human trajectory supervision. The two are reunited through trajectory distillation, where the frozen teacher's rollouts are distilled into a camera-only planner, avoiding the need to place the camera student inside a rendered closed-loop training environment.
Dataset
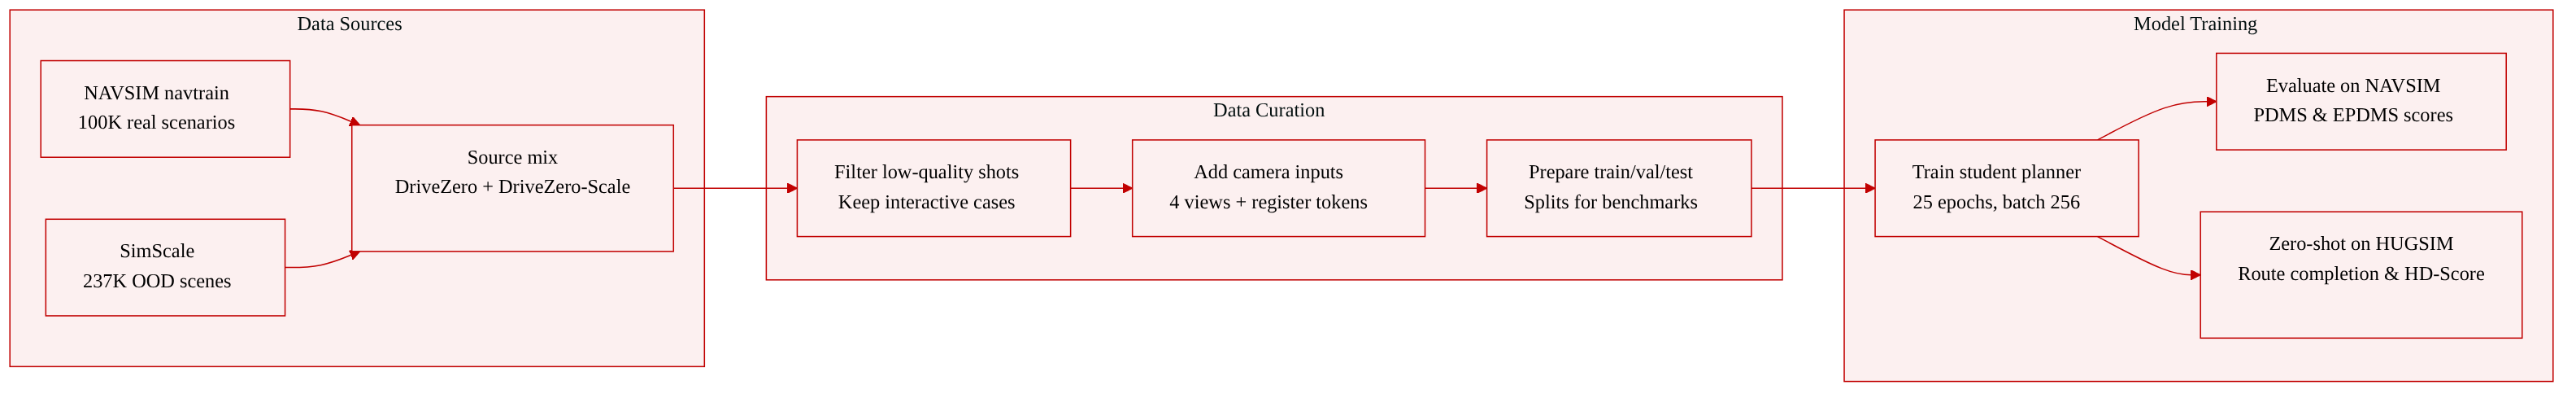
The authors construct the DriveZero training dataset from two primary sources. The first is the navtrain split from NAVSIM, built on nuPlan, which contains 100K interactive real-world scenarios. Instead of using logged human driving trajectories for supervision, the student model is trained on trajectories accumulated from DriveRL rollouts. The second source adds 237K out-of-distribution (OOD) simulation scenes from SimScale for data scaling; the resulting variant is called DriveZero-Scale.
For input, DriveZero uses four camera views: CAM_F0, CAM_B0, CAM_L0, and CAM_R0. The planner consists of 64 trajectory proposals, a 256-dimensional planning representation, and a 4-layer proposal decoder. Camera features are compressed using 16 register tokens per camera, following the DrivoR approach. During training, the DriveVFM backbone remains frozen, and only rank-32 Q/V LoRA adapters are trainable. The model is trained for 25 epochs with a batch size of 256, using the AdamW optimizer.
The paper evaluates the camera-only student on three benchmarks. NAVSIMv1 navtest (built from nuPlan as a subset of OpenScene) and NAVSIMv2 navhard provide pseudo closed-loop evaluation under standard sensor-input protocols. On navtest, the authors report the Predictive Driver Mode Score (PDMS) and its components: no-collision, drivable-area compliance, time-to-collision, comfort, and ego-progress. On navhard, they report the two-stage Extended Predictive Driver Model Score (EPDMS) with safety, compliance, progress, and planning-quality components; the second stage tests robustness to Gaussian-Splatting-based ego-state perturbations. They also evaluate zero-shot transfer on HUGSIM, a true closed-loop benchmark reconstructed from scenes in KITTI-360, nuScenes, PandaSet, and Waymo, reporting route completion and HD-Score over Easy, Medium, Hard, and Extreme scenarios. Zero-shot means no HUGSIM-specific finetuning is used.
Method
The authors propose a decomposed end-to-end autonomous driving framework that separates perception, action learning, and deployment. The methodology consists of three core components: DriveRL for learning a privileged teacher policy via closed-loop reinforcement learning, DriveVFM for pretraining a robust visual backbone without task-specific annotations, and DriveZero for distilling the teacher behavior into a deployable camera-only planner.
DriveRL serves as the privileged action model. It operates on structured scene observations, including ego kinematics, surrounding traffic participants, and local vector maps. Using a mixed-agent simulator built from real driving logs, the authors train the teacher policy with Proximal Policy Optimization (PPO). The policy outputs bounded Beta distributions over longitudinal jerk and steering-angle rate, directly controlling the vehicle without trajectory refinement. This closed-loop training allows the teacher to optimize behavior beyond human demonstrations and recover from perturbed states.
To bridge the gap between the privileged structured state and deployable camera inputs, the authors introduce DriveVFM. Instead of relying on manually annotated auxiliary perception tasks, DriveVFM consolidates frozen vision foundation models, such as DINOv3, SigLIP2, SAM, and Depth Anything V2, into a single driving backbone. By matching the features of these heterogeneous models through an agglomerative distillation process, the backbone acquires driving-relevant semantics, geometry, and spatial structure from a diverse corpus of web-scale and driving imagery.
The final component, DriveZero, reunifies the perception and action models through multimodal trajectory distillation. As shown in the figure below:
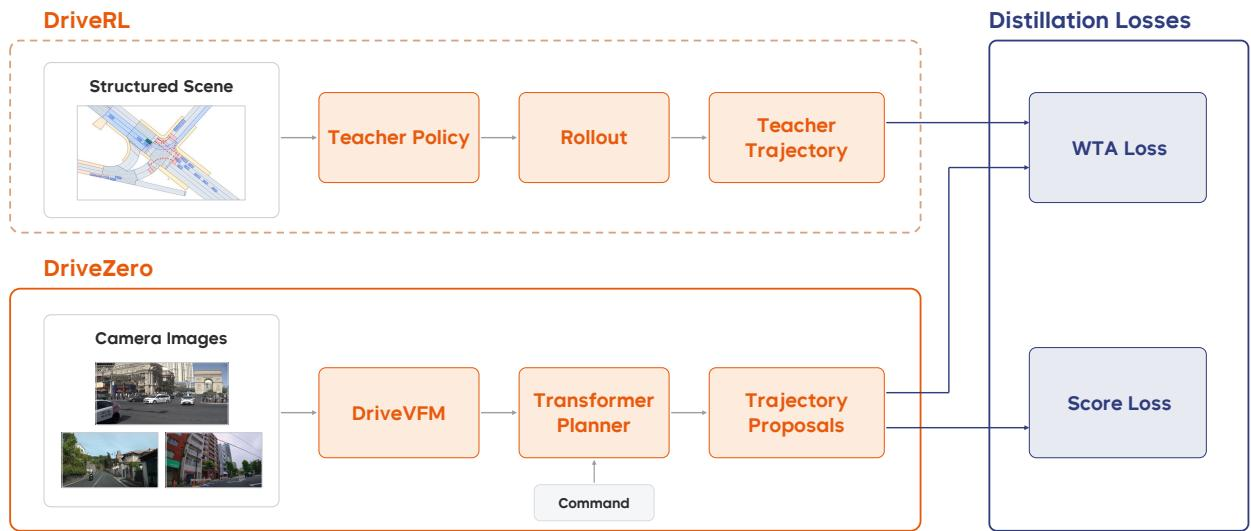
DriveZero functions as a camera-only end-to-end planner trained open-loop on logged frames. It takes multi-view camera images, ego kinematics, and a navigation command as inputs. The DriveVFM backbone, fine-tuned with Low-Rank Adaptation, encodes the images, and the resulting visual tokens are enriched with 3D position embeddings. Learnable registers compress these tokens into a compact set of scene tokens. The ego kinematics and navigation command are embedded into an ego token, which is added to multiple learnable trajectory queries. A trajectory decoder then maps these queries to M candidate trajectory proposals via cross-attention to the scene tokens.
During training, the frozen DriveRL teacher receives the structured state and a goal point, rolling out a trajectory with background actors following the driving log. This teacher trajectory serves as the regression target for the student. The authors employ a winner-takes-all objective for trajectory distillation. Each candidate proposal is compared with the teacher trajectory, and only the closest proposal contributes to the trajectory loss:
Ltraj=mmindist(τ^m,τT)where τ^m is the m-th proposal and dist(⋅,⋅) is the L1 distance averaged over points.
In parallel, a separate scoring decoder evaluates each candidate trajectory. It predicts six driving-quality components covering collision avoidance, drivable-area compliance, progress, time to collision, comfort, and driving-direction compliance. These components are supervised by their corresponding Planning Metric-based targets using a binary cross-entropy loss:
Lscore=M1m=1∑Mk=1∑6BCE(σ(s^mk),smk)The complete training objective combines both losses:
LDriveZero=λtrajLtraj+λscoreLscoreAt inference time, the system selects the candidate with the highest predicted aggregate score. Furthermore, because the teacher is goal-conditioned, the authors augment the route intent during training to generate diverse and goal-consistent supervision signals, significantly expanding the available training data beyond the single realized trajectory in human logs.
Experiment
The evaluation validates the proposed decomposition into a reinforcement-learned action model, a perception model pretrained without task annotations, and a distillation step that unifies them into a camera-only planner. DriveRL, trained in closed-loop on nuPlan with mixed-agent worlds, exceeds the Log-Replay expert across all six evaluation settings, with test-time action search further improving the mean score. DriveZero, the camera-only student, reaches state-of-the-art results on NAVSIMv1, NAVSIMv2, and HUGSIM without any human trajectory supervision, and scaling with out-of-distribution simulation data pushes it further, outperforming the human driver on navtest. Ablations confirm that the visual foundation model, cumulative teacher contributions, and goal-augmented distillation from the RL teacher each provide consistent gains, with the latter surpassing human-trajectory supervision.
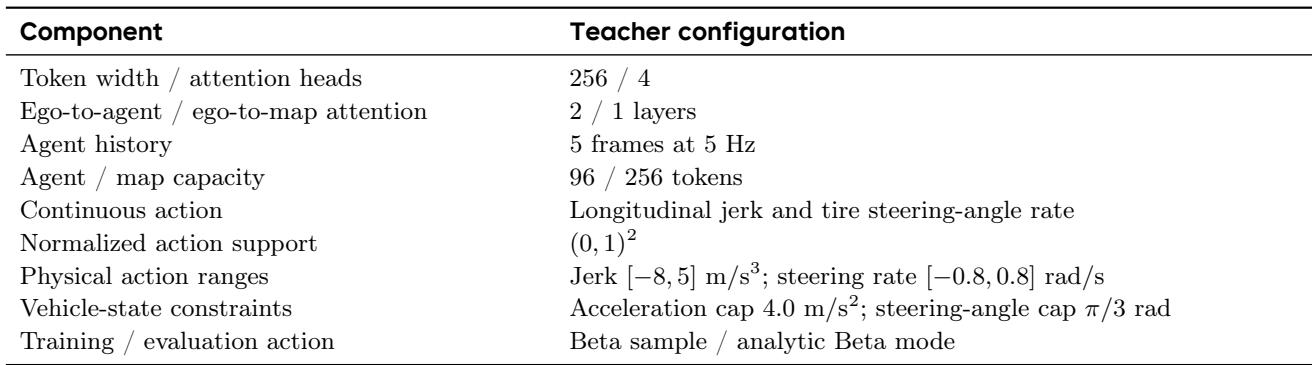
DriveRL uses a transformer-based policy with 256 token width and 4 attention heads, incorporating ego-to-agent and ego-to-map attention layers, and outputs continuous control via longitudinal jerk and steering-angle rate. Training is conducted on 96 GPUs with 2,048 parallel worlds, using a mix of log-replay and IDM scenes, and the policy is trained with PPO over 2,400 updates for about 21 hours. The model uses a 256-token width with 4 attention heads and 2 ego-to-agent plus 1 ego-to-map attention layers. Agent history spans 5 frames at 5 Hz, with capacities of 96 agent tokens and 256 map tokens. Control outputs are continuous, with jerk limited to [-8, 5] m/s³ and steering rate to [-0.8, 0.8] rad/s. Training uses a 1:1 mixture of log-replay and IDM scenes, with 110-step rollouts at 5 Hz. The policy is optimized with PPO over 4 epochs per update, using a discount factor of 0.99.
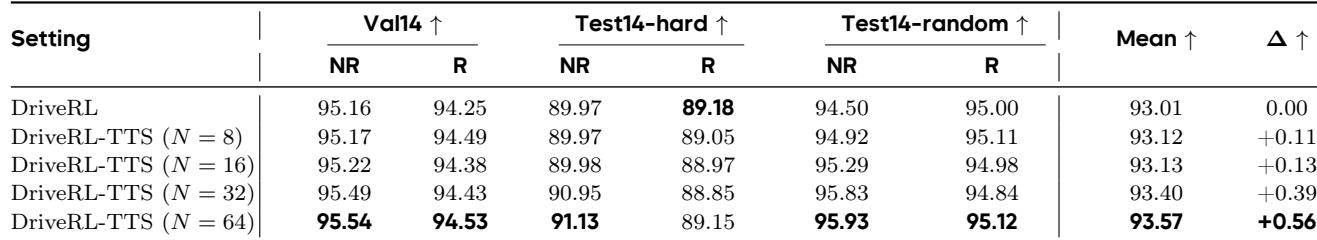
DriveRL achieves the highest unweighted mean score across all six nuPlan evaluations, outperforming both human-data-trained and human-free baselines in most settings. Adding value-guided test-time action search further improves the mean score by 0.56 points, with gains in five of six settings and minimal change on the hardest reactive case. DriveRL surpasses Log-Replay in every non-reactive and reactive setting, showing closed-loop RL can go beyond demonstration-seeded behavior. DriveRL also outperforms CaRL and GigaFlow, the two prior methods trained without human data, on all reported settings. Value-guided test-time action search raises the mean score from 93.01 to 93.57, improving five of six settings while leaving the hardest reactive case essentially unchanged.
Scaling the number of action candidates during test-time search improves the average driving score of a fixed checkpoint, with the largest gains on non-reactive hard and random splits. The improvement is consistent across most settings, confirming that additional inference computation acts as a local policy-improvement operator. Increasing the candidate budget from 8 to 64 raises the mean score from 93.12 to 93.57. The largest gains occur on non-reactive Test14 splits, with improvements of 1.16 and 1.43 points. The reactive splits show smaller or mixed changes, while non-reactive splits benefit more consistently from larger candidate sets.
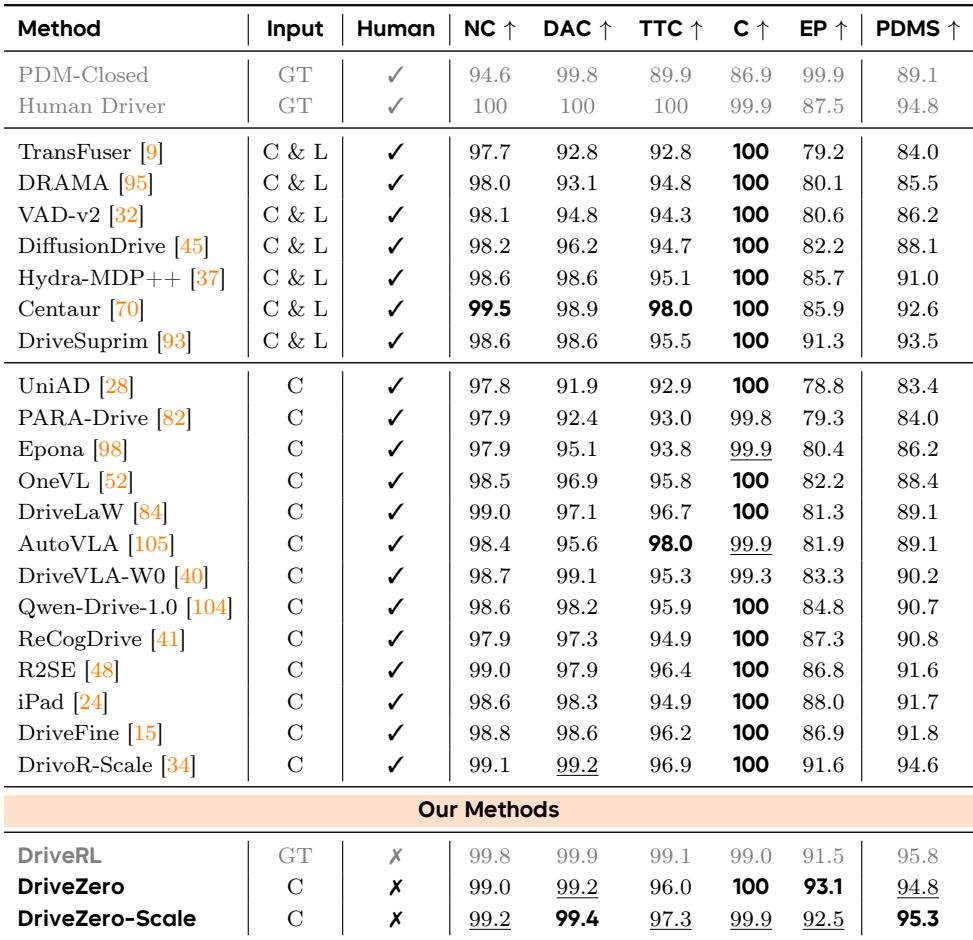
DriveZero, trained with RL supervision from DriveRL, achieves strong pseudo closed-loop performance on the NAVSIMv1 navtest benchmark using only camera input, outperforming prior camera-only and fusion methods. Scaling with additional simulation data further improves its PDMS score while maintaining high safety and efficiency metrics. RL-trained DriveRL surpasses both the human driver and PDM-Closed on PDMS, with near-human safety and higher driving efficiency. Camera-only DriveZero reaches 94.8 PDMS without human trajectory supervision, beating all prior camera-only and camera-LiDAR fusion methods. Adding OOD simulation data (DriveZero-Scale) raises PDMS to 95.3, with safety metrics above 99 and improved efficiency.
DriveZero, a camera-only method, achieves an EPDMS of 51.5 on the NAVSIMv2 navhard benchmark, outperforming all methods trained only on the navtrain split and surpassing a comparable RL-Teacher-based approach. Scaling with SimScale data improves the combined score to 57.1, driven by a large gain in the Stage 2 score, and establishes a new state of the art even against methods using ground-truth symbolic inputs. DriveZero outperforms all methods trained exclusively on the navtrain split, including a comparable RL-Teacher-based approach. Scaling with SimScale data raises the combined EPDMS by 5.6 points, with the Stage 2 score improving by 8.3 points while Stage 1 decreases slightly. The scaled model surpasses both a SimScale-using baseline and a method that relies on ground-truth symbolic inputs.
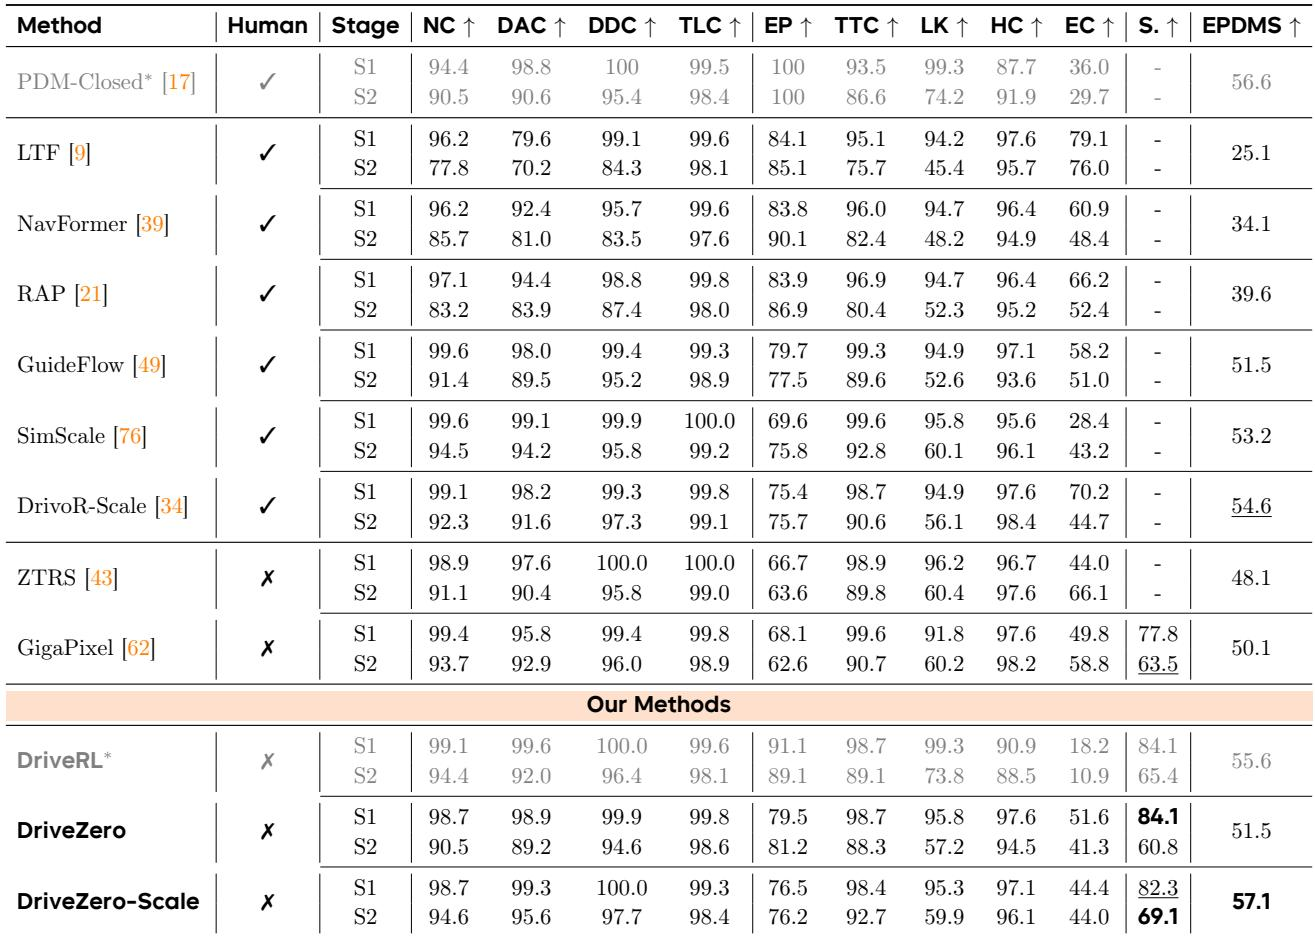
DriveRL, a transformer-based closed-loop RL policy trained with PPO in large-scale parallel simulation, achieves the highest mean score across all six nuPlan settings, outperforming both human-data-trained and human-free baselines, with value-guided test-time action search providing a further 0.56 point improvement. Scaling the number of action candidates during search consistently improves a fixed checkpoint's score, particularly on non-reactive splits, confirming that additional inference computation acts as a local policy-improvement operator. Distilled into a camera-only student, DriveZero surpasses prior camera-only and fusion methods on NAVSIMv1 navtest, and scaling with additional simulation data further raises its performance while maintaining high safety and efficiency. On the harder NAVSIMv2 navhard benchmark, DriveZero also sets a new state of the art, with scaling yielding a large gain in the Stage 2 score and outperforming even methods that use ground-truth symbolic inputs.