Command Palette
Search for a command to run...
에이전틱 지능을 위한 코드 기반 대규모 근거 스킬 합성
에이전틱 지능을 위한 코드 기반 대규모 근거 스킬 합성
Yongqi Tong Pan Wang Hang Wang Jianshe Li Xin Zhang Jiang-Ming Yang Wei Wu
초록
재사용 가능한 스킬은 에이전틱 시스템에 전이 가능한 절차적 지식을 부여하므로, 에이전트를 축적된 경험 너머로 확장하려면 확장 가능한 스킬 습득이 필수적이다. 기존 스킬 합성 방법에는 두 가지 주요 한계가 있다. 궤적 기반 스킬 합성은 환경에 본질적으로 결합되어 있고, 문서 기반 생성물은 근거 지원과 검증이 부족할 수 있다. 소스 코드는 다른 경로를 제공한다. 사전 경험이 필요 없으면서도 이후 추상화를 근거화할 실행 가능한 증거를 보유한다. 따라서 우리는 Code2Skill을 제시한다. 이는 선택된 코드 단위를 구현에 고정된 원자 연산, 복합 워크플로, 반복 패턴 스킬 레코드로 승격하고, 소스 본문을 가린 재구성과 소스 인지 비교를 통해 이를 검증하는 완전 자동화 파이프라인이다. Code2Skill을 인기 있고 활발히 유지 관리되는 19,769개의 GitHub 리포지토리에 적용하여, 워크플로, 경계, 출처, 소스 증거 메타데이터를 갖춘 1,006,822개의 승인 레코드를 포함하는 근거 기반 스킬 뱅크인 CodeSkillBank를 구축했다. 9개 모델 설정과 8개 벤치마크에 걸친 72개의 프로토콜 일치 평가에서, 검색된 CodeSkillBank 스킬로 보강된 모델은 대응 기준선 대비 평균 11.7%의 성능 향상을 달성했고, 57개 사례에서 기준선을 능가했다. 통합된 다운스트림 인터페이스 하에서 Code2Skill은 비교된 궤적 기반 스킬 뱅크들을 공유 7개 벤치마크 모두에서 능가하여, 리포지토리에서 도출된 스킬이 에이전트가 자체 상호작용을 통해 충분한 경험을 축적하기 전에도 효과적인 절차적 지식을 제공할 수 있음을 보여준다. 게다가 광범위한 분석은 테스트된 AI 생성 코드로부터 합성된 스킬이 93.50%의 통과율을 달성한 반면, 사람이 작성한 코드에서 도출된 스킬은 93.00%를 기록했음을 보여준다. 이는 AI 생성 코드가 점점 보편화됨에 따라 동일한 파이프라인이 CodeSkillBank를 지속적으로 확장할 수 있다는 초기 증거를 제공한다. 종합하면 Code2Skill은 소프트웨어 리포지토리에 내재된 전문 지식을 근거에 기반하고 검증 가능하며 전이 가능한 스킬로 변환함으로써, 에이전틱 시스템에서 인간의 절차적 지식을 재사용하기 위한 새로운 패러다임을 제시한다.
One-sentence Summary
Researchers at Ant International propose Code2Skill, a fully automated pipeline that lifts selected code units into implementation-anchored atomic-operation, composite-workflow, and recurring-pattern skill records verified through source-body-blind reconstruction and source-aware comparison, and applying it to 19,769 GitHub repositories yields CodeSkillBank with 1,006,822 records and an average performance gain of 11.7% across 72 evaluations.
Key Contributions
- Code2Skill is a fully automated pipeline that lifts selected source-code units into implementation-anchored atomic-operation, composite-workflow, and recurring-pattern skill records, and verifies them through source-body-blind reconstruction followed by source-aware comparison.
- Applying Code2Skill to 19,769 popular and actively maintained GitHub repositories yields CodeSkillBank, a grounded skill bank containing 1,006,822 accepted records with workflow, boundary, provenance, and source-evidence metadata.
- In evaluations spanning nine model settings and eight benchmarks, retrieved CodeSkillBank skills achieve an average performance gain of 11.7% over matched baselines, with gains in 57 of 72 protocol-matched evaluations. Under a unified downstream interface, repository-derived skills also outperform compared trajectory-derived skill banks on all seven shared benchmarks.
Introduction
The authors address a practical bottleneck in agentic AI: large foundation models can reason well, but complex long-horizon tasks require reusable procedural knowledge that lives outside model parameters, often encoded as skills in an agent harness. Skills matter because they can be updated, versioned, and deployed independently, offering a scalable way to add domain-specific expertise. Prior skill synthesis is limited: trajectory-based methods distill skills from an agent’s own execution traces, so their quality is bounded by the generating agent and they may become outdated when models, tools, or task distributions change; document-based methods avoid this coupling but lack executable grounding and verification. The authors introduce Code2Skill, a fully automated pipeline that mines large-scale source code repositories, abstracts useful implementations into typed skill records, and verifies grounding by reconstructing the original implementation from the skill alone. Applied to 19,769 GitHub repositories, it produces CodeSkillBank, a skill base with 1,006,822 accepted records, and improves downstream agent performance across software engineering, reasoning, and system interaction benchmarks.
Dataset
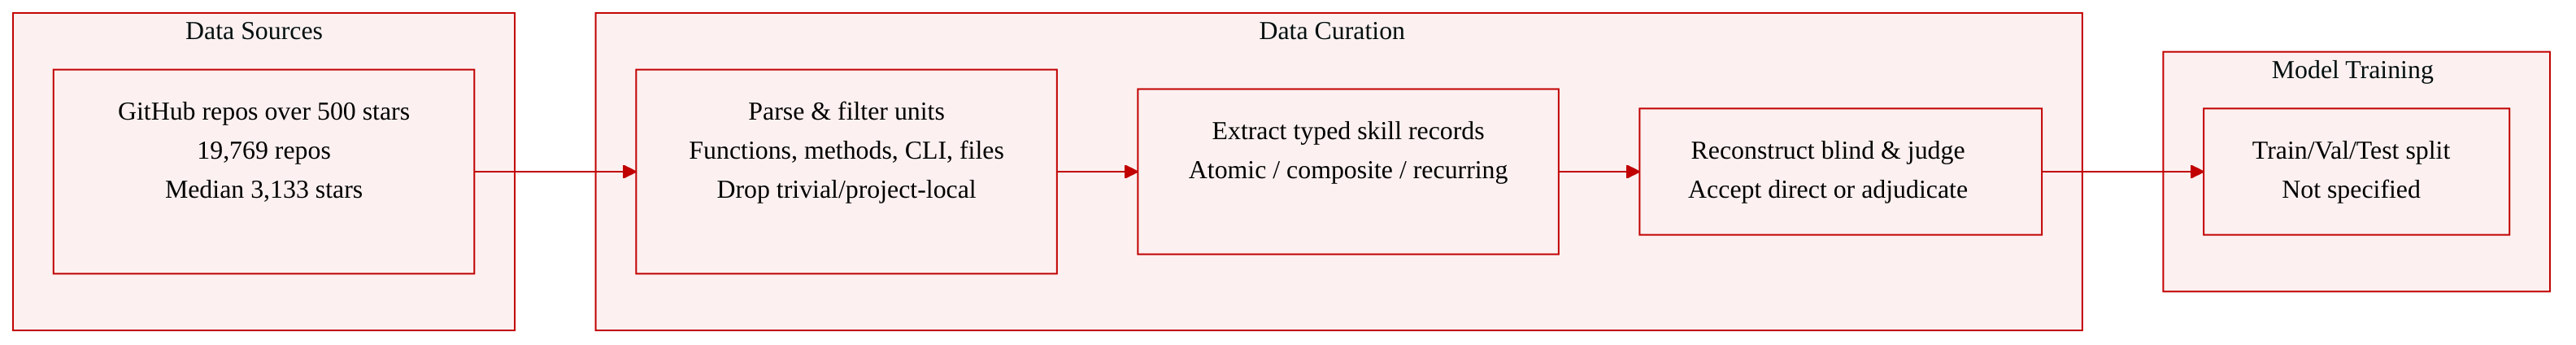
Dataset sources and scale
- The authors build CodeSkillBank from GitHub repositories available by April 14, 2026 with more than 500 stars.
- The source pool contains 19,769 repositories.
- The repository pool is concentrated in actively maintained public projects:
- Median: 3,133 stars and 82 merged pull requests.
- 78.3% have at least 1,000 stars.
- 46.9% have at least 100 merged pull requests.
- 66.0% were pushed within the previous year.
- The pool covers major programming languages and software ecosystems.
Dataset composition
- CodeSkillBank consists of typed skill records at three granularities:
- Atomic skills: a single well-defined operation within one function or method.
- Composite skills: ordered workflows coordinating multiple operations.
- Recurring-pattern skills: higher-level implementations beyond a single localized operation or workflow.
- Each record separates operational guidance from execution constraints and supporting evidence.
- Records include fields such as:
- Problem captured
- When to use
- Control rule
- Workflow
- Invariants and failures
- Anti-goals
- Source evidence
- Provenance and construction metadata
Processing and filtering
- The pipeline parses functions, methods, command-line entry points, and file-level components from each repository.
- An LLM tagger selects units with reusable intent, operational structure, and visible execution constraints.
- Trivial, project-local, and unsupported traces are rejected.
- The extractor maps selected units to typed, task-facing candidates.
- A source-body-blind reconstructor regenerates code using only the record.
- A source-aware judge accepts sufficiently consistent reconstructions and routes remaining cases to an adjudicator.
- Accepted records retain final status, rationale, reconstruction outcome, and provenance at repository, file, symbol, and source-span levels.
Quality and use
- Human annotation of sampled pipeline outcomes reports:
- 92% of final skill descriptions are judged accurate.
- 80% of final records are judged worth retaining.
- 84% of directly accepted records support correct reconstruction.
- The rejection sample is weaker: 32% description accuracy, 28% retention value, and no correct reconstructions.
- The paper uses CodeSkillBank as a large-scale skill base for procedural knowledge. The provided excerpt does not give explicit training split or mixture ratios.
Method
The authors formalize skill construction as a mapping from a source-code unit, such as a function, method, command-line entry point, or file-level component, together with its repository context, to a candidate skill record. A valid record should specify when the procedure applies, which behavior to reproduce, which preconditions and invariants govern execution, how failures should be handled, and which source spans support these claims. The formulation imposes three requirements. A record must be grounded, meaning recoverable implementation spans support its procedural claims and are challenged through source-body-blind reconstruction. It must be transferable, meaning project-specific identifiers and integration details are abstracted away while reusable preconditions, steps, invariants, and failure-handling strategies are preserved. It must also be maintainable, retaining provenance, supporting source spans, record type, and construction status so the record can be inspected, invalidated, or regenerated as the code evolves.
The pipeline begins by selecting candidate procedural evidence. Code2Skill scans GitHub repositories and retains higher-quality projects, then parses functions, methods, command-line entry points, and file-level components. An LLM tagger selects units with reusable intent, operational structure, and visible execution constraints. Trivial, project-local, and unsupported traces are rejected. Selected units remain candidates until extraction assigns a record type and reconstruction and adjudication determine acceptance.
Skill record generation maps each selected source unit and its structural context to a typed, task-facing candidate. The authors use three record granularities because procedural knowledge appears at different source scopes. Atomic skills capture a single well-defined operation within one function or method. Composite skills capture ordered workflows that coordinate multiple operations. Recurring-pattern skills capture higher-level implementations beyond a single localized operation or workflow. Each record separates operational guidance from execution constraints and supporting evidence while retaining provenance and construction metadata. The schema includes problem captured, when to use, control rule, workflow, invariants and failures, anti-goals, and source evidence. These fields preserve procedural steps, decision boundaries, transferable control rules, invariants, and provenance beyond a conventional code summary.
To prevent extraction from omitting critical operational details or introducing unsupported constraints, the pipeline uses source-body-blind reconstruction and consistency checking. A reconstructor regenerates code using only the record, without access to the source body. A source-aware judge directly accepts sufficiently consistent reconstructions and routes the remaining cases to an adjudicator, which distinguishes unsupported skill records from failures of the reconstruction process. The round trip uses LLM-based comparison to check consistency across the record, reconstruction, and source implementation. Accepted records retain their final status, rationale, reconstruction outcome, and repository-, file-, symbol-, and source-span-level provenance to support inspection, source-aware refresh, and traceability.
After acceptance, retrieval-oriented feature tagging creates a task-oriented retrieval view for every accepted record while preserving a one-to-one correspondence. Purpose indexing separately filters low-value candidates, groups records by similar purpose, and selects an existing record as the representative of each group. Both transformations leave the evidence archive intact.
For utilization, each evidence archive supports audit and maintenance because records retain provenance, reconstruction status, and acceptance trace. A downstream utilization interface controls when to query the bank, how much of each retrieved record to show, and at which decision point to provide that context. This covers prompt-level retrieval, planning-time retrieval, post-generation review, verifier-side reward use, and training-time skill conditioning. Given a task and agent or model state ht before decision step, if the interface queries the bank with qt, it constructs a rendered skill context and passes it to the recipient's usual policy or model call:
zt={Renderr(TopKk(qt;B)),∅,if a query is issued,otherwise.at∼πθ(s)(⋅∣x,ht,zt).Here B denotes the retrieval-facing store available to the current evaluation, and at denotes the output at that decision point, such as a generation step, plan, review, verifier judgment, or environment action. The no-skill comparator uses the same protocol with zt=∅. For learning-time settings, the interface also determines which checkpoint θ(s) is evaluated. Skills may be visible to a verifier or reward model while remaining hidden from the policy trajectory being judged, whereas inference-only protocols keep model or policy parameters fixed.
Experiment
Across multiple model families and eight benchmarks spanning programming, software engineering, terminal and OS control, and reasoning, the authors evaluate an offline code-derived skill bank inside a draft-review-revision agent loop. The experiments show that code-derived skills consistently improve agent performance over a no-skill control and outperform trajectory-derived skill banks under a shared interface, with planning-time and post-generation review being more reliable insertion points than generation-time prompting. Compact summaries preserve most of the skill utility while sharply reducing context use, and skills remain beneficial when integrated into reinforcement learning, especially through post-generation review. Finally, tested AI-generated implementations yield skills that perform comparably to human-derived skills but produce distinct task-level outcomes, supporting continuous expansion from AI code.
All CodeSkillBank integration interfaces improve resolve rate over the no-skill baseline. Policy prompting and reward reference produce moderate gains, while post-generation review provides the largest improvement. These results come from a single checkpoint and do not establish learning speed, convergence, or final policy performance. Every skill-enabled condition outperforms the no-skill control. Policy and reward-side interfaces yield comparable moderate improvements. Post-generation review produces the largest resolve-rate gain, roughly twice the policy and reward-side gains. The findings reflect a single checkpoint without repeated seeds or learning curves.
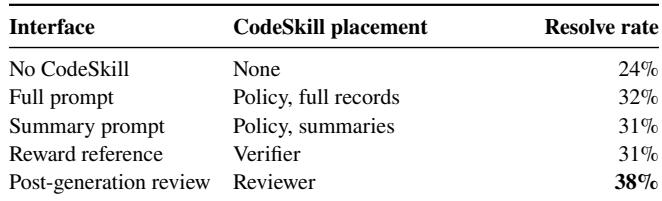
The evaluation compares CodeSkillBank integration interfaces against a no-skill baseline on resolve rate. Policy prompting and reward reference provide comparable moderate gains, while post-generation review delivers the largest improvement, roughly twice those gains. These results come from a single checkpoint without repeated seeds or learning curves, so they do not establish learning speed, convergence, or final policy performance.