Command Palette
Search for a command to run...
Iris: 탐색 경계로의 등반
Iris: 탐색 경계로의 등반
Ziyuan Liu Hengqi Liu Zichuan Wang Yang Qin Jiachen Liang Xu Chu Shaowei Chen Yuantao Gu Mu Chuan
초록
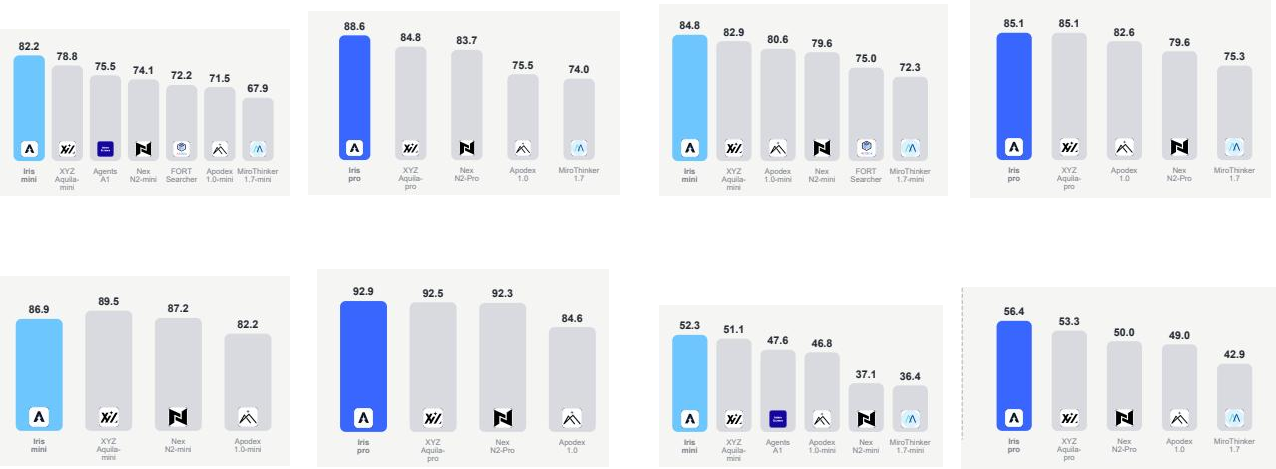
우리는 35B-A3B 및 397B-A17B 규모로 훈련된 두 탐색 에이전트인 Iris-mini와 Iris-pro를 제시하며, 이를 뒷받침하는 데이터 파이프라인과 훈련 레시피를 함께 소개한다. 작업은 웹 코퍼스의 하이퍼링크 구조에서 역으로 구성된다: 시드 페이지와 그 외부 링크에서 추출된 엔티티 그래프를 기반으로 다중 홉 체인을 작성하고, 모든 비정답 엔티티를 설명적 참조로 재작성하여 문자열 일치로는 어떤 단서도 해결할 수 없게 하며, 참조 모델이 폐쇄형으로는 실패하지만 지원 증거가 제공되면 해결하는 질문만을 허용한다. 이러한 질문은 궤적으로 변환되며, 지도 미세 조정(SFT) 전에 두 번 필터링된다: 먼저 궤적 수준에서 정확성, 퇴화성, 탐색 깊이를 기준으로, 그 다음 턴 수준에서 수기로 작성되지 않고 데이터에서 유도된 평가 기준을 사용하는 판정자에 의해 필터링된다. 그 후 정책은 실시간 탐색에 대한 강화 학습(RL)으로 최적화되며, 보상 판정자와 관찰 요약기는 훈련 클러스터 내에서 제공되고, 과도하게 긴 롤아웃은 요청 수준에서 중단된 후 다음 단계에서 커밋된 접두사부터 재개된다. 우리는 SFT-RL 등반이라고 부르는 절차로 두 단계를 번갈아 수행하며, 각 RL 라운드에서 가장 어렵게 해결된 가장 효율적인 롤아웃을 다음 지도 학습 패스에 반환한다. 추론 시 컨텍스트 관리는 이러한 벤치마크에서 시스템 간 보고된 대부분의 차이보다 더 가치가 있기 때문에, 우리는 모든 벤치마크를 관리 유무에 따라 평가하며 도구 세트, 컨텍스트 제한, 판정자를 고정한다. 모든 결과는 단일 ReAct 에이전트에서 나오며, 하위 에이전트나 테스트 시간 검증이 없다. 관리 기능을 활성화한 상태에서 BrowseComp, BrowseComp-ZH, DeepSearchQA, Humanity's Last Exam에서 두 모델은 각각 82.2/84.8/86.9/52.3 및 88.6/85.1/92.9/56.4에 도달하여, 각각의 매개변수 범위에서 오픈소스 탐색 에이전트 중 가장 강력한 종합 결과를 보여준다. 우리는 모델 가중치와 데이터 구축, 훈련, 평가를 위한 완전한 레시피를 공개할 계획이다.
One-sentence Summary
AllSpark Team presents Iris-mini and Iris-pro, 35B-A3B and 397B-A17B search agents trained via a reverse-constructed multi-hop question pipeline with trajectory- and judge-level filtering, followed by alternating SFT and RL against live search (SFT–RL climbing), achieving 82.2/84.8/86.9/52.3 and 88.6/85.1/92.9/56.4 on BrowseComp, BrowseComp-ZH, DeepSearchQA, and Humanity’s Last Exam with context management, the strongest open-source results in their parameter ranges.
Key Contributions
- Presents Iris-mini and Iris-pro, two search agents trained at the 35B-A3B and 397B-A17B scales, with a data pipeline that reverse-constructs multi-hop questions from web hyperlink structure, rewrites answer entities into descriptive references to block string matching, and admits only questions a reference model fails closed-book but solves with evidence.
- Combines trajectory-level and turn-level filtering before supervised fine-tuning, then applies reinforcement learning against live search with an in-cluster judge and observation summarizer, alternating SFT and RL in a procedure called SFT–RL climbing that feeds the hardest solved and most efficient rollouts back into the next supervised pass.
- With context management enabled, achieves 82.2/84.8/86.9/52.3 and 88.6/85.1/92.9/56.4 on BrowseComp, BrowseComp-ZH, DeepSearchQA, and Humanity’s Last Exam, the strongest overall results among open-source search agents in their parameter ranges, and reports positive transfer of search-trained models to general tool use and cowork benchmarks.
Introduction
Search agents extend language models beyond closed-form reasoning by enabling interaction with external tools and dynamic environments, requiring decisions about what to search, how to interpret evidence, and when to stop. This differs from conventional language-model evaluation, where tasks and computation budgets are fixed, and building reliable agents demands stronger models, better training data, and long-horizon interaction strategies. Prior work has progressed through tool use, reinforcement learning with retrieval, and synthetic task construction, but performance often varies more due to inference-time harness differences than the underlying policy, particularly in context management (CM). Long-horizon searches can exhaust context windows, shrinking the effective budget, and existing solutions like trajectory summarization or history removal obscure how much performance stems from the policy versus the harness, making CM a critical yet underreported factor.
The authors present an end-to-end recipe for data construction, training, and evaluation of search agents. They build multi-hop tasks from web-graph structure, remove easily searchable anchors, and retain only questions that are difficult and objectively verifiable. They collect trajectories from a strong teacher, apply trajectory-level and turn-level filtering, then optimize the policy with reinforcement learning against live search, using an in-cluster judge and observation summarizer, alternating SFT and RL iteratively to reinforce successful behaviors. Their main contribution is a complete pipeline that combines filtered SFT, RL with live web search, and iterative climbing, evaluated under two inference regimes with and without CM, achieving best overall performance among open-source agents on benchmarks like BrowseComp, BrowseComp-ZH, DeepSearchQA, and Humanity’s Last Exam. They also plan to release model weights and pipeline components to facilitate reproduction and further research.
Dataset
Dataset Composition and Sources
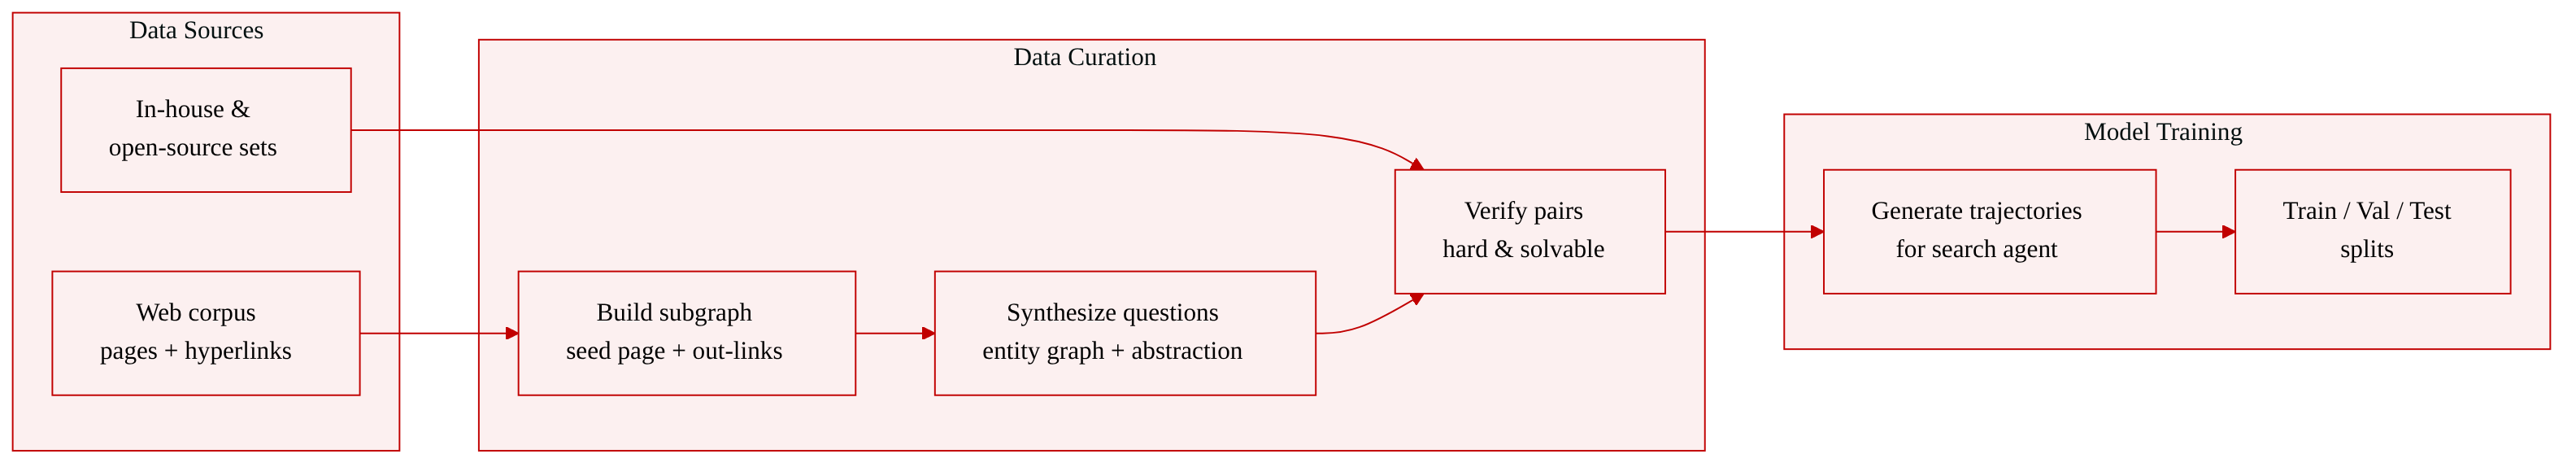
The authors build a training dataset for a search agent using a fully LLM-driven pipeline that reverse-constructs questions from the hyperlink structure of a web corpus. The goal is to generate questions that (i) cannot be answered from parametric memory alone and (ii) require composing evidence from multiple sources. The pipeline has three stages: web-graph construction, task synthesis, and dual-criteria verification. The final dataset also includes some in-house and open-source question sets (referenced as [6, 28, 2, 25]).
Web-Graph Construction
- The corpus is modeled as a directed graph where nodes are pages and edges are hyperlinks.
- Each synthesis instance starts with a seed page sampled using an answer-anchored mode: the authors fix a target answer entity and retrieve pages describing it.
- The seed is expanded along its out-links into a local subgraph, retaining full page text truncated to a fixed budget.
- To recover the true out-link set, the authors merge two sources: a structured semantic mirror of the corpus (RDF triples) and rendered page markup. This merge maximizes link recall because reader services strip inline anchors.
Task Synthesis
Given a subgraph, the pipeline produces a single obscured multi-hop question in three steps:
- Entity-graph extraction: Raw pages are distilled into a compact, connected entity graph (with at most n nodes) containing salient entities and typed semantic relations. The extractor keeps only entities and relations that lie on a multi-hop path toward the seed theme, creating a dense relational skeleton for question authoring.
- Multi-hop question generation: The seed theme (target answer) is used to generate an initial question with a reasoning path. The path must have at least N coupled relations, and the answer is not allowed to appear in the question text.
- Anchor abstraction: Every non-answer entity is rewritten into a descriptive reference that uniquely identifies the entity but removes its name and aliases. This forces the final question to require disambiguation-by-reasoning rather than string matching.
Dual-Criteria Verification
- A pair (abstracted question, answer) is admitted only if it passes two criteria judged by a reference model:
- Difficulty: The reference model, in closed-book mode with no tools, cannot answer the question correctly.
- Solvability: The reference model, given the entity graph as context, can answer the question correctly.
- Answer equality is decided by a semantic-matching judge. The accepted set contains abstracted multi-hop questions, each paired with a verified, unique answer.
Usage in the Model
The accepted dataset, along with the in-house and open-source question sets, is used for trajectory generation. The paper does not specify a training split or mixture ratio in the provided text, but the dataset is designed to train a search agent on hard, solvable multi-hop questions that require composing evidence across sources.
Method
Method
The authors train a web-search agent through a fully LLM-driven data pipeline that reverse-constructs multi-hop questions from the hyperlink structure of a web corpus, followed by iterative cycles of supervised fine-tuning and reinforcement learning. The overall approach consists of two main components: a data pipeline that generates hard, solvable training questions, and a training recipe that turns those questions into reliable search behavior.
Data Pipeline
The data pipeline is organized into three stages: web-graph construction, task synthesis, and dual-criteria verification.
Web-graph construction. The authors model the corpus as a directed graph whose nodes are pages and whose edges are hyperlinks:
G=(V,E),Out(v)={u∈V∣(v,u)∈E}.Each synthesis instance begins from a seed page drawn by a sampling policy, v0∼Pseed(V), for which they use an answer-anchored mode that fixes a target answer entity and retrieves pages describing it. The seed is then expanded along its out-links into a local subgraph:
Gsub=({v0}∪N,Esub),N={vi}i=1k⊆Out(v0),retaining the full text of each page truncated to a fixed budget. Because the reader services that render pages strip inline anchors, the authors recover the true out-link set of v from a structured semantic mirror of the corpus (RDF triples) together with rendered page markup, merging the two sources to maximize link recall.
Task synthesis. Given a subgraph Gsub, this stage produces a single obscured multi-hop question through three steps: distilling the pages into an entity graph, authoring a question over that graph, and abstracting away every directly searchable anchor.
First, the authors distill Gsub into a compact, connected entity graph:
Ge=(Ve,Re)=fext(Gsub),∣Ve∣≤n,where Ve are salient entities and Re are typed semantic relations that preserve the cross-page link structure of Gsub. The extractor keeps only entities and relations that lie on a multi-hop path toward the seed theme, yielding a dense relational skeleton over which questions can be authored precisely.
Let y=theme(v0) denote the seed theme, taken as the target answer. The authors generate an initial question together with its reasoning path over the entity graph:
(q0,P)=fgen(Ge,y)s.t.∣P∣≥N∧y∈/q0,where P=(e1r1e2r2⋯y) is a path in Ge whose traversal uniquely yields y. The hard constraint ∣P∣≥N forces the question to depend on at least N coupled relations.
Concrete anchors let an agent bypass the intended reasoning by directly searching a surface string. The authors remove this shortcut with an abstraction operator A that rewrites every non-answer entity into a descriptive reference:
A(e):name(e),alias(e)∈/A(e)∧A(e) uniquely identifies e,∀e∈Ve∖{y}.The initial question is then rewritten into its abstracted form:
q~=fabs(q0,A),substituting each mentioned entity e by A(e) while preserving the reasoning structure and the answer y. The resulting q~ demands disambiguation-by-reasoning rather than string matching.
Dual-criteria verification. The authors admit a pair (q~,y) only if it is simultaneously hard and solvable, judged by a reference model Mref under two settings:
cdiff(q~)=I[Mref(q~)=y],csolv(q~)=I[Mref(q~∣Ge)=y],and they keep only the intersection:
D={(q~,y)∣cdiff(q~)⋅csolv(q~)=1}.The difficulty criterion, evaluated closed-book with no tools, discards simple questions the model already answers from memory. The solvability criterion, evaluated with Ge supplied as context, discards questions whose answer is wrong or non-unique. Answer equality is decided by a semantic-matching judge. The accepted set D of abstracted multi-hop questions, each paired with a verified unique answer, is then used for trajectory generation.
Training Recipe
The authors train the search agent through iterative cycles of supervised fine-tuning (SFT) and reinforcement learning (RL).
Supervised fine-tuning. A strong teacher MT is prompted to solve each question q∈D under the ReAct paradigm, interleaving reasoning, tool calls, and observations against live search tools. A trajectory is the resulting sequence of reasoning steps, tool calls, and observations, terminated by a final answer:
τ=(r1,a1,o1,…,rT,aT,oT,rT+1,y^)∼πMT(⋅∣q,T),where rt is the reasoning at step t, at∈T is a tool call from the tool set T={SEARCH,SCRAPE}, ot is the returned observation, and y^ is the final answer. Each observation is a document-level summary produced on the fly rather than a raw page, keeping trajectories within a bounded context budget.
Let Draw={(q,τ)} be the pool of collected trajectories. Every sample must clear a trajectory-level stage that admits τ only if it is correct, non-degenerate, and non-trivial. Correctness is a two-part gate: the rollout must terminate successfully, and its answer must be judged correct by an LLM judge J against the reference y∗:
ccorr(q,τ)=I[success(τ)]⋅I[J(q,y^τ,y∗)=CORRECT].The authors then remove degenerate trajectories: repetition loops, runaway tool calling, unterminated thinking blocks, and other pathologies. Their primary detector is a sliding-window compression ratio, computed in O(n) over the decoded text:
ρcr(w)=∣zlib(w)∣∣w∣,cdegen(τ)=I[wmaxρcr(w)≥τcr].Repetitive text compresses far more than fluent text, so any window whose ratio reaches τcr signals a loop, whatever its period and wherever it begins. Auxiliary detectors cover what compression alone can miss: periodically repeating lines, long single-character runs, and consecutive tool calls with byte-identical arguments. Finally, the authors keep only trajectories with at least K tool-call turns, discarding shallow cases a direct lookup could resolve:
cdepth(τ)=I[Ttool(τ)≥K].An exact-duplicate pass over full message sequences then drops byte-identical trajectories while keeping distinct rollouts of the same question, giving the coarse set:
Dsft=dedup{(q,τ)∈Draw∣ccorr⋅(1−cdegen)⋅cdepth=1}.Coarse filtering keeps or drops whole trajectories. When a question sits near the capability boundary of the teacher, however, a correct trajectory may still contain a locally poor turn: a redundant search, a hallucinated tool name, or reasoning inconsistent with the action actually taken. As a turn-level refinement, the authors label individual turns with an LLM judge. The difficulty is that a turn which looks wasteful in isolation is often a legitimate exploratory step, and because no human is in the loop, the judge has to draw that line on its own. The authors therefore induce the criteria from the data rather than hand-crafting them. Specifically, they sample some trajectories and ask the judge to critique them in free form, then consolidate the recurring failure modes into an explicit rubric used in the final judging prompt. For each assistant turn, the judge receives the question, reference answer, and a fixed local window of surrounding turns, and outputs either KEEP or MASK, represented as mt∈{0,1}. To prevent overly aggressive filtering, the authors mask at most 10% of the assistant turns in any trajectory. Masked turns remain in the context but are excluded from the training loss, providing cleaner learning signals without discarding useful interaction history.
For each assistant turn, let C<t denote its visible history, reconstructed by the harness's replay operator from the append-only conversation so as to stay byte-identical to what the agent conditioned on at inference. Over D^sft the authors maximize the likelihood of the teacher's output:
LSFT(θ)=−E(q,τ)∼Dsftt=1∑T+1mtlogπθ(ut∣C<t),where ut is the assistant output at turn t, namely the reasoning and tool call (rt,at) for t≤T and the final reasoning and answer (rT+1,y^) at t=T+1. The per-turn mask mt∈{0,1} is supplied by fine filtering; observation, user, and system tokens carry zero loss by construction.
Reinforcement learning. The authors then optimize the agent against live search with a group-relative policy gradient. To keep long-horizon rollouts affordable without going fully asynchronous, they place the rollout regime between on- and off-policy through request-level partial rollout. To avoid depending on external APIs at training time, they co-locate an in-house model that serves as both reward judge and observation summarizer.
Long-horizon rollouts have a heavy tail: a few sessions run far longer than the rest and stall a synchronous step. Rather than discard unfinished work, the authors interrupt at the request level. Once a step has committed enough completed trajectories, in-flight over-sampled sessions are aborted and resumed at the next step from their committed prefix. Rollouts are organized as a forest whose nodes are message states, each caching its token, loss-mask, log-probability, and weight-version deltas, so a resumed trajectory is a path that splices prefixes generated under different policy weights, a mismatch corrected with truncated importance sampling. Completed turns are therefore reused rather than thrown away, which keeps rollout GPUs busy under a synchronous, co-located schedule at the cost of roughly 2× over-sampling as headroom.
Rather than call an external API, the authors run several FP8 engines of an in-house Qwen3.5-397B-A17B model inside the training cluster, alongside the actor and rollout engines. Acting as a generative reward model (GenRM), the model scores a rollout with a binary verdict on the extracted answer y^τ against the reference y∗:
R(q,τ)=I[GenRM(q,y^τ,y∗)=A],with no additive format term, since an empty or mid-thought-truncated answer extracts to ∅ and already scores 0 without invoking the judge. As a summarizer, the same engines compress each retrieved page into a short, query-relevant digest that supplies the observation ot. This is the only context-reduction mechanism in the rollout, with no message-history pruning or sliding window, so the context the policy conditions on is exactly what is trained on. Serving both roles in-cluster removes the external API dependency from the training loop, and one allocation covers training, rollout, and reward.
Iterative climbing. The authors alternate SFT and RL in iterative cycles. Each round of RL explores the current policy, after which a small set of high-quality rollouts is distilled back into the policy through supervised fine-tuning; RL then resumes from the updated model. Each such cycle is called a climb. This alternation complements the strengths of the two objectives: RL improves behaviors sampled by the current policy through relative rewards, while supervised fine-tuning directly reinforces rare but successful trajectories instead of relying on their contribution to a group-relative gradient.
For each query q, the authors retain at most one rollout from the existing RL samples. Let Rˉ(q) denote the pass rate within its rollout group. They select queries with 0<Rˉ(q)≤1/2, targeting cases that are solvable but not yet reliable. Among successful rollouts, they require at least Krft tool-call turns and then select the shortest valid trajectory:
Sq={τi∣R(q,τi)=1,Ttool(τi)≥Krft},τq⋆=τ∈SqargminTtool(τ).The depth constraint filters out lucky or trivial solutions, while the shortest-trajectory criterion discourages unnecessary search. The resulting set is deduplicated and used for SFT before the next RL round. Since the difficulty band is defined by the current policy's pass rate, it automatically shifts toward harder examples as the policy improves, providing a simple self-paced curriculum and a natural stopping signal as the candidate pool diminishes.
Experiment
The evaluation covers four benchmarks (BrowseComp, BrowseComp-ZH, DeepSearchQA, and HLE) with two model scales, Iris-mini and Iris-pro, tested under single-pass settings with and without context management. Iris-mini leads its parameter range on three benchmarks, while Iris-pro tops or ties all four, with both outperforming larger models and showing strong intrinsic search capability. Analysis of context management reveals consistent gains, especially for the smaller model and on long-horizon search tasks, though the gains are benchmark-dependent and retry strategies push scores higher at substantial inference cost. Overall, the results confirm that the training approach yields competitive search agents, with remaining gaps to frontier systems and a noted need for evaluation beyond benchmark metrics.
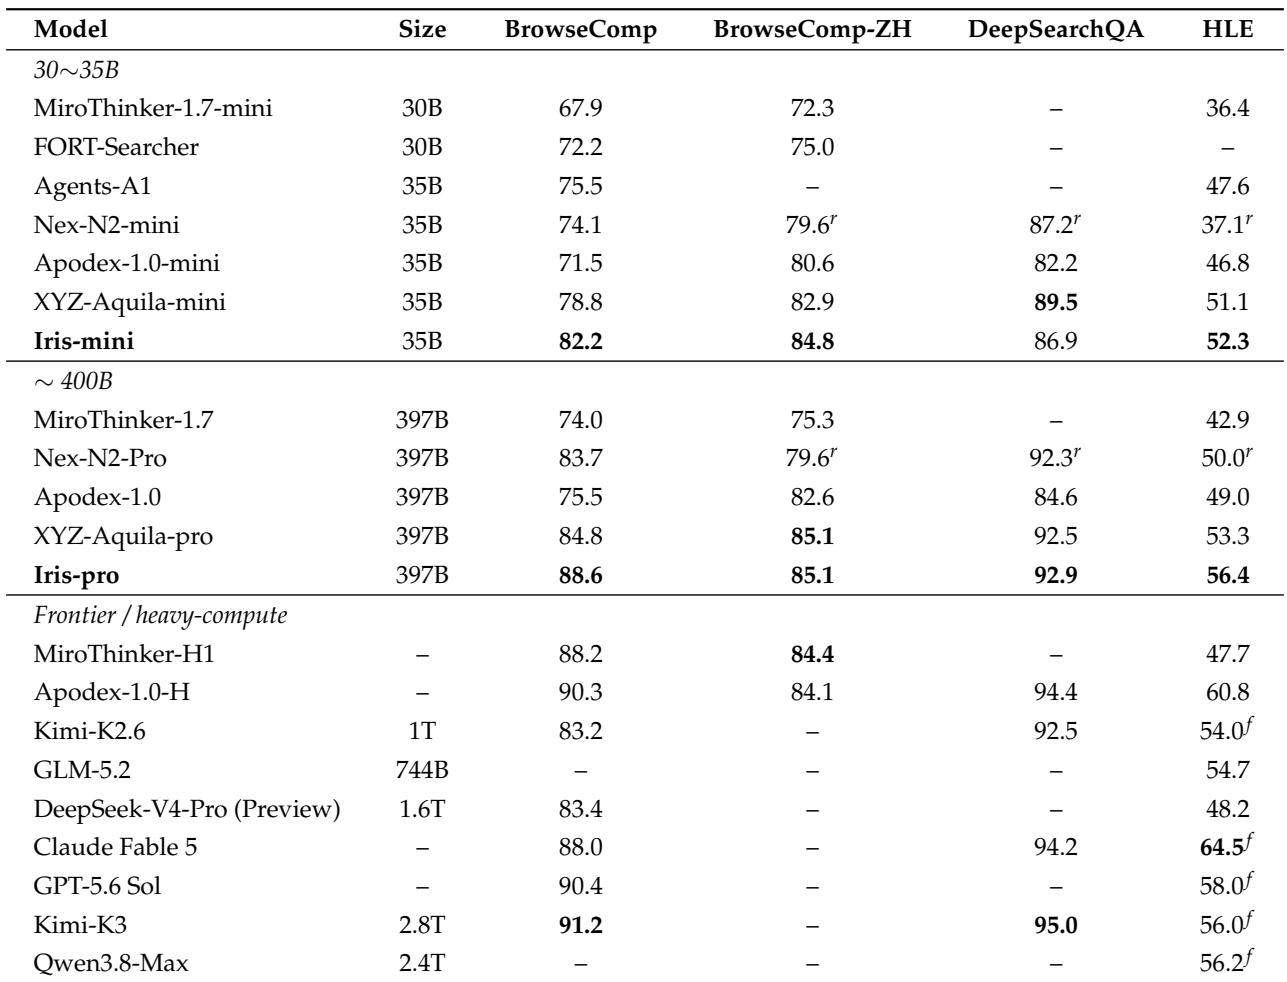
Iris-mini and Iris-pro achieve competitive or leading results across four search benchmarks, with Iris-mini excelling in the 30-35B range and Iris-pro leading or matching the best scores in the ~400B range. The models show strong intrinsic search capabilities, outperforming larger and heavily compute-dependent systems, though gaps remain relative to frontier models. Iris-mini outperforms XYZ-Aquila-mini by 3.4 points on BrowseComp and leads on BrowseComp-ZH and HLE in its parameter range. Iris-pro achieves the highest scores on BrowseComp, DeepSearchQA, and HLE, and ties on BrowseComp-ZH, with a 3.8-point lead over XYZ-Aquila-pro on BrowseComp. Without context management, Iris-mini and Iris-pro outperform several no-CM baselines by large margins, indicating gains are not solely from inference-time strategies. Context management consistently improves performance, with larger gains for Iris-mini than Iris-pro, as the smaller model exhausts context more often.
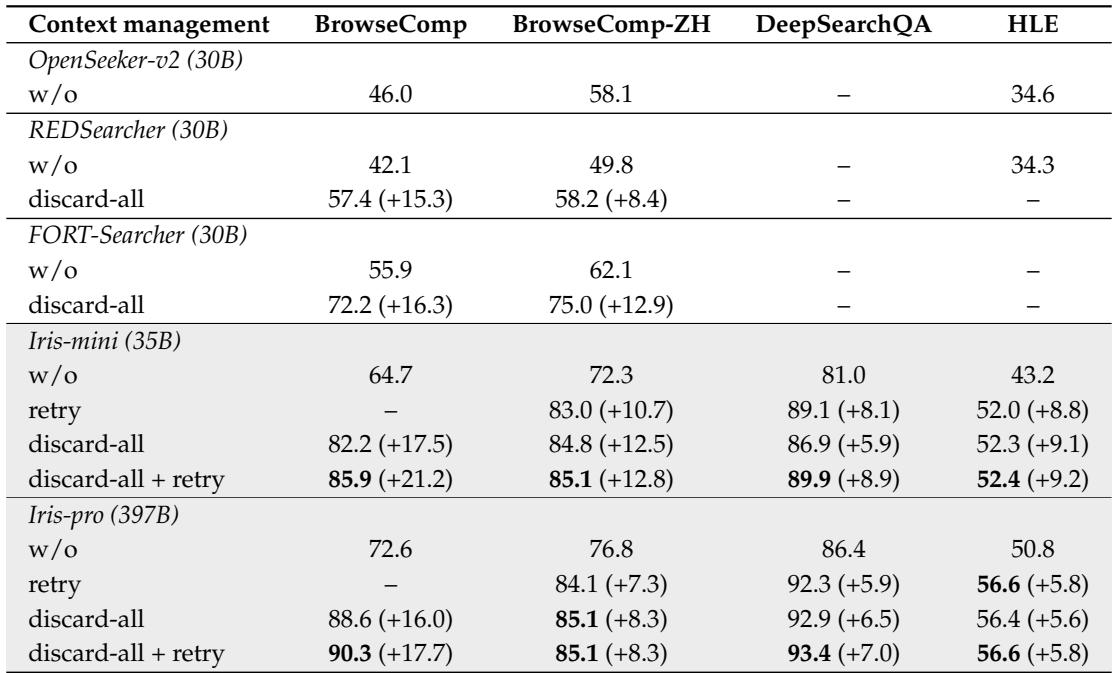
Context management (CM) consistently improves performance over no-CM baselines across all evaluated systems, with larger gains for the smaller Iris-mini model than for Iris-pro. The effectiveness of CM varies by benchmark, correlating with how often sessions exhaust their context, and combining discard-all with retry yields the highest scores but at substantial inference cost. CM improves all systems over their no-CM baselines, with gains up to 21.2 points for Iris-mini on BrowseComp. Iris-mini benefits more from CM than Iris-pro, as it consumes context faster and reaches limits more often. Gains are benchmark-dependent: BrowseComp benefits most, while HLE gains less despite a lower baseline, because its deficit is not context-related. On BrowseComp-ZH, three configurations (Iris-mini with retry, and Iris-pro with both CM variants) achieve the identical score of 85.1, suggesting capacity-independent limits. Combining discard-all with retry gives the strongest results in most settings, but the added inference cost makes it more an upper-bound exploration than a primary configuration.
Iris-mini and Iris-pro achieve competitive or leading results across four search benchmarks, with Iris-mini excelling in the 30-35B range and Iris-pro leading or matching the best scores in the ~400B range, outperforming larger and heavily compute-dependent systems while leaving gaps to frontier models. Context management consistently improves performance over no-CM baselines, with larger gains for Iris-mini, which exhausts context more often, and combining discard-all with retry yields the highest scores but at substantial inference cost. Gains are benchmark-dependent, with BrowseComp benefiting most and HLE less so, and some identical scores across configurations suggest capacity-independent limits.