Command Palette
Search for a command to run...
WorldReward: 카메라 조건부 세계 모델을 위한 보상 모델링
WorldReward: 카메라 조건부 세계 모델을 위한 보상 모델링
초록
카메라 조건부 세계 모델은 명령된 행동이 기대되는 장면 변화를 유도하면서도 외관, 기하학, 시간적 역학이 일관성을 유지하는 대화형 비디오를 생성한다. 기존의 보상은 일반적으로 이러한 요구 사항을 개별적으로 평가한다: 기하학 기반 보상은 궤적 실행을 추정하지만 실행된 동작의 시각적 품질을 판단할 수 없으며, 이미지 기반 보상은 프레임 품질을 측정하지만 행동 실행이나 시간적 역학을 포착하지 못한다. 우리는 비전-언어 모델(VLM)이 행동을 시각적 결과와 연관시키는 공유 추론 공간을 제공한다고 가정한다. 그러나 완전한 긴 비디오를 전체 행동 시퀀스에 대해 판단하는 것은 길고 잡음이 많은 맥락을 만들어, 수명이 짧은 국소적 행동 증거가 놓치거나 희석될 수 있다. 이러한 문제를 해결하기 위해, 우리는 카메라 조건부 세계 모델을 위한 행동 일관성과 시각적 품질 평가를 통합하는 VLM 기반 쌍별 선호 보상 모델인 WorldReward를 제시한다. WorldReward는 쌍을 이루는 비디오를 행동 정렬 청크로 분해하고 각 청크를 구조화된 시각적 증거로 구성하여, 모델이 각 행동의 실행을 시각적 품질과 함께 평가할 수 있게 한다. 청크 수준의 결정은 투표를 통해 별도의 비디오 수준 행동 및 시각적 품질 선호로 집계된다. WorldReward를 훈련하기 위해, 우리는 최첨단 VLM에 의해 생성되고 다중 턴 도구 기반 에이전트 감사와 표적 인간 검토를 통해 정제된 구조화된 판단을 사용하여 대규모 추론 증강 선호 데이터셋을 구축한다. 또한, 행동 일관성, 외관 품질, 모션 품질에 걸쳐 인간 선호와 보상 모델의 일치도를 측정하는 인간 주석 벤치마크인 WorldReward-Bench를 도입한다. WorldReward-Bench에서 WorldReward는 행동, 외관, 모션에서 각각 GPT-5.5를 3.42, 1.45, 3.56퍼센트 포인트 초과하여 세 가지 차원 모두에서 가장 높은 일치도를 달성한다. HY-WorldPlay 1.5의 강화 학습(RL) 사후 훈련에 사용될 때, 단기에서 장기 지평에 걸쳐 행동 실행과 시각적 품질을 일관되게 개선한다.
One-sentence Summary
Researchers from Fudan University, Tencent Hunyuan, Shanghai Innovation Institute, and Shanghai Jiao Tong University propose WorldReward, a VLM-based pairwise preference reward model that unifies action-consistency and visual-quality evaluation for camera-conditioned world models by decomposing paired videos into action-aligned chunks with structured visual evidence and aggregating chunk-level decisions via voting, outperforming GPT-5.5 on the human-annotated WorldReward-Bench across action, appearance, and motion, and improving RL post-training of HY-WorldPlay 1.5.
Key Contributions
- Introduces WorldReward, a VLM-based pairwise preference reward model that unifies action-consistency and visual-quality evaluation for camera-conditioned world models by decomposing paired videos into action-aligned chunks, organizing each chunk into structured visual evidence, and aggregating chunk-level decisions via voting into separate video-level preferences.
- Constructs a large-scale reasoning-augmented preference dataset, generated by a frontier VLM and refined through multi-turn tool-based agent auditing and targeted human review, to train WorldReward.
- Presents WorldReward-Bench, a human-annotated benchmark measuring reward-model agreement with human preferences across action consistency, appearance quality, and motion quality, where WorldReward achieves the highest agreement on all three dimensions, exceeding GPT-5.5 by 3.42, 1.45, and 3.56 percentage points respectively, and improves both action execution and visual quality in RL post-training of HY-WorldPlay 1.5 across short- to long-term horizons.
Introduction
Video-based world models simulate how visual environments evolve under user controls, but their usefulness depends on faithfully executing commanded actions while maintaining coherent geometry, appearance, and temporal dynamics over long horizons. Reward models that measure both properties are essential for evaluation and reinforcement learning (RL) post-training, yet existing approaches fall short. Geometry-based rewards track camera trajectories but ignore visual quality, image-based rewards score frames independently and miss temporal issues like flickering or motion discontinuities, and combined systems assess action and quality with decoupled, heterogeneous signals. Direct VLM judging over full videos struggles with sparse frame sampling that misses short-lived transitions or gets overwhelmed by long, noisy contexts.
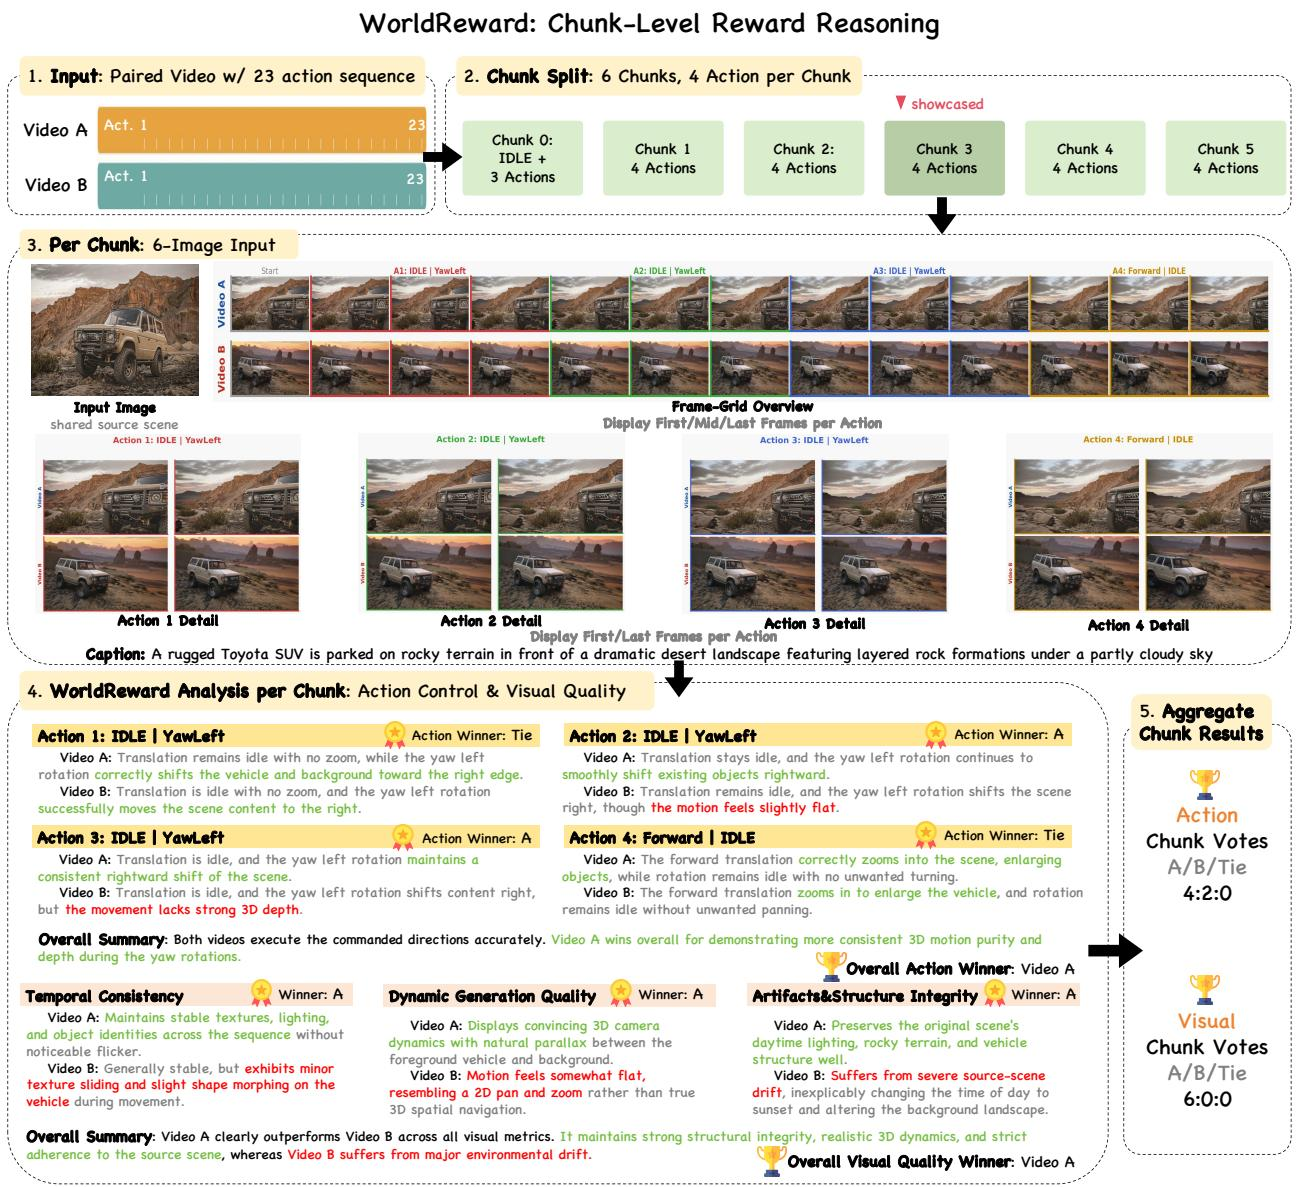
The authors propose WorldReward, a VLM-based pairwise preference reward model that unifies action-consistency and visual-quality evaluation in a single system. It divides long video pairs into temporally aligned chunks of four consecutive actions, judges each chunk from structured visual evidence such as paired frame grids and action-level panels, and aggregates chunk decisions by voting into separate global preferences. This local-to-global design lets the model verify direction-specific evidence, like content enlargement during forward motion or downward shifts during upward tilts, while also examining temporal consistency and artifact integrity. Training uses a reasoning-augmented preference dataset built from frontier-VLM distillation, multi-turn agent auditing, and human calibration, and evaluation introduces WorldReward-Bench, a human-annotated benchmark of 760 paired generations with independent labels for action, appearance, and motion quality. WorldReward achieves the highest human agreement across all dimensions, outperforming proprietary VLM judges and geometric estimators, and improves both action execution and visual quality when used as an RL reward for post-training HY-WorldPlay 1.5.
Dataset
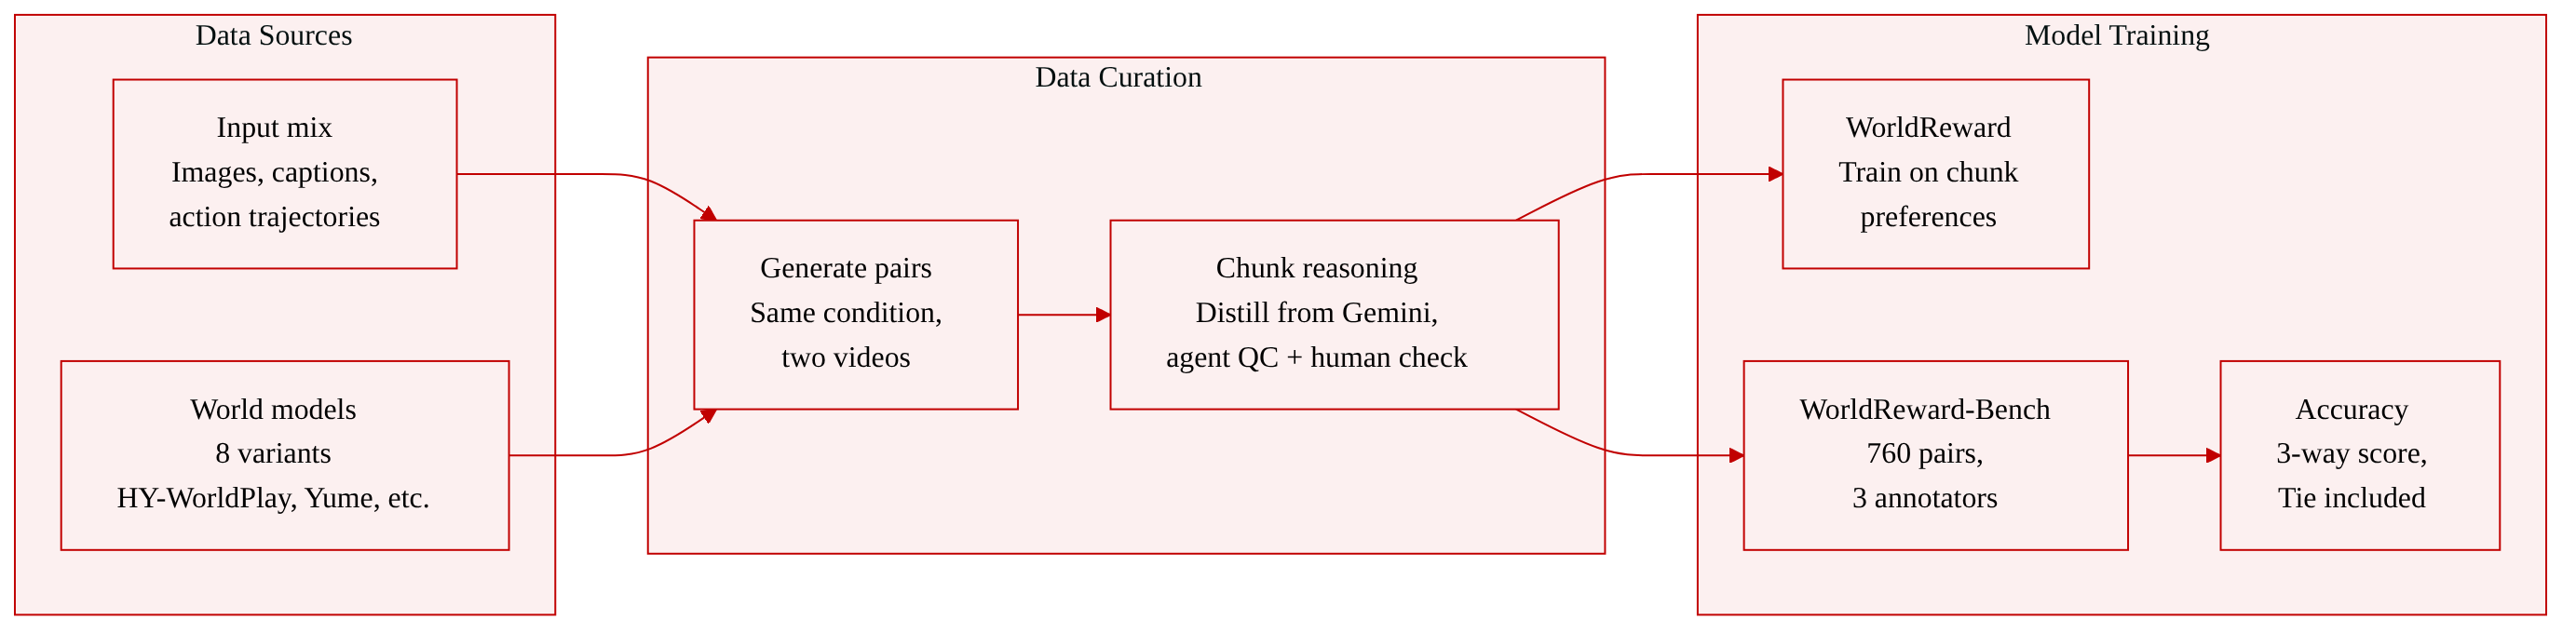
Dataset Construction and Usage
The authors construct two main datasets: a reasoning-augmented preference dataset for training the reward model, and a human-annotated benchmark for evaluation.
Reasoning-Augmented Preference Data
- Composition and sources: The dataset is built through a three-stage pipeline: preparing diverse world-model inputs, generating paired world-model outputs, and constructing chunk-level reasoning annotations with agent-assisted quality control and human review.
- Input conditions: Each condition is a tuple containing an input image, its caption, and an action trajectory. The same condition is used to generate both videos in a pair, ensuring matched visual content and camera controls.
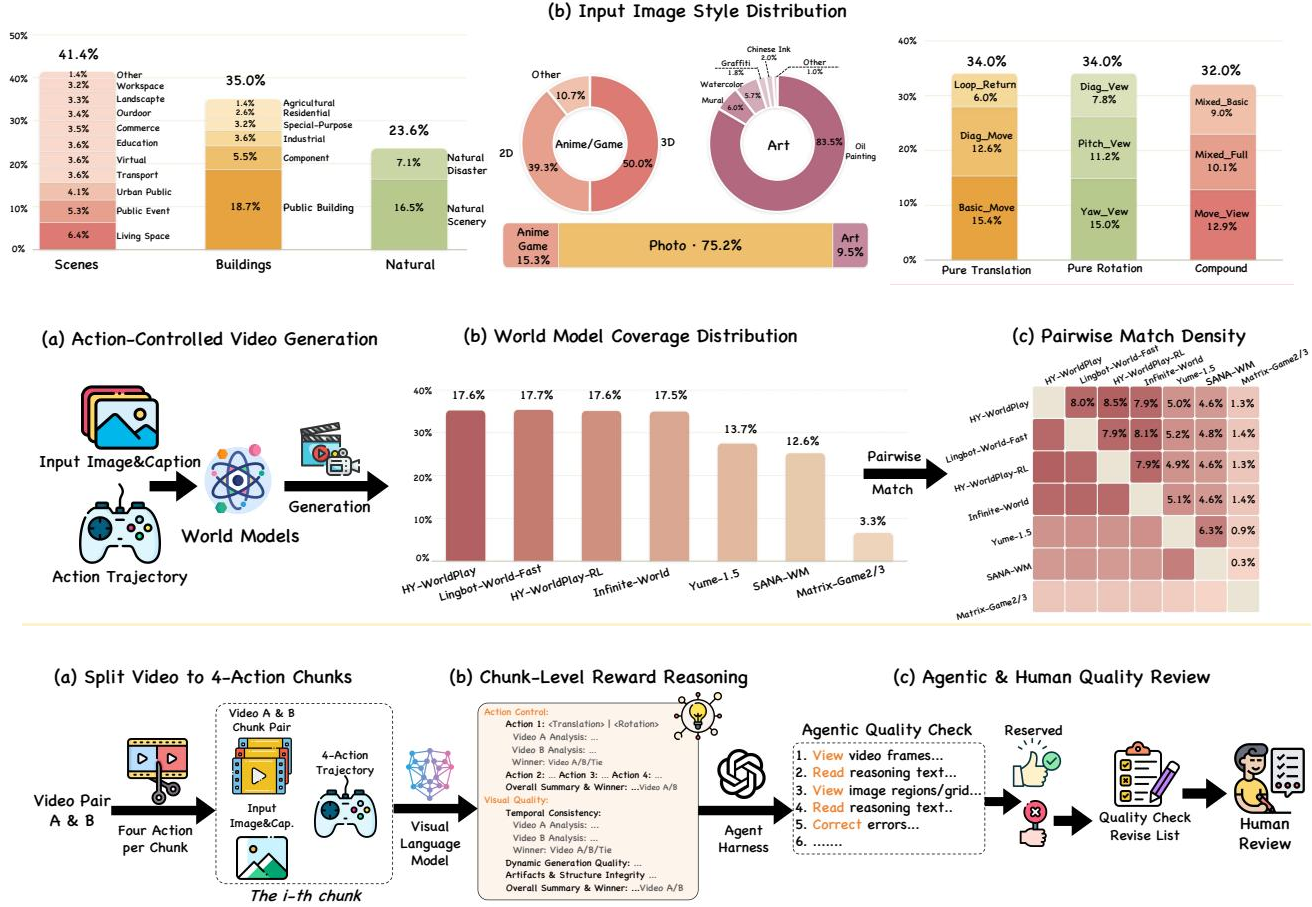
- Image coverage: Input images are organized along two axes. Content categories include scene-centric images, built environments, and natural scenes, with fine-grained categories such as living spaces, public events, urban public areas, transport, public buildings, industrial or residential scenes, natural scenery, and natural disasters. Styles are primarily photorealistic, with additional anime, game, and artistic images such as oil paintings, watercolors, murals, graffiti, and ink-style content.
- Action coverage: Trajectories are organized into three families:
- Pure Translation: Position-only camera motions without rotation. Basic_Move covers single-axis translations (forward, backward, left, right). Diag_Move combines two translation axes (e.g., forward+left). Loop_Return moves away and returns along a symmetric reverse path.
- Pure Rotation: Viewpoint-only motions with fixed position. Yaw_View rotates horizontally, Pitch_View rotates vertically, and Diag_View combines yaw and pitch changes.
- Compound: Trajectories combining translation and rotation. Mixed_Basic executes translation and rotation sequentially. Mixed_Full applies one translation axis and one rotation axis simultaneously. Move_View combines multi-axis translation with multi-axis rotation.
- Pairwise generation: Videos are generated using eight camera-conditioned world model variants, including HY-WorldPlay and its RL-post-trained variant, LingBot-World-Fast, Infinite-World, Yume-1.5, SANA-WM, and Matrix-Game models. These differ in architecture, training data, interaction horizon, and controllability. Pair assignments are balanced across major model combinations, with compatibility-aware assignment ensuring models are only evaluated on controls they support. Matrix-Game models support only a subset of trajectory families, so their pair frequencies are lower.
- Chunk-level reasoning construction: Each matched video pair is divided into fixed-size chunks aligned with corresponding frames. Structured reward reasoning is distilled from Gemini 3.1 Pro, pairing action and visual-quality preferences with evidence-based rationales.
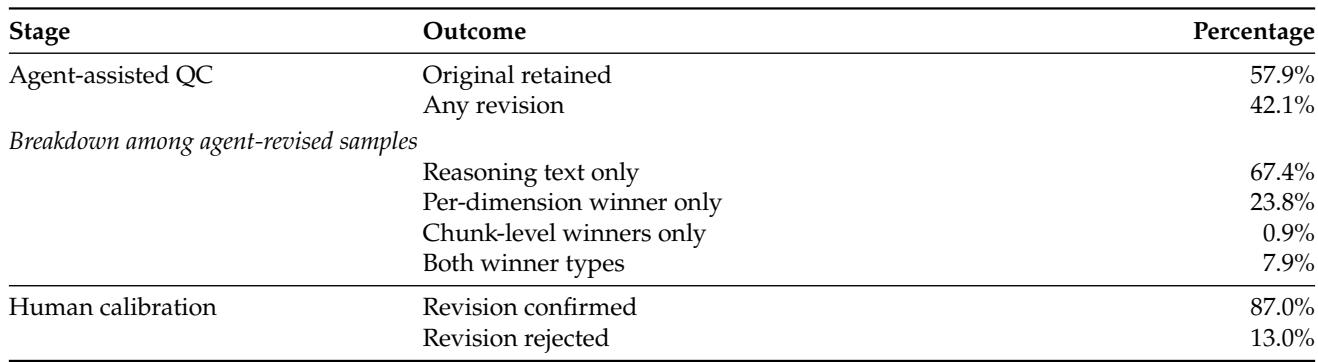
- Quality control: An agent-harness-based QC procedure using GPT-5.5 adaptively invokes image-reading tools over multiple rounds. The agent inspects the source image and frame-grid overview, selects action-level panels, and revisits evidence for cross-checking. It either retains the original verdict or returns a diff localizing corrections to a chunk and evaluation dimension. Revised samples undergo human calibration, where reviewers inspect visual evidence alongside the proposed diff. Among revised samples, 67.4% modify only reasoning text, 23.8% modify only per-dimension winners, 0.9% modify only chunk-level winners, and 7.9% modify both per-dimension and chunk-level winners. The human confirmation rate is 87.0%.
- Usage: The resulting dataset combines chunk-level multimodal inputs, evidence-based reward reasoning, and separate action-control and visual-quality preferences. This provides the supervision used to train WorldReward.
WorldReward-Bench
- Composition: A human-annotated benchmark containing 760 paired comparisons. Within each pair, two videos are generated from the same source image, caption, and action trajectory, isolating differences in trajectory execution and visual content.
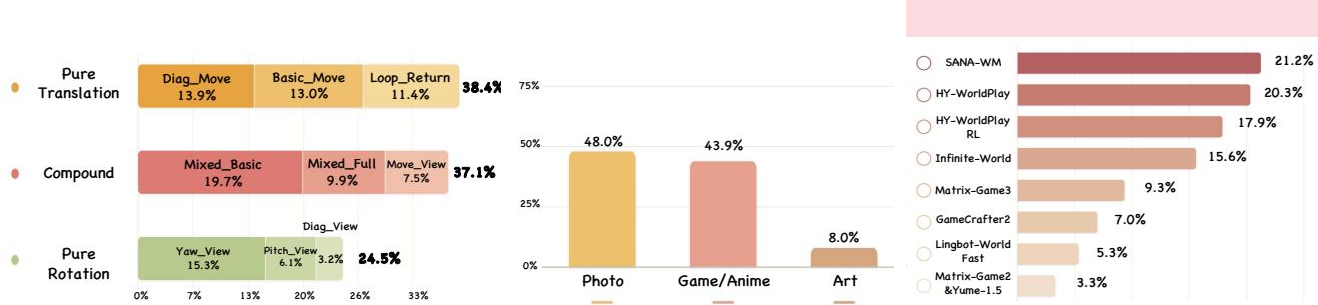
- Coverage: Pure translation and compound trajectories account for 38.4% and 37.1% of the benchmark, respectively, while pure rotation contributes 24.5%. All trajectory sub-families are represented. Style distribution includes photorealistic scenes, game/anime content, and artistic imagery. Paired videos are drawn from a broad pool of world models.
- Annotation protocol: Each pair is independently evaluated by three annotators. Model identities are hidden, and candidate order is randomized. Annotators assess three dimensions separately:
- Action consistency: How faithfully scene changes follow the prescribed trajectory, examining direction and temporal order.
- Appearance quality: Visual fidelity, temporal consistency, and preservation of scene content and structure.
- Motion quality: Plausibility and smoothness of generated dynamics.
- Annotators complete a calibration round before annotation. They select A or B only when one candidate shows a clear advantage; otherwise, they assign Tie. Each dimension is considered independently.
- Label determination: The benchmark label is determined by majority vote for each dimension. Cases without a majority, including three-way disagreements, are reviewed by an additional annotator under the same criterion.
- Evaluation metric: Three-way preference accuracy is reported over all pairs, treating Tie as an explicit label.
Method
The authors formulate the reward modeling problem for camera-conditioned world models as a paired comparison setting. Given a source image, its caption, and a camera or action trajectory, two candidate videos are generated. The reward model must predict dimension-specific preferences for action consistency and visual quality. Rather than processing the full video as a single unstructured input, which can dilute local motion errors and overwhelm the model, the authors decompose the action trajectory into temporally ordered chunks.
As shown in the figure below, each chunk contains a short segment of consecutive actions and the corresponding decoded frame blocks from both candidates. The structured visual input for each chunk consists of the source image to detect scene drift, a frame-grid overview displaying the start, middle, and end frames of each action to inspect temporal consistency, and action-level detail panels comparing the first and last frames of the corresponding action segment from the two videos. This organization allows the model to ground its judgment in localized evidence before aggregating decisions.
For each action-video chunk, the model performs pairwise reward reasoning at both the action and visual-quality levels. For action control, it compares the two videos for each action in the chunk to determine if the local scene transition follows the commanded direction, then summarizes these into an overall action winner. For visual quality, it evaluates temporal consistency, dynamic generation quality, and artifact and structure integrity.
Let rkact and rkvis denote the action and visual-quality winners predicted for chunk k, where each winner belongs to {A,B,Tie}. The chunk-level decisions are aggregated across all K chunks by voting to produce the global action winner Ract and global visual-quality winner Rvis:
Rm=⎩⎨⎧A,B,Tie,nAm>nBm,nBm>nAm,nAm=nBm,m∈{act, vis}.where ncm is the number of chunks favoring candidate c. This local-to-global principle ensures that fine-grained judgments are combined into robust video-level reward signals.
To train a reliable reward model, the authors construct a reasoning-augmented preference dataset through a three-stage pipeline.
As shown in the figure below, the pipeline begins with preparing diverse world-model inputs across various content categories, visual styles, and trajectory families including pure translation, pure rotation, and compound motions. Next, pairwise reward data is generated using a diverse pool of camera-conditioned world models, ensuring matched visual content and action difficulty. Finally, chunk-level reasoning annotations are constructed. The authors first distill structured reward reasoning from a large vision-language model, pairing preferences with evidence-based rationales. An agent-assisted quality-control stage then adaptively inspects the visual evidence to reduce distillation noise, followed by human calibration to verify the proposed revisions.
The authors formulate reward-model training as supervised fine-tuning of a multimodal large language model. Let D={(zi,si)}i=1M denote the chunk-level training set, where zi is the structured multimodal input and si is the target response containing the reasoning and categorical preferences. Using teacher forcing, they optimize the standard autoregressive language-modeling objective:
LSFT(θ)=−∑i=1MLi1i=1∑Mt=1∑Lilogpθ(si,t∣zi,si,<t).This objective teaches the model to explain the relevant visual evidence and produce the corresponding action and visual-quality preferences.
The authors further leverage WorldReward to provide reinforcement signals for post-training world models. They retain a clip-level rollout framework where candidate clips are sampled from independent initial noises. For every unordered candidate pair, WorldReward constructs the same chunk-level reward input and produces dimension-specific preferences. These categorical comparisons are converted into pairwise win-rate rewards, which are then standardized within each rollout group to compute advantages. The two advantages are combined into an optimality probability, which is used in a negative-aware flow-matching objective to update the world-model policy. This design preserves the efficiency of clip-level long-horizon post-training while explicitly balancing action execution and visual quality through a shared interpretation of the visual context.
To evaluate how reliably reward models reproduce human preferences, the authors construct a human-annotated benchmark.
As shown in the figure below, the benchmark is designed to cover diverse camera controls, visual styles, and world-model sources. It includes pure translation, compound, and pure rotation trajectories, along with photorealistic, game and anime, and artistic imagery. Each video pair is independently evaluated by annotators who assess action consistency, appearance quality, and motion quality separately, with the final label determined by majority vote.
Experiment
The experiments validate WorldReward, a reward model trained on paired world-model videos with structured reasoning annotations, against human preferences on a held-out benchmark and in post-training applications. WorldReward outperforms proprietary VLMs, learned preference models, and geometry-based estimators across action consistency, appearance, and motion quality, and generalizes across diverse trajectories and visual domains. When applied to post-train a world model, it improves both action adherence and visual quality over existing baselines, with gains confirmed by human evaluation. Ablations show that annotation refinement, structured visual evidence, and per-video reasoning supervision are key contributors, while the model remains robust to candidate ordering and its judgments align closely with humans on individual pairs.
The agent-assisted quality control pipeline retained 57.9% of original chunk-level annotations and revised 42.1%, with most revisions involving reasoning text only. Human reviewers then confirmed or rejected the agent-proposed revisions, providing a final layer of supervision. Over half of the chunk-level annotations were kept unchanged by the agent harness. Among revised samples, the majority were updated only in reasoning text, while a smaller portion involved per-dimension winner changes. A small fraction of revisions included chunk-level winner changes, either alone or combined with per-dimension winners.
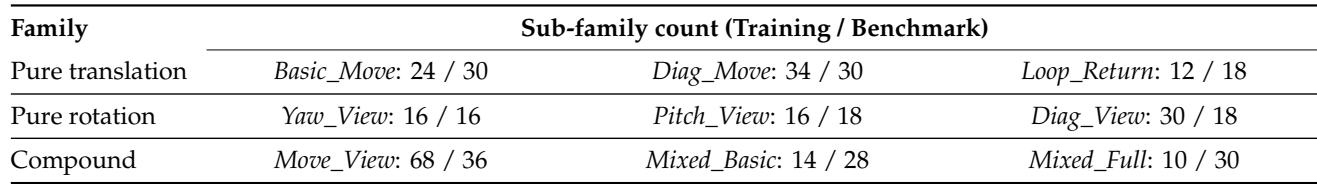
The training and benchmark trajectory libraries are independently constructed but share the same taxonomy of nine sub-families, with counts varying across categories such as translation, rotation, and compound motions. The benchmark uses longer trajectories (23 steps vs. 11) and shifts the distribution within each sub-family to test generalization rather than memorization. The benchmark library is independently built with 224 trajectories, each containing 23 action steps, compared to 11 steps in the training library. Sub-family counts differ between training and benchmark, with notable increases in compound categories like Mixed_Basic (14 to 28) and Mixed_Full (10 to 30), while Move_View decreases from 68 to 36. The distribution shift within the same trajectory taxonomy is intentional to evaluate transferable action-video relations.
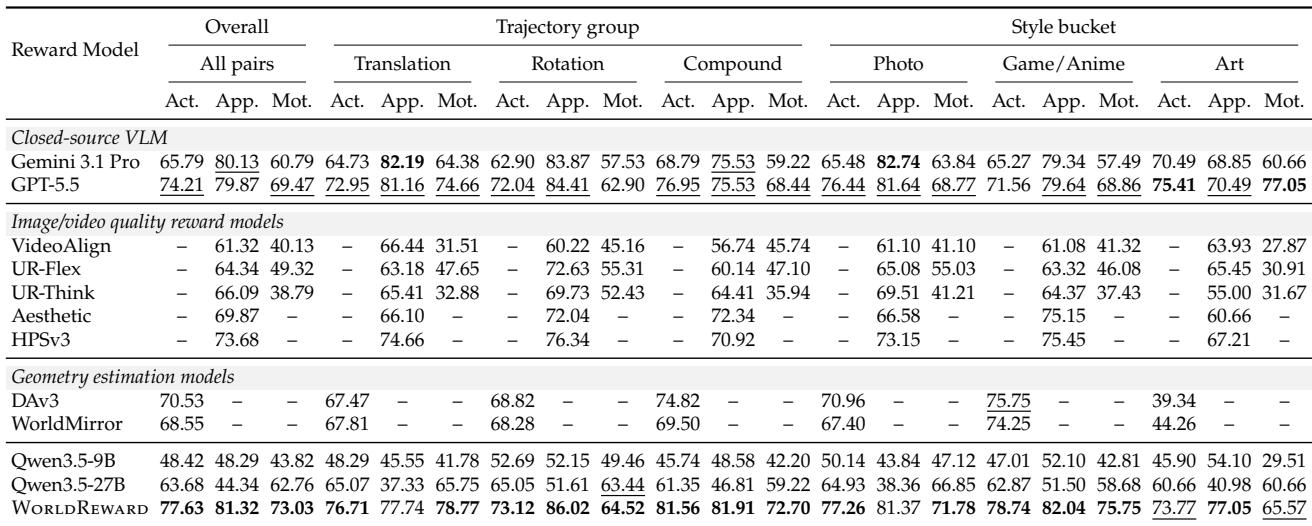
WorldReward achieves the highest overall agreement with human preferences across action consistency, appearance quality, and motion quality, outperforming both closed-source VLMs and image/video quality reward models. Its joint reasoning about action execution and visual content enables reliable judgments on all three dimensions, including on compound trajectories and across diverse visual domains. WorldReward surpasses closed-source VLMs on all three dimensions, with the largest gains in action consistency and motion quality. Geometry estimators capture action signals but cannot assess visual consequences, while image/video preference models miss action adherence. WorldReward leads on compound trajectories, indicating reliable action judgments beyond isolated movements. Across visual domains, WorldReward achieves top action and motion agreement on photorealistic content and highest appearance agreement on artistic content.
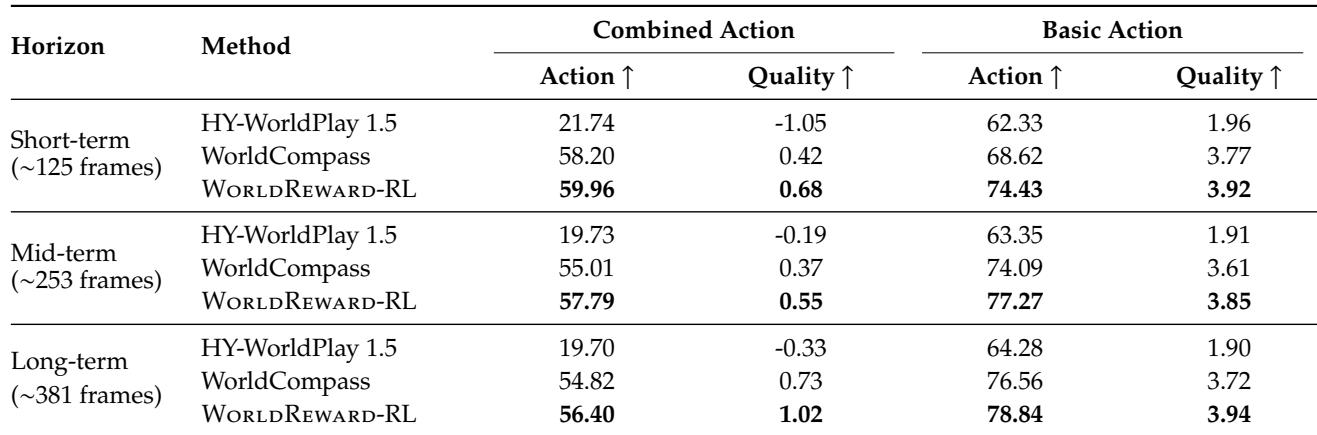
Post-training with WorldReward-RL improves action-adherence accuracy and visual quality over WorldCompass across all horizons and action types. The gains are consistent for both basic and combined actions, with visual quality also improving, indicating no trade-off between command following and appearance. WorldReward-RL outperforms WorldCompass on combined-action accuracy by 1.58-2.78 points and on basic-action accuracy by 2.28-5.81 points across all horizons. HPSv3 visual quality scores increase for both action types and all horizons, with combined-action scores rising by 0.18-0.29 and basic-action scores by 0.15-0.24. At the longest horizon, WorldReward-RL achieves higher HPSv3 scores than WorldCompass for both combined and basic actions, showing sustained improvement over longer generations.
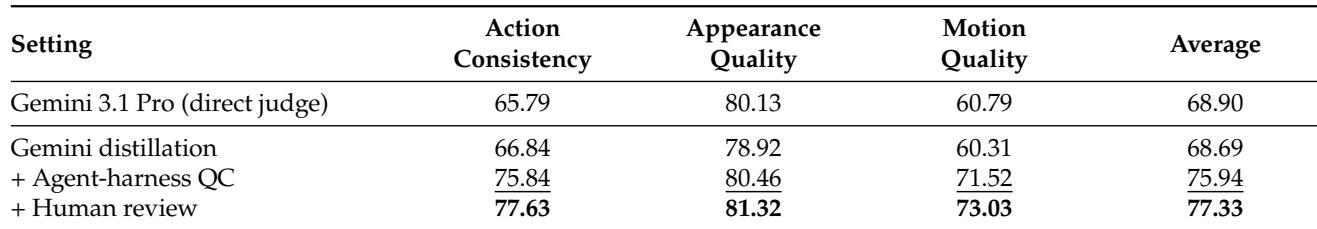
Distilling Gemini 3.1 Pro into the reward model largely preserves direct judge agreement with a slight gain in action consistency but small losses in appearance and motion quality. Substantial improvement comes from agent-harness quality control and human review, which together raise average agreement and yield the best scores across all dimensions. Agent-harness quality control raises average agreement from 68.69% to 75.94%, with the largest gains in action consistency and motion quality. Human review adds a further 1.39-point improvement and produces the best agreement across all three dimensions. The final advantage over direct VLM judging comes primarily from annotation refinement rather than distillation alone.
The evaluation setup combines an agent-assisted quality control pipeline with human review to refine preference annotations, retaining most original labels while revising a minority, primarily in reasoning text. WorldReward, a reward model trained on this data, achieves the highest agreement with human preferences across action consistency, appearance, and motion quality, outperforming closed-source VLMs and other reward models. Post-training with WorldReward-RL improves both action adherence and visual quality over the base model across all horizons and action types, showing no trade-off between command following and appearance. Ablations confirm that the main performance gain comes from the agent-harness annotation refinement and human review, rather than distillation alone, which only slightly shifts agreement scores.