Command Palette
Search for a command to run...
ENEAS: 임베딩 기반 신경 앙상블을 통한 적응형 분할
ENEAS: 임베딩 기반 신경 앙상블을 통한 적응형 분할
Javier del Pino Salvador Rodríguez Alejandro Garabito Javier Álvarez Chema Garabito
초록
우리는 인스턴스 추적과 의미론적 발견을 위한 통합적이고 텍스트 프롬프트 가능한 방법인 ENEAS를 제시한다. SAM 3 [6]과 같은 최신 파운데이션 모델을 포함한 텍스트 프롬프트 가능한 분할 모델들은 여전히 시간적 환각, 공간적 조각화, 의미론적 오분류 문제를 겪고 있다. 즉, 객체가 시야에서 벗어날 때 대상 부재를 보고하지 못하고, 극단적인 근접 촬영에서 완전한 객체 대신 국부적인 질감을 분할하며, 시각적 특징을 존재론적 현실보다 우선시하여 조각상, 그림, 반사와 같은 시각적으로 유사한 사물을 대상 엔티티로 분할한다. ENEAS는 단일 방법으로 두 가지 방식으로 작동한다: 고유 인스턴스의 정밀한 추적과 고품질 분할, 그리고 의미론적 검증 계층에 의해 해결되는 텍스트 쿼리가 지칭하는 모든 인스턴스의 개방형 개념 발견이다. 추적을 위해 우리는 이전에 포인트 상호작용으로 제한되었던 기하학적으로 강건한 SeC 아키텍처를 텍스트 프롬프팅 어댑터로 확장하고 그 시간적 메모리를 활용하여, 대상이 사라짐에도 불구하고 방해 요소로 표류하지 않고 유지되며, 대상이 전체 화면을 채울 때에도 온전하게 유지되도록 한다. 발견을 위해 검증 계층은 고속 시각적 임베딩 매칭과 조건부 VLM 정제를 결합하여, 모호한 후보에 대해서만 의미론적 추론을 호출함으로써 시각적 모델만으로는 구분할 수 없는 존재론적 오류를 걸러내면서도 지연 시간을 낮게 유지한다. 단일 오분류 방해 요소가 자산을 손상시키는 3D 재구성을 염두에 두고 설계된 ENEAS는 비디오, 광범위한 라이브러리, 시간적 또는 공간적으로 정렬되지 않은 데이터 컬렉션의 고품질 의미론적 추적 및 분할을 가능하게 하며, 실제 인스턴스와 그 도플갱어(닮았지만 동일하지 않은 것)를 구별하는 능력을 제공한다. 코드와 모델은 github.com/speridlabs/eneas에서 제공된다.
One-sentence Summary
SperidLabs presents ENEAS, a unified text-promptable method for instance tracking and semantic discovery that extends the SeC architecture with a text-prompting adapter and temporal memory to prevent drift and fragmentation, while a semantic verification layer combining visual embedding matching with conditional VLM refinement filters ontological errors like statues or reflections, enabling high-quality segmentation for 3D reconstruction.
Key Contributions
- Introduces ENEAS, a unified text-promptable method for instance tracking and semantic discovery, extending the SeC architecture with a text-prompting adapter and temporal memory to report target absence and keep objects whole under extreme scale changes.
- For semantic discovery, decouples geometric proposal from semantic verification, combining a sigmoid-based embedding filter with prompt ensembles and a conditional VLM judge invoked only for ambiguous candidates, filtering ontological errors while keeping latency low.
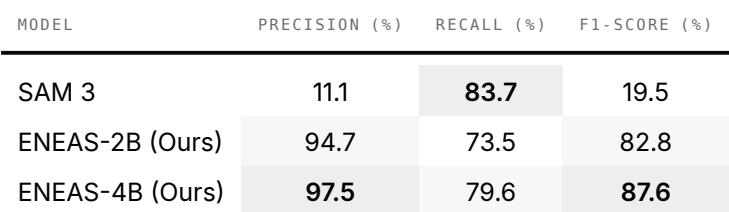
- On the Church Statues dataset, raises F1 from 19.5% for SAM 3 to 82.8% with a 2B judge and 87.6% with a 4B judge while maintaining precision above 94%, and matches or improves the tracking profile of SAM 3 on SA-Co/VEval.
Introduction
Text-guided segmentation has become a core tool in modern visual understanding, letting users name an object and receive pixel-accurate masks across video or unordered image collections. However, current foundation models like SAM 3 still struggle with temporal hallucinations, spatial fragmentation, and semantic misclassification: they fail to report when a target leaves the view, segment local textures instead of whole objects during close-ups, and prioritize visual similarity over ontological reality, so statues or paintings get masked as people. Prior work either lacks a notion of identity, causing drift to distractors, or relies on visual priors alone, which cannot distinguish true instances from lookalikes.
The authors present ENEAS, a unified method that handles both specific instance tracking and open-concept semantic discovery within one framework. For tracking, they extend the memory-based SeC architecture, previously limited to point interactions, with a text-prompting adapter, enabling the target to be held through disappearance without drifting and kept whole under extreme scale changes. For discovery, they combine high-speed sigmoid-based embedding matching with a conditional vision-language model (VLM) judge, invoked only for ambiguous candidates, which filters out ontological errors while keeping latency low. Designed for 3D reconstruction, where a single misclassified distractor corrupts the asset, ENEAS delivers precise semantic tracking and segmentation across ordered video, broad libraries, and unordered collections, with the discrimination to tell true instances from their doppelgangers.
Dataset
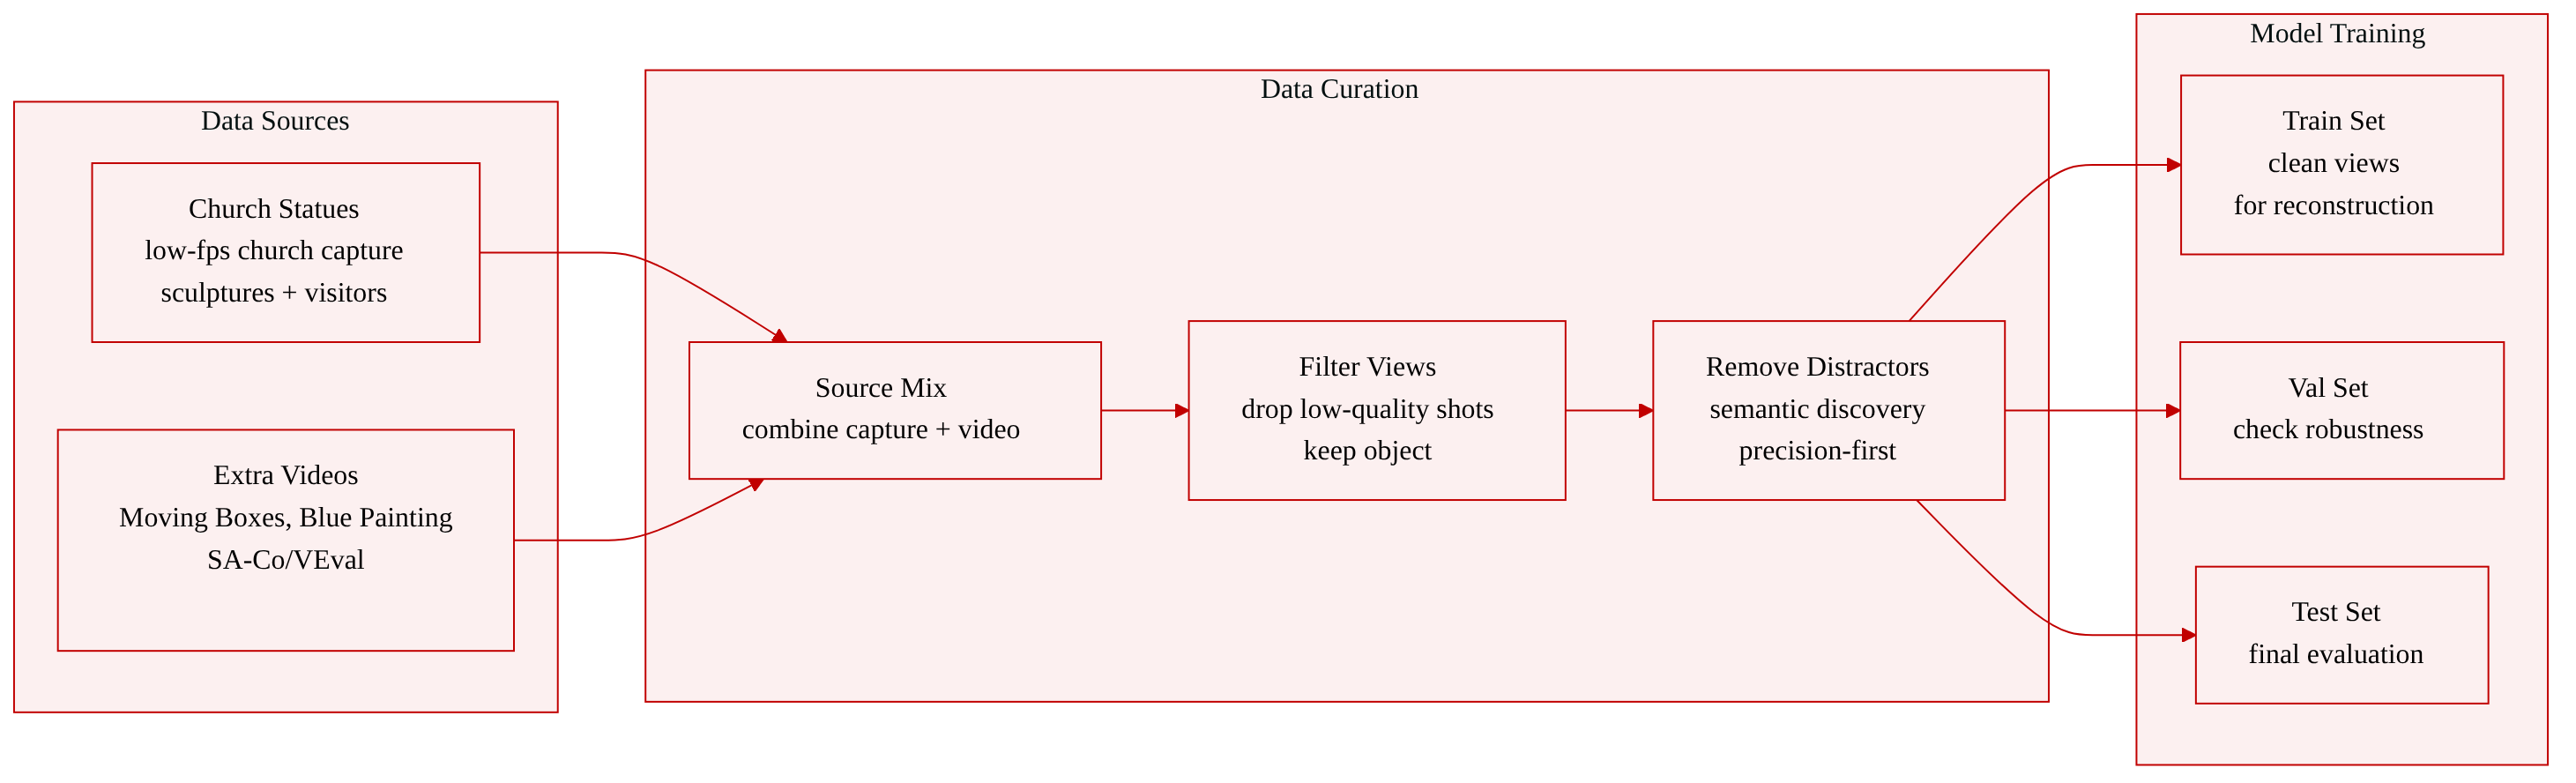
The authors design ENEAS for 3D reconstruction and novel view synthesis. In this setting, a capture is a collection of photographs or a low frame rate video where views differ widely in viewpoint, often lack temporal order, and occlude the subject to varying degrees. Before reconstruction, the system must decide for each view what to keep and what to remove. Instance tracking isolates the object to reconstruct, while semantic discovery removes distractors (typically people) to avoid ghost artifacts. The authors note that errors are asymmetric: a false positive masks part of the asset and destroys it, while a false negative leaves a visible artifact. This asymmetry motivates a precision-first design. The capture regime makes the approach affordable because most views contain few or no distractors, so an embedding filter resolves them and a vision language model (VLM) is rarely invoked. The process is offline, so a few seconds per image amounts to minutes for hundreds of views, which is negligible compared to reconstruction time.
The primary dataset is Church Statues, consisting of frames from a low frame rate recording of a church interior acquired for 3D reconstruction. The scene contains hyper-realistic religious sculptures alongside visitors, where sculptures must be preserved and visitors removed. This setup naturally maximizes ontological ambiguity for the prompt "person." The authors manually produced ground-truth instance annotations for this dataset.
Two additional datasets are used for robustness verification beyond the capture scenario:
- Moving Boxes: an indoor scene where people carry and stack boxes among furniture, occluding each other and the chairs.
- Blue Painting: a dynamic indoor sequence where a single painting undergoes viewpoint changes, occlusions, and close-ups.
These two, together with the external SA\uee55Co/VEval benchmark, are conventional video datasets used to confirm that the robustness achieved in the capture scenario holds in more standard settings.
Method
ENEAS is a single method that takes a natural-language prompt and a set of frames and returns binary masks. It is built on shared components: Florence-2 grounds the prompt into image regions, and a Segment Anything model produces the final masks. Depending on whether the prompt refers to a specific instance (e.g., “the blue painting”) or to a category (e.g., “person”), the method either propagates a single initialization through time or verifies every candidate region semantically.
Given a collection of frames {It}t=1N, It∈RH×W×3, which may or may not be temporally ordered, and a natural-language prompt p, ENEAS returns binary masks. When p designates a specific instance, the output is one mask per frame, Mt∈{0,1}H×W, with Mt=0 whenever the object is not visible. When p names a category, the output is a set of masks per frame, {Mt(i)}i=1nt, one per instance, where the number of instances nt varies from frame to frame. Both cases share a grounding operator G(I,p) that returns image regions matching p, and a segmentation operator S(I,r) that turns a region r into a mask.
For tracking a specific object defined by the user (e.g., “the blue car”), ENEAS builds upon the SeC architecture, which extends SAM 2 with a concept-level memory of the target. Rather than matching appearance alone, the tracker maintains a high-level representation of what the object is, which makes it robust to drastic viewpoint changes and to the target leaving and re-entering the view. Since SeC natively supports only point-based interaction, the authors add a text-driven initialization: on a reference frame It0, the grounding operator locates the object described by the prompt, r0=G(It0,p), and this single region initializes the tracker. Every other mask is then obtained by propagation,
Mt=T(It∣r0,Ht),where T is the SeC tracker and Ht its memory of the frames already processed, so that identity is enforced throughout: when the object is not visible, Mt is empty rather than drifting to a look-alike. Two interaction modes are supported, points for maximum precision and natural language for ease of use, and the reference frame may be chosen anywhere in the sequence.
For semantic discovery, ENEAS re-evaluates every frame, so that new instances entering the scene are found without re-prompting. It is organized as a cascade of stages of increasing cost, each applied only to the candidates the previous one could not resolve. The complete decision flow is visualized in Figure 1.
The first stage is region proposal. The grounding operator, instantiated with Florence-2, proposes a set of candidate regions for the requested category on every frame, Rt=G(It,p), and duplicate proposals are merged. This stage is deliberately permissive: it should miss nothing, at the cost of proposing distractors that later stages must remove.
The second stage is embedding verification. Each candidate is scored against the category with a vision-language embedding model, SigLIP 2, that judges every image-text pair independently, so that the presence of other objects in the crop does not suppress the score of the target. To make the scores robust to the difference between the whole images the model was trained on and the crops it sees here, several phrasings of the category are averaged into a single score s(r)∈R per candidate. Two thresholds, τrej<τacc, split the candidates into three groups:
r↦⎩⎨⎧acceptdiscardverifyif s(r)≥τacc,if s(r)<τrej,otherwise,so that clearly matching candidates are accepted, clearly non-matching ones are discarded, and the remainder, the uncertainty interval, is deferred to the next stage. The two thresholds are the knobs that trade latency against semantic rigor.
The third stage is semantic verification. Only candidates in the uncertainty interval are shown to a vision-language model, Qwen3-VL, acting as a judge that returns a binary verdict v(r)∈{0,1}. It is asked whether the region truly is an instance of the category and not a look-alike such as a statue, a mannequin, or a picture. Pixels belonging to neighbouring candidates are masked out so that the judgement concerns the candidate alone, and the model answers in a fixed format without free-form reasoning, which keeps the cost of each verdict low. Because this stage is reached only by genuinely ambiguous candidates, its cost scales with the ambiguity of the scene rather than with the number of objects in it.
The final stage is mask generation. The accepted set At, made of the candidates accepted directly and those with v(r)=1, is passed to the segmentation operator, instantiated with SAM 2 from the Segment Anything family, giving one mask per instance, Mt(i)=S(It,ri) for ri∈At.
The architecture described above is the result of a rigorous iterative process aimed at resolving specific trade-offs between recall, precision, and computational latency. Recall is defined as the system’s capacity to detect every instance of the target category, minimizing false negatives. Precision denotes the ability to rigorously distinguish the target concept from semantic distractors, ensuring that false positives are eliminated. The authors detail the evolution of the method through four distinct development phases.
In Phase 1, the initial approach employed a detect-filter-validate strategy. The authors implemented an exhaustive dense object captioning mechanism to generate bounding boxes with rich textual descriptions for all salient elements in the scene. To alleviate the load on the validation stage, they applied an intermediate textual filter, computing semantic similarity between the generated descriptions and the target prompt using text-only embeddings. For final validation, they attempted to optimize throughput using a composite visual prompting strategy, constructing a single query image containing the full frame annotated with color-coded, numbered bounding boxes, supplemented by a grid of spatially clustered crops. The downstream vision-language model was queried with a complex, multi-step prompt to iterate through and validate each numbered instance sequentially. This approach exhibited critical failure modes. The textual filter depended strictly on the generative fidelity of the region proposal network, and the generation module frequently assigned arbitrary proper nouns (e.g., labeling a statue as “Saint Christian”) to generic objects, bypassing the semantic filter. The approach also suffered from spatial aggregation, frequently merging distinct semantic entities into single bounding boxes, which rendered precise instance segmentation impossible. The high cognitive load of the multi-target association task within a single prompt necessitated deep reasoning, introducing prohibitive latency starting at a minimum of 15 seconds per frame and escalating significantly in dense scenes.
In Phase 2, to address spatial aggregation and recall issues, the authors transitioned to a text-conditioned region proposal strategy. By explicitly prompting the detector with the target category, they improved instance separation but introduced a high rate of false positives. They attempted to filter these candidates using contrastive vision-language embedding matching, initially computing the softmax probability of the target text against generic negative classes such as “background” and “other object.” To improve granularity, they implemented a secondary object detection pass to identify specific objects present in the scene and included these dynamic labels in the softmax computation. However, this approach revealed the fundamental deficiency of applying global softmax normalization to this task. The mutual exclusivity constraint inherent in the softmax function forces class probabilities to compete. In scenarios where a target object co-occurred with highly salient attributes identified in the secondary pass, such as a person holding a microphone, the model suppressed the target class probability in favor of the accessory’s label, making it impossible to define a stable acceptance threshold.
In Phase 3, to resolve the score suppression issue, the authors implemented a sigmoid-based vision-language embedding matching. This architecture employs a pairwise sigmoid loss, treating each image-text pair as an independent binary classification problem, effectively decoupling the target object’s score from the presence of other semantic concepts in the crop. They utilized an encoder optimized for native aspect ratios, which preserves the dense features of variable-size crops better than standard fixed-resolution encoders. Despite these improvements, they observed performance degradation caused by the domain shift between the model’s full-image pretraining and crop-level inference inputs. To mitigate this, they implemented a prompt ensemble strategy, averaging embeddings across multiple template variations to enforce robustness in the visual signal.
In Phase 4, despite the improved embedding filter, a zone of uncertainty persisted where visual embeddings alone failed to resolve ontological ambiguities, such as hyper-realistic statues. To address this, the authors integrated a lightweight VLM. Initially, executing the model with its native deep reasoning capability proved accurate but incurred significant latency due to extensive token generation. Furthermore, the model struggled with contextual interference from neighboring objects within the crop. To mitigate this, they apply black masking to isolate the target pixel-wise. They then disabled the deep reasoning mechanism in favor of a structured analytic prompt with explicit critical thinking constraints, forcing the model to verify the ontology without the overhead of generating internal reasoning tokens. By restricting this validation to the uncertainty interval, they achieve high semantic precision while reducing verification latency to approximately one second on resource-constrained hardware.
Experiment
The experiments validate ENEAS across instance tracking and semantic discovery, with emphasis on the latter due to its novel cascaded verification combining embedding filters and VLMs. On the Church Statues capture, which maximizes ontological ambiguity between real people and hyper-realistic statues, ENEAS achieves a fourfold F1 improvement over SAM 3 by trading recall for precision, while ablations confirm that the VLM referee is essential for resolving cases where visual embeddings fail, and that a robust threshold configuration provides the best accuracy-efficiency balance. Instance tracking tests on Blue Painting show ENEAS maintains identity under occlusion and scale changes better than per-frame detection baselines, and on Moving Boxes it adapts to standard scenes with near-perfect F1 at reduced latency. Scaling the VLM from 2B to 4B improves F1 from 82.8% to 87.6% but increases latency by 52%, establishing the 2B model as the default for general use.
ENEAS models outperform SAM 3 on Church Statues, with the 4B variant achieving the highest F1-score by resolving ambiguous cases, though at increased latency. The system adapts its configuration based on scene complexity, trading speed for accuracy only when needed. ENEAS-4B reaches the best F1-score of 87.6%, surpassing both ENEAS-2B and SAM 3. SAM 3 has very low precision (11.1%) despite high recall, indicating many false positives. The 2B model's lower F1-score is attributed to overreasoning on unambiguous samples, introducing stochastic errors. Using a faster mode on a standard scenario reduces latency to 1.14 seconds per frame, a three-fold speedup, while maintaining near-perfect F1-score of 98.0%. The 4B model improves F1-score by 4.8 points over the 2B model but increases latency by 52%.
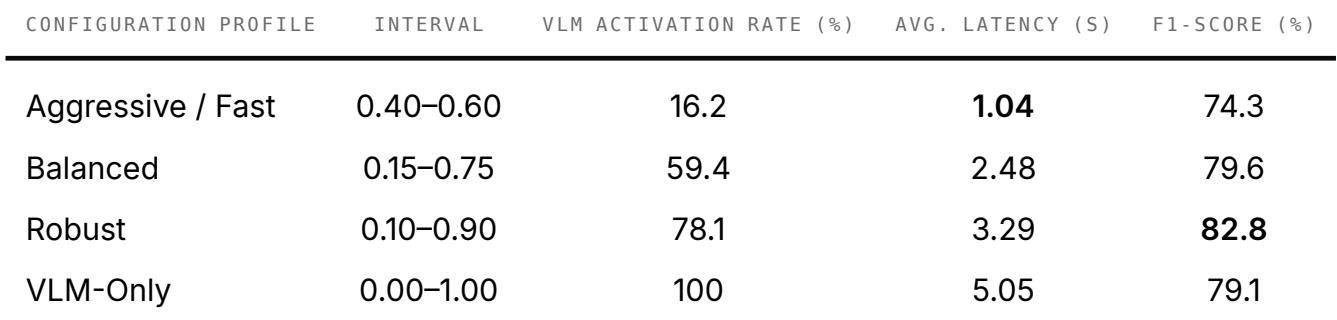
The table shows how varying the uncertainty interval affects the trade-off between VLM activation, latency, and accuracy. Wider intervals increase VLM usage and latency but improve F1-score up to a point, after which full VLM activation reduces accuracy due to overreasoning. The balanced and robust configurations offer better accuracy than the VLM-only approach while maintaining lower latency. Widening the uncertainty interval raises VLM activation and latency, with F1-score peaking at the robust configuration before declining under full VLM activation. The VLM-only configuration yields lower accuracy than the robust configuration, indicating that overusing the VLM on unambiguous samples introduces errors. The robust configuration achieves the highest F1-score but at more than three times the latency of the aggressive configuration.
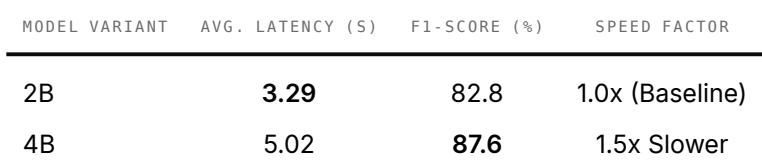
Increasing the vision-language model size from 2B to 4B improves F1-score from 82.8% to 87.6% but raises average latency from 3.29 to 5.02 seconds, a 52% increase. The 2B model is the default for its better efficiency-accuracy trade-off, while the 4B variant is offered for offline use where higher accuracy is prioritized. The 4B model achieves a higher F1-score than the 2B baseline, resolving more ambiguous cases. Latency increases by about 52% when switching from the 2B to the 4B model. The 2B model is selected as the default due to its optimal balance of speed and accuracy, while the 4B is a configurable option for offline scenarios.
ENEAS models outperform SAM 3 on Church Statues, with the 4B variant achieving the highest F1-score by resolving ambiguous cases, though at increased latency. The system adapts its configuration based on scene complexity, trading speed for accuracy only when needed. ENEAS-4B reaches the best F1-score of 87.6%, surpassing both ENEAS-2B and SAM 3. SAM 3 has very low precision (11.1%) despite high recall, indicating many false positives. The 2B model's lower F1-score is attributed to overreasoning on unambiguous samples, introducing stochastic errors. Using a faster mode on a standard scenario reduces latency to 1.14 seconds per frame, a three-fold speedup, while maintaining near-perfect F1-score of 98.0%. The 4B model improves F1-score by 4.8 points over the 2B model but increases latency by 52%.