Command Palette
Search for a command to run...
인과 기반 모델
인과 기반 모델
Christopher Stith Hossein Rahmani Jesse C. Cresswell
초록
인과 추론은 데이터로부터 치료나 개입의 효과를 추정하는 실천입니다. 전통적으로 인과 추론은 각각의 새로운 문제에 대해 맞춤형 파이프라인을 요구합니다: 먼저 인과 메커니즘을 제안하고, 호환되는 추정기를 선택한 다음, 마지막으로 이를 훈련하는 것입니다. 한편, 다양한 환경과 양식에 걸쳐 머신러닝의 많은 부분이 기반 모델 패러다임으로 전환되었습니다: 네트워크를 한 번 대규모로 사전 훈련하고 미세 조정 없이 새로운 작업에 적용하는 방식입니다. 인과 기반 모델(CFM)은 이러한 패러다임을 인과 추론에 도입합니다. CFM은 사전 훈련된 신경망으로, 모델 업데이트 없이 문맥 내 학습을 사용하여 완전히 새로운 데이터셋에서 평균 치료 효과와 같은 인과적 수량을 추정합니다. 본 연구는 이 새로운 분야에 대한 실용적인 소개를 제공합니다. CFM을 논의하기 전에 인과 추론과 머신러닝에 필요한 배경 지식을 요약합니다. 전반에 걸쳐 예제 코드와 Jupyter 노트북을 포함하며, 이는 아이콘을 클릭하여 접근할 수 있습니다. 전체 코드베이스는 github.com/layer6ai-labs/cfms에서 제공됩니다.
One-sentence Summary
Researchers from Layer 6 AI and TD Bank Group introduce causal foundation models (CFMs), pretrained neural networks that estimate causal quantities such as the average treatment effect on entirely new datasets via in-context learning without model updates, and provide a practical introduction to this emerging area with example code and Jupyter notebooks.
Key Contributions
- This paper provides a practical, hands-on introduction to causal foundation models (CFMs), including example code and Jupyter notebooks, with the full codebase released at github.com/layer6ai-labs/cfms.
- The work formalizes CFMs as pretrained transformer-based models that estimate causal quantities (e.g., conditional average treatment effects, conditional interventional distributions) via in-context learning on new datasets without fine-tuning, and situates this definition against precursor work such as CaML, BBCI, and CInA.
- Empirical results show that current CFMs achieve competitive performance on causal benchmarks while drastically reducing deployment time compared to traditional estimators that require per-problem training and tuning.
Introduction
Causal inference is central to answering interventional questions across economics, medicine, and policy, where the goal is to estimate effects of treatments or policies rather than mere correlations. Traditional estimation methods, such as Bayesian additive regression trees, double machine learning, and causal forests, require a labor-intensive pipeline for each new problem: proposing a causal mechanism, selecting an estimator, tuning hyperparameters, and training, with no reuse across tasks. This limits scalability and speed, especially in real-world settings with large or diverse datasets.
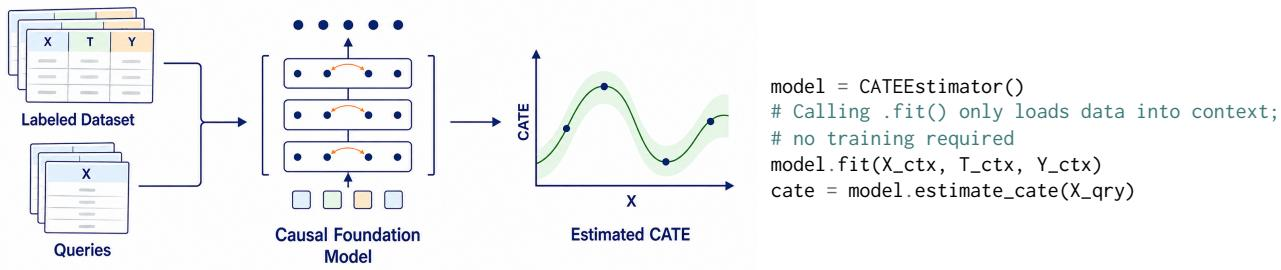
To address these limitations, the authors introduce causal foundation models (CFMs), which are pretrained transformer-based neural networks that can be applied directly to unseen causal inference tasks without further training or fine-tuning. CFMs are trained on a prior over data-generating processes and causal mechanisms, enabling them to perform amortized Bayesian inference via in-context learning at inference time. The authors provide a practical, hands-on introduction to CFMs, including example code and Jupyter notebooks, and benchmark the first openly available CFMs against traditional estimators. Their main contribution is to make CFMs accessible to a broader audience, demonstrating that these models offer both substantial gains in inference speed and competitive or superior performance, while also reviewing recent developments and applications in the field.
Method
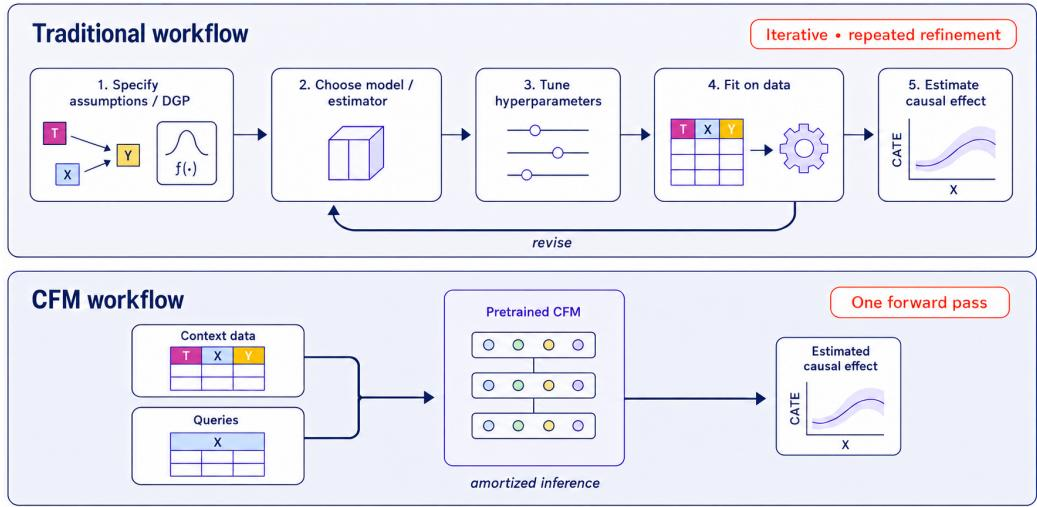
Causal Foundation Models (CFMs) leverage prior-data fitted networks to amortize Bayesian inference for causal quantities such as the Conditional Expected Potential Outcome (CEPO) or the Conditional Interventional Distribution (CID). Unlike traditional causal estimators that require iterative model selection, hyperparameter tuning, and training for each new dataset, CFMs compress this workflow into a single forward pass. As shown in the figure below, the CFM workflow keeps pretrained parameters fixed and uses the observational dataset as context for in-context learning, eliminating the need for weight updates during inference.
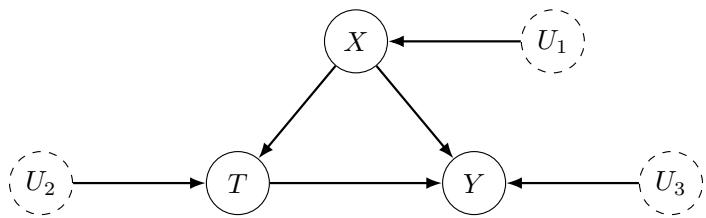
To train CFMs, the authors rely on Structural Causal Models (SCMs) to define data-generating processes. An SCM augments a Bayesian network with explicit structural equations relating each node. For instance, consider endogenous variables {X,T,Y} and exogenous variables {U1,U2,U3}. The corresponding directed acyclic graph representing these causal relationships is illustrated below.
By sampling exogenous variables and propagating them through the structural equations, SCMs can simulate both observational and interventional data efficiently. This capability is crucial for designing synthetic priors over DGPs, which are necessary because real-world observational data lacks the ground-truth interventional or counterfactual labels required for training.
CFMs utilize transformer-based architectures to enable in-context learning. The model receives a tabular observational dataset Dobs={(xn,tn,yn)}n=1N as context and a causal task as a query. Before being passed to the transformer, the input data is tokenized and embedded. The embedding of the context dataset includes observed covariates, treatments, and factual outcomes, while the query embedding contains no outcome information. The transformer applies masked attention such that each token attends to the context, but no token attends to the query. This ensures that query predictions depend only on the context data. The architecture also accounts for the distinguished role of the treatment variable, either by enforcing it as the first column or by passing treatments and covariates through separate encoders before concatenation.
CFMs are trained using a modified version of the prior-data loss, known as the causal prior-data loss. For the CEPO-PPD, the loss takes the form:
Lt(θ)=Eψ∼π,Dobs∪{x}∼Pobsψ[−log(qθ(μt(x;Pψ)∣x,t,Dobs))]This loss evaluates the model likelihood assigned to the ground-truth causal quantity computed from the sampled DGP ψ. Crucially, it does not require knowing the true underlying PPDs in closed form, making it tractable as long as interventional data can be simulated.
The training of CFMs involves sampling from a synthetic causal prior and generating both observational and interventional data. As shown in the figure below, a high-level training run begins by sampling an SCM from the prior, generating an observational dataset, simulating interventional targets, and performing supervised learning using the causal prior-data loss.
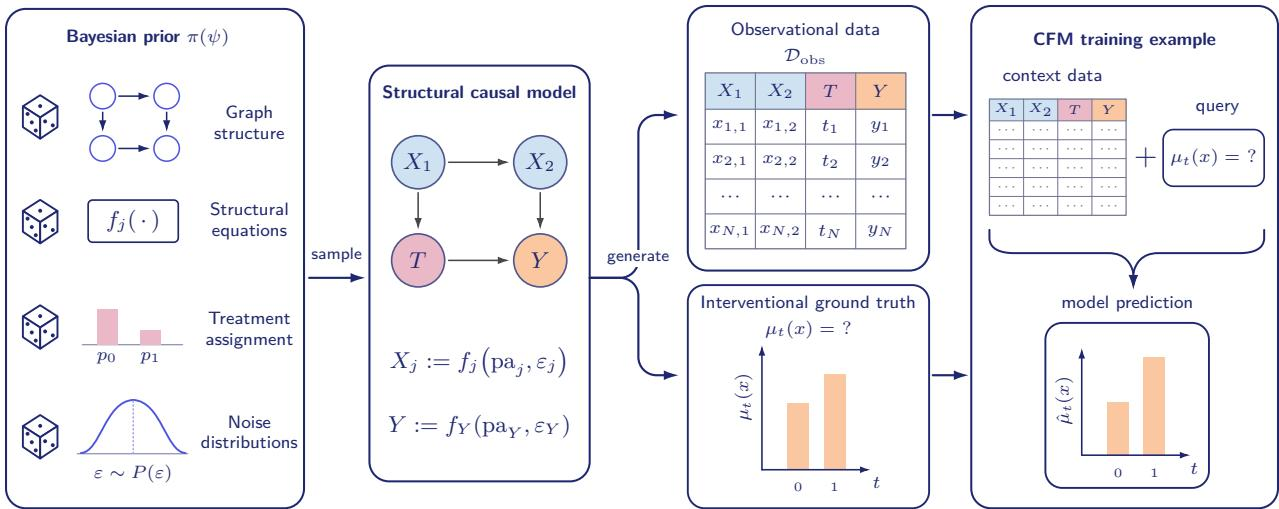
To generate the necessary interventional ground truth, the model simulates interventions on the SCM. For example, to generate data from the conditional interventional distribution Pψ(⋅∣do(T=t),X=x), the structural equation for T is replaced by a fixed treatment value T=t∗. The figure below illustrates this process, showing how the full set of original structural equations maps exogenous noise to observational data, while the intervention replaces the treatment equation to produce interventional targets with ground-truth potential outcomes.
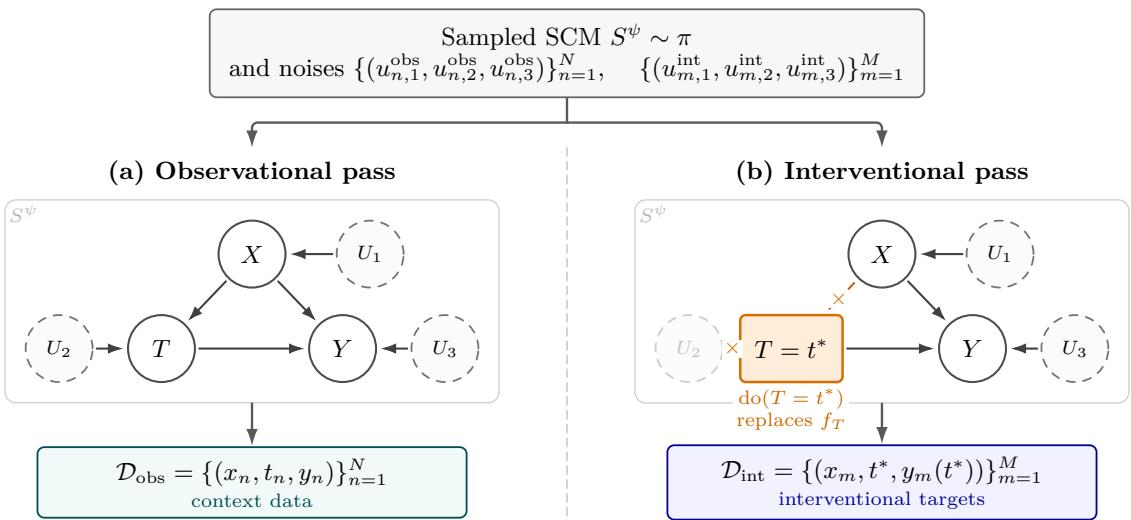
Through this process, the CFM learns to approximate the causal PPD, enabling it to predict causal quantities from purely observational data in a single forward pass at inference time.
Experiment
The evaluation uses the semi-synthetic RealCause-Lalonde benchmark (Lalonde-CPS and Lalonde-PSID cohorts) to compare three causal foundation models (CFMs), Do-PFN, CausalPFN, and CausalFM, against highly tuned classical estimators like meta-learners, IPW, and DML, with metrics covering CATE accuracy (PEHE), ATE relative error, runtime, and average rank. Despite not being trained on the benchmark data, CFMs are competitive with classical baselines, with CausalPFN achieving the lowest average rank among CFMs and closely matching a tuned T-Learner, while also being 1-2 orders of magnitude faster on CPU due to amortized inference. However, Do-PFN and CausalFM systematically shrink treatment effect estimates toward zero, recovering only a small fraction of the true ATE contrast, whereas CausalPFN closely recovers the population effect.
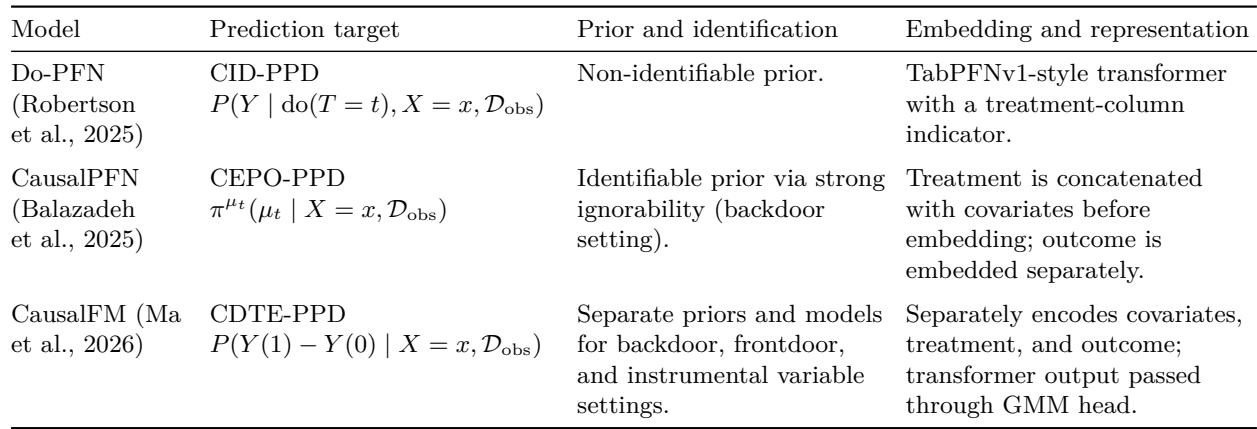
Early causal foundation models are all pretrained on synthetic data and use in-context learning, but differ in their prediction targets, prior identifiability, and architecture. Models that predict the conditional expected potential outcome with an identifiable backdoor prior tend to perform better in benchmark evaluations, while those predicting full interventional distributions or treatment effects with non-identifiable priors show systematic shrinkage toward zero. CausalPFN uses an identifiable backdoor prior and predicts the conditional expected potential outcome, achieving the best average rank among causal foundation models. Do-PFN and CausalFM, which predict interventional distributions or treatment effects with less identifiable priors, recover only a small fraction of the true treatment effect, with errors near one on both cohorts. All causal foundation models are significantly faster than traditional estimators, with CPU runtimes 1-2 orders of magnitude lower and further speedups on GPU.
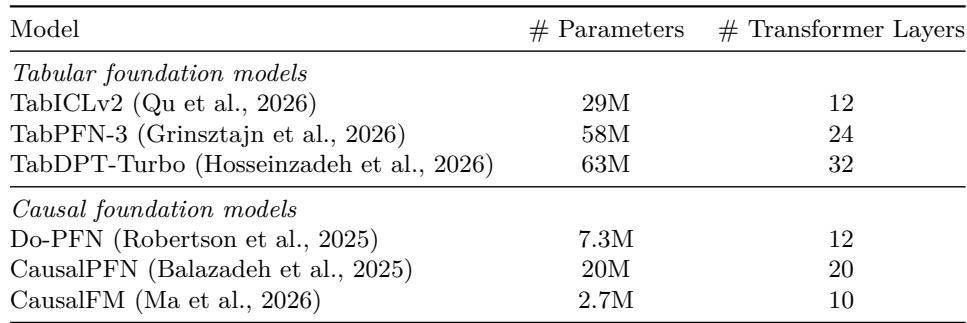
Causal foundation models (CFMs) are transformer-based and vary in size and depth, with CausalPFN being the most competitive among CFMs on benchmark tasks. CFMs offer significant runtime advantages over traditional estimators, though their ability to recover average treatment effect magnitudes varies by model. CausalPFN has 20M parameters and 20 transformer layers, while Do-PFN is smaller with 7.3M parameters and 12 layers. CausalPFN achieves the lowest average rank among CFMs, closely trailing a tuned T-Learner baseline. CFMs are 1-2 orders of magnitude faster on CPU than training and tuning traditional models, with CausalPFN being the fastest on CPU. CausalPFN recovers the population effect closely (ATE relative error 0.17 on Lalonde-CPS), whereas Do-PFN and CausalFM show systematic shrinkage toward zero.
Causal foundation models (CFMs) are competitive with classical estimators on the RealCause-Lalonde benchmark, with CausalPFN achieving the best average rank among CFMs and closely matching the tuned T-Learner. CFMs are 1-2 orders of magnitude faster in runtime than traditional estimators, but only CausalPFN recovers the true average treatment effect magnitude, while other CFMs systematically shrink estimates toward zero. CausalPFN achieves the lowest average rank among CFMs, closely trailing the tuned T-Learner while outperforming it on Lalonde-CPS. CFMs run 1-2 orders of magnitude faster than traditional estimators on CPU, with CausalPFN being the fastest. Do-PFN and CausalFM show near-unity ATE relative error on both cohorts, indicating systematic shrinkage of predicted effects toward zero. IPW, though not providing individual-level estimates, achieves the strongest ATE relative error among all methods. CFMs that output alternative posterior representations are less performant than CausalPFN but remain competitive with tuned X- and S-Learners.
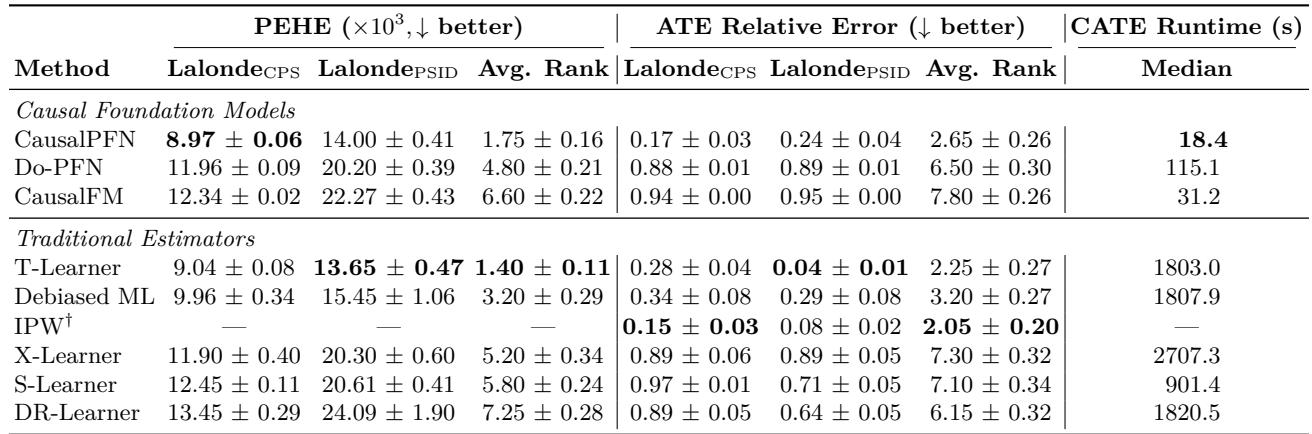
The evaluation compares causal foundation models (CFMs) against classical estimators on benchmark datasets, focusing on prediction targets, prior identifiability, and runtime. CausalPFN, which uses an identifiable backdoor prior and predicts conditional expected potential outcomes, achieves the best average rank among CFMs and closely matches a tuned T-Learner, while also recovering true treatment effect magnitudes. In contrast, models predicting full interventional distributions or treatment effects with less identifiable priors, such as Do-PFN and CausalFM, systematically shrink estimates toward zero, resulting in near-unity relative errors. All CFMs are 1-2 orders of magnitude faster than traditional estimators on CPU, with CausalPFN being the fastest, though only it reliably recovers the population effect.