Command Palette
Search for a command to run...
적게 읽고, 더 많이 해결하라: AI 에이전트를 위한 외부 콘텐츠의 토큰 효율적 희소 읽기
적게 읽고, 더 많이 해결하라: AI 에이전트를 위한 외부 콘텐츠의 토큰 효율적 희소 읽기
Zedong Liu Jiaan Wu Xinyang Ma Le Xu Kai Wang Yuanchao Hu Dingwen Tao Guangming Tan
초록
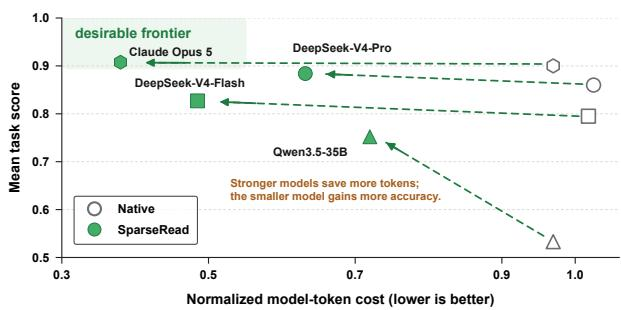
웹 기반 AI 에이전트는 웹페이지, 문서, 저장소, 도구 응답에 반복적으로 접근하지만, 읽기 인터페이스는 희소한 근거만 필요할 때에도 종종 객체 전체를 노출한다. 이러한 과도한 읽기는 토큰과 지연 비용을 증가시키고 관련 근거를 희석시킬 수 있다. 본 논문은 에이전트 모델을 수정하지 않고 콘텐츠 수용을 제어하는 재사용 가능한 읽기 제어 계층인 SparseRead를 제시한다. Read Intent Protocol은 변화하는 요구와 소스 커버리지를 추적하고, Adaptive Reader Backends는 근거를 찾아 노출하는 방식을 선택하며, Budgeted Read Gate는 에피소드당 누적 원시 노출을 제한하면서 충실한 전체 보기 폴백을 제공한다. 통합된 Reader 인터페이스는 이질적인 자원 전반에서 상호 교환 가능한 근거 획득을 지원한다. Claude Opus 5를 포함한 여섯 개 모델과 다섯 개 시나리오에서 SparseRead는 총 토큰을 최대 92.9%, wall time을 최대 89.0% 줄였으며, 97%의 설정에서 작업 품질을 유지하거나 향상시켰다. 웹 심층 검색 작업에서는 토큰을 31.0–43.0%, 작업 완료 시간을 23.0–37.0% 절감했다. 제거 실험은 세 가지 설계를 검증했으며, 세 가지 에이전트 프레임워크와의 통합은 이식성을 입증했다.
One-sentence Summary
Researchers from the University of Chinese Academy of Sciences, the Institute of Computing Technology, the Chinese Academy of Sciences, and the Songshan Lake Materials Laboratory propose SparseRead, a reusable reading control layer whose Read Intent Protocol, Adaptive Reader Backends, and Budgeted Read Gate govern content admission without modifying agents, reducing total tokens by up to 92.9% and wall time by up to 89.0% while preserving or improving task quality in 97% of settings.
Key Contributions
- SparseRead is a reusable reading control layer that governs content admission without modifying the agent model, combining a Read Intent Protocol for evolving needs and source coverage, Adaptive Reader Backends for evidence location and exposure, and a Budgeted Read Gate that bounds cumulative raw exposure per episode with faithful full-view fallback.
- A unified Reader interface supports interchangeable evidence acquisition across heterogeneous resources and lets retrieval or compression methods serve as replaceable backends.
- Evaluations across six models, including Claude Opus 5, and five scenarios show total token reductions up to 92.9% and wall-time reductions up to 89.0%, with task quality preserved or improved in 97% of settings; Web deep-search tasks show token reductions of 31.0-43.0% and time reductions of 23.0-37.0%. Ablations validate the three designs, and integration with three agent frameworks demonstrates portability.
Introduction
Large language model agents increasingly operate over webpages, code repositories, and API responses across long-horizon tasks, but external observations often account for a large share of tokens and can persist across model calls. The authors characterize the resulting mismatch as over-reading: agents receive object-level content even when a decision requires only a small evidence slice, and broad context can dilute relevant evidence without improving quality. Existing approaches such as KV-cache compression, observation masking, and retrieval reduce representation overhead or fetch content on demand, but they do not jointly control what an artifact read should expose, track source coverage across evolving intents, bound cumulative exposure, and permit a faithful full-view fallback. SparseRead introduces a reading control layer in which an agent expresses a Read Intent and receives a bounded EvidencePack with explicit coverage, supported by adaptive reader backends and a budgeted gate that chooses between sparse access and a full view.
Method
The authors observe that useful evidence is often sparse within source documents. For long-document QA, annotated supporting evidence covers a median of only 3.17% of source tokens. This sparsity motivates evidence acquisition guided by current information needs rather than fixed summaries.
Refer to the reading-budget breakdown below:
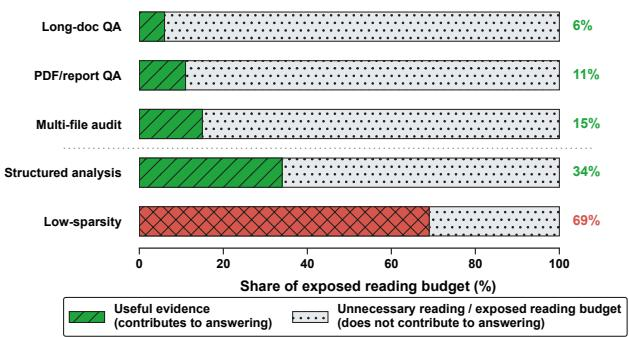
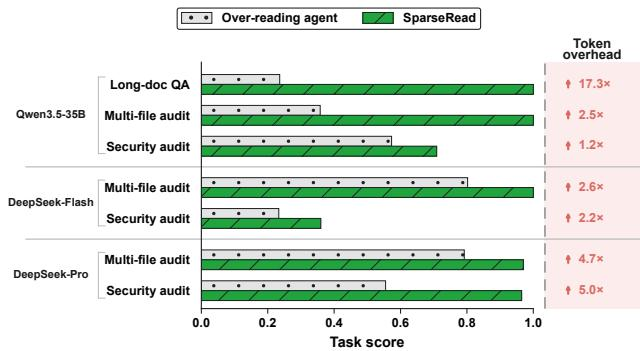
Furthermore, the cost of broad reading compounds across model calls. Content exposed at one step may remain in later calls, leading to significant replay-weighted exposure. If broad reading always improved quality, over-reading would be a cost-only problem, but selective reading often preserves or improves scores while reducing exposed context.
As shown in the figure below, full-read agents can spend up to 17.3 times more tokens than SparseRead while failing to improve task scores. This indicates that broad context is not a free substitute for reading control.
To address these issues, the authors identify that retrieval or compression alone is insufficient due to evolving evidence needs and uncertain regime boundaries. The optimal reading strategy depends on the artifact type and the specific task requirements.
Refer to the challenges of controlled reading below:
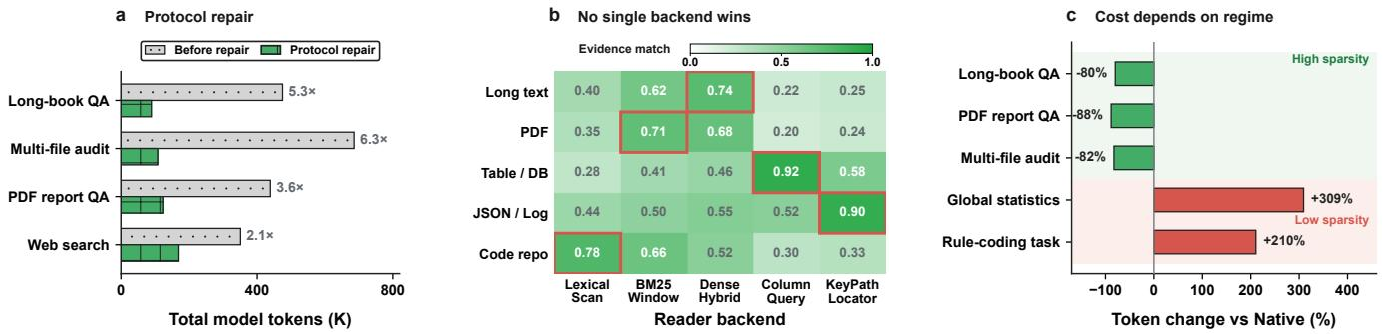
The figure above illustrates these challenges: protocol repair significantly reduces token usage, no single backend wins across artifact types (e.g., dense hybrid retrieval suits long text while key-path locators suit JSON), and the cost benefit depends heavily on the regime (sparse reading saves tokens on high-sparsity tasks but increases them on global statistics tasks).
Consequently, the authors propose SparseRead, which separates reading control from evidence acquisition. The architecture comprises a control plane and an evidence plane, connected by a common contract mapping Read Intent to an EvidencePack.
The architecture is illustrated in the framework diagram:
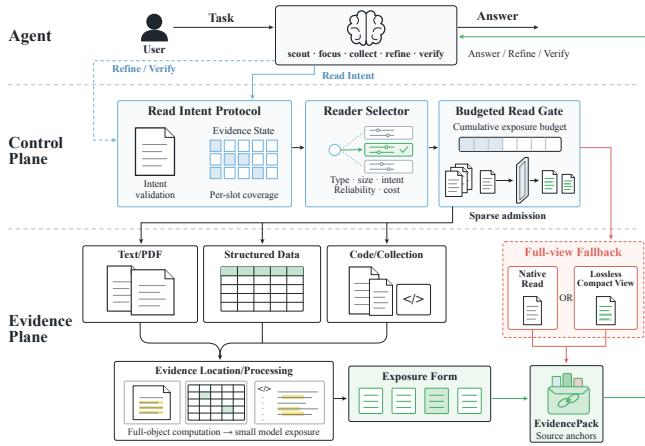
The control plane interprets the agent's reading intent, selects eligible Reader configurations, maintains the evidence record, and governs what enters the model context. The evidence plane contains Readers that declare their supported artifact types, actions, and execution costs. Readers acquire evidence but do not decide when they are invoked.
Read Intent Protocol The protocol treats reading as a sequence of evidence requests guided by the agent. At each access, the agent supplies a structured Read Intent describing what it needs for its next decision. This access intent takes precedence over a session intent derived from the user's opening request. The protocol maintains the validity and relevance of prior evidence using SHA-256 fingerprints to identify artifact versions. It tracks evidence coverage, identifying which slots have supporting evidence and which remain unresolved, without judging sufficiency. The agent interacts through five stable actions: scout, focus, collect, refine, and verify.
Adaptive Reader Backends A Reader is defined by the artifacts it handles. Within a Reader, evidence acquisition involves choosing how to locate or process evidence and what to expose to the agent. SparseRead adapts the choice of Reader configuration r∗ based on the artifact type, size range, and Read Intent h. The system selects the configuration that minimizes estimated cost C(r∣g) subject to a reliability threshold pvalid(r∣g)≥τ:
r∗=argr∈Ro,hminC(r∣g)s.t.pvalid(r∣g)≥τwhere Ro,h represents compatible configurations for artifact o and intent h. This allows the system to adapt to different artifact types, such as using column queries for tables or hybrid retrieval for text.
Budgeted Read Gate The Read Gate determines when selective access is worthwhile and when to fall back to a complete view. It enforces a budget where the cumulative sparse payload E does not exceed the length L of the least expensive faithful full view f(o). Before delivering a batch, the Gate compares its estimated size with the remaining budget. If the next batch cannot fit intact, it is withheld and the Gate delivers f(o) instead. This ensures that the total unweighted artifact exposure is bounded, preventing the downsides of uncontrolled selective reading while allowing savings when the agent can finish with minimal evidence.
Experiment
The evaluation tests SparseRead across six models, five scenarios including long-context comprehension, multi-file audit, structured analysis, web deep search, and scientific script generation, and against naive, retrieval, and context-reduction baselines. The main results show that SparseRead substantially lowers token use and wall time while preserving or improving task scores in nearly all settings, and it outperforms retrieval and compression baselines that often lose quality or increase cost. Cross-framework experiments with NanoBot, OpenCode, and OpenClaw confirm portability without retraining, with scores preserved or improved in most settings. Ablations attribute the gains to combined read intents, adaptive reader backends, and the budgeted read gate, which together reduce redundant reads, improve evidence coverage, and control resource exposure.
SparseRead reduced token use and wall time in every evaluated agent framework and model setting, while task scores were preserved or improved in most cases. Median savings varied across frameworks, with two showing larger reductions and one showing more moderate reductions. The method transferred across frameworks through thin adapters without requiring model retraining. Across all 18 settings, token use and wall time were lower, and scores were preserved or improved in 15 settings. Median token reductions were about 65% for two frameworks and about 31% for the third, with time savings following a similar pattern. For Opus 5, token savings ranged from roughly one-third to nearly three-fifths and time savings from under one-third to over half, with score gains across settings. Reusing the protocol, Readers, and Gate through thin adapters supported portability across agent frameworks without model retraining.
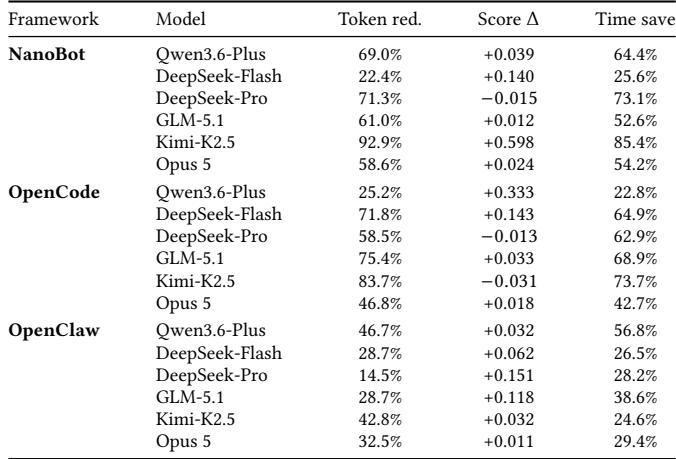
SparseRead was evaluated across multiple agent frameworks and model settings, where it consistently lowered token use and wall time while task scores remained stable or improved in most cases. Savings varied by framework, with two showing larger reductions and one showing more moderate reductions, and the approach transferred across frameworks through thin adapters without requiring model retraining. The results indicate that SparseRead provides portable efficiency gains across different agent environments.