Command Palette
Search for a command to run...
逆強化学習によるソーシャルメディアにおける行動的同質性の分析:Redditを事例として
逆強化学習によるソーシャルメディアにおける行動的同質性の分析:Redditを事例として
Lanqin Yuan Philipp J. Schneider Marian-Andrei Rizoiu
概要
オンラインコミュニティは、社会的言説の形成や現実世界の集合的行動に影響を与える上で重要な役割を果たしている。人々が類似した特徴や意見を持つ他者とつながる傾向、すなわち同質性は、両極化や分断をさらに増幅させるエコーチェンバーの形成において重要な役割を担っている。オンラインコミュニティにおける同質性を検証する既存研究は、明示的なインタラクションネットワークの構築やトピック分析など、コンテンツや隣接性に基づく手法によって同質性を推定してきた。しかし、これらの手法はインタラクションネットワークを容易に構築できないプラットフォームには適用が困難であり、プラットフォーム全体にわたるユーザーインタラクションの複雑な性質を捉えることができていない。本研究は、ユーザー同質性を定量化する新しい手法を提案する。まず、逆強化学習(IRL)の枠組みを用いてユーザーの行動方針を推定し、次にこれらの行動方針を行動的同質性の尺度として利用する。提案手法をRedditに適用し、6年間にわたる590万件のインタラクションを対象としたケーススタディを実施することで、異なるコミュニティ間で変動する明確な行動パターンやユーザーの役割をこの手法が明らかにできることを示す。さらに、行動的同質性尺度を従来のコンテンツに基づく同質性指標と比較検証し、ソーシャルメディアの動力学やそのより広範な社会的含意を分析する有力な手法を提供する。主な発見として、サッカーとeスポーツのように全く異なるトピックを議論していてもユーザーの行動は非常に類似している(行動的同質性が高く、話題的同質性は低い)場合があること、そしてRedditには他者に反対することを目的としていると見られるユーザー群が確かに存在することが挙げられる。
One-sentence Summary
Researchers at the University of Technology Sydney and EPFL propose using Inverse Reinforcement Learning to infer user policies as a measure of behavioral homophily, applied to 5.9 million Reddit interactions over six years, revealing that users can exhibit high behavioral homophily across unrelated topics and identifying a class of users whose primary behavior is disagreement.
Key Contributions
- A method based on inverse reinforcement learning infers user policies from hierarchical Reddit discussions and uses them as a measure of behavioral homophily, capturing behavior when explicit interaction networks are unavailable.
- The method is applied to a six-year case study of 5.9 million Reddit interactions across diverse subreddits, revealing distinct behavioral patterns and user roles, including high behavioral similarity across unrelated topics and participation centered on disagreement.
- The behavioral homophily measure is compared with traditional topic-based homophily, showing alignment while identifying behavioral similarities across distinct topics and consensus mechanisms that shape engagement.
Introduction
Social media platforms shape public discourse, information flow, and even financial markets, yet their online communities often involve granular individual behaviors that macro-level network analysis misses. On platforms such as Reddit, users interact in hierarchical, anonymous subreddits without explicit follower ties, making traditional homophily measures based on social connections, hashtags, or topical similarity less informative. The authors leverage inverse reinforcement learning to infer hidden reward policies from user actions such as posting, replying, and reaching agreement within nested discussions. They use the learned policies to define a behavioral homophily measure and study Reddit communities, offering a way to examine engagement patterns, polarization, and community dynamics when conventional social tie data is unavailable.
Dataset

-
The authors use Reddit as the primary source, collecting data with the Pushshift Reddit API. The raw corpus consists of 1.3 TB of compressed text covering all of Reddit from January 1, 2015 to January 1, 2022.
-
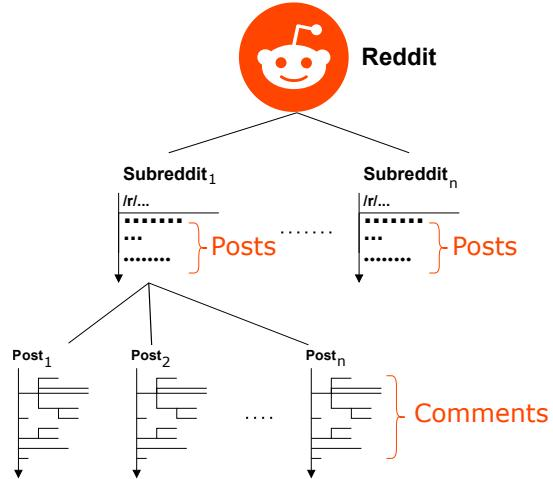
They begin from Reddit’s hierarchical structure, which contains subreddits, posts, root comments, and nested replies. This structure is used to define both direct user activity and indirect interaction structure.
-
The authors construct a seed set of subreddits that spans general interest communities and controversial or niche communities. They do not use publicly unavailable subreddit subscriptions. Instead, they define a user’s home subreddit as the subreddit where the user is most active based on comments across Reddit.
-
For user sampling, the authors rank users by activity in each seed subreddit for each year, where activity means posts or comments. They add the top 50 most active users per subreddit per year and randomly sample 50 users from each quartile of the yearly ranking, producing 250 users per subreddit per year.
-
To reduce the cost of identifying home subreddits, they randomly sample one third of the initial user set, creating an intermediate subset of 6,000 users. From this subset, they identify 1,331 unique home subreddits. They select the 15 home subreddits with the most home users and sample 45 users from each, matching the size of the smallest selected subreddit.
-
The final user dataset contains 662 users after removing banned users and users with deleted accounts.
-
For each selected user, the authors extract direct activity, including created threads, root comments, and replies. They also extract indirect activity, restricted to first descendant replies or responses directly connected to the user’s action in Reddit’s nested comment graph.
-
Content from deleted accounts or suspended posts is marked unavailable. During preprocessing, users affected by such missing data are omitted to avoid noise in downstream analysis.
-
The authors add stance labels to comment reply interactions using three categories: agree, neutral, and disagree. For this labeling step, they use the DEBAGREEMENT dataset, which contains labeled parent comment and reply pairs from five subreddits: r/BlackLivesMatter, r/Brexit, r/climate, r/democrats, and r/Republican. The parent and reply text are concatenated for classification.
-
They also build a topic based dataset component using BERTopic. From the sampled posts, they derive 484 distinct topics and represent each user with a vector of topic usage frequencies over the observation period.
-
The resulting dataset combines Reddit activity logs, selected user identifiers, home subreddit assignments, direct and indirect interaction records, stance labels, and topic frequency vectors. The authors use it to measure behavioral homophily and to construct a topic based homophily baseline.
Method
The authors construct a behavioral homophily inference framework that combines community selection, activity labeling, inverse reinforcement learning, and similarity scoring. The system begins with identifying meaningful subreddit communities, continues with selecting diverse users and collecting their conversational activity, then labels each interaction with stance and topic features, learns individualized user policies through inverse reinforcement learning, and finally measures behavioral and topical similarity. As shown in the framework diagram below:
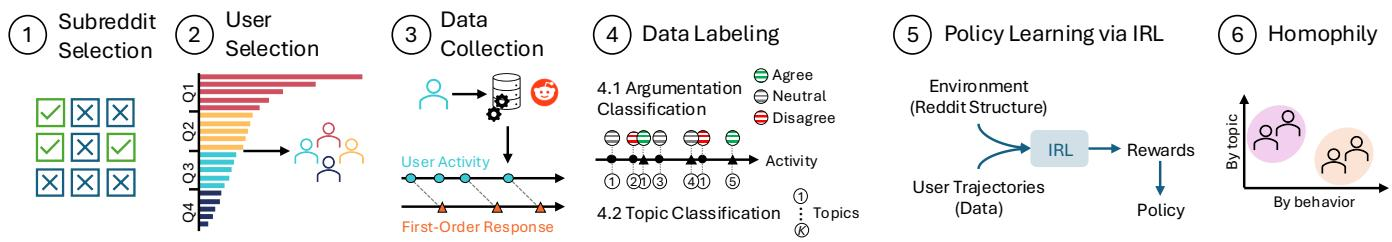
The pipeline first handles community construction by defining each user’s home subreddit as the subreddit in which the user is most active across all of Reddit. Because Reddit subscriptions are not publicly observable, this activity-based definition provides a practical proxy for genuine community membership. The method then selects users by ranking activity within seed subreddits and sampling across activity quartiles, ensuring that the analysis is not restricted only to highly active accounts.
For data collection, the method models Reddit activity as a hierarchical conversational environment. Direct activity includes user-initiated actions such as creating threads, posting root comments, and posting replies. Indirect activity captures the first-order responses triggered by those actions. This hierarchical structure is treated as a directed acyclic graph, where each action may have descendants, and only the immediate child response is used for modeling interaction dynamics. The Reddit hierarchy diagram below illustrates this structure:
The labeling stage introduces two feature streams used later in similarity analysis. The first is argumentation classification, where each comment is assigned to one of three stance categories: agree, neutral, or disagree. This is implemented by fine-tuning a transformer-based language model on labeled parent-reply comment pairs. The second is topic classification, where a topic modeling approach assigns each activity item to one of a finite set of latent discussion topics. Each user is then represented by a topic frequency vector, which later supports topic-based homophily measurement.
The core inference module uses maximum entropy deep inverse reinforcement learning to recover latent user rewards from observed behavior. Instead of assuming a known reward function and learning optimal actions, the method observes user trajectories and infers the reward structure that best explains those trajectories. Each user is treated as an independent agent operating within the Reddit environment. The agent’s trajectory consists of events involving the user across the platform, mapped into state-action feature pairs. The environment state includes categories such as creating an initial thread, posting an initial root comment, replying with agreement, neutrality, or disagreement, receiving replies, and engaging with already active discussions. The agent chooses among actions such as waiting for a reply, creating a new thread, posting a root comment, or posting a reply with a given stance.
The state space contains 12 states, while the action space contains 6 actions. The reward function is parameterized by a neural network:
R(s)=w⊤φl(s),with layerwise transformations
φ1(s)=σ(W1s),and for j∈{2,…,l},
φj(s)=σ(Wjφj−1(s)).Here, w is a weight vector, σ is a nonlinear activation function, and the network parameters are
θ={W1,…,Wl}.The reward model is trained by maximizing the likelihood of observed trajectories under a maximum entropy framework. This encourages a reward interpretation that explains the user’s behavior without committing to unnecessarily deterministic assumptions about unobserved preferences. Policy learning proceeds through soft value iteration, producing a user-specific policy πu that represents the action distribution in each state. For each user, the resulting policy can be viewed as a 12×6 matrix, where each row gives the probability distribution over the six possible actions conditioned on a given state.
Homophily is then inferred by comparing these learned policies. Two users are considered behaviorally similar when their policy distributions are similar across states that each user frequently visits. To formalize this, the method introduces a state visitation weight for user u and state s:
wus=∣τu∣∑k=1∣τu∣1{sk=s},where τu={(s1,a1),…,(s∣τu∣,a∣τu∣)} is the observed trajectory and 1{sk=s} is an indicator function. The proposed divergence between two users’ policies is the symmetric weighted Kullback-Leibler divergence:
SWKL(πu,πu′)=21s∈S∑(wusDKL(πus∥πu′s)+wu′sDKL(πu′s∥πus)).This measure emphasizes states that are behaviorally representative for each user and reduces the influence of rare or noisy state visits. For topic-based comparison, the method constructs a user-topic vector vu from topic frequencies and computes cosine distance between users:
cos(vu,vu′)=1−∥vu∥∥vu′∥vu⊤vu′.Together, the inverse reinforcement learning module learns individualized action-selection patterns from observed Reddit trajectories, while the homophily inference module converts those learned policies into a quantitative measure of behavioral similarity and combines it with topical alignment for community-level analysis.
Experiment
The experiments use Reddit home subreddits to evaluate homophily along both topical and behavioral dimensions. They find that topical alignment is generally strong within subreddits, while behavioral alignment is weaker and can diverge from shared interests, as shown by distinct behavioral personas and community-specific engagement patterns. Further analysis shows that topics and behaviors are mostly correlated, though temporal dynamics vary by user role and highlight the value of combining topical and behavioral signals.
The case study examines Reddit communities spanning open question asking, identity support, politics, gaming, and humor. It samples users across different activity levels and compares topic alignment with behavioral convergence across communities. The surrounding analysis suggests that similar user behavior can cross topic boundaries, while topic interests and engagement patterns show different stability over time. The examined subreddits cover political, social identity, question answering, gaming, and humor topics. The sampling design includes users from different activity quartiles rather than only the most active accounts. Users whose behavior is closer to their home subreddit also appear closer to users from another community despite different topics. Overall homophily variability appears stable over time, but different user roles show distinct topic and behavior patterns.
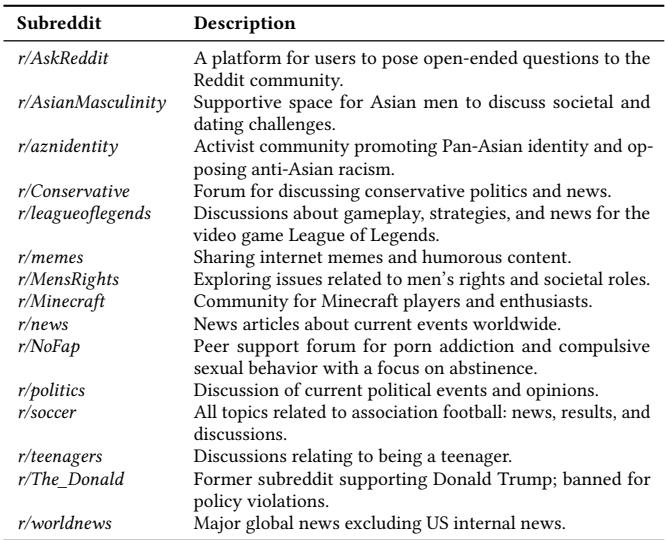
The study evaluates Reddit communities covering open question asking, identity support, politics, gaming, and humor, sampling users across activity levels to compare topic alignment and behavioral convergence. It finds that similar user behavior can appear across topic boundaries, while topic interests and engagement patterns show different stability over time. Overall homophily variability remains stable, but user roles exhibit distinct topic and behavior patterns.