Command Palette
Search for a command to run...
LINE:大規模情報ネットワーク埋め込み
LINE:大規模情報ネットワーク埋め込み
Jian Tang Meng Qu Mingzhe Wang Ming Zhang Jun Yan Qiaozhu Mei
概要
本論文では、可視化、ノード分類、リンク予測など多くのタスクに有用である、非常に大規模な情報ネットワークを低次元ベクトル空間へ埋め込む問題を扱う。既存のグラフ埋め込み手法の多くは、数百万のノードを含む現実の情報ネットワークに対してはスケーラビリティが不十分である。本論文では、非有向、有向、重み付きのいずれにも適用可能な新たなネットワーク埋め込み手法「LINE」を提案する。本手法は、ネットワークの局所構造と大域構造の双方を保持するように精心して設計された目的関数を最適化する。また、古典的な確率的勾配降下法の限界に対処し、推論の有効性と効率性を双方とも向上させるエッジサンプリングアルゴリズムを提案する。言語ネットワーク、ソーシャルネットワーク、引用ネットワークを含む多様な実世界の情報ネットワークに対する経験的実験により、LINEの有効性が実証されている。本アルゴリズムは非常に効率的であり、数百万の頂点と数十億のエッジを持つネットワークの埋め込みを、一般的な単一マシン上で数時間以内に学習することが可能である。LINEのソースコードはオンラインで公開されている。
One-sentence Summary
Researchers from Microsoft Research Asia, Peking University, and University of Michigan propose LINE, a scalable network embedding method for arbitrary network types that preserves both local and global structures via a carefully designed objective function and an edge-sampling algorithm, enabling the embedding of networks with millions of vertices and billions of edges within a few hours on a single machine.
Key Contributions
-
The paper introduces LINE, a scalable network embedding method for undirected, directed, and weighted information networks.
-
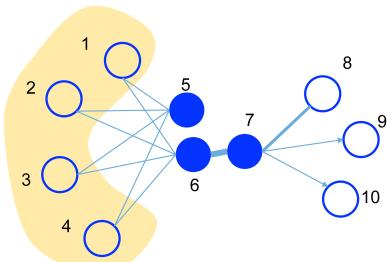
The paper defines first-order and second-order proximity and designs objective functions that preserve both local pairwise relationships and broader neighborhood structure, making the embeddings more robust to sparse links.
-
The paper proposes an edge-sampling inference method that improves weighted-edge handling beyond classical stochastic gradient descent, and experiments on language, social, and citation networks show that LINE can learn embeddings of networks with millions of vertices and billions of edges in a few hours on a typical single machine.
Introduction
The authors explain that information networks are central to many data mining tasks, and embedding their vertices into low-dimensional vectors enables visualization, node classification, link prediction, and recommendation. Prior graph embedding methods either scale poorly to networks with millions of nodes or use objectives that are not designed to preserve the broader network structure, especially when observed edges are sparse. The authors propose LINE, a scalable network embedding model for directed, undirected, weighted, and unweighted graphs, which preserves both first-order and second-order proximity and uses edge sampling with stochastic gradient descent to train efficiently on large weighted networks.
Dataset
-
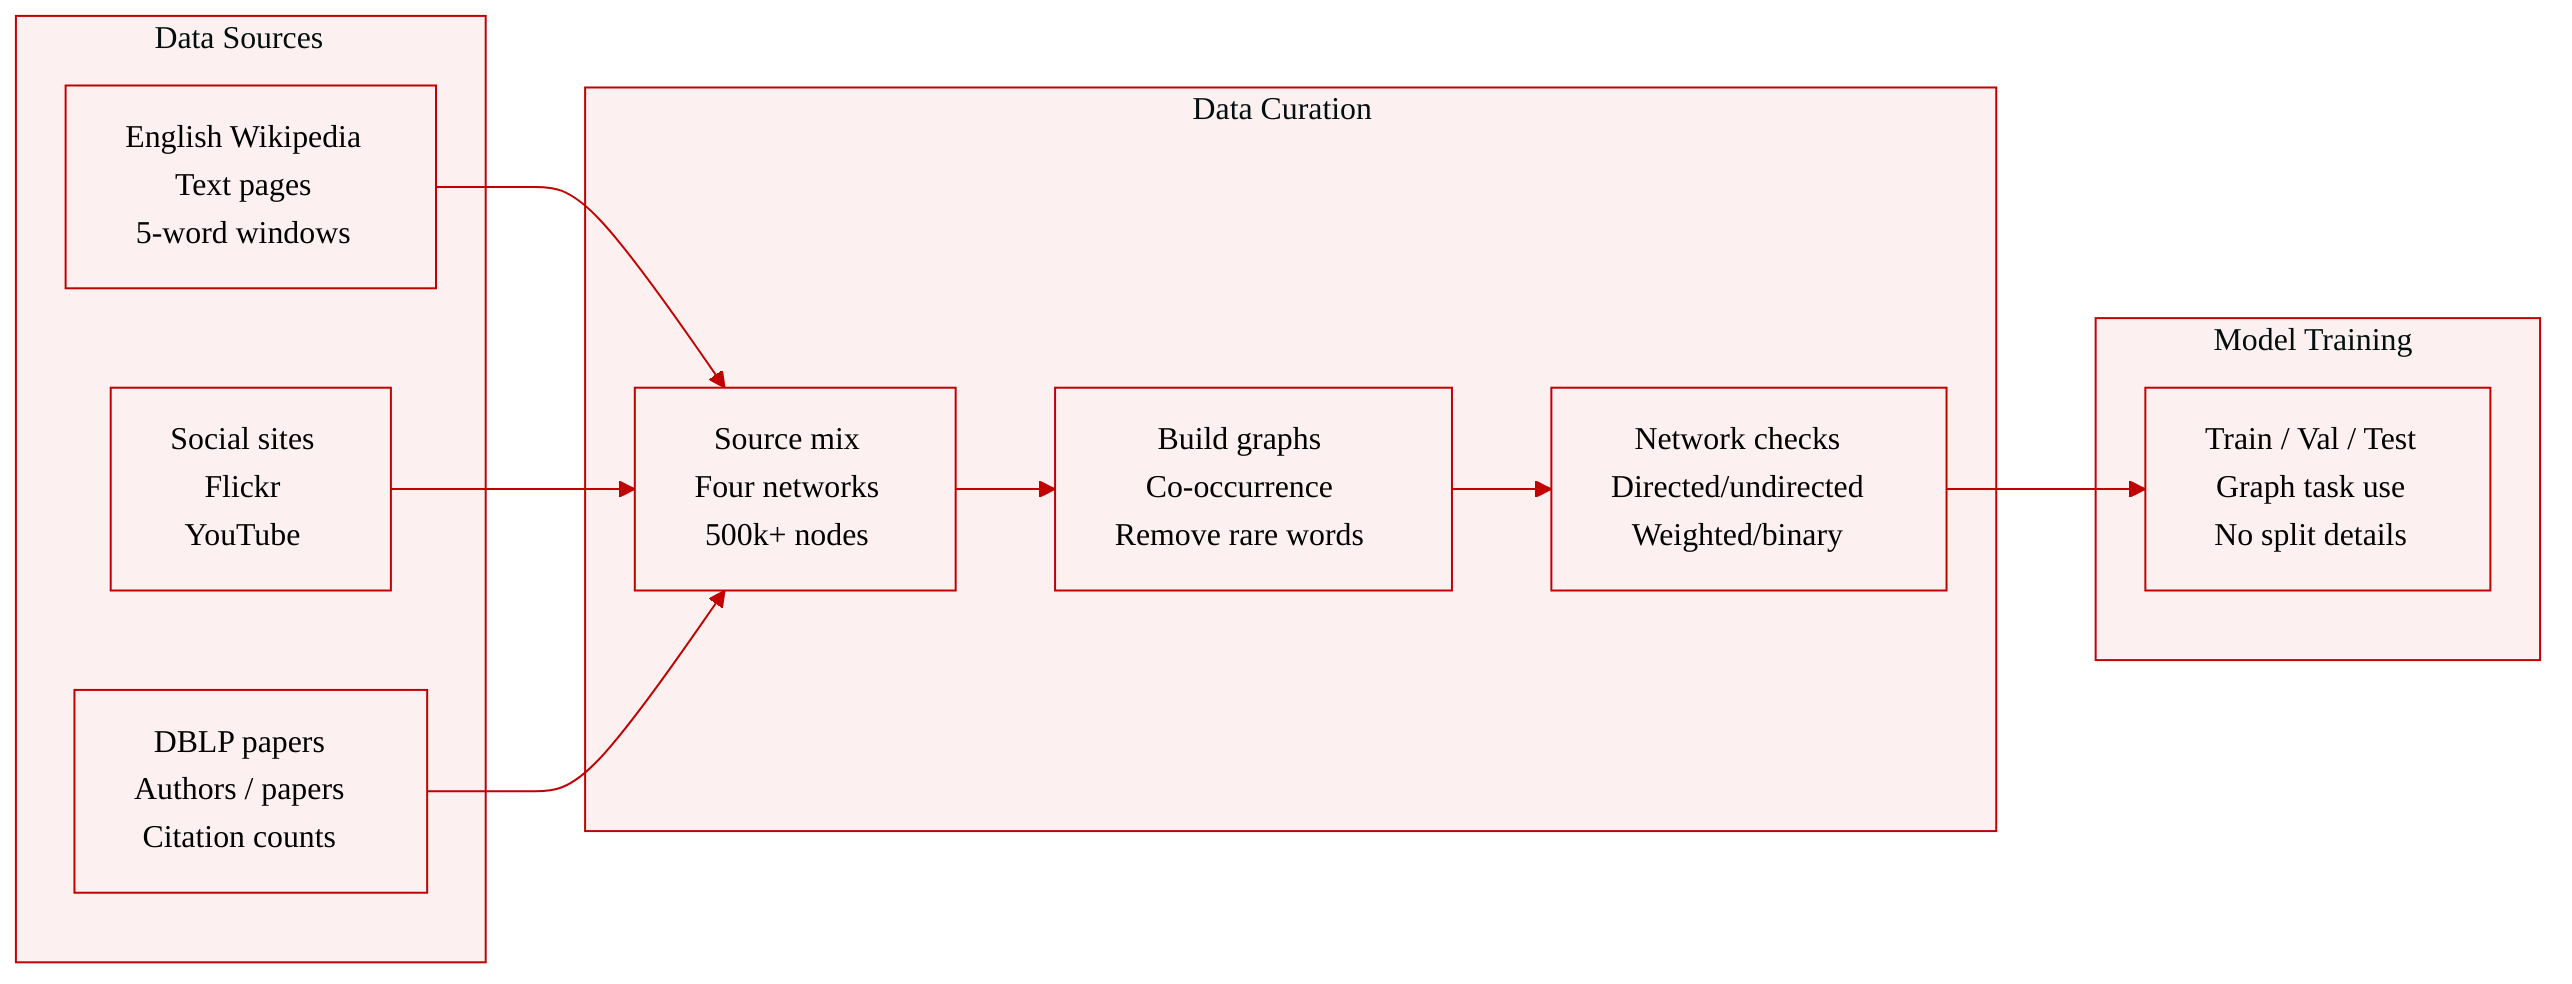
The authors use four network datasets covering language, social, and citation domains for their experiments.
-
Language network: constructed from the entire set of English Wikipedia pages. They create a word co-occurrence network by treating words within every 5-word sliding window as co-occurring pairs. Words with frequency below 5 are removed.
-
Social networks: they use Flickr and YouTube. The Flickr network is denser than the YouTube network, and the YouTube network is the same one used in DeepWalk.
-
Citation networks: they build two networks from DBLP, one between authors and one between papers. The author citation network counts how many papers an author has written and cited by another author, producing weighted edges between authors.
-
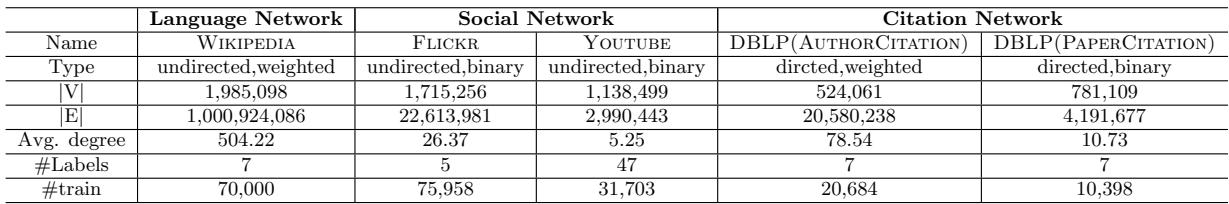
Overall dataset scale and properties: the networks vary between directed and undirected, binary and weighted, and each contains at least half a million nodes and millions of edges. The largest network has around two million nodes and about one billion edges.
-
Dataset usage: the authors use these networks as input graph data for experiments on information networks, with the dataset statistics summarized in Table 1. The provided text does not report explicit training splits or mixture ratios.
Method
The authors leverage LINE as a network embedding framework designed to learn low-dimensional vertex representations for large information networks while preserving two complementary notions of proximity. The model is organized around two learning modules. The first module captures first-order proximity, which reflects the direct local relationship between connected vertices. The second module captures second-order proximity, which reflects the similarity of vertices based on their surrounding network neighborhoods. A simple combination strategy then fuses the two learned representations to form the final vertex embedding.
For first-order proximity, the authors model each undirected edge as a direct local relationship between its endpoints. Given a vertex vi with embedding ui and a vertex vj with embedding uj, they define a joint probability
p1(vi,vj)=1+exp(−uiT⋅uj)1.This probability increases when the two embeddings are compatible under a logistic scoring function. The empirical edge distribution is derived from the observed edge weights. If wij is the weight of edge (i,j) and W is the total edge weight in the graph, the empirical probability is proportional to wij/W. To make the learned model match this empirical structure, the authors minimize the KL divergence between the empirical joint distribution and the model joint distribution. After removing constant terms, the optimization objective becomes
−(i,j)∈E∑wijlogp1(vi,vj).This first-order module is effective for graphs in which direct connections carry the primary semantic or structural meaning, but it is naturally suited to undirected graphs because the joint probability is symmetric.
For second-order proximity, the authors use a context-based modeling strategy that applies to both directed and undirected networks. In this module, each vertex plays two roles. It can appear as a target vertex, and it can also appear as a context for other vertices. To distinguish these two roles, each vertex vi is associated with two embeddings: ui represents the vertex itself, while ui′ represents the vertex as a context for its neighbors. The authors argue that vertices with similar connection patterns should have similar distributions over contexts. Therefore, second-order proximity is modeled through a conditional probability distribution over contexts.
For a directed edge (i,j), the probability that vertex vj appears as a context of vertex vi is defined by a softmax over the entire vertex set:
p2(vj∣vi)=∑k=1∣V∣exp(uk′T⋅ui)exp(uj′T⋅ui).This formulation makes p2(⋅∣vi) a distribution over all possible contexts generated by vi. The empirical conditional distribution is also based on observed edge weights. If di is the out-degree of vertex vi, the empirical probability that vj is observed as a context of vi is proportional to wij/di. The training objective minimizes the KL divergence between the empirical context distribution and the model context distribution for every vertex. The authors further introduce a prestige weight to account for the fact that vertices may differ in importance. In their practical setting, the prestige weight is set to the degree of the vertex, which simplifies the objective to
−(i,j)∈E∑wijlogp2(vj∣vi).This second-order module captures global neighborhood structure by comparing the context distributions of vertices.
To preserve both first-order and second-order proximity, the authors use a simple but effective training scheme. They train the first-order proximity model and the second-order proximity model separately, then concatenate the two learned embeddings for each vertex. This yields a unified representation that contains information from direct local edges and from broader neighborhood patterns. The authors also note that a more principled joint training objective is possible, but the separate learning followed by concatenation is practical and efficient for large-scale networks.
A key part of the method is scalable optimization. Directly optimizing the second-order softmax objective is expensive because every prediction requires a normalization term over the full vertex set. The authors address this issue with negative sampling. For each observed edge (i,j), the model maximizes the likelihood of the positive context while minimizing the likelihood of several sampled negative contexts. The optimization objective for an edge becomes
logσ(uj′T⋅ui)+n=1∑KEvn∼Pn(v)[logσ(−un′T⋅ui)],where σ(x)=1/(1+exp(−x)) is the sigmoid function and K is the number of negative samples. The negative distribution is proportional to the out-degree of a vertex raised to the power 3/4, which biases sampling toward more connected vertices. For the first-order objective, a similar negative sampling approach is used, but the context vectors are replaced by the vertex vectors themselves. This also helps avoid a trivial solution in which embedding magnitudes grow indefinitely.
The training process uses asynchronous stochastic gradient descent. In each step, a mini-batch of edges is sampled, and the gradients of the embedding vectors are updated accordingly. This asynchronous design supports high-throughput optimization on large graphs. However, the authors observe that edge weights can vary widely in real networks. When the gradient contains the original edge weight, edges with large weights can produce extremely large updates, while edges with small weights produce very small updates. This makes it difficult to select a stable learning rate.
To resolve this issue, the authors introduce an edge sampling mechanism. Instead of multiplying the gradient by the raw edge weight, they sample edges according to their weights and treat the sampled edges as binary edges. In effect, a weighted edge is statistically unfolded into multiple binary edges without explicitly materializing all of them. The sampling probabilities are proportional to the original edge weights. Directly sampling from a cumulative weight distribution would require linear time per sample, so the authors use an alias table for efficient sampling. Sampling an edge from an alias table takes constant time. As a result, each optimization step costs time proportional to the embedding dimension and the number of negative samples, and the overall training complexity is linear in the number of edges rather than in the number of vertices.
The framework also includes practical mechanisms for two common deployment scenarios. For low-degree vertices, the second-order module may be unreliable because these vertices have few observed connections. The authors mitigate this by augmenting each low-degree vertex with higher-order neighbors, specifically neighbors of neighbors. The added second-order connection weight is computed by propagating first-order weights through intermediate neighbors. This gives the embedding module more contextual evidence for vertices that would otherwise be poorly represented. For newly arrived vertices, the authors keep the embeddings of existing vertices fixed and update only the embedding of the new vertex. If the new vertex has observed connections to the existing network, its embedding is optimized using a local objective based on the first-order or second-order proximity terms. If no such connections exist, the representation cannot be inferred from graph structure alone and requires auxiliary information.
Experiment
The experiments evaluated the LINE embedding method on large language, social, and citation networks, comparing it with graph factorization and DeepWalk through word analogy, document classification, vertex classification, network visualization, sparsity analysis, parameter sensitivity, and scalability tests. The edge sampling treatment was shown to be effective and efficient, with second order proximity best for semantics and dense graphs, first order proximity more important in sparse social networks, and their combination complementary across many tasks. The results also showed that direct stochastic gradient descent struggled with heterogeneous edge weights, neighborhood reconstruction could mitigate sparsity for second order embeddings, and asynchronous optimization gave nearly linear speedup while preserving performance.
The dataset statistics cover language, social, and citation networks, showing that Wikipedia is a very large and dense weighted word network, while YouTube is much sparser than Flickr among the social networks. Citation networks differ in direction and density, with author citation graphs being more dense than paper citation graphs. Experiments on social networks indicate that second-order proximity becomes more effective as network density and node degree increase. Wikipedia has the largest network and the highest average degree, reflecting dense word co-occurrence structure. Flickr is denser than YouTube, providing a useful setting for comparing sparse and moderately dense social networks. The author citation network is more connected than the paper citation network despite using the same DBLP source. Second-order proximity methods improve on denser or reconstructed networks, while they can underperform on very sparse or low-degree regions.
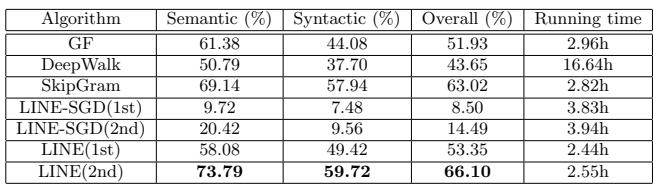
On the Wikipedia word analogy task, embeddings learned with second-order proximity achieve the highest accuracy across semantic, syntactic, and overall settings. The result is stronger than Skip-Gram embeddings trained from the original corpus and stronger than other graph embedding baselines. The runtime of the best model remains close to that of other fast methods, while DeepWalk is both slower and less accurate. Second-order proximity improves semantic and syntactic analogy accuracy. The second-order model surpasses Skip-Gram and other graph embedding methods. DeepWalk trails weighted co-occurrence embeddings despite exploring network structure.
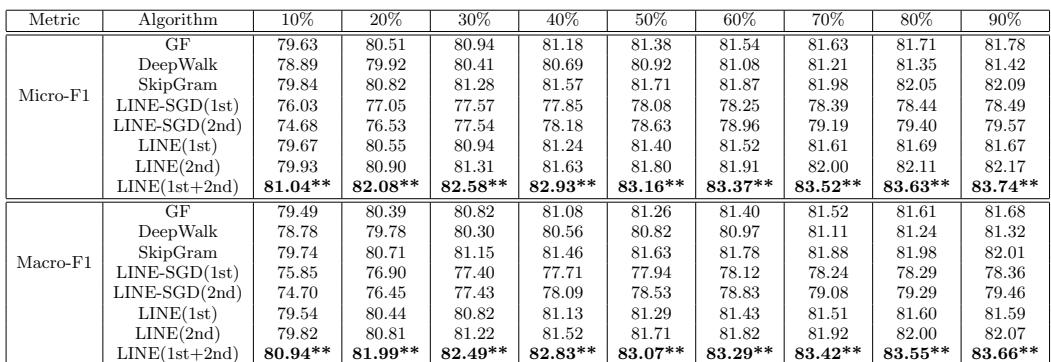
On Wikipedia page classification, micro-F1 generally improves as more network links are retained. LINE(2nd) gives the strongest overall performance, while graph factorization, LINE(1st), and SkipGram remain competitive. LINE(2nd) is consistently stronger than first-order and random-walk based methods across the evaluated link densities. Performance tends to rise as the network becomes less sparse, indicating that richer neighborhood information helps the embeddings.
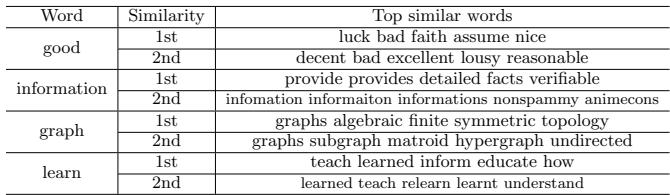
The comparison shows that second-order proximity tends to return words that are more lexically close or topically related, such as spelling variants of information and graph-related terms. First-order proximity also produces related words, but some are broader or weaker matches, such as luck and faith as neighbors of good. These examples suggest that second-order proximity captures contextual replacement patterns more directly than first-order proximity. Second-order similar words often include close forms or topical neighbors, such as infomation and informaton for information. First-order similar words can be less tightly related, as seen with luck and faith among the top neighbors of good.
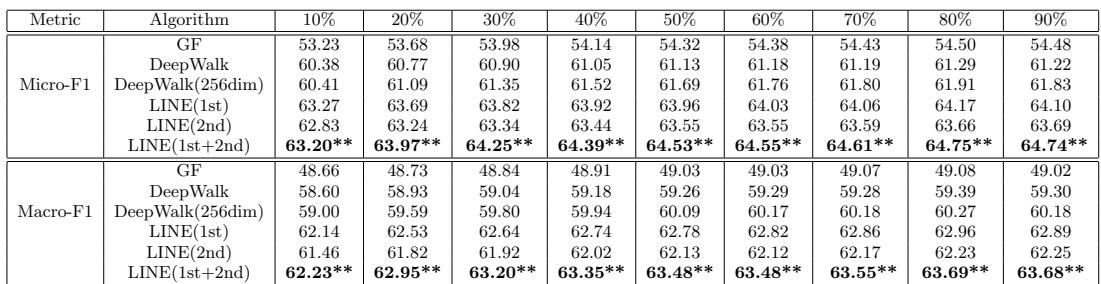
On the Flickr social network, the combined LINE model achieves the strongest multi-label classification performance and shows significant gains over DeepWalk across different training fractions. The first-order proximity performs slightly better than the second-order proximity, consistent with stronger first-order ties and limited benefit from neighborhoods in a sparse social network. LINE with both first-order and second-order proximity outperforms all compared methods. First-order proximity is more effective than second-order proximity on this social network. Graph factorization trails DeepWalk and the LINE variants. Combining proximity types improves robustness for sparse social-network embeddings.
The evaluation examines large language, social, and citation networks to test whether first-order and second-order proximity embeddings capture node relationships under different densities. Experiments validate that second-order proximity is especially useful in dense or structurally richer networks, yielding stronger performance on Wikipedia word analogy, page classification, and qualitative word neighborhood analyses. On the sparser Flickr social network, first-order proximity is more effective, while combining first- and second-order proximity gives the best overall multi-label classification, supporting the conclusion that embedding performance depends on network density and the choice of proximity structure.