Command Palette
Search for a command to run...
分析データベースにおけるスカラー関数の拡張可能なGPU高速化:コンパイル、ベンチマーキング、最適化
分析データベースにおけるスカラー関数の拡張可能なGPU高速化:コンパイル、ベンチマーキング、最適化
Kaushik Rajan Sampath Rajendra Momin Al-Ghosien Nicolas Bruno Carlo Curino Matteo Interlandi Yinan Li Lukas M. Maas Craig Peeper Surajit Chaudhuri Johannes Gehrke
概要
GPUによるSQLクエリ実行の高速化は、データベース研究における中心的な課題である。既存のシステムでは関係演算子のGPUへのオフロードにより顕著な高速化が達成されてきたが、分析エンジンがサポートする多様なスカラー関数の高速化は未解決である。本分析の結果、多くのスカラー関数が substantial な計算オーバーヘッドを伴い、CPU上の分析クエリにおける主要なボトルネックとなる場合が多いことが明らかになった。この観察は、GPU上でのスカラー関数高速化における機会と課題を体系的に探索する動機となる。関係演算子のように数少なく標準化されたものとは異なり、プロダクションデータベースは数百のスカラー関数をサポートしている。標準化された仕様が存在しないことに加え、この多様性により手動でのGPU移植は不可能である。この課題に対し、本論文では、プロダクションデータベースのCPUベースのスカラー関数実装を効率的なGPUカーネルへ変換し、かつ元のセマンティクスを保持する、LLVM-MLIRに基づくコンパイラツールチェーンを提案する。本アプローチでは、スカラー関数 high レベルの中間表現へリフトし、リソース最適化変換を適用した上でGPUアセンブリコードを生成し、すべての関連するデータ型、パラメータ、およびデータベースコンテキスト変数に対応する。既存のベンチマークでは分析クエリにおけるスカラー関数を十分に負荷検証できないため、元のクエリの意図を保持しつつスカラー関数を利用するTPC-Hのバリアントを導入する。生成したGPUカーネルを最先端のGPUデータベースシステムに統合した結果、わずかに高価なハードウェアを使用する主要なCPUデータベースと比較して、拡張TPC-Hで7.6倍、プロダクションクエリで6.4倍という substantial な性能向上を実証し、GPUとCPUデータベース間の性能差をさらに拡大した。生成されたカーネルは手動で最適化されたGPU実装に匹敵する性能を達成しており、本アプローチはGPU上でのスカラー関数高速化における拡張可能かつ実用的な解決策であることを確立する。
One-sentence Summary
Microsoft presents an LLVM-MLIR-based compiler toolchain that automatically translates the hundreds of CPU-based scalar functions in production databases into efficient GPU kernels by lifting them to a high-level intermediate representation and applying resource-optimizing transformations, yielding 7.6× and 6.4× speedups over a leading CPU database on enhanced TPC-H and production queries, respectively.
Key Contributions
-
An empirical roofline analysis of database scalar functions shows that simple arithmetic and conversion operations are memory-bound, while most other scalar functions are compute-bound, making them strong candidates for GPU acceleration.
-
An LLVM-MLIR-based compiler toolchain automatically translates CPU scalar-function implementations from production databases into GPU kernels while preserving original semantics, lifting code to MLIR, applying resource-optimizing transformations, and generating GPU assembly for relevant data types, parameters, and database context variables.
-
A TPC-H variant stresses scalar functions while preserving original query intent, and integration into a GPU database achieves 7.6x speedup on enhanced TPC-H and 6.4x on production queries over a leading CPU database with slightly more expensive hardware, with generated kernels comparable to hand-optimized GPU implementations.
Introduction
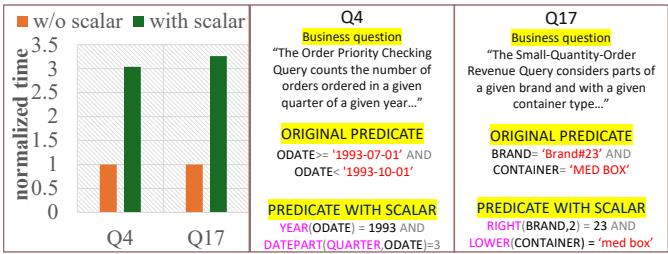
Analytical database queries commonly use scalar SQL functions for string manipulation, date arithmetic, type conversion, and numeric computation, and the paper shows these functions are frequent in production workloads and can account for a large share of CPU query time. Prior GPU database work mostly accelerated relational operators, while scalar functions remained difficult because they number in the hundreds, have vendor-specific semantics, and often force expensive GPU to CPU fallbacks over PCIe. The authors leverage LLVM MLIR to translate existing C++ scalar function implementations from SQL Server into optimized GPU kernels, and they add TPC-H-scalar, a benchmark suite that reflects realistic scalar function usage. They integrate these kernels into a GPU database and show substantial end-to-end speedups over a high-end CPU system.
Dataset
-
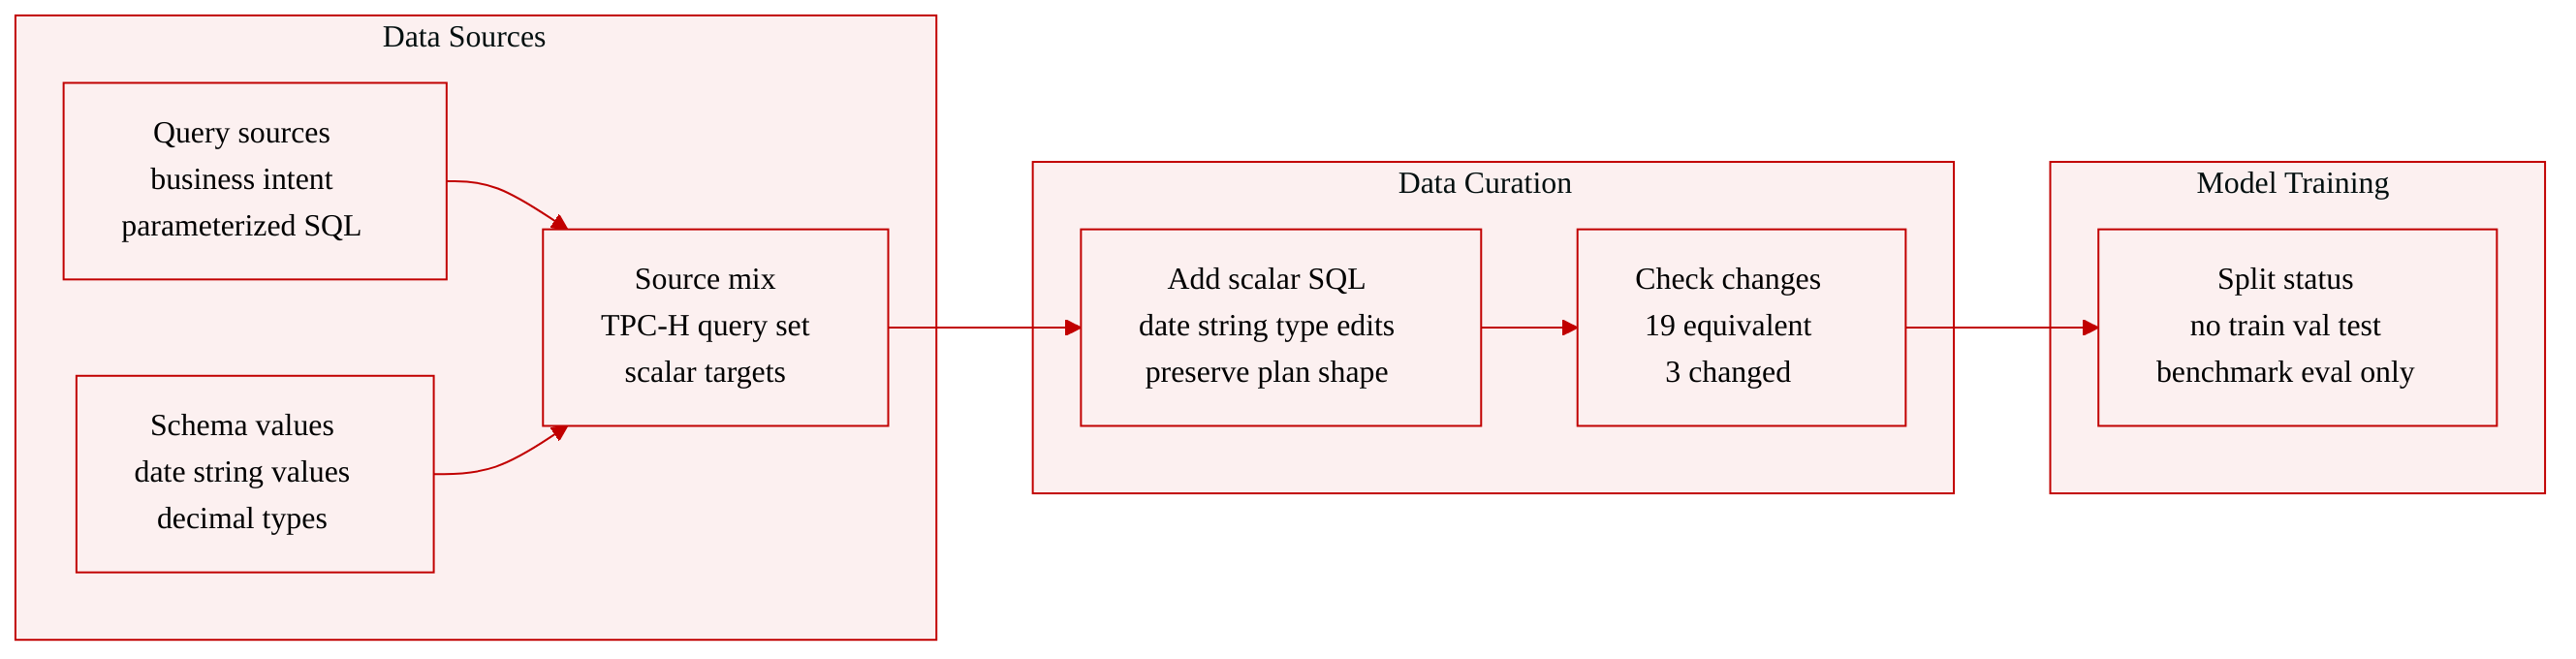
The authors use TPC-H as the source benchmark dataset. They represent each query with a business question, a functional SQL definition, and substitution parameters, then build TPC-H-scalar by injecting scalar functions into projections and filters.
-
The resulting benchmark workload is used to evaluate scalar-function handling, not as a model-training corpus. The provided text does not define training splits, mixture ratios, cropping, or additional metadata beyond the benchmark query definitions and parameter rules.
-
The authors apply a strict filtering and preservation rule: scalar functions are added only by replacing projection or filter expressions while preserving the high-level analytical intent. They preserve plan shape and cardinalities so the modified queries keep the performance characteristics of the original relational operators.
-
Across the benchmark, the authors report that 19 queries remain equivalent to the original TPC-H queries, and only three queries are not equivalent. The relevant schema includes date columns such as l_shipdate, o_orderdate, and l_receiptdate; string columns such as p_type, o_orderpriority, and p_brand; phone strings; and decimal columns such as l_discount and l_tax. Original TPC-H data has fixed-precision decimal columns and no float columns, while modified queries introduce float constants in arithmetic expressions.
-
C1, date-part extraction: Nine queries are modified to apply scalar date functions such as YEAR and DATEPART to date columns and compare the results with numeric year, month, or quarter parameters instead of database-specific date strings.
-
C2, string normalization before comparison: String equality predicates are rewritten to normalize values with functions such as LOWER before comparing against constants, reflecting production cases where casing or punctuation may vary.
-
C3, type conversion: Two queries are modified to format date output using CONVERT. Other expressions that use l_discount or l_tax are scaled with float constants and converted to decimal or money types to simulate production-style precise arithmetic and currency conversion.
-
C4, extracting or validating part of a string: Queries that filter on strings with embedded numeric parts, such as order priority, brand identifiers, or phone country codes, are rewritten to use string extraction functions such as RIGHT, LEFT, or SUBSTRING-like logic and compare the extracted value with a parameter.
-
C5, date arithmetic: Three queries are rewritten to use DATEADD or DATEDIFF when comparing or combining date columns. These are the only non-equivalent queries, and the filters are adjusted to retain similar predicate selectivity.
Method
Compiler Architecture and Code Generation Pipeline
The authors leverage MLIR as the central intermediate representation for compiling existing C++ scalar database functions into GPU kernels. The input is not a hand-written kernel, but the original implementation of a scalar function together with all transitively referenced functions. A standard C++ frontend first resolves templates, overload selection, and polymorphism, and the Polygeist compiler translates the resulting C++ AST into MLIR. In this representation, classes become struct types, member functions are mapped to func operations, memory accesses are expressed through memref operations, scalar computation uses arith operations, and common math or memory intrinsics are mapped to existing MLIR dialects. The produced IR is in Static Single Assignment form, with each value assigned exactly once, which gives the compiler a stable typed representation for analysis and transformation.
At a high level, the compilation workflow has four main phases: frontend translation, high-level simplification, loop restructuring, and GPU lowering. The authors leverage a compiler composed of approximately 50 optimization and lowering passes, including custom passes specifically designed for the patterns that arise when compiling database scalar functions. The initial MLIR can be large and inefficient because C++ classes often contain many fields, only some of which are relevant to a particular function, and because early exits from loops or functions can generate redundant branches, loads, and stores in the IR. The compiler therefore applies scalar replacement of aggregates, store-load forwarding, constant propagation, common subexpression elimination, branch elimination, and peephole optimizations at the high-level dialect stage. Scalar replacement of aggregates decomposes struct and class allocations into individual scalar fields, enabling later analyses to determine whether each field is written, read, updated with a constant, or unused. This makes it possible to remove unnecessary fields and control flow before the program is lowered to more target-specific representations. As shown in the figure below:
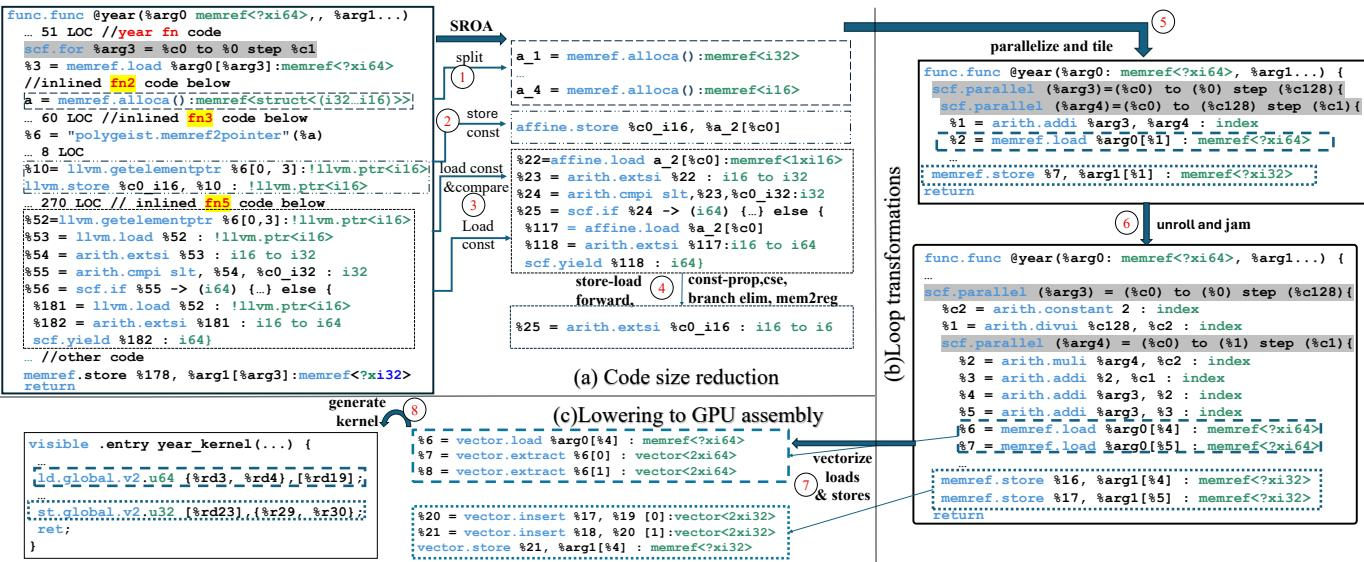
After simplification, the compiler transforms serial loops into tiled parallel loops that align with the GPU thread hierarchy. These loop tiles are then processed by an unroll and jam transformation, which increases the amount of work performed by each thread during a single kernel invocation. This thread coarsening reduces thread block and warp scheduling overhead, improves reuse of loaded values, and exposes contiguous memory accesses. Once such accesses are visible, the compiler converts them into vector loads and stores using the vector dialect. The goal is to make the final GPU kernel issue wide hardware memory instructions, such as loads that fetch two 64-bit values in a single instruction. This is particularly important because the target execution model processes column vectors rather than individual scalar rows, so memory access efficiency strongly affects throughput.
For GPU lowering, the tiled loop body is outlined into a gpu.func kernel. Loop indices are replaced by expressions that derive each thread’s index from the GPU block and thread identifiers. During this phase, the compiler carefully sinks constants into the kernel body rather than passing them as kernel parameters. Keeping constants local to the kernel allows later lowering passes to specialize the generated code for the known constant values, which can remove branches, simplify address computation, and produce more efficient instruction sequences. The remaining dialects inside the kernel are then lowered to LLVM IR, and LLVM’s code generator emits GPU assembly. In the generated kernel, vectorized loads and stores appear as native wide-memory operations, reducing instruction count and improving bandwidth utilization.
The pipeline also includes offline auto-tuning and pre-compilation. Because the set of supported scalar functions is known ahead of time, kernels can be generated during the system build process and reused at runtime. The compiler augments its loop optimization strategy with an auto-tuner that sweeps two key parameters: loop tile size and unroll factor. Candidate configurations include:
t∈{64,128,…,1024},u∈{1,2,4}.For each scalar function, the auto-tuner benchmarks generated kernel variants on representative inputs and selects the configuration that minimizes execution time:
(t∗,u∗)=argt,uminLatency(kernelt,u).The selected precompiled kernels are stored with the system and dynamically loaded when query execution encounters the corresponding scalar operator.
The compiler is integrated into a tensor query processing engine through extensions to the query optimizer, tensor abstraction layer, and runtime. The optimizer identifies GPU-supported subplans that contain scalar operators, allowing such operators to be offloaded to the accelerator. The tensor abstraction layer exposes additional operators that invoke precompiled kernels over tensor inputs and outputs. Input tables are transferred to the GPU in compressed columnar format to reduce data movement, then decompressed into one-dimensional tensors before kernel execution. Each operator consumes input tensors and produces output tensors.
String columns require a specialized GPU representation because scalar functions that manipulate strings typically expect a different memory layout than the columnar tensor format. The runtime therefore represents string vectors as three tensors, one for string data, one for offsets, and one for lengths. For each string scalar function, a stub function adapts the tensor-oriented interface to the original row-based implementation by iterating over the triple of vectors and invoking the underlying C++ scalar function. Dynamic memory allocation is also carefully controlled. String output buffers are provided by the runtime and preallocated on the GPU, while short-lived allocations in scalar functions are represented as stack allocations in the IR. Standard library calls for mathematical and memory operations are mapped to existing MLIR dialects, allowing the compiler to generate GPU code without requiring special handwritten intrinsics for every common operation.
Experiment
The experiments evaluate the impact of scalar functions in analytical databases using an enhanced TPC-H benchmark, production workload queries, and microbenchmarks, while comparing a GPU compiler system against a commercial CPU database under both warm and cold data conditions. These studies validate that compiler-generated GPU kernels significantly reduce scalar-function overhead and deliver strong end-to-end query performance, while remaining competitive with manually tuned and higher-level kernel implementations. Additional roofline and portability analyses show that the approach generalizes across GPU vendors, although data-dependent string and date functions can limit peak efficiency.
The implementation uses MLIR dialects to represent C++ scalar functions during compilation into GPU kernels. These dialects cover functions, control flow, memory operations, arithmetic, math libraries, and Polygeist-specific conversions for cases not handled by the standard high-level operations. This structure supports lowering from C++ constructs to machine-level memory and computation while preserving useful analysis boundaries. Function dialects represent function bodies and calls. Affine dialects expose loops with static bounds for possible parallelization. Structured control flow dialects capture loops and conditional regions. Memref dialects support complex memory layouts before hardware lowering. Arithmetic and math dialects cover scalar operations and standard functions. Polygeist dialect operations provide conversions such as memref to pointer.
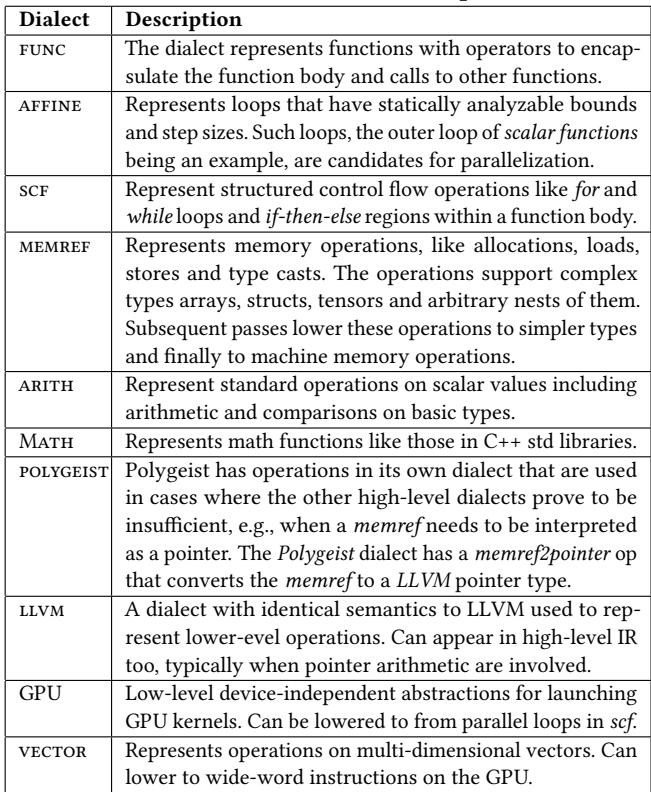
The table groups scalar expression usage into date extraction, string normalization, type conversion, string extraction or validation, and date arithmetic. These patterns appear in analytical queries during filtering, projection, grouping, and aggregation. They can be incorporated into benchmark queries while preserving the original plan shape and cardinality. Date extraction functions are used to filter or project year, month, and quarter components from date columns. String normalization functions standardize text before comparisons, handling case and punctuation differences. Type conversion functions format dates for output and adjust numeric or mixed type expressions. String extraction and validation functions reveal embedded numeric fields and check whether values look numeric or date like. Date arithmetic functions express date ranges and relative date checks instead of simple constant comparisons.
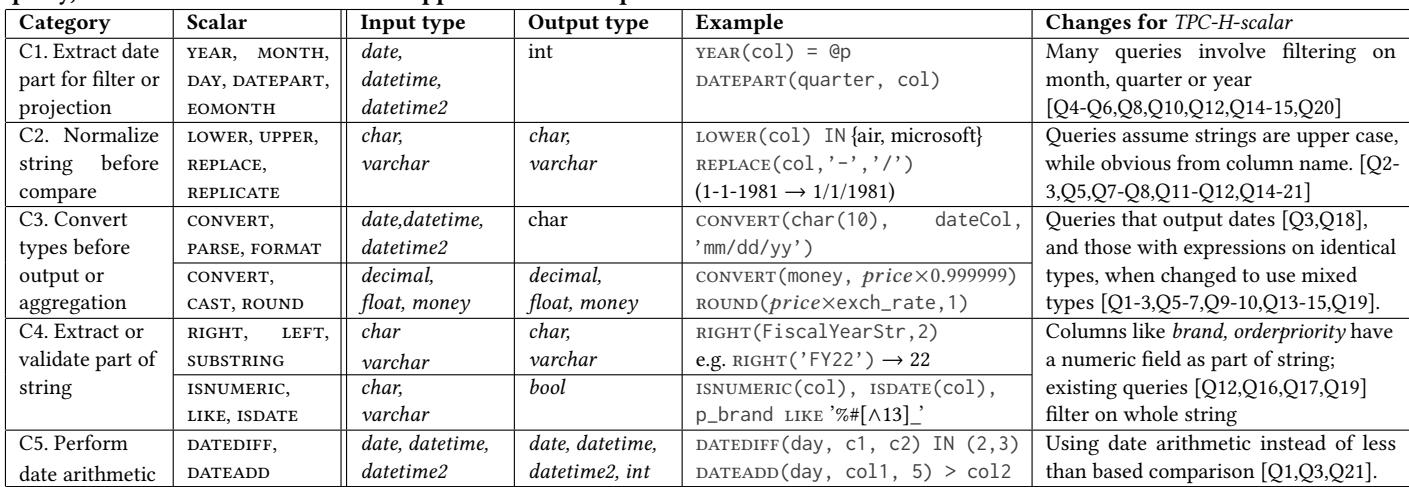
The evaluation is organized around compiling C++ scalar functions into GPU kernels using MLIR dialects for functions, control flow, memory, arithmetic, math, and Polygeist conversions, with each experiment validating the representation and lowering of a specific class of constructs while preserving useful analysis boundaries. A separate categorization of scalar expression usage covers date extraction, string normalization, type conversion, string extraction or validation, and date arithmetic, showing that these patterns appear naturally in analytical filtering, projection, grouping, and aggregation. Overall, the results indicate that the dialect design supports structured lowering of complex scalar logic and that the identified expression patterns can be incorporated into benchmark queries without changing the original plan shape or cardinality.