Command Palette
Search for a command to run...
汎用的なUDFクエリのためのベンチマーク UDFBench
汎用的なUDFクエリのためのベンチマーク UDFBench
Yannis Foufoulas Theoni Palaiologou Alkis Simitsis
概要
ユーザー定義関数(UDF)は、宣言型SQLに機能的な能力を付与することで表現力を拡張するが、UDFとSQLの実行環境間におけるインピーダンスミスマッチ、およびクエリオプティマイザがUDFクエリに対して常に優れた実行計画を生成できないという限界により、クエリ処理における根本的なボトルネックとなる。研究面および商用面では、論理最適化やヒューリスティックから物理最適化やコンパイル技術に至るまで、高性能なUDFクエリ実行を実現するための様々な手法が提案されている。しかし、各手法は提案する技術の評価において異なるアプローチを採用している。UDFクエリの最適化は実用上極めて重要であるにもかかわらず、これまでにUDFはデータベースベンチマークの焦点となったことがない。本論文では、実世界のスキーマとデータに基づくUDFを中心としたデータベースベンチマークであるUDFBenchを提案する。UDFクエリ実行における主要なオーバーヘッドを特定し、これらのオーバーヘッドを単独または複合的に実験的に評価できるよう、UDFBenchのUDFおよびクエリを設計する。最後に、UDFBenchの移植性と適用範囲を示すため、特性の異なる5つの主要データベースに対する実験的分析を提示する。
One-sentence Summary
Athena Research Center and University of Athens introduce UDFBench, a UDF-centric database benchmark built on real-world schema and data that isolates and combines core overheads in UDF query execution to enable portable experimentation across five popular databases with distinct architectural characteristics.
Key Contributions
-
A choke-point analysis of research and commercial UDF query processing techniques identifies core execution overheads and performance deficiencies, covering logical and physical optimization, UDF and data type variety, programming languages, and execution environments.
-
UDFBench is presented as a modular, open-source benchmark based on real-world schema, data, and queries, designed to test UDFs as first-class citizens in SQL queries and to isolate or combine core execution overheads.
-
Experimental evaluation on five data engines with different architectures demonstrates portability, reveals performance deficiencies and design limitations, and provides a standardized testbed for engines supporting multi-lingual UDFs in SQL.
Introduction
The authors examine user defined functions in relational SQL engines, where UDFs let developers embed complex logic and analytics in database queries. This matters for data science and analytics workloads, especially Python based UDFs, but performance is often poor because SQL evaluation and procedural execution are poorly integrated, creating conversion and optimization overheads.
Prior benchmarks mostly target joins, transactions, or procedural SQL, and SQL ProcBench remains limited by dialect specific definitions, narrow UDF coverage, simple query patterns, and weak support for cross language UDF execution. The authors respond with UDFBench, a modular, open source benchmark that treats UDFs as first class citizens, uses a real world inspired schema, data, and queries, and evaluates multiple data engines to expose bottlenecks and guide future research.
Dataset
-
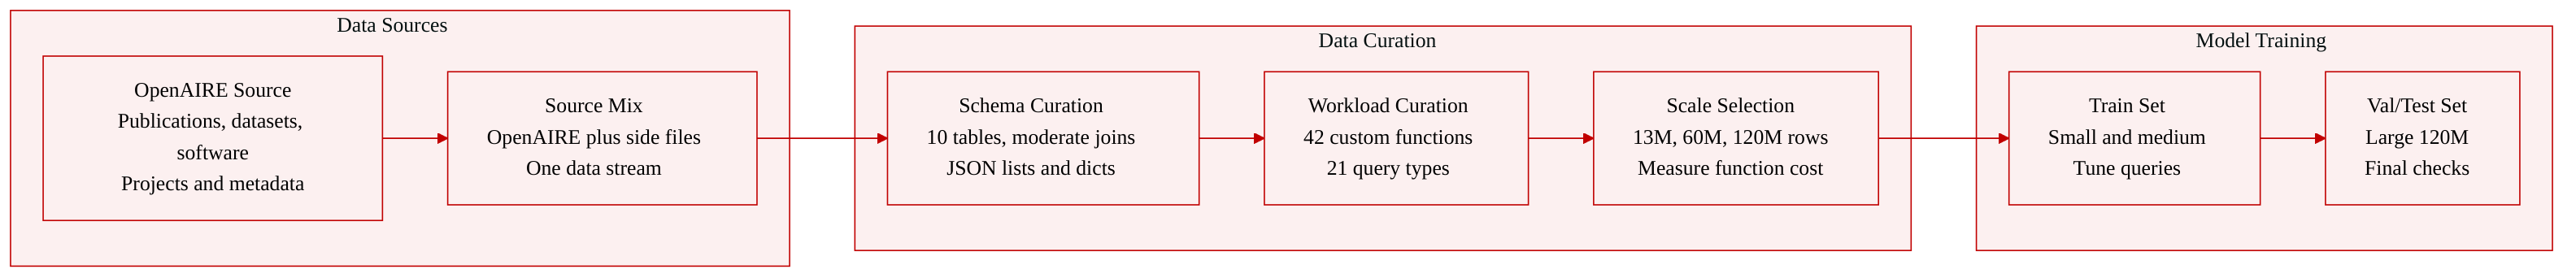
Dataset source: The authors derive UDFBench from OpenAIRE, a real-world information extraction and analytics system for Open Access publications, including harvested publications, datasets, software artifacts, and projects.
-
Core composition: The benchmark combines a curated database schema, real-world data at three scale factors, user-defined functions, and SQL queries that mix relational operators with UDFs.
-
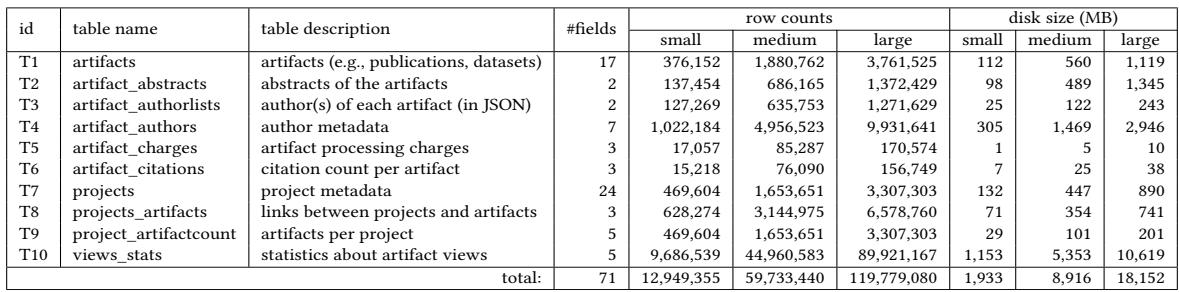
Schema: The schema contains 10 tables: two core tables for artifacts and projects, seven tables for author metadata, author lists, abstracts, accessing fees, project-artifact links, and related metadata, and one table for artifact view statistics.
-
Data shape and filtering: The schema includes denormalized and semi-structured fields such as JSON lists and dictionaries, plus connections to external denormalized files. The authors focus on moderate join paths, aggregations, grouping, and mixed data types rather than very large many-join benchmarks.
-
Data scale subsets: The paper provides three real-world data subsets: small with 13 million rows, medium with 60 million rows, and large with 120 million rows. The chosen sizes are intended to expose UDF overhead without mixing it excessively with I/O or disk-spill effects.
-
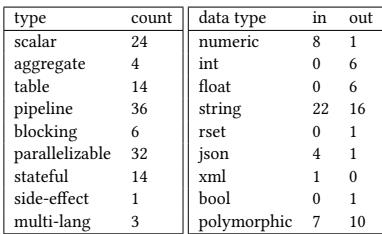
UDF subset: The benchmark includes 42 UDFs inspired by production OpenAIRE code, covering 24 scalar, 4 aggregate, and 14 table UDFs across 10 subtype categories. These UDFs vary in input/output schema mapping, pipeline versus blocking behavior, parallelizability, statefulness, side effects, supported languages, and simple versus complex data types.
-
Query subset: The benchmark includes 21 queries inspired by real-world use cases. They are organized into four classes: simple UDF-heavy queries, queries mixing UDFs with expensive relational operators, queries with complex relational logic and deep nesting, and queries involving DML operations such as insert and update.
-
Query metadata: Each query is characterized by its class, number and type of UDFs, input/output data types, null handling, UDF chaining and nesting depth, potential optimizations, in-process behavior, dynamic or stateful UDF usage, and count of expensive relational operators.
-
Processing and metadata construction: The authors classify UDFs and queries using schema and workload metadata, including UDF types, subtypes, data types, parallelism, statefulness, side effects, and optimization opportunities. The data are constructed to test scalar, aggregate, and table UDF behavior across engines.
-
Usage in the paper: The authors use the dataset as a benchmark testbed, not as a model-training corpus. The schema, data subsets, UDFs, and queries are used to evaluate UDF execution overhead, query optimization opportunities, execution modes, and engine-specific UDF capabilities.
-
No cropping strategy: This is a database benchmark dataset, so no image cropping or visual preprocessing is used. The main processing steps are schema curation, data scaling, UDF classification, query design, and workload metadata annotation.
Method
The authors design UDFBench around a choke point analysis method that decomposes UDF query execution into measurable subsystems: language runtime boundaries, UDF type mappings, data type conversion, execution scheduling, query optimization surface, and UDF specific compiler techniques. Instead of evaluating isolated functions, the framework generates queries that combine relational operators with scalar, aggregate, and table functions, then measures how each factor contributes to end to end latency. The goal is to expose where overhead originates before it is hidden inside an engine black box.
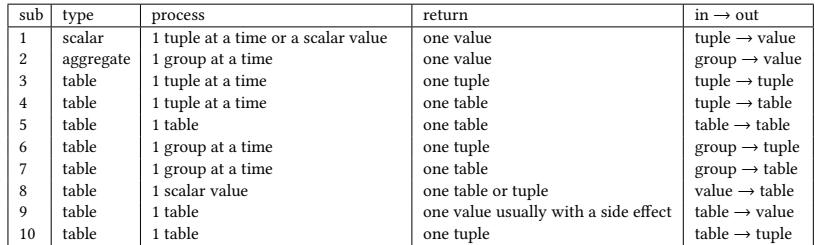
The workload is centered on a curated UDF catalog. Scalar functions process one input tuple and return one value. Aggregate functions process one group and return one value. Table functions process a table, a group, or scalar arguments and may return a tuple or a new table. The authors represent the general relationship as f:I→O, where I and O can denote tuples, groups, or tables. Based on these input to output mappings, the benchmark organizes UDFs into subtypes that expose different execution behaviors. Row level table functions are candidates for data partitioning and parallel execution, while whole table functions are blocking. Group level table functions resemble aggregates but produce multiple output rows, creating a different optimization space.
The implementation layer adapts these UDFs to engine specific mechanisms. The authors account for differences in supported languages, type systems, persistence, and parallel execution. Polymorphic UDFs can be written once and typed at query time in engines that support such dynamic signatures, while other engines require separate implementations for each type variation. Stateful functions depend on whether an engine can preserve compiled resources across calls. Parallel execution is exposed through engine level hints or safe parallel annotations, and the benchmark also includes thread and process based scheduling choices to compare scalability.
Data type handling is treated as a major source of overhead. Simple numeric values may pass through runtime interfaces with limited conversion. String values can involve buffers, memory views, or direct pointers, depending on the engine and UDF language. Complex types often require serialization into JSON, conversion to native objects, and later conversion back to relational representations. The authors include both simple and complex return types in equivalent scalar UDF variants, so the measured cost separates computation from conversion and copy behavior.
As shown in the figure below:
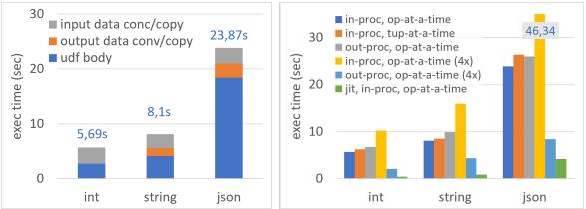
The left comparison shows that returning integer, string, or JSON values from semantically similar scalar UDFs changes the balance between UDF body execution and input or output conversion. The right comparison contrasts execution strategies such as in process versus out of process invocation, operator at a time versus tuple at a time execution, thread parallelism, process parallelism, and JIT compiled execution. This allows the authors to attribute performance differences to runtime interaction, function call volume, parallelism limits, and compiler support.
The query design then combines these components into optimization test cases. The authors create query patterns with nested calls, chained scalar functions, filter plus map plus table function pipelines, aggregate processing, polymorphic table sources, and stateful functions. These structures provide an increasing ladder of complexity for techniques such as predicate reordering, UDF pushdown, adaptive execution, loop fusion, vectorization, function inlining or outlining, and JIT compilation. By embedding the UDFs inside SQL pipelines rather than testing them as isolated programs, UDFBench measures the interaction between procedural logic and relational execution.
Experiment
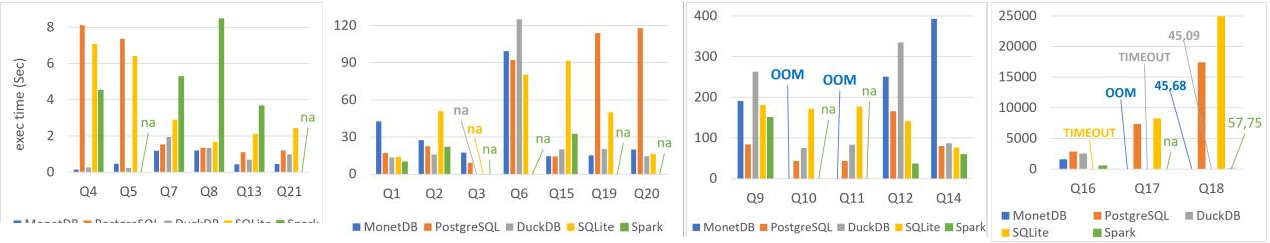
The experiments evaluate UDFBench across PostgreSQL, MonetDB, DuckDB, SQLite, and Spark using a real-world OpenAIRE-derived schema, multiple dataset scales, 42 UDFs, and four query classes, with micro-experiments that validate UDF types, execution architecture, parallelism, statefulness, optimization, compilation, programming language, distributed execution, and implementation complexity. The results show that vectorized engines excel for aggregate and zero-copy UDF execution, while tuple-at-a-time or in-process models can be more effective for blocking table UDFs, and parallelism depends strongly on engine design and language constraints. Overall, stateful and fused UDF implementations reduce overhead, current query optimizers often miss UDF-aware reordering, and adaptive execution or JIT compilation offer promising but not yet fully realized improvements, while poor support for many UDF subtypes limits execution compatibility.
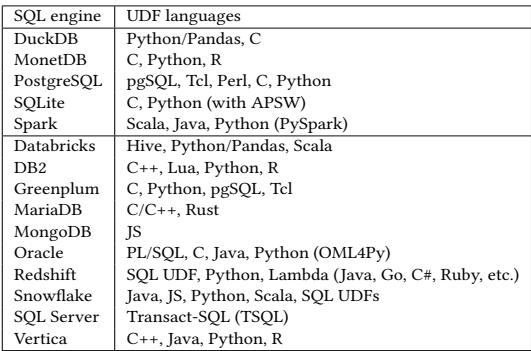
Popular SQL engines support a wide range of UDF languages, with C/C++ and Python appearing across most engines and additional support varying by engine. This diversity complicates query execution because a single query may combine UDFs from different language runtimes, requiring data conversion and coordinated processing. Python is one of the most broadly supported UDF languages across SQL engines. C and C++ support is also common across engines. Additional UDF language support varies by engine, including R, Java, Scala, Perl, Tcl, and Hive.
The benchmark schema is based on a real-world scholarly metadata application and includes tables centered on artifacts and projects, with supporting tables for abstracts, author metadata, author lists, charges, and citations. Its small, medium, and large data sizes scale row counts and disk footprints consistently while remaining sized to expose UDF overheads without excessive I/O or disk spills. The schema also contains nested attributes and varied data types, enabling queries with aggregations, grouping, and moderate join paths beyond purely relational processing. The core artifact and project tables connect to multiple supporting tables for metadata and related records. Author information appears in both relational metadata and nested JSON-style lists, encouraging UDFs that handle more than standard SQL values. The dataset grows proportionally across scale factors, preserving the same schema while increasing volume and storage footprint.
The table classifies UDFs by type and subtype based on their input and output behavior, covering scalar, aggregate, and table UDFs. Scalar and aggregate UDFs have a fixed mapping from input to output, while table UDFs include multiple mappings such as tuple, group, and table inputs and outputs. These distinctions shape execution behavior and optimization opportunities. Scalar and aggregate UDFs consistently map their inputs to outputs. Table UDFs have several input-to-output mappings, including tuple to tuple and tuple to table. Table UDFs that process one tuple at a time can be parallelized through data partitioning. Table UDFs that process an entire table at once behave as blocking operations. Group-at-a-time table UDFs return multiple values and enable optimizations similar to aggregate UDFs.
The UDF set is dominated by scalar and table functions, with table UDFs spanning multiple input and output mappings. Pipeline execution is more common than blocking execution, and many functions can be parallelized, while a smaller portion is stateful. String types are the most frequent input and output schema types, and several numeric-related types appear mainly in outputs. Pipeline execution is much more common than blocking execution among the UDFs. Parallelizable UDFs are more frequent than stateful UDFs. String types dominate the input and output schemata, while aggregate-oriented numeric types appear mainly in outputs.
The benchmark collection covers a broad mix of user-defined functions, classified by function type, input-output mapping, and cost or complexity. Scalar functions dominate the set, table functions form a substantial and varied group, and aggregate functions are comparatively few. Scalar UDFs are the most common, while table UDFs are also well represented and span multiple subtypes. The classification separates simple same-shape scalar and aggregate mappings from more complex table mappings, including parallelizable tuple or group processing and blocking whole-table processing.
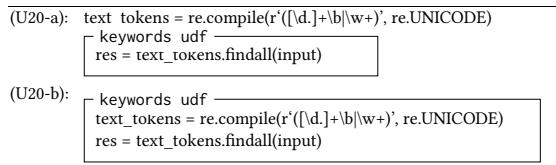
The experiments build a benchmark on a realistic scholarly-metadata schema and evaluate it at several scale factors to expose UDF overhead while limiting I/O and spills. The evaluation classifies user-defined functions by language support, scalar, aggregate, and table type, input-output mapping, execution mode, parallelizability, and complexity. Qualitative results show that UDF support varies across engines, scalar and table functions dominate, and pipeline and parallelizable UDFs are more common than blocking or stateful ones. These findings indicate that effective UDF execution systems must handle diverse languages, nested data types, string-heavy workloads, and mixed operator semantics.