Command Palette
Search for a command to run...
拡散モデルが記憶化しない理由:学習における暗黙的な動力学的正則化の役割
拡散モデルが記憶化しない理由:学習における暗黙的な動力学的正則化の役割
Tony Bonnaire Giulio Biroli Raphaël Urfin Marc Mézard
概要
拡散モデルは幅広い生成タスクにおいて顕著な成功を収めている。その重要な課題は、学習データの記憶化を防ぎ汎化を可能にするメカニズムの理解にある。本研究では、汎化から記憶化への過渡における学習動力学の役割を調査する。大規模な実験と理論分析を通じて、2つの異なる時間スケールを特定する:モデルが高品質なサンプルの生成を開始する初期時間 τ_gen と、記憶化が現れる後期の時間 τ_mem である。重要なのは、τ_mem が学習データセットサイズ n に比例して線形に増加する一方、τ_gen は一定に保たれるという発見である。これにより、n の増加に伴いモデルが効果的に汎化する学習時間の窓が拡大するが、この窓を超えて学習を継続すると強い記憶化を示す。学習データセットサイズ n がモデルに依存する閾値を超えて初めて、無限の学習時間においても過学習が消失するようになる。これらの発見は、過剰パラメータ化された設定においても記憶化を回避可能にする、学習動力学における暗黙的な動力学的正則化の存在を明らかにしている。本結果は、現実的なデータセットおよび合成データセットに対する標準的なU-Netアーキテクチャを用いた数値実験と、高次元極限で研究された扱いやすいランダム特徴モデルを用いた理論分析によって裏付けられている。
One-sentence Summary
Researchers at LPENS, Université PSL, and Bocconi University demonstrate that diffusion models exhibit implicit dynamical regularization through two distinct timescales: an early τgen at which high-quality samples emerge and a later τmem growing linearly with dataset size n beyond which memorization occurs, creating a widening generalization window that prevents overfitting even in highly overparameterized settings.
Key Contributions
- The study identifies two training timescales in diffusion models: τ_gen, when high-quality generation first emerges, and τ_mem, when memorization of training data begins.
- τ_mem grows linearly with training-set size n while τ_gen remains constant, creating a broader window for early stopping as n increases; memorization at long training times disappears only when n exceeds a model-dependent threshold.
- Numerical experiments with standard U-Net architectures on realistic and synthetic datasets and a tractable random-features analysis in the high-dimensional limit support the presence of an implicit dynamical regularization that can prevent memorization in highly overparameterized diffusion models.
Introduction
Diffusion models and score-based generative methods are now central for generating images, audio, video, and scientific data. They learn a score function that guides sampling from noise, but models trained to zero loss can recover the empirical score and memorize training examples. Prior work identified memorization in large models and studied regularizers such as architecture, learning rate, and early stopping, yet it remained unclear why highly expressive models often generalize before later overfitting.
The authors show that the training dynamics of score learning create an implicit regularization toward smooth, generalizing solutions. They identify two training timescales: an early time when high-quality novel samples emerge, and a much later time when the model begins memorizing the dataset. This second timescale grows with training set size, creating a wide early-stopping window for reliable generation.
Method
The authors leverage a compact score-learning model to isolate the architecture and training dynamics behind generalization and memorization in diffusion models. The core object is a score network parameterized as a two-layer Random Features Neural Network, where the first layer is random and frozen while the output layer is learned. For data in Rd, the score estimate is
sA(x)=pAσ(dWx),with W∈Rp×d drawn from a Gaussian distribution and kept fixed, A∈Rd×p updated during training, and σ applied elementwise. The analysis is carried out in the high-dimensional regime d,p,n→∞ while keeping
ψp=dp,ψn=dnfixed. This parametrization provides a tractable score module: the nonlinear random features σ(Wx/d) define a fixed nonlinear basis, and the learned matrix A controls how those features are combined into a vector field over the data space.
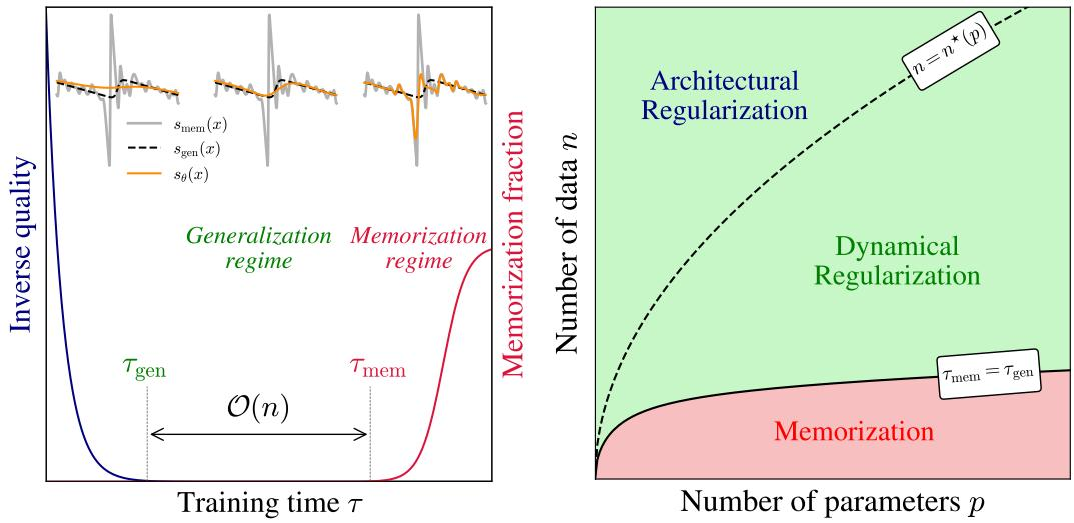
The overall learning trajectory, in which a model can first reach a generalization phase and later drift toward memorization, is summarized qualitatively in the framework illustration below.
The phase picture emphasizes two control knobs, the number of training points n and the expressivity of the score model, often measured by the number of parameters p. When n is small, training can lead to memorization of the empirical score. As n grows beyond a model-dependent threshold, the architecture itself prevents exact memorization, yielding what can be understood as architectural regularization. In addition, stopping training in an intermediate time window yields dynamical regularization, where the learned score is expressive enough to generalize but has not yet adapted fully to individual training samples.
The training pipeline is built around score matching at a fixed diffusion time t. For a clean sample x and noise ξ∼N(0,Id), the noisy state is of the form
xt(x,ξ)=e−tx+Δtξ.The empirical training objective is the score matching loss, rescaled by 1/d so that it remains finite as d grows. Conceptually, the loss penalizes the score network when its output does not correctly undo the injected noise. The corresponding test loss and the distance to the population score are
Ltest=d1Ex,ξ[ΔtsA(xt(ξ))+ξ2],and
Escore=d1Ex[∥sA(x)−∇logPx∥2].The first quantity measures in-sample and out-of-sample learning behavior, while the second measures how closely the learned field approaches the true population score. The gap
Lgen=Ltest−Ltrainis used as an indicator of overfitting.
The trainable output layer A is updated by gradient descent,
A(k+1)=A(k)−η∇ALtrain(A(k)),where η is the learning rate. In the small-learning-rate limit, and after rescaling discrete updates by
τ=d2kη,the discrete dynamics converges to a continuous gradient flow,
A˙(τ)=−2ΔtpdAU−p2dΔtVT.The matrix U is the central object controlling the speed of learning. It is an empirical second-moment matrix of the random features under the noisy input distribution,
U=n1ν=1∑nEξ[σ(dWxtν(ξ))σ(dWxtν(ξ))T],and V contains correlations between the random features and the injected noise,
V=n1ν=1∑nEξ[σ(dWxtν(ξ))ξT].Because the flow is linear in A, the dynamics can be solved exactly once the spectrum of U is known. The principal timescales of training are determined by the inverse eigenvalues of ΔtU/ψp. Thus, the architecture design reduces the training-time behavior of score learning to a spectral analysis problem.
To analyze the spectrum, the method introduces diffusion-time dependent quantities at, bt, vt2, and st2 built from Gaussian expectations of the activation σ. These quantities capture how the nonlinearity mixes the data scale, the diffusion scale, and the frozen random projection. With these objects, the Stieltjes transform of the eigenvalue density of U satisfies a coupled system of equations. Once this system is solved, the density is recovered from the imaginary part of the Stieltjes transform.
In the strongly overparameterized regime, the spectrum separates into distinct components. When ψp>ψn≫1, the spectral density can be written informally as
ρ(λ)=(1−ψp1+ψn)δ(λ−st2)+ψpψnρ1(λ)+ψp1ρ2(λ).The atom proportional to δ(λ−st2) does not affect the training or test losses and can be ignored for the dynamics. The two remaining parts, ρ2 and ρ1, generate different timescales. The bulk ρ2 lives on the scale ψp, while ρ1 lives on the scale ψp/ψn when the model is strongly overparameterized. In the underparameterized regime ψn>ψp≫1, the spectrum takes the form
ρ(λ)=(1−ψp1)ρ1(λ)+ψp1ρ2(λ),again with ρ1 and ρ2 corresponding to distinct learning directions.
The bulk ρ2 is associated with the early generalization stage. Its eigenvalues produce a timescale τgen of order 1/Δt. On this timescale, both training and test losses decrease, the generalization gap is effectively zero, and the model improves its approximation of the population score. The component ρ1 controls the later memorization stage. Its smaller eigenvalues produce a longer timescale,
τmem∼Δtλminψp,where λmin is the lower edge of the ρ1 bulk. In the overparameterized regime this becomes large and grows with the dataset size. On this longer timescale, the training loss continues to decrease, but the test loss begins to increase, reflecting overfitting to the finite sample score.
The dynamics predicted by this spectral analysis are visible directly in the Random Features training curves. Refer to the loss evolution figure below.
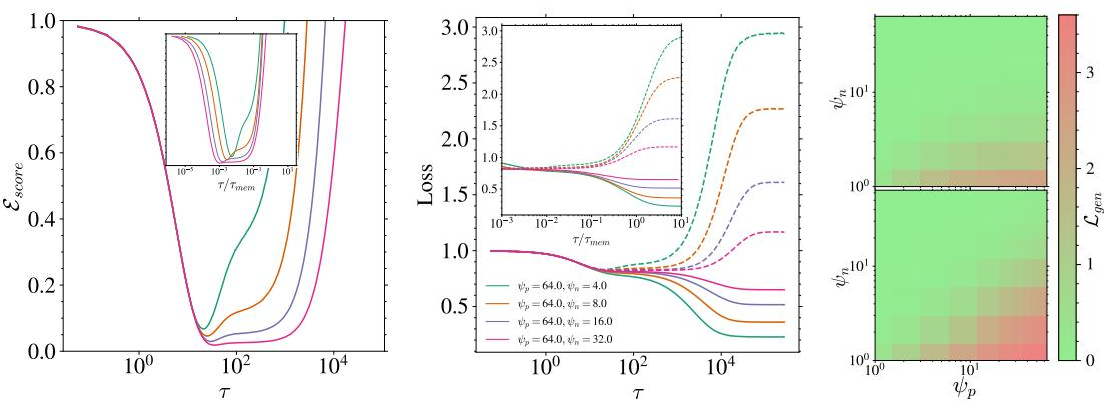
The trajectories show a fast decay of the distance to the true score followed by a later degradation. The test loss initially decreases along with the training loss, then increases after the memorization timescale is crossed. Rescaling time by τmem collapses curves with different dataset sizes, confirming the spectral prediction that the second timescale is governed by the smallest relevant eigenvalues of the feature covariance. Heatmaps over (ψn,ψp) further show how the generalization gap depends on the stopping time and on the parameter-to-data ratios.
For realistic diffusion models, the same training logic is studied with a conditional U-Net score architecture. The pipeline takes an image, applies the forward noise process, and feeds the noisy input together with a diffusion time embedding into the network. The score network uses three resolution levels with a base channel width W and multipliers 1, 2, and 3, and a sinusoidal time embedding is added to the features at each resolution. Training proceeds with stochastic gradient descent using momentum, and the learned score is evaluated by generating samples and measuring both sample quality and memorization through nearest-neighbor comparisons.
The architecture-level behavior is shown below.
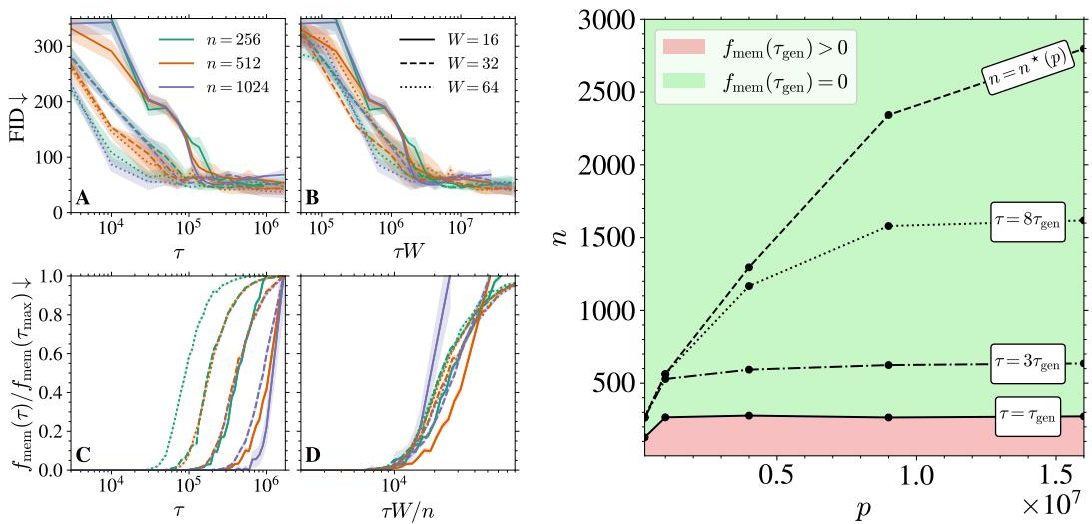
The curves illustrate how changing the number of parameters and the dataset size shifts the transition between generalization and memorization. When time is rescaled by the appropriate training-timescale factor, curves with different widths or dataset sizes align, indicating that the U-Net dynamics follows the same broad generalization-to-memorization structure identified in the Random Features analysis. The phase diagram also shows how the boundary between generalization and memorization moves with training time, reinforcing the dynamical regularization mechanism.
Experiment
Experiments trained diffusion models on grayscale CelebA images while varying dataset size and network capacity, tracking train and test losses, sample quality, and closeness to training examples to identify the shift from generalization to memorization. The results reveal a consistent two-phase training process: models first learn a reusable generative distribution, then later memorize the training set after a delayed overfitting stage, with larger datasets widening the useful early-training window and larger models compressing it. The study also shows that this behavior is not caused simply by repeated samples, but by the interaction of model expressivity, optimization time, and available data.