Command Palette
Search for a command to run...
拡散モデルを自身より能力の低い版で誘導する
拡散モデルを自身より能力の低い版で誘導する
Tero Karras Miika Aittala Tuomas Kynkäänniemi Jaakko Lehtinen Timo Aila Samuli Laine
概要
画像生成拡散モデルにおける主要な関心軸は、画像品質、生成結果の多様性、そしてクラスラベルやテキストプロンプトといった与えられた条件との整合性の度合いである。広く用いられているクラシファイアフリー誘導のアプローチでは、無条件モデルを用いて条件付きモデルを誘導し、プロンプトとの整合性の向上と高品質な画像生成を同時に実現する一方、多様性の低下を招く。これらの効果は本質的に絡み合っており、制御が困難であると考えられてきた。本研究では、無条件モデルではなく、モデル自身のより小さく未訓練な版を用いて生成を誘導することで、多様性を犠牲にすることなく画像品質に対するデカップリングされた制御が可能となるという驚くべき発見を得た。これによりImageNet生成において顕著な改善がもたらされ、公開されているネットワークを用いて64×64解像度でFID 1.01、512×512解像度でFID 1.25という最高記録を樹立した。さらに、本手法は無条件拡散モデルにも適用可能であり、その品質を大幅に向上させる。
One-sentence Summary
NVIDIA and Aalto University propose Autoguidance, which guides a diffusion model's generation using a smaller, less-trained version of itself instead of an unconditional model, enabling disentangled control over image quality without sacrificing variation and setting record FIDs of 1.01 and 1.25 on ImageNet at 64×64 and 512×512 resolution.
Key Contributions
-
The paper introduces a guidance method that replaces the unconditional model with a smaller, less-trained version of the same conditional model, enabling disentangled control over image quality while preserving sample variation.
-
An analysis of classifier-free guidance interprets its image-quality gains as adaptive truncation that moves samples away from under-fit regions toward a higher-quality implied distribution. Simple isotropic score amplification instead uniformly lengthens score vectors, reducing variation and oversimplifying details.
-
Experiments show record ImageNet FID scores of 1.01 at 64×64 and 1.25 at 512×512 using publicly available networks, while the same guidance also substantially improves unconditional diffusion models.
Introduction
Denoising diffusion models generate images by iteratively removing noise through a learned score function, often conditioned on labels or text prompts to control output. In practice, they are usually sampled with classifier-free guidance, a standard way to lower generation temperature by contrasting conditional and unconditional denoising estimates, which improves prompt alignment and image quality. However, classifier-free guidance only works for conditional generation, can push samples away from the intended conditional distribution because the guiding model solves a different task, and entangles quality gains with prompt-following gains. The authors introduce autoguidance, which instead guides sampling using a weaker version of the same model under the same conditioning, such as one with reduced capacity or training budget. This preserves the quality-boosting effect, avoids the task mismatch problem, supports unconditional generation, and improves image quality measured by FID and FID-like metrics.
Method
The authors leverage autoguidance to improve generation quality by guiding a strong diffusion model with a deliberately weaker version of the same model. The method uses two denoisers, denoted as D1 and D0. D1 is the target high-quality model, while D0 is a degraded model trained on the same task, with the same conditioning interface, and from the same data distribution. The weaker model differs from the stronger one by having additional quality limitations, such as lower capacity, fewer training iterations, reduced training quality, or synthetic perturbations applied at inference time.
At inference time, the standard denoiser output is replaced by a guided output that amplifies the difference between the strong and weak predictions. With a weight convention where w=1 recovers the strong model without guidance, the guided denoiser can be written as
D~(xt,t,c)=D0(xt,t,c)+w[D1(xt,t,c)−D0(xt,t,c)].Equivalently,
D~(xt,t,c)=D1(xt,t,c)+(w−1)[D1(xt,t,c)−D0(xt,t,c)].Here, xt is the current noisy sample, t is the diffusion time step, c is the optional conditioning signal, and w controls the guidance strength. During sampling, both D1 and D0 are evaluated at each step, and their difference provides a correction direction for the denoiser prediction. This correction is applied without introducing an external classifier, a separate conditional branch, or a different target distribution.
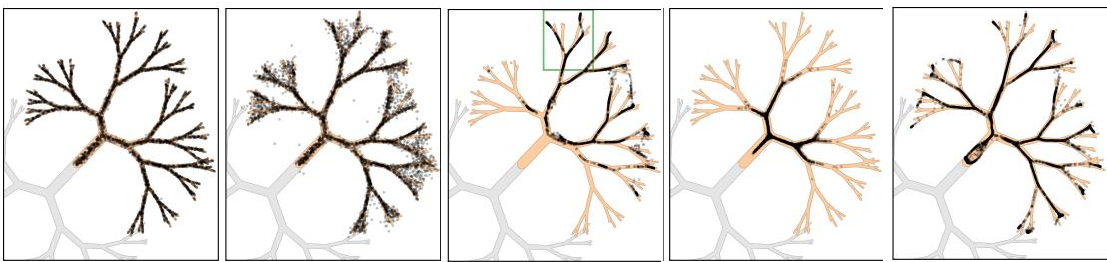
The motivation is that limited model capacity and under-training tend to produce characteristic errors in diffusion models. Score matching under constrained capacity often places excessive emphasis on low-probability or under-represented regions of the data distribution. The exact failure pattern depends on architecture, dataset, and training details, but a weaker version of the same model is expected to make broadly similar errors in the same regions, only more strongly. Autoguidance uses the disagreement between D1 and D0 to estimate where the stronger model is likely incorrect and to push samples away from those degraded predictions. When the two models agree, the correction is small. When they disagree, the difference indicates a direction associated with improved sample quality.
For the method to work, the two models must suffer from compatible degradations. The main model D1 and the guiding model D0 should target the same data distribution and make errors of the same general kind. The quality gap between them must also be large enough so that the systematic density spread-out caused by guidance outweighs random differences such as random initialization, data shuffling order, and independent training trajectories. In practice, D0 can be constructed as a smaller network, an early training snapshot, or a version of the base model with controlled perturbations.
The authors validate this principle through controlled synthetic degradations applied to a well-trained real-world diffusion model. The untouched base model serves as a reference for measuring whether guidance recovers the original sample quality. In the dropout setting, a light dropout variant is used as D1 and a stronger dropout variant as D0. Autoguidance with compatible dropout levels recovers performance close to the uncorrupted base model. In the input-noise setting, D1 is formed by increasing the input noise level of the base model, with the corresponding noise conditioning adjusted accordingly, while D0 uses a larger noise increase. Again, compatible noise perturbations allow guidance to recover performance close to the base model.
When the degradations are mismatched, such as using dropout for D1 and input noise for D0, guidance does not provide a benefit. In that case, the best result is obtained by disabling guidance, corresponding to w=1. This supports the central design constraint: autoguidance is effective only when both models share a common degradation pattern and therefore a meaningful quality direction.
A key architectural consequence of this design is that guidance no longer relies on an unrelated conditional or null model. Instead, it isolates the image quality correction from the conditioning mechanism. Because both models address the same distribution, autoguidance is not expected to suffer from the same high-noise limitations observed in classifier-free guidance, where different conditioning distributions can differ strongly in content and may unnecessarily reduce diversity.
Experiment
The experiments evaluate autoguidance through controlled synthetic degradations and ImageNet diffusion benchmarks using EDM2 baselines, comparing main models with weaker guiding models under compatible or mismatched degradations. The findings show that autoguidance is effective only when the guiding model reproduces the same broad types of errors as the main model, especially when it has reduced capacity and shorter training time. Overall, the method improves generation quality over classifier-free guidance while better preserving diversity, image coverage, and visual style, with notable benefits for unconditional generation.
Autoguidance improves diffusion model generation quality over the baseline and common guidance variants on both ImageNet resolutions. The best results occur when the guiding model is smaller and trained for less time than the main model, while using separate EMA settings for the two models further helps. The method also gives strong gains in unconditional generation, where the baseline performance is much weaker than in the conditional case. A smaller guiding model with a shortened training budget gives the strongest quality improvements. Sharing the same EMA setting between the main and guiding models worsens results compared with using independent EMA lengths. Autoguidance substantially improves unconditional ImageNet generation, where the baseline struggles more.
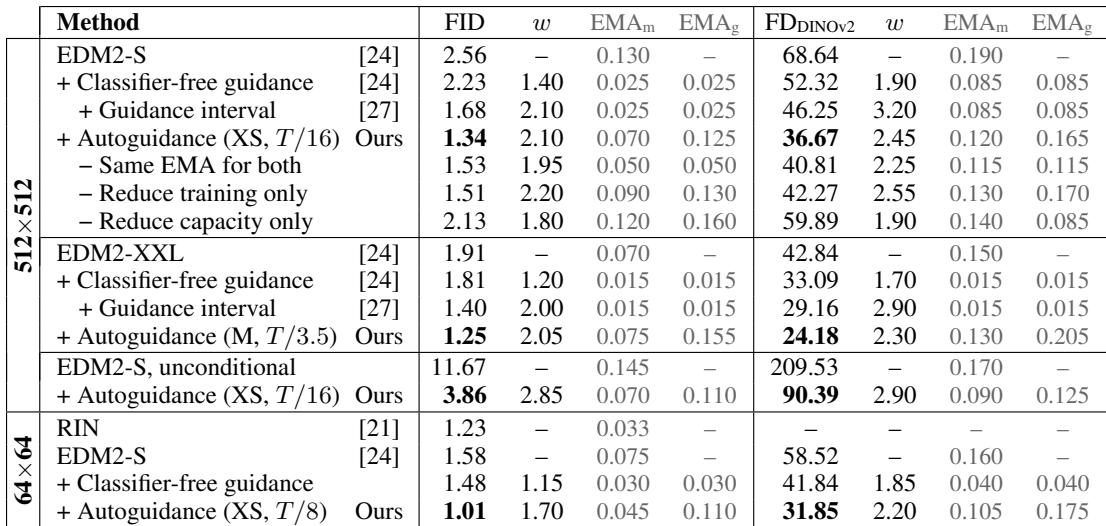
Experiments show that autoguidance improves diffusion model generation over the baseline and common guidance variants across ImageNet resolutions, with especially large benefits in unconditional generation where baseline performance is weaker. The strongest quality gains are obtained when the guiding model is smaller and trained for a shorter duration than the main model, and using separate EMA settings for the two models is better than sharing one setting.