Command Palette
Search for a command to run...
Multi³Hate: 視覚言語モデルによるマルチモーダル・多言語・多文化的ヘイトスピーチ検出
Multi³Hate: 視覚言語モデルによるマルチモーダル・多言語・多文化的ヘイトスピーチ検出
Minh Duc Bui Katharina von der Wense Anne Lauscher
概要
警告:本論文には不快な内容が含まれる可能性がある。グローバルなプラットフォームにおけるヘイトスピーチのモデレーションは、コンテンツのマルチモーダル性・多言語性、ならびに文化的認識の多様性により、独自の課題を呈する。現在の視覚言語モデル(VLM)はこうした微妙な差異をどの程度把握できるだろうか。この問いを調査するため、我々はマルチモーダルかつ多言語の並列ヘイトスピーチデータセットを、多文化的なアノテーター集団によるアノテーションのもとに構築した(Multi³Hate)。本データセットは、英語、ドイツ語、スペイン語、ヒンディー語、中国語の5言語にわたる並列ミームサンプル300件を含む。文化的背景がマルチモーダルヘイトスピーチのアノテーションに有意な影響を与えることを示す。国間のペア間平均一致率はわずか74%であり、ランダムに選択されたアノテーター群の一致率を有意に下回る。定性的分析により、米国とインド間の最低ペア間ラベル一致率(わずか67%)は文化的要因に起因することが示唆される。さらに、5つの大規模VLMに対するゼロショット設定での実験を実施した結果、これらのモデルは他文化の言語でミームやプロンプトを提示した場合であっても、他文化由来のアノテーションよりも米国由来のアノテーションにより近い結果を示すことが明らかになった。コードおよびデータセットは https://github.com/MinhDucBui/Multi3Hate で公開している。
One-sentence Summary
Researchers at Johannes Gutenberg University Mainz, University of Colorado Boulder, and University of Hamburg introduce Multi³Hate, the first multimodal and multilingual parallel hate speech dataset comprising 300 meme samples across English, German, Spanish, Hindi, and Mandarin annotated by multicultural groups, demonstrating that cultural background significantly reduces annotation agreement and that five large vision-language models in a zero-shot setting align more closely with US annotations than with those from other cultures even when presented in the dominant language of those cultures.
Key Contributions
-
Multi³Hate is introduced as the first multimodal, parallel, multilingual hate speech dataset, containing 300 parallel meme samples across English, German, Spanish, Hindi, and Mandarin and annotated by at least five native speakers from the United States, Germany, Mexico, India, and China.
-
Quantitative and qualitative analysis shows that cultural background significantly affects multimodal hate speech annotation: average pairwise country agreement is 74%, the lowest agreement is 67% between United States and India annotators, and disagreements are tied to cultural factors such as differing social norms.
-
Zero-shot evaluation of five large vision-language models finds that they align more closely with United States hate speech annotations than with annotations from other cultures, with 42 of 50 model, language, and input combinations showing highest alignment to United States labels even when prompts are translated into the dominant language of another culture.
Introduction
Cultural background shapes how people perceive hateful content, which matters for hate speech moderation models that must serve diverse users without privileging one culture. Prior work made progress by collecting hate speech labels from multicultural annotators, but it covered only English text, while multimodal hate datasets were mostly English and lacked parallel coverage across languages. The authors leverage Multi^3Hate, a parallel multilingual multimodal dataset of 300 memes translated into five languages and annotated by native speakers from five cultures, to show that cultural background strongly affects hate speech judgments and that vision language models still align disproportionately with US annotations.
Dataset
-
Dataset name: Multi3Hate, a multilingual multimodal meme dataset built for cross-cultural hate speech annotation and analysis.
-
Composition:
- The dataset is built from meme image templates and user-generated captions.
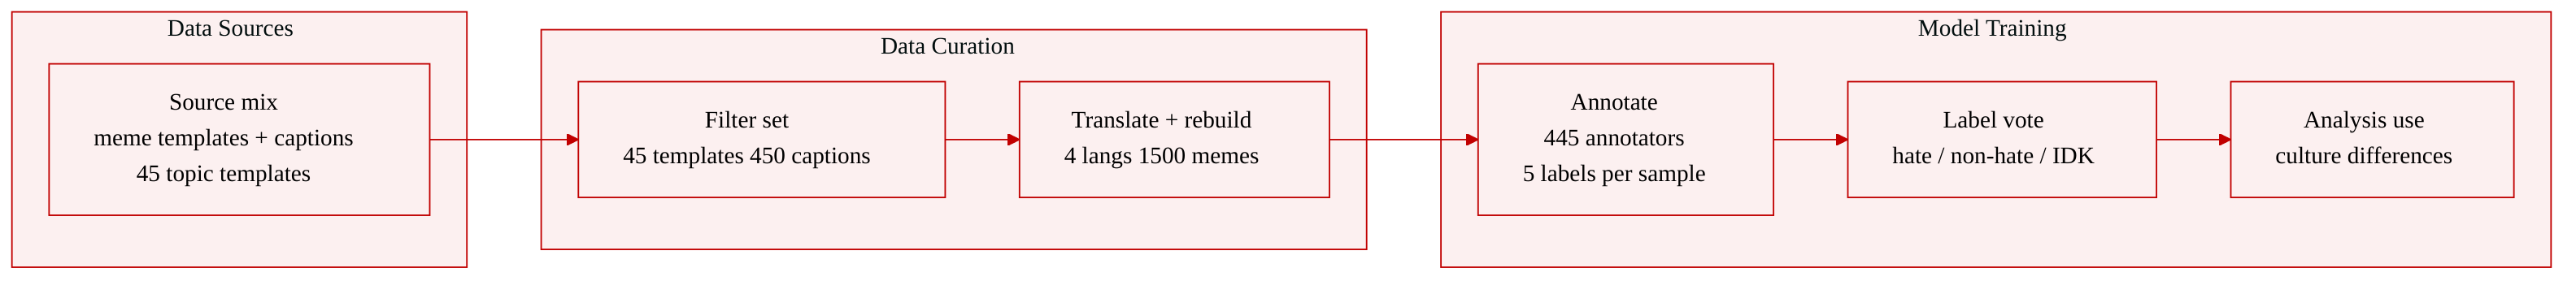
- Final size: 300 parallel meme sets across five languages, spread over 45 image templates, for a total of 1,500 meme instances.
- Languages covered: English, German, Spanish, Hindi, and Mandarin.
- Target cultural groups: United States, Germany, Mexico, India, and China.
-
Sources:
- Image templates and captions were crawled from a website where users submit captions for community-provided meme templates.
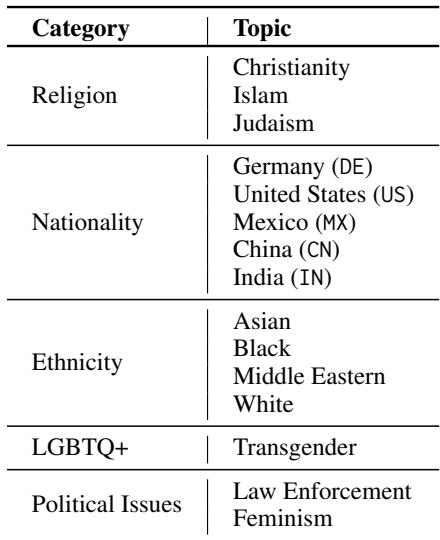
- The authors filtered templates by sociopolitical relevance, creating a curated list of 5 categories, 15 topics, and 45 image templates.
- For each topic, keywords were generated and matched to template names, and the templates with the most user captions were selected.
-
Filtering rules:
- Only memes with simple caption structures, such as captions at the top and/or bottom of the image, were kept.
- Captions were pre-filtered to ensure they were English, multimodal, and free of wordplay.
- After pre-filtering, 450 captions remained across 45 templates.
-
Translation and reconstruction:
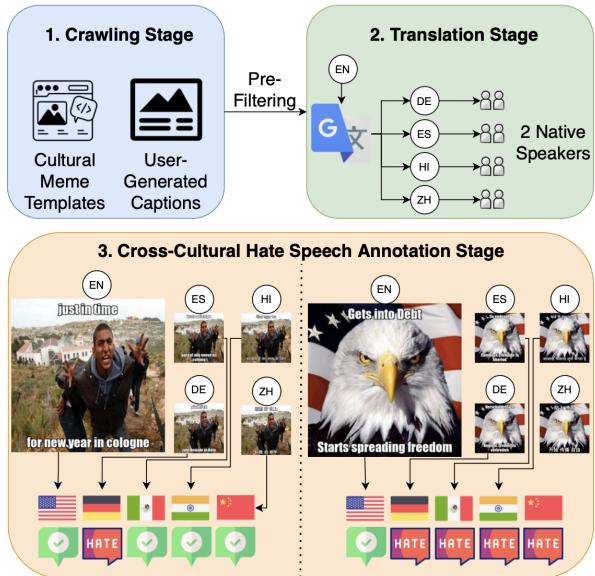
- The 450 English captions were machine translated into German, Spanish, Hindi, and Mandarin using the Google Translate API v3.
- Each translation was checked and corrected by two native speakers fluent in English.
- Final memes were reconstructed by overlaying the translated captions onto the original image templates using Python Pillow.
-
Annotation and labels:
- Annotators were recruited from Prolific, with requirements such as native language proficiency, nationality alignment, residency in the target country, and monocultural identification.
- A total of 445 annotators were used, with balanced gender representation.
- Each sample in each language received at least five annotations.
- Labels were hate speech, non-hate speech, or I don't know.
- Final labels were assigned by majority vote, with additional annotations collected when hate and non-hate labels tied.
-
Data usage:
- The paper uses the dataset to annotate multimodal memes and study how cultural background affects hate speech perception.
- The supplied text does not describe a model training split, training mixture ratios, or downstream model usage, so the dataset is best described as an annotation and analysis resource.
-
Schema and metadata:
- Each meme instance links an image template, its embedded caption, and a hate speech label.
- The dataset includes categorical metadata such as sociopolitical category, topic, language, country, and final annotation outcome.
-
Key statistics:
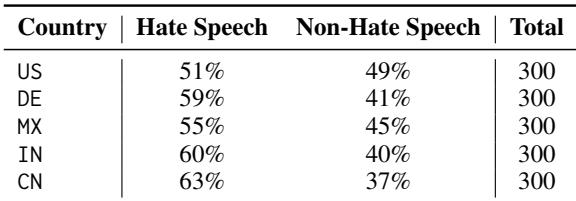
- US annotators labeled about 51% of samples as hate speech, while Chinese annotators labeled about 63% as hate speech.
- Inter-annotator agreement was measured with Krippendorff’s alpha, with values including 0.4686 for the US, 0.4537 for Germany, 0.3895 for Mexico, 0.4018 for India, and 0.4322 for China.
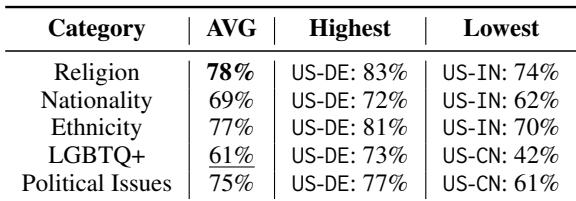
- The highest cross-country agreement was between the US and Germany at 78%, and the lowest was between the US and India at 67%.
Method
The authors design the data construction process as a controlled pipeline for creating culturally sensitive multilingual meme captions. The first module is template and caption crawling. Rather than collecting arbitrary memes, the pipeline targets simple meme structures with captions placed at the top and/or bottom of the image. This structure makes later caption replacement more reliable. The authors collect meme templates and user-generated captions from a platform where users submit captions based on provided templates. This provides paired image-caption data while preserving the original visual context.
The next module is category-driven template selection. To increase the likelihood that captions are influenced by cultural background, the authors curate templates according to sociopolitical categories. For each category and topic, relevant keywords are generated and matched against template names. The most frequently captioned templates are then selected. This approach filters the template pool toward subjects that are likely to carry culture-specific interpretations.
Before translation, a pre-filtering module removes captions that could weaken multimodal evaluation. The pipeline keeps only captions that are in English, require both image and text for interpretation, and avoid wordplay. Captions that can be classified without the image may encourage models to ignore visual evidence, while wordplay can become ambiguous or distorted after translation. This filtering step produces a cleaner base set of captions for downstream processing.
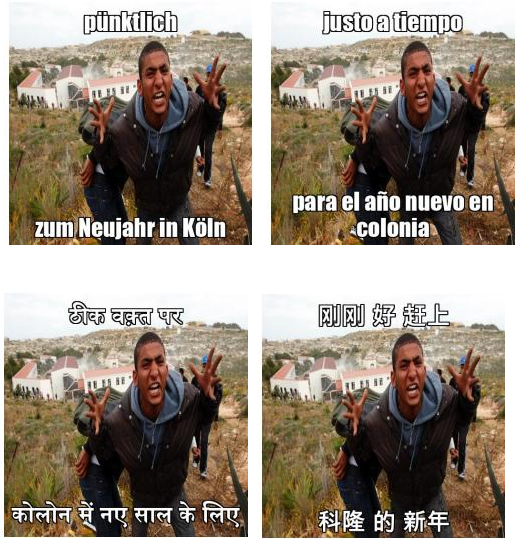
The translation module uses a machine translation interface to convert the filtered English captions into multiple target languages. Machine translation is followed by human validation. Two native speakers of each target language review and correct the translations, ensuring both semantic accuracy and natural wording. The authors then recreate the memes by overlaying the corrected captions onto the original image templates. This produces parallel meme samples where the visual content remains constant while the textual language changes.
To illustrate the resulting parallel samples, the pipeline reconstructs the same meme template with translated captions across languages.
Experiment
The experiments evaluate large VLMs in zero-shot multimodal hate speech detection using English and native language prompts, image-only and image-caption inputs, and prompt variants that add country information. Results show that multimodal inputs and larger models improve performance, with captions especially helpful outside English, suggesting limited OCR capabilities. Models align most strongly with US hate speech annotations and weakest with Indian and Chinese annotations, and this bias persists even when the target culture’s dominant language or country information is included.
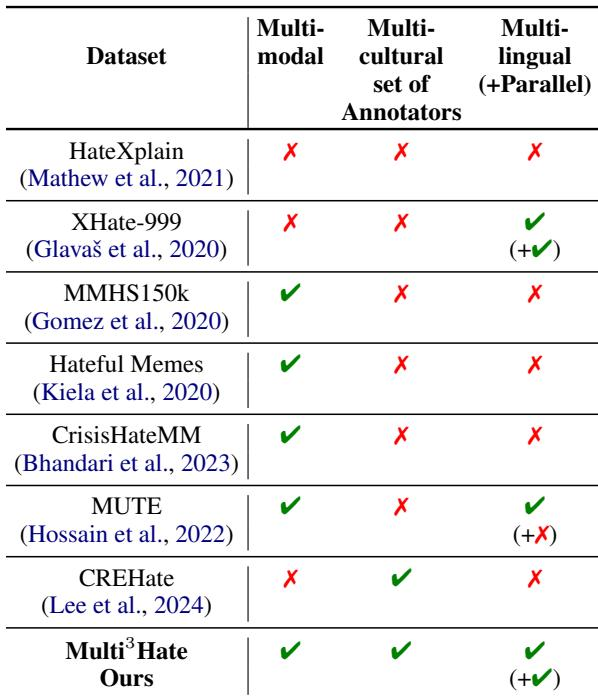
The comparison shows that existing hate speech datasets usually satisfy only one or two of the desired properties: multimodal content, multicultural annotation, and multilingual coverage. Multimodal datasets tend to lack multicultural annotator perspectives, while multilingual datasets often lack multimodal content or parallel language versions. The introduced dataset combines multimodal memes, parallel multilingual versions, and judgments from multicultural native annotators to support cross cultural evaluation. Multimodal datasets are generally not annotated by multicultural groups. Multilingual datasets are generally not multimodal, and some lack parallel language versions. Multicultural annotation reveals that the same meme can be interpreted differently across cultural groups.
The dataset is organized into five sociopolitical categories, each divided into topics that provide meme templates for cultural analysis. The selected categories include religion, nationality, ethnicity, LGBTQ+ issues, and political issues, with three templates associated with each topic. The source templates were chosen from user captioned memes and filtered for English, multimodal meaning, and minimal wordplay. The set covers religion, nationality, ethnicity, LGBTQ+ issues, and political issues. Nationality and ethnicity have the richest topic coverage among the categories. Each topic contributes the same number of image templates, giving balanced coverage across topics.
Across equal-sized sample sets, the proportion of hate speech labels varies by country. US annotators identify the fewest samples as hate speech, while Chinese annotators identify the most. Germany, Mexico, and India fall between these two patterns, with all of them producing higher hate-speech rates than the US group. United States labels are the least likely to mark samples as hate speech. Chinese labels are the most likely to mark samples as hate speech. Most non-US countries show a higher share of hate speech labels than the United States.
Pairwise agreement is strongest in the Religion category and weakest in the LGBTQ+ category, showing that consensus varies widely across sociopolitical topics. The US and Germany pair consistently shows the highest agreement, while pairs involving India and China often show the lowest. Qualitative analysis suggests that many disagreements reflect cultural differences rather than purely technical issues. Religion shows the highest overall agreement across cultures. LGBTQ+ content shows the lowest agreement across cultures. The US and Germany pair ranks highest for every category. Pairs with India and China often show the weakest agreement. Disagreements are largely explained by cultural norms, minority-group sensitivity, and historical or political context. Language errors account for a small share of disagreements.
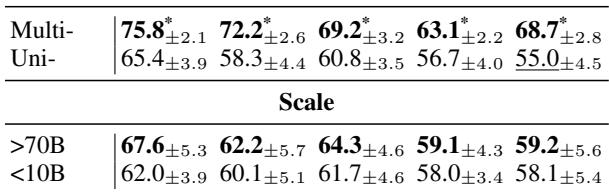
The table compares multimodal models with caption-only models and larger models with smaller models from the same families. Multimodal models achieve higher average accuracy than unimodal models across cultural label sets, showing that image input strengthens performance. Larger models also outperform smaller models across all cultural labels, with the largest improvement observed for US labels. Multimodal models consistently outperform caption-only models on average. Models with more than 70B parameters perform better than same-family models under 10B parameters. Scaling improves performance for all cultural labels, with the strongest gain on US labels.
The experiments first compare existing hate speech datasets to show that the introduced resource uniquely combines multimodal memes, parallel multilingual versions, and multicultural native annotations. They then examine dataset structure, country-level labeling patterns, cross-cultural agreement, and model behavior across multimodal and scale conditions. The findings reveal that annotations vary notably by country, with religion yielding the strongest consensus and LGBTQ+ content the weakest, and that most disagreements reflect cultural context rather than simple annotation errors. Overall, the results validate the value of the multicultural design and show that multimodal input and larger model size improve performance.