Command Palette
Search for a command to run...
学習 vs 検索: 大規模言語モデルによる回帰におけるコンテキスト内例文の役割
学習 vs 検索: 大規模言語モデルによる回帰におけるコンテキスト内例文の役割
Aliakbar Nafar Kristen Brent Venable Parisa Kordjamshidi
概要
生成型大規模言語モデル(LLMs)は、コンテキスト内学習者として機能する能力を有する。しかしながら、コンテキスト内学習(ICL)の根底にあるメカニズムは依然として主要な研究課題であり、モデルがICLをどのように活用しているかに関する実験的研究結果は一貫していない。本研究では、回帰タスクに焦点を当てることで、ICLメカニズムが内部知識の検索とコンテキスト内例文からの学習の組み合わせであると主張し、これを評価するためのフレームワークを提案する。まず、LLMが現実世界の回帰問題を解くことができることを示し、次に、LLMがどの程度内部知識を検索し、どの程度コンテキスト内例文から学習しているかを測定するための実験を設計する。この過程はこれら二つの極間のスペクトラム上に位置すると論じる。タスクに関する事前知識や、コンテキスト内例文が提供する情報の種類や豊かさなど、様々な要因に応じてこれらのメカニズムがどの程度作動するかについて、詳細な分析を提供する。本研究の知見の頑健性を裏付けるために、3つのLLMを採用し、複数のデータセットを用いる。本研究の結果は、対象とする問題に応じて、コンテキスト内例文からのメタ学習を活用し、知識の検索を促進するためにプロンプトをどのように設計すべきかについての洞察を提供する。
One-sentence Summary
Researchers at Michigan State University, the Florida Institute for Human and Machine Cognition, and the University of West Florida propose a framework for evaluating in-context learning mechanisms in LLMs, demonstrating that ICL operates on a spectrum between retrieving internal knowledge and learning from in-context examples, and offering guidance on engineering prompts to leverage either meta-learning or knowledge retrieval for regression tasks.
Key Contributions
- The study demonstrates that large language models can perform regression on realistic datasets by using in-context examples to predict numerical outputs from feature-value inputs, extending prior analyses based on synthetic tasks.
- The study introduces an evaluation framework that measures in-context learning as a spectrum between internal knowledge retrieval and learning from in-context examples, with factors including the number of feature-value pairs, the number of examples, and prompting strategies.
- Experiments using three large language models and multiple datasets show that the models combine internal knowledge retrieval with in-context learning, and the study proposes prompt engineering techniques for controlling this balance in regression tasks.
Introduction
Large language models use in-context learning to adapt to tasks from examples in the prompt, often improving over zero-shot prompting, which matters because it shapes how to build flexible, reliable AI applications. Prior work mostly treats in-context learning as either meta-learning new patterns from examples or retrieving knowledge stored during pretraining, but many studies rely on narrow, synthetic, or older model settings, leaving unresolved contradictions about the role of examples, labels, and prompt design. The authors argue that in-context learning lies on a spectrum between learning and retrieval, and they support this with a regression-based evaluation framework that measures how internal knowledge, examples, features, and prompting strategies control this balance.
Dataset
-
The authors use three regression datasets selected to evaluate language-model performance across domains and task complexity.
-
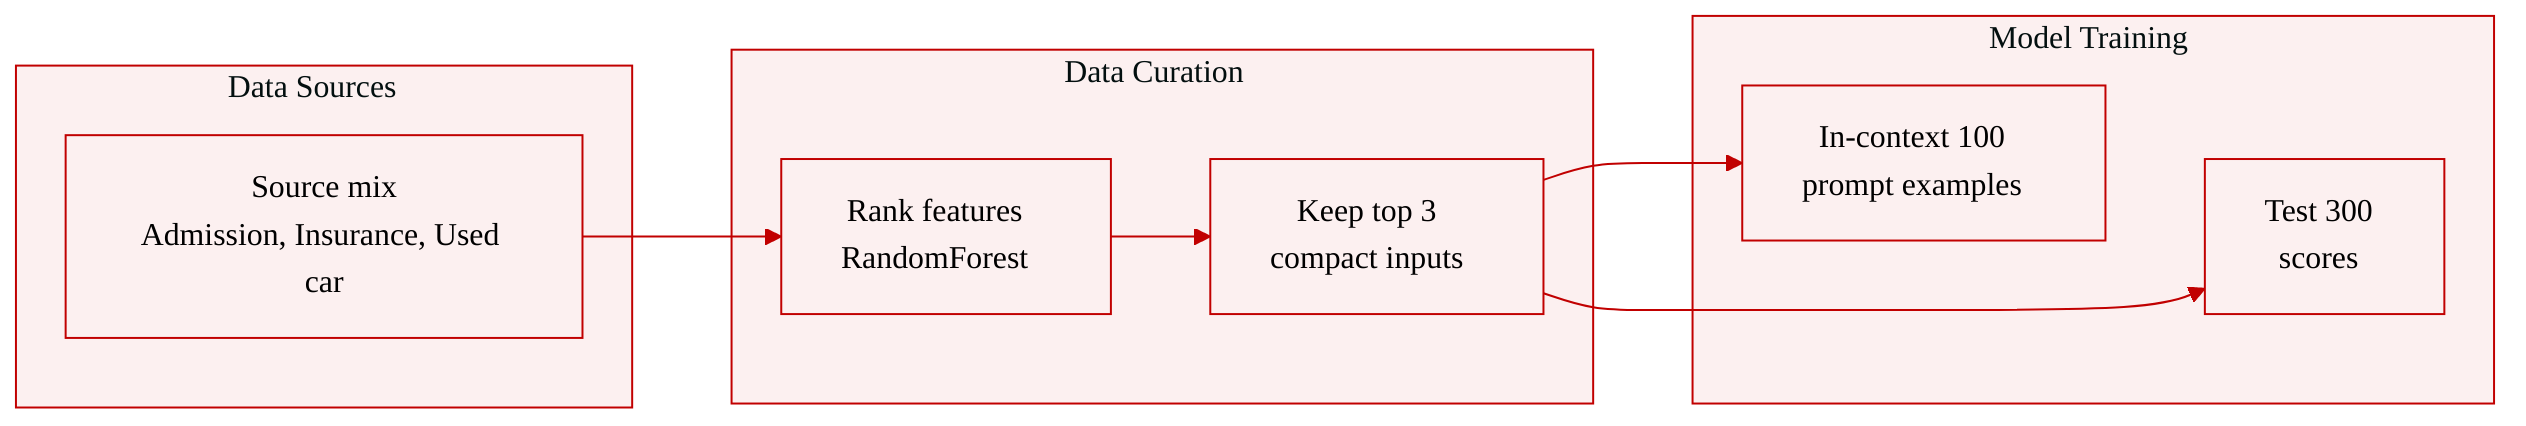
Each dataset is preprocessed to retain only its three most important features, with feature importance calculated using a RandomForest estimator.
-
Admission Chance is a graduate-school admission dataset for Indian students. The authors select three highly correlated features and use this dataset because it is less likely to appear in USA-centric LLM training data.
-
Insurance Cost focuses on predicting annual individual medical costs billed by U.S. health insurance companies, with demographic statistics compiled from the U.S. Census Bureau. The first feature is by far the most important.
-
Used Car Prices estimates the 2019 price of a used Toyota or Maserati. The first two features are the most impactful for this task.
-
For each dataset, the authors construct two splits: an in-context subset of 100 instances and a test subset of 300 instances.
-
The processing emphasizes compact, feature-focused inputs by filtering each dataset down to its strongest predictive features before evaluation.
Method
The proposed method treats tabular regression as a language-model prediction task. Given a dataset
D={(xi,yi)}i=1n,each sample contains an input vector xi and a numerical target yi. The input xi is represented as a collection of feature value pairs (fij,vij), where fij denotes the feature name and vij denotes its numerical value. For example, the feature name can be a semantic attribute such as fuel economy, mileage, or vehicle class, and the corresponding value is the numeric observation for that sample. The target yi is the numeric output to be predicted.
The core pipeline presents the large language model with a prompt constructed from in-context examples. Specifically, the authors select a subset of m examples from the in-context split of the dataset,
{(x1,y1),(x2,y2),…,(xm,ym)},and then query the model with the feature pairs of a test sample x. The model is expected to return a scalar estimate of the corresponding target value. When m=0, the setting becomes a zero-shot prompting setting, where no regression examples are supplied in the context.
The prompt is composed of three main components: a task instruction, a set of in-context examples, and a final query. The task instruction defines the regression objective and constrains the output format. In particular, the model is asked to estimate the target value using only a number, without generating explanations or intermediate reasoning text. The in-context examples provide supervised input output demonstrations, while the query contains the feature values of the sample for which the model must produce a prediction.
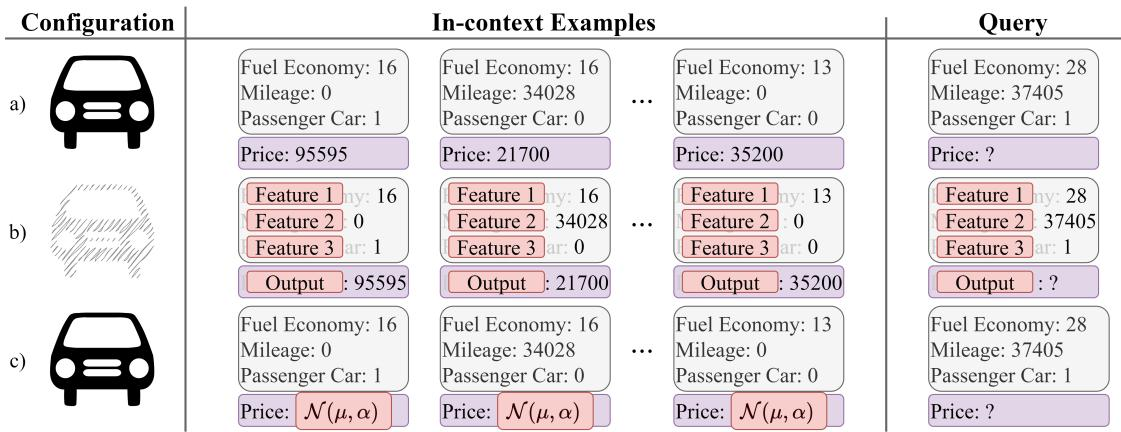
The key methodological module is the set of prompt configurations used to probe whether the model is exploiting feature semantics, learning from in-context patterns, or merely fitting the provided numerical distribution. Refer to the framework diagram.
In the named feature configuration, the prompt exposes the real feature names and the real name of the target variable. For example, the model may be asked to estimate a used car price from features such as city fuel economy, mileage, and vehicle classification. The in-context examples include the same semantic feature names and their corresponding target values. This configuration allows the model to combine its pretrained domain knowledge with the observed feature output relationships.
In the anonymized feature configuration, the semantic feature names and the target name are removed from the prompt and replaced with generic labels such as Feature 1, Feature 2, and Output. The input values are kept unchanged, but the model no longer has access to meaningful feature descriptions. As a result, the model cannot directly rely on domain knowledge associated with the original variables. It must instead infer the mapping from the numerical feature values to the output values using only the in-context examples.
In the randomized ground truth configuration, the named features are retained, but the true target values in the in-context examples are replaced with random numerical values. These values are generated from a Gaussian distribution based on the dataset statistics, independent of the original feature value relationship. This configuration functions as a control condition. If the model still achieves strong performance under this setting, it suggests that the improvement may not come from genuinely learning the regression relationship in the examples. Instead, the model may be influenced by the presence of examples, prompt structure, or distributional priors unrelated to the true input output function.
A direct question answering baseline is also used to establish a reference point for numerical generation without in-context regression examples. In this setup, the model receives the named features of the test sample and is asked to estimate the target directly. To reduce the search space for numeric generation, the instruction includes dataset-level statistics such as the mean and standard deviation of the target variable. This baseline helps distinguish the effect of raw numerical prior knowledge from the effect of in-context learning.
Experiment
The experiments compare strong LLMs with Ridge and RandomForest regression on three datasets while varying prompt format, number of in-context examples, and feature count to isolate how LLMs combine knowledge retrieval and learning from examples. Direct question answering shows limited feature use when task knowledge is weak, whereas named-feature prompts improve performance by invoking internal knowledge and can outperform traditional models in low-example settings. Randomizing example labels or anonymizing features shifts behavior toward example-based learning, while more features mainly strengthen knowledge retrieval and can expose numerical data contamination, suggesting that effective prompt design should balance informative features, example quantity, and example order.