Command Palette
Search for a command to run...
人手評価ガイドラインにおける脆弱性の定義と検出:信頼できるNLG評価に向けた予備的研究
人手評価ガイドラインにおける脆弱性の定義と検出:信頼できるNLG評価に向けた予備的研究
Jie Ruan Wenqing Wang Xiaojun Wan
概要
人手評価は、自然言語生成(NLG)システムの品質を評価する際のゴールドスタンダードとして機能している。しかし、信頼性が高く再現可能な人手評価を保証する上での鍵となる要素である評価ガイドラインには、限られた注意しか払われてこなかった。本研究の調査により、主要国際会議で人手評価を伴う最近の論文のうち評価ガイドラインを公開しているのは29.84%に過ぎず、これらのガイドラインの77.09%に脆弱性が存在することが明らかになった。信頼性の低い評価ガイドラインは不正確な評価結果をもたらし、NLG分野の正しい方向への発展を妨げる可能性がある。これらの課題に対処するため、信頼できる評価ガイドラインに向けた第一歩として、既存の論文から抽出したガイドラインおよび大規模言語モデル(LLM)により生成したガイドラインに対する注釈付きデータセットを初めて構築した。さらに、8種類の脆弱性の分類体系を提案し、評価ガイドラインの作成原則を定式化した。加えて、LLMを用いたガイドライン脆弱性の検出手法を検討し、人手評価の信頼性を向上させるための提言集を提供する。注釈付きの人手評価ガイドラインデータセットおよび脆弱性検出手法のコードは公開されている。
One-sentence Summary
Peking University researchers introduce the first human evaluation guideline dataset, including a taxonomy of eight vulnerabilities and an LLM-based detection method, revealing that 77.09% of existing NLG evaluation guidelines are vulnerable in order to enhance the reliability of human evaluation for NLG systems.
Key Contributions
- The paper releases the first annotated human evaluation guideline dataset, built from guideline excerpts extracted from published papers and examples generated by large language models, and makes the dataset and vulnerability-detection code publicly available.
- A taxonomy of eight guideline vulnerabilities and a principle for composing reliable evaluation guidelines are introduced to define concrete flaws and guide robust guideline construction.
- An LLM-based detection method is explored using few-shot prompting and chain-of-thought reasoning, with recommendations for using the detector to assess guideline reliability before conducting human evaluations.
Introduction
Natural Language Generation often relies on human evaluation because automated metrics can correlate poorly with human judgments, making clear evaluation guidelines essential for reliable and reproducible assessment. Prior work treats human evaluation as a gold standard but rarely examines or releases the guidelines used by annotators, and existing vulnerability detection work does not address flaws in these evaluation instructions. The authors analyze papers from major NLP conferences and find that few evaluation guidelines are released, while many released guidelines contain vulnerabilities such as ambiguity, bias, unclear ratings, and inflexible instructions. Their main contribution is a taxonomy of eight guideline vulnerability types, the first annotated dataset of human evaluation guidelines, and an LLM based method using chain of thought prompting to detect guideline weaknesses and support more reliable evaluation practices.
Dataset
-
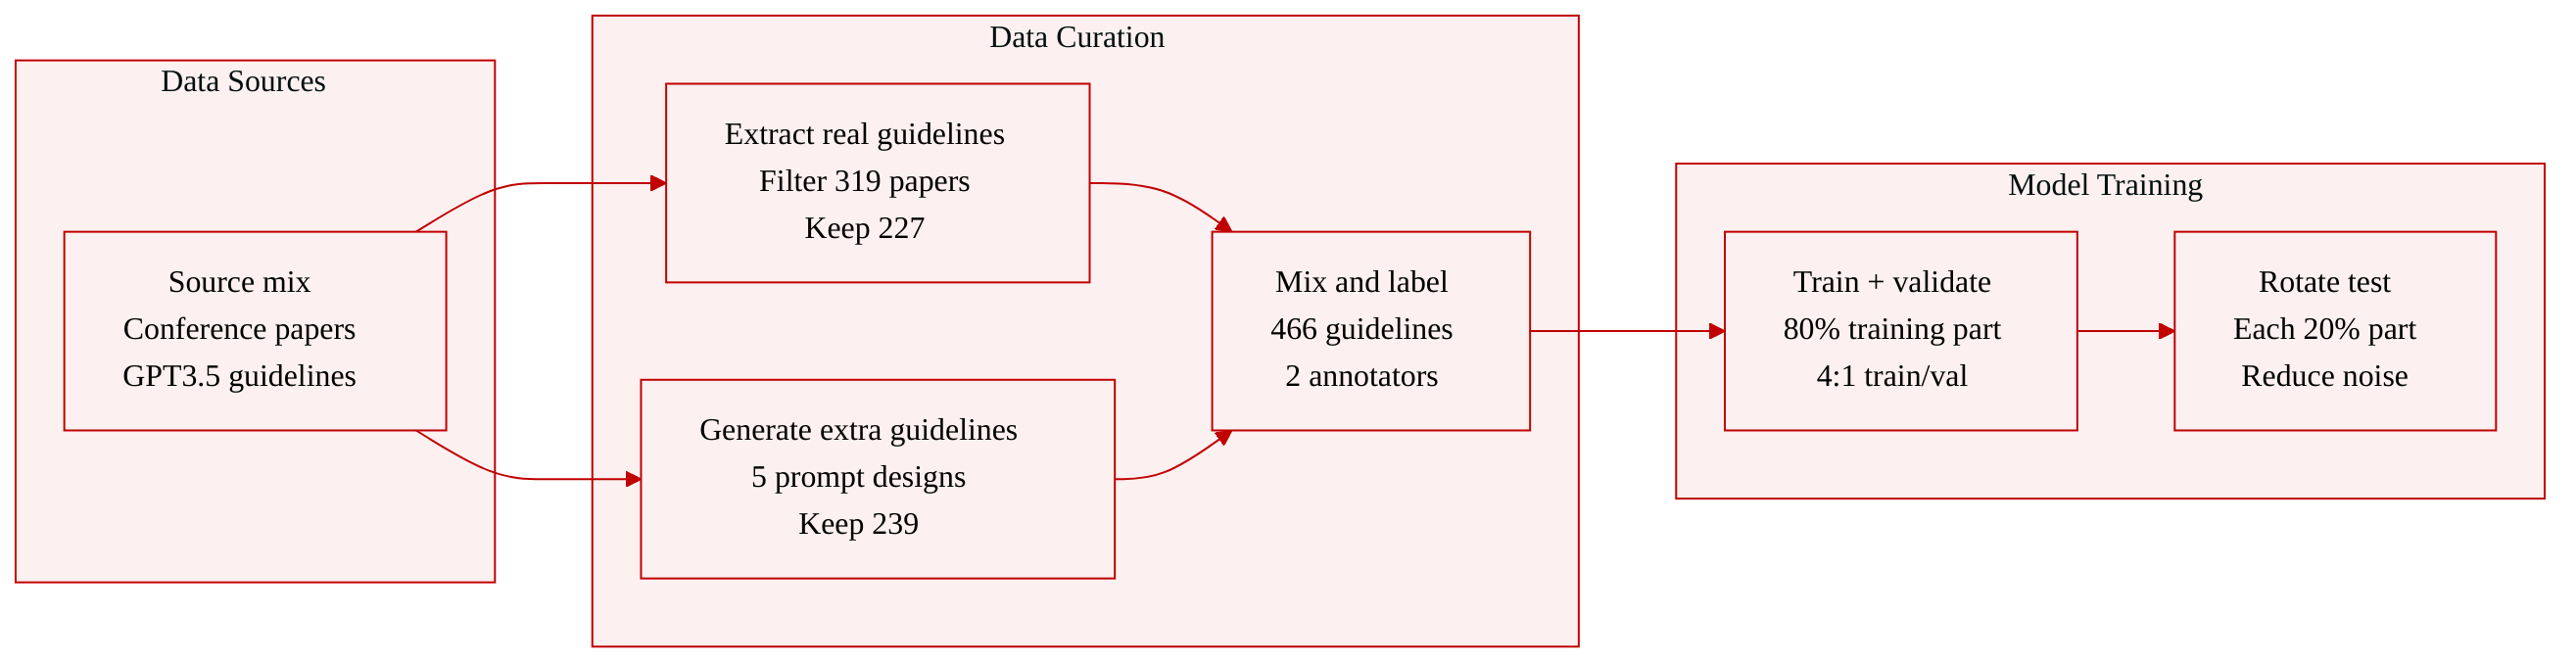
The authors construct the dataset because no existing resource directly evaluates human evaluation guidelines. The dataset combines authentic guidelines extracted from published papers and synthetic guidelines generated by GPT3.5 Turbo.
-
Authentic subset: papers are crawled from ACL, EMNLP, and NAACL from 2020 to 2022, yielding 3,233 raw papers. Keyword filtering uses terms such as human evaluation, manual assessment, guideline, instruction, questionnaire, interface, and screenshot to isolate 677 evaluation related papers and narrow the candidate paper set to 319. After manual filtering for NLG tasks, the authors extract 227 guidelines: 111 from ACL, 62 from EMNLP, and 54 from NAACL. Guidelines originally shown as figures or charts are converted into textual form.
-
Synthetic subset: the authors use five prompt designs for GPT3.5 Turbo, including raw prompts, raw prompts with evaluation aspects, structured prompts, structured prompts with evaluation aspects, and structured prompts with evaluation aspects and constraints. Each prompt covers 12 NLG tasks, 2 evaluation settings, and alternating keywords instruction and guideline, producing 48 guidelines per prompt. The final synthetic set contains 239 generated guidelines.
-
Final composition: the dataset contains 466 human evaluation guidelines in total, with 227 authentic guidelines and 239 synthetic guidelines. The average length is 247.64 words for authentic guidelines and 237.05 words for synthetic guidelines.
-
Schema and metadata: each sample is a guideline text associated with source information, such as authentic or synthetic origin, and annotation labels. Synthetic guidelines can also be traced to prompt type, NLG task, evaluation setting, and keyword choice. The dataset is annotated against eight vulnerability types: ethical issues, unconscious bias, ambiguous definition, unclear rating, edge cases, prior knowledge, inflexible instructions, and others. A None label is assigned when no vulnerability is present.
-
Annotation process: four qualified English proficient annotators label the guidelines. Authentic and synthetic guidelines are randomly mixed in the annotation interface to reduce source bias. Each guideline is annotated by two annotators, and a third annotator resolves disagreements. The dataset underwent batch assignment, daily review, and reannotation when daily accuracy was below 80 percent. Cohen kappa agreement between annotators is 0.722 for authentic guidelines and 0.737 for synthetic guidelines.
-
Processing details: no cropping strategy is reported. Main processing steps include keyword filtering, manual filtering of relevant NLG papers, guideline extraction, conversion of visual guideline elements into text, synthetic expansion through prompt templates, and annotation quality control.
-
Dataset usage: the authors divide the full dataset into five parts, with four parts used for training, 80 percent, and one part used for testing, 20 percent. The training portion is further split into train and validation sets in a 4 to 1 ratio. Each of the five parts is then used as a test set in turn while the remaining parts are used for training, so the full dataset contributes to evaluation and performance variance is reduced.
Method
The synthetic guideline generation module treats guideline construction as a prompt controlled generation workflow. Rather than relying on manually written rules, the authors leverage GPT-3.5-Turbo and design five prompt templates that progressively increase the degree of instruction, structure, evaluation conditioning, and constraint specification. The templates include a raw prompt, a raw prompt with evaluation aspects, a structured prompt, a structured prompt with evaluation aspects, and a structured prompt with both evaluation aspects and constraints. This design allows the generated guidelines to cover different levels of explicitness and formality, which can improve diversity in the resulting synthetic dataset.
The generation process combines prompt template control with combinatorial task expansion. For each prompt template, the authors instantiate different natural language generation tasks and evaluation settings, while alternating between the keywords “instruction” and “guideline.” The combination of 12 NLG tasks, 2 evaluation settings, and 2 keyword variants produces a fixed number of guidelines for each prompt template:
Nper prompt=12×2×2=48Across the five prompt templates, this workflow yields a broad synthetic guideline collection in which each guideline is shaped by a specific combination of task domain, evaluation perspective, prompt structure, and keyword phrasing. The use of evaluation aspects introduces assessment-oriented context, while the structured and constrained templates push the language model toward more organized and rule-like outputs. This modular prompt-based generation design makes it possible to systematically expand the raw guideline dataset while controlling both diversity and formatting consistency.
Experiment
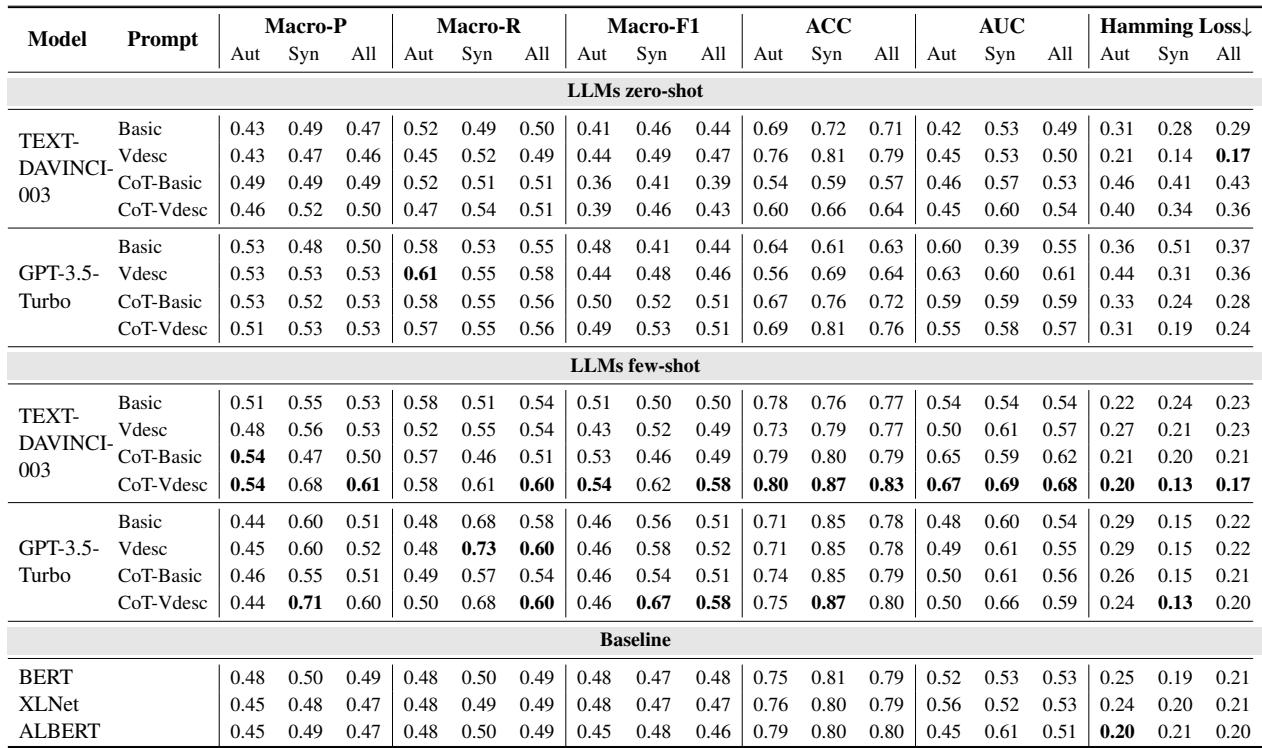
The experiments treat guideline vulnerability detection as a multi-label classification task, comparing open and closed source LLMs, Transformer baselines, and zero shot and few shot prompting strategies across rotated training and testing splits. Case studies show that closed source models can provide useful reasoning, whereas open source models often produce invalid outputs, and the quantitative analysis confirms that few shot examples and Chain-of-Thought prompting generally improve detection. Overall, Text Davinci 003 with the CoT VDesc strategy is validated as the most effective setup, while results also show that synthetic guidelines are easier to audit than authentic ones and that model performance still varies across vulnerability types.
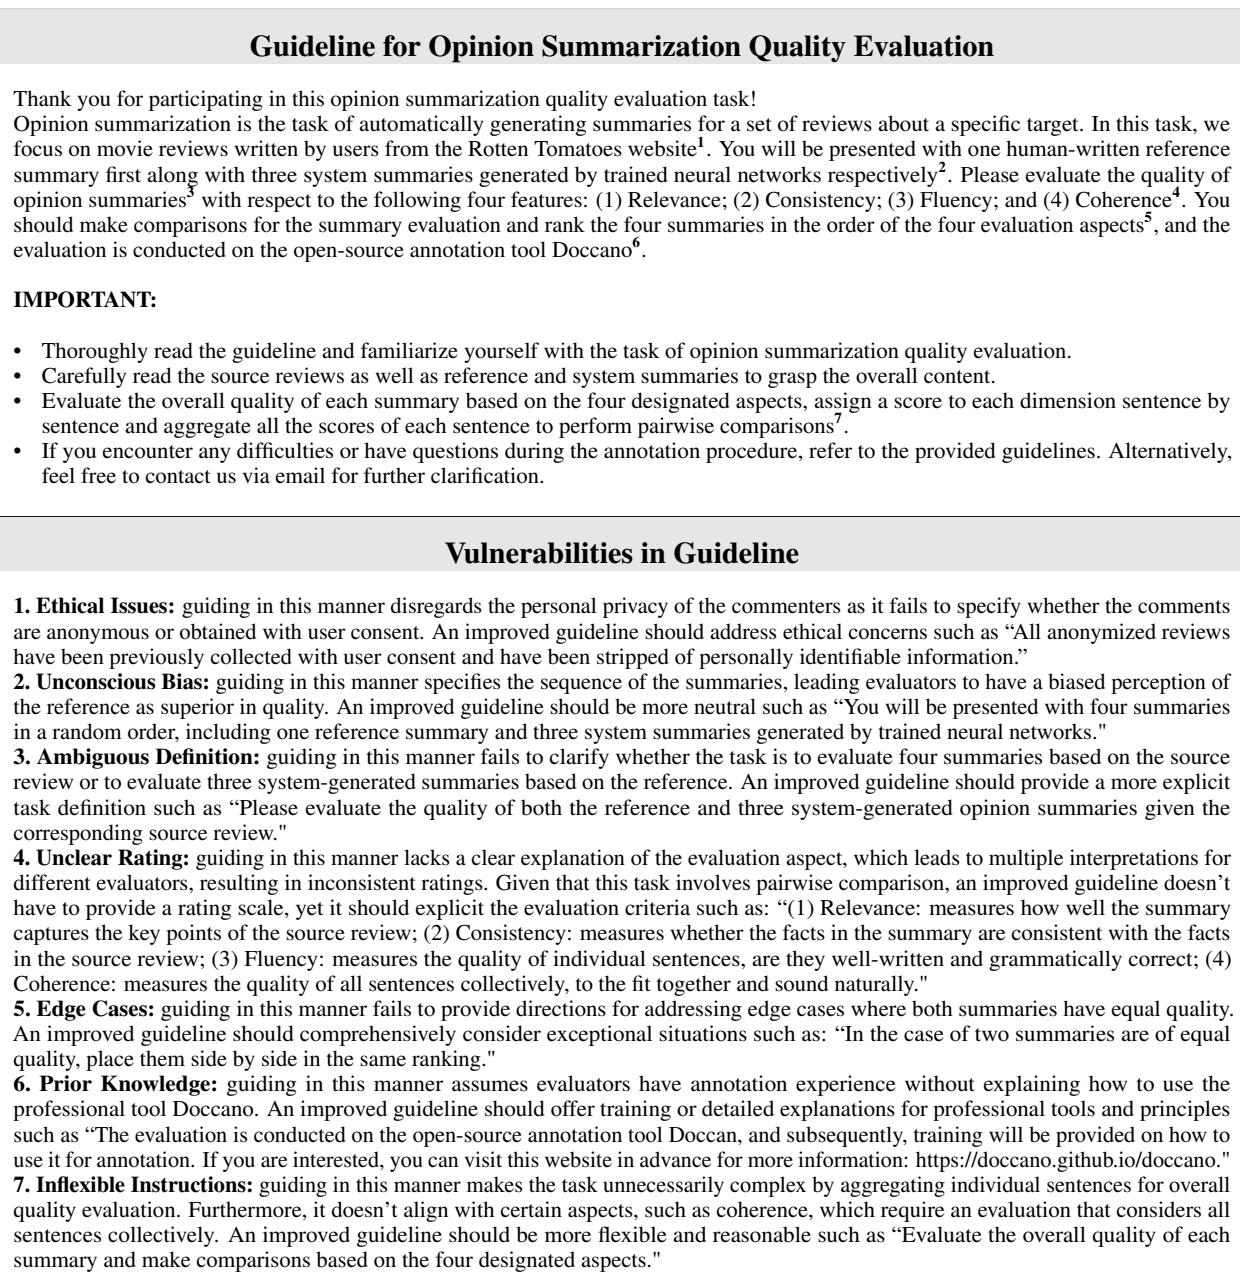
This illustration presents a taxonomy of guideline vulnerabilities in human evaluation instructions. It pairs a sample opinion summarization evaluation guideline with vulnerability diagnoses and suggested revisions for issues such as ethical oversight, ordering bias, unclear definitions, vague criteria, missing tie handling, insufficient tool instructions, and overly rigid procedures. The examples show that clearer, more neutral, and more explicit guidelines can reduce annotation ambiguity and bias. Sample vulnerabilities include privacy concerns, biased presentation order, ambiguous task scope, unclear rating definitions, missing edge-case guidance, assumed annotation tool knowledge, and inflexible aggregation of sentence scores. Each vulnerability is paired with a recommended revision that specifies consent and anonymization, random ordering, explicit task scope, concrete evaluation criteria, tie handling, tool training, and more flexible overall-quality comparison.
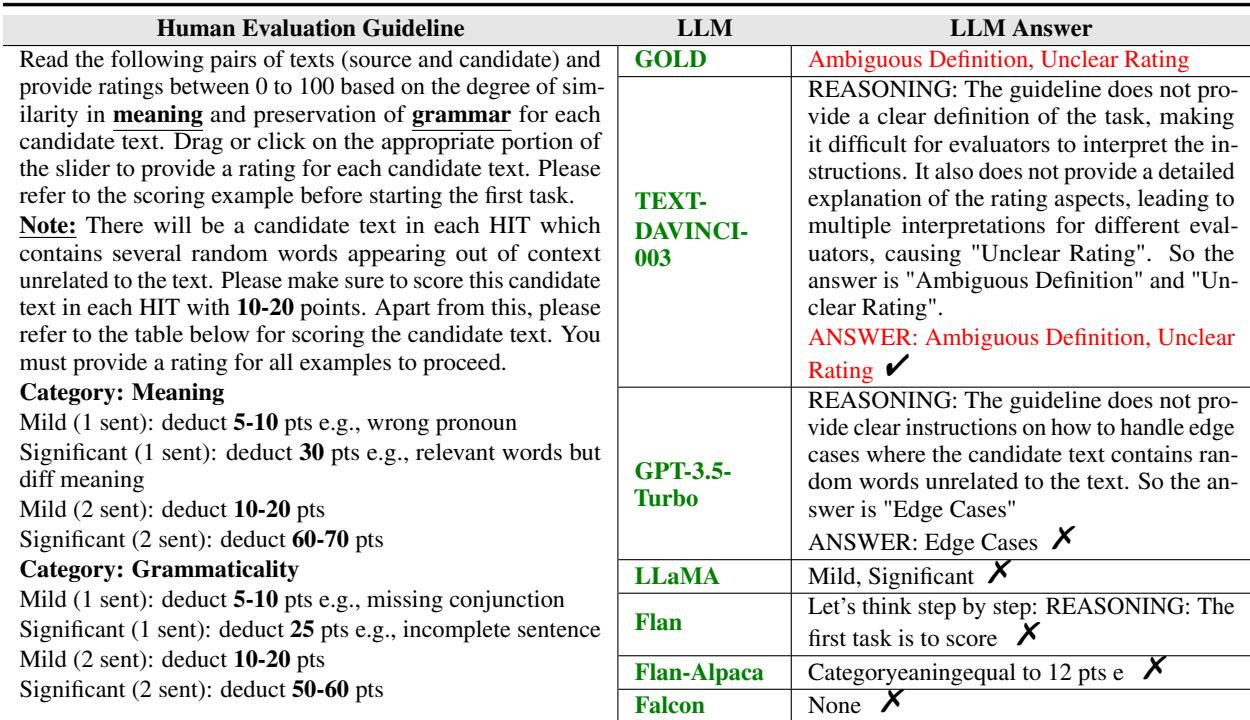
In the few-shot CoT example, TEXT-DAVINCI-003 correctly identifies Ambiguous Definition and Unclear Rating for the human evaluation guideline. Its reasoning also narrows the scope of the vulnerabilities, making them easier to correct. GPT-3.5-Turbo instead returns Edge Cases despite the guideline already describing how to handle unrelated random words, and the open-source models fail to produce valid vulnerability answers. TEXT-DAVINCI-003 produces the correct vulnerability types with usable reasoning GPT-3.5-Turbo misclassifies the guideline as having Edge Cases, while open-source models output unstructured or empty responses
LLMs generally outperform pretrained baselines for guideline vulnerability detection, especially when using few-shot prompting and chain-of-thought strategies. TEXT-DAVINCI-003 with the CoT-Vdesc strategy is the strongest overall setup, while GPT-3.5-Turbo performs comparably and some pretrained models remain competitive in zero-shot settings without chain-of-thought. Models tend to detect synthetic guidelines more effectively than authentic guidelines, and recall is usually higher than precision, indicating a bias toward labeling guidelines as non-vulnerable. TEXT-DAVINCI-003 with CoT-Vdesc few-shot prompting gives the best overall detection performance. LLM-based models consistently beat pretrained baselines across most prompt strategies. Synthetic guidelines are detected more easily than authentic guidelines. Recall usually exceeds precision, showing a tendency to miss vulnerabilities by predicting no vulnerability.
The experiments evaluate a taxonomy of vulnerabilities in human evaluation guidelines, using guideline examples, qualitative revisions, and prompt-based detection tests. They show that more explicit, neutral, and structured instructions can reduce ambiguity and bias, while well prompted large language models, especially with few-shot chain of thought, are generally more effective than pretrained baselines at identifying vulnerability types. However, detection remains imperfect, with authentic guidelines more challenging than synthetic ones and tendencies toward imbalanced or conservative vulnerability judgments.