Command Palette
Search for a command to run...
MKA:エンドツーエンドの専門的タスクにおけるマルチモーダル知識エージェントの評価
MKA:エンドツーエンドの専門的タスクにおけるマルチモーダル知識エージェントの評価
概要
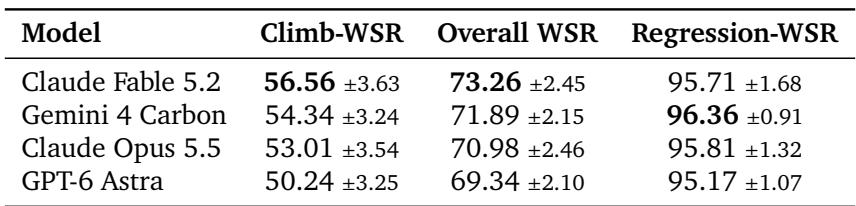
本稿では、視覚的理解に依存するエンドツーエンドの専門的知識作業を自律エージェントがどの程度遂行できるかを測定する、Multimodal Knowledge Agent(MKA)ベンチマークを導入する。各タスクでは、CAD設計図、電子回路図、X線画像、複雑なチャート、地理空間地図など、視覚的に情報密度の高い複数のファイルから情報を抽出・統合し、.xlsx、.pptx、.pdf、.docx、.html、.pngのいずれかの形式で独立した成果物を作成することが求められる。既存のベンチマークではこの能力はほとんど検証されていない。画像閲覧ツールを除去してもGDPval(Patwardhan et al., 2025)におけるGemini 4 Carbonのスコアは変化せず(4.3節)、GDP.pdf(Garre et al., 2026)やGDP.xlsx(Surge AI, 2026)のような単一形式の評価では、ファイルやモダリティを横断した推論は要求されない。MKAは10の経済セクターにわたる200のタスクで構成される。成果物は、専門家による重み付きルーブリックに基づき、サンドボックス化されたエージェント型自動評価器によって採点される。この自動評価器は、専門家による評価実験において基準判定の96.2%で人間のドメイン専門家と一致し(Cohenのκ = 0.91)、重み付き満足率(WSR)により全体スコアと、前世代モデルでは未飽和の先端基準(Climb-WSR)のスコアを算出する。評価した先端モデル(Gemini 4 Carbon、Claude Fable 5.2、Claude Opus 5.5、GPT-6 Astra)の中で、Claude Fable 5.2(Climb-WSR 56.6%、全体WSR 73.3%)とGemini 4 Carbon(Climb-WSR 54.3%、全体WSR 71.9%)が最高スコアを達成したが、Carbonのトークン使用量は5.7分の1であった。最も強力なモデルでもClimb-WSRは57%未満にとどまり、マルチモーダルエージェントには依然として大きな改善余地が残されている。
One-sentence Summary
Google DeepMind and Artificial Analysis introduce the Multimodal Knowledge Agent (MKA) benchmark, a 200-task, 10-sector evaluation of autonomous agents performing end-to-end professional knowledge work that requires extracting and integrating information from visually dense files and producing standalone deliverables; unlike prior benchmarks, it uses an expert-aligned sandboxed autorater that agrees with human domain experts on 96.2% of criterion judgments (Cohen’s κ=0.91), and the strongest evaluated models, Claude Fable 5.2 and Gemini 4 Carbon, reach only 56.6% and 54.3% Climb-WSR, respectively.
Key Contributions
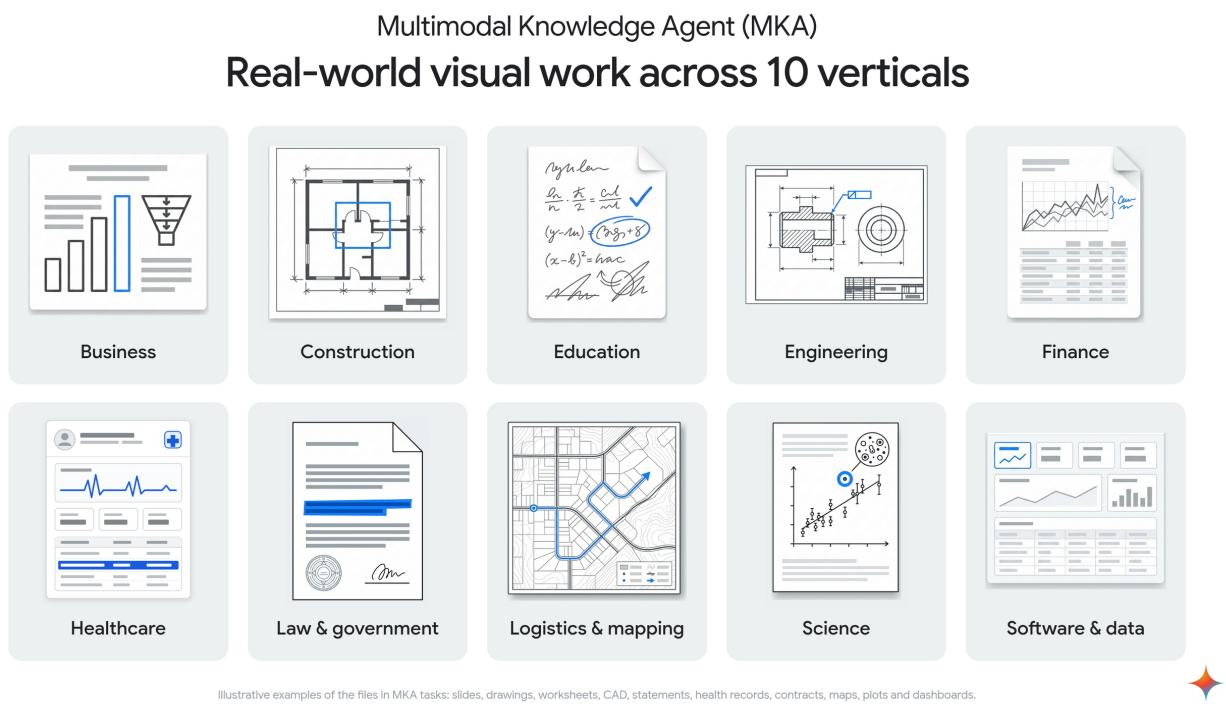
- The paper introduces the Multimodal Knowledge Agent (MKA) benchmark, a 200-task evaluation across 10 sectors where agents must combine information from multiple visually dense files, such as CAD blueprints, electronics schematics, radiographs, complex charts, and geospatial maps, and produce standalone deliverables in .xlsx, .pptx, .pdf, .docx, .html, or .png format.
- It contributes a sandboxed agentic autorater that grades deliverables against expert-weighted rubrics, reports overall weighted satisfaction rate and Climb-WSR on criteria unsaturated by prior-generation models, and agrees with human domain experts on 96.2% of criterion judgments (Cohen's kappa = 0.91).
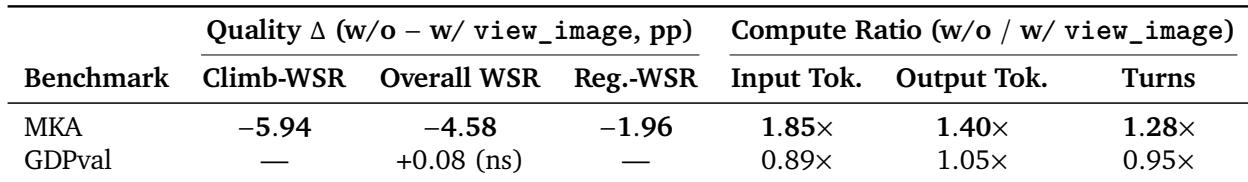
- The benchmark evaluation shows that Claude Fable 5.2 (56.6% Climb-WSR, 73.3% Overall WSR) and Gemini 4 Carbon (54.3% Climb-WSR, 71.9% Overall WSR) achieve the highest scores among evaluated frontier models, with Gemini 4 Carbon using 5.7x fewer tokens. It also finds that removing visual tools degrades Climb-WSR while increasing turns (1.28x) and output tokens (1.40x), and that top Climb-WSR remains below 57%, leaving substantial headroom for multimodal agents.
Introduction
Real-world knowledge work is deeply visual, requiring professionals to interpret diagrams, schematics, charts, and scanned documents while verifying the layout of files they produce. Yet frontier agents show a text-and-code bias: they convert files to plain text or Markdown, depend on brittle OCR or computer-vision scripts, and still suffer from geometric blindness and text-prior bias when viewing images directly. Existing benchmarks miss this because workplace suites often allow task-critical signal to be extracted via scripts, while visual QA, spreadsheet, browsing, and GUI benchmarks limit multimodal reasoning to single-turn answers, tabular data, short strings, or pixel-level clicking. To address this, the authors introduce MKA, a 200-task benchmark spanning 10 sectors and 83 occupations with heterogeneous visual artifacts such as floor plans, schematics, route maps, and radiographs, where 88% of tasks require standalone file deliverables; they pair it with a sandboxed Agentic Autorater that visually renders and programmatically inspects outputs, and show that vision is load-bearing for both deliverable quality and compute efficiency, with top models still leaving substantial headroom.
Dataset
Dataset composition and sources
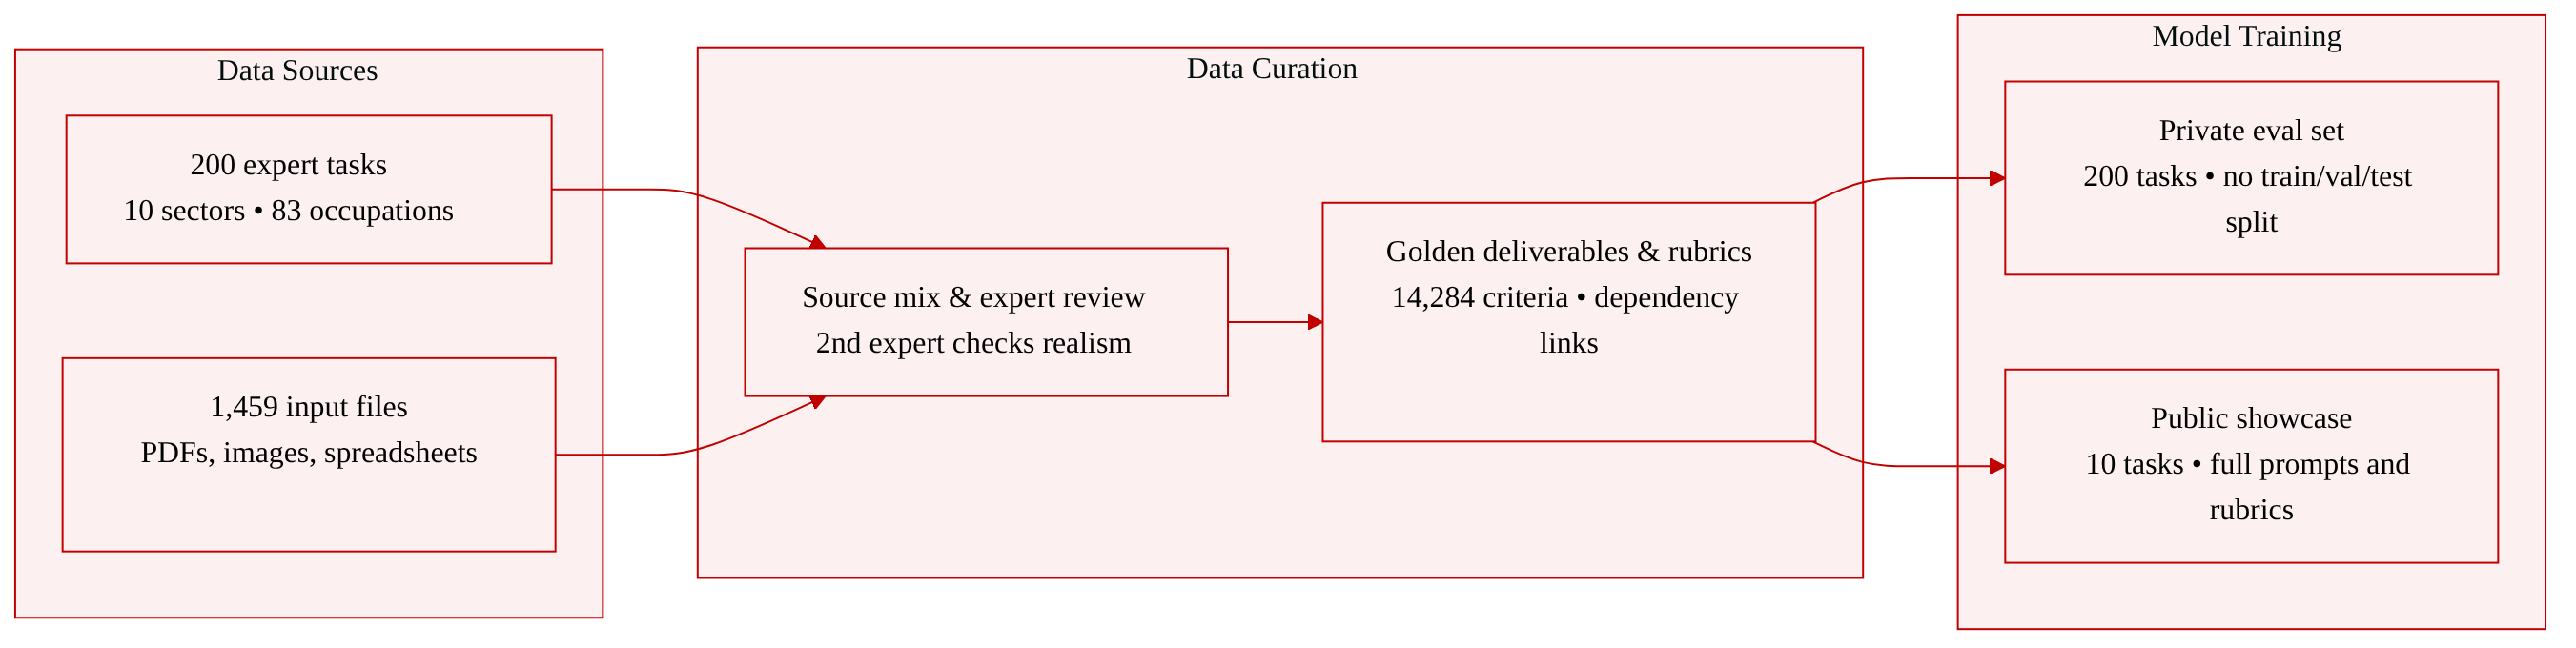
- MKA contains 200 real-world tasks written and verified by vetted domain professionals.
- The tasks are evenly split across 10 sectors, with 20 tasks per sector, and cover 83 occupations such as financial analysts, architects, engineers, GIS surveyors, data scientists, attorneys, and physicians.
- Each author has at least five years of professional experience, and every task was reviewed by a second expert for realism and accuracy.
- Each task includes a single prompt specifying the user scenario, requirements, and target deliverable.
Public and private splits
- MKA, the full 200-task set, is used as a private evaluation suite.
- It is hosted and graded independently on a public leaderboard by Artificial Analysis using the open-source Stirrup framework.
- MKA-Showcase is a separate public release containing 10 tasks, one per sector, with full prompts, input files, and grading rubrics.
- The split helps prevent benchmark contamination while still supporting independent evaluation.
Input files
- Each task includes 2 to 45 input files.
- The dataset contains 1,459 input files total, with a mean of 7.30 and median of 6.0 files per task.
- Input format distribution:
- PDF documents: 43.0%, 628 files.
- Images and scans: 22.9%, 334 files.
- Spreadsheets: 10.9%, 159 files.
- Word documents: 10.2%, 149 files.
- Geospatial and text/JSON: 6.0%, 88 files.
- Slide decks: 3.5%, 51 files.
- CSV and TSV: 3.4%, 50 files.
- Examples include architectural plans, SEC Form 10-K filings, CT scans, multi-tab Excel workbooks, GIS layers, LiDAR rasters, email threads, and clinical trial tables.
Deliverables
- 176 of 200 tasks, or 88.0%, require creating or modifying a standalone file.
- The remaining 24 tasks, or 12.0%, are answered directly in the text response.
- Deliverable format distribution:
- PDF reports: 45 tasks, 22.5%.
- Word documents: 42 tasks, 21.0%.
- Presentations: 34 tasks, 17.0%.
- Spreadsheets: 32 tasks, 16.0%.
- Text reports: 30 tasks, 15.0%.
- Images and charts: 9 tasks, 4.5%.
- Web apps: 8 tasks, 4.0%.
Rubric metadata and construction details
- MKA contains 14,284 rubric criteria total.
- The mean is 71.4 criteria per task, the median is 68.5, and the range is 20 to 150.
- 91.3% of criteria evaluate the 176 standalone-file tasks, while 8.7% evaluate the 24 text-response tasks directly.
- Each criterion has an integer weight from 1 to 5.
- Each criterion is labeled as either a primary objective, 94.5%, or secondary objective, 5.5%.
- 29.5% of criteria list explicit prerequisite criteria, forming a directed acyclic graph within each task.
- 99.6% of criteria include an expert-written golden justification citing the source location of ground truth and, where applicable, its derivation.
- The excerpt does not describe image cropping or augmentation; the main processing is expert assembly of multi-file input bundles, golden deliverable creation, and rubric writing.
How the data is used
- The authors use the 200-task MKA set as a private evaluation benchmark, not as a training set.
- No training split or mixture ratios are specified in this dataset section.
- MKA-Showcase provides a smaller public sample with full prompts, inputs, and rubrics for external inspection and leaderboard use.
Method
Agentic Harness and Autorater
The evaluation procedure uses a shared agentic execution environment so that all models are assessed under identical operational constraints. The authors evaluate every model in Stirrup, an open-source, lightweight agent framework maintained by Artificial Analysis. The harness supplies the agent with the task prompt and the paths of the input files as text. The agent therefore has to inspect the files and construct the final deliverables through its own tool calls. All models use the same harness, system instructions, tool set, container image, and resource budgets, and only the model endpoint changes. This externally maintained, minimal harness avoids model-specific scaffolding and makes deliverable quality and token efficiency comparable across model families.
Agent Loop and Execution Environment
The agent loop runs without human intervention until the model calls the finish tool or reaches a limit of 250 turns. Each task has an 8-hour wall-clock limit and can use up to a 1M-token context window when the model supports it. Compaction is triggered once the model reaches 70% of its context length. If the model replies without a tool call, the harness prompts it to continue. During the final 20 turns, the harness appends a warning with the number of remaining turns so the agent can submit its deliverables before the turn limit.
Each task runs in a fresh, isolated Linux container with 4 vCPUs and 128 MB of base RAM that can dynamically burst up to 16 GB. The container is based on a Debian image with Python 3.13, and the working directory is /workspace, with input files staged under /workspace/input. The sandbox has internet access. The image includes document, PDF, OCR, and rendering tools such as LibreOffice, Tesseract, pymupdf, weasyprint, and Python Office libraries. This allows agents to parse inputs and build deliverables without additional software installation.
Stirrup exposes four tools: code_exec, view_image, web_search, and finish. The code_exec tool runs bash commands and Python scripts with a 300-second per-command timeout, while web_search issues web queries with a 180-second timeout. The view_image tool loads a raster image into the model's visual context and is designed to respect the native image resolution of the output file. To inspect a document or slide deck visually, the agent first renders pages to PNG files through code_exec using command-line tools such as LibreOffice and pdftoppm, then views the required pages with view_image. At the end of a trajectory, finish checks that every declared deliverable exists and terminates the session.
Agentic Autorater for Deliverable Grading
The authors use an agentic, multimodal judge to grade the produced files. Static text extraction omits charts and formatting, while static page renders hide cell formulas and can clip wide sheets. Because the rubrics check both visual layout and underlying file internals, the grader needs direct access to both representations.
The Agentic Autorater is also implemented as a Stirrup agent. It runs in its own fresh container and has access to code_exec, view_image, and a structured submit_verdicts finish tool, but it has no web access. Its workspace contains only the candidate's deliverable files and the final text response. The autorater does not receive the task input files, because the rubrics are self-contained: each criterion states the expected value, tolerance, or property directly. In a single session, the autorater checks the candidate outputs against the verbatim task prompt and rubric and returns, for each criterion, a pass/fail verdict, a justification, and the files it cited.
For the judge model, the authors use OpenAI GPT-6 Luna. Selecting a judge outside the Google model family avoids favoring Gemini models. The authors also note that the same-family preference hypothesis is not supported by the results, since GPT-6 Astra ranks last among the evaluated models.
Experiment
All models are evaluated in the shared Stirrup agent harness on multimodal knowledge-agent tasks, and an independent agentic autorater closely matches expert human judgments. Frontier models saturate the easier regression criteria, while harder climb criteria remain largely unsolved, with Claude Fable 5.2 and Gemini 4 Carbon leading quality and Gemini 4 Carbon achieving markedly lower token usage and cost. Ablating visual tool access has little effect on GDPval but substantially reduces MKA performance, indicating that coding-based OCR and image workarounds can partially compensate yet cannot replace genuine visual perception for complex visual inputs.
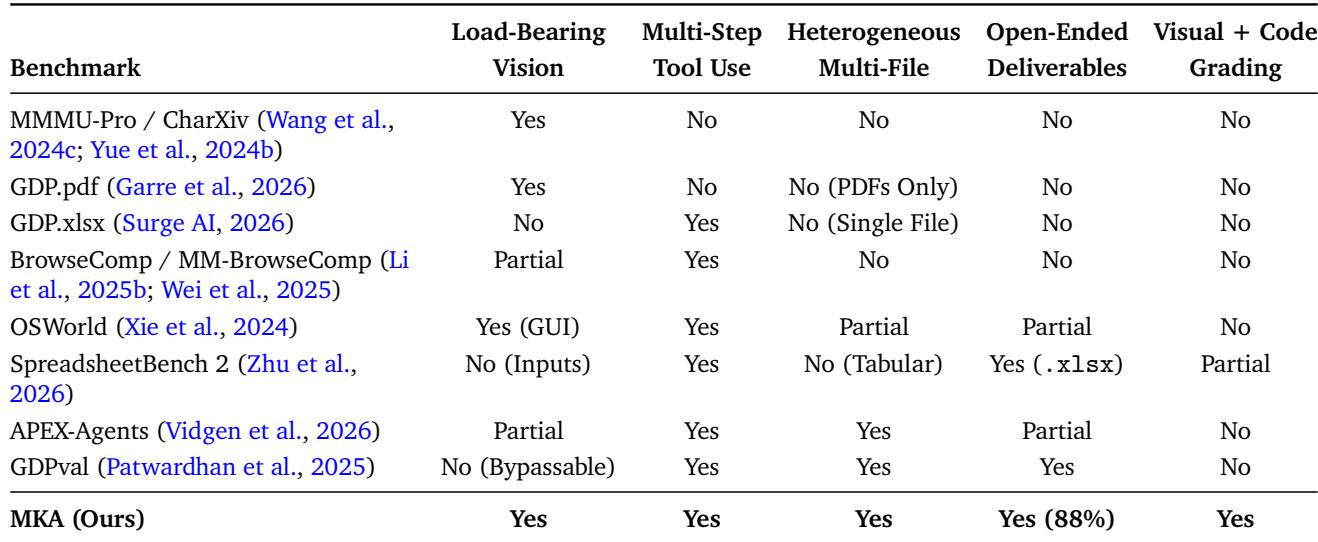
MKA is designed to combine load-bearing visual perception, multi-step tool use, heterogeneous multi-file inputs, open-ended deliverables, and visual plus code grading in a single benchmark, a combination not present in the compared benchmarks. Existing suites cover only parts of this profile: multimodal QA benchmarks require vision but remain single-turn and closed-ended, while spreadsheet, browsing, GUI, and workplace benchmarks lack or only partially satisfy visual, multi-file, and open-ended deliverable requirements. Ablations show removing image viewing barely changes GDPval quality or compute but degrades MKA success and increases trajectory length, indicating vision is essential to the benchmark. MKA is presented as the only setting that jointly requires load-bearing vision, multi-step tool use, heterogeneous multi-file inputs, open-ended deliverables, and visual plus code grading. Multimodal QA suites such as MMMU-Pro and CharXiv require visual perception but do not include tool use, multiple heterogeneous files, or open-ended deliverables. Spreadsheet and browsing benchmarks support multi-step tool use but are not load-bearing for vision or open-ended deliverables. Workplace and GUI benchmarks such as APEX-Agents and OSWorld only partially meet the combined requirements of vision, heterogeneous files, and open-ended deliverables. Removing image viewing leaves GDPval nearly unchanged while in MKA it lowers success and increases turns and output tokens as agents fall back on code workarounds.
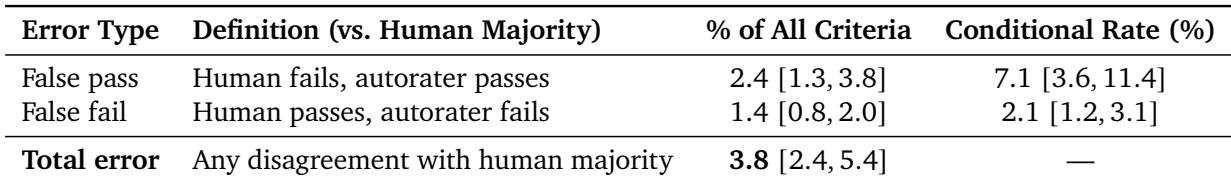
The autorater disagrees with the human majority on a small share of criteria, with an overall error rate of 3.8%. Disagreement is dominated by false passes rather than false fails, both in absolute terms and after accounting for base rates. This suggests the autorater is more likely to overlook a human-flagged failure than to reject work that humans accepted. False passes are the larger error type, making up 2.4% of all criteria versus 1.4% for false fails. The conditional false pass rate is 7.1% on human-failed criteria, compared with a 2.1% conditional false fail rate on human-passed criteria, indicating a stronger tendency toward leniency.
On MKA, all four models saturate regression quality, leaving climbing quality as the main differentiator. Claude Fable 5.2 and Gemini 4 Carbon lead on climb and overall deliverable quality. Under paired bootstrap, the top three models are statistically indistinguishable on climb quality, while the top two significantly outperform GPT-6 Astra. Regression performance is near ceiling across all models, so quality differences are concentrated in climbing. Claude Fable 5.2 and Gemini 4 Carbon achieve the highest climb and overall quality, with GPT-6 Astra trailing. Paired bootstrap comparisons show no clear separation among the top three models on climb quality, but the top two outperform GPT-6 Astra.
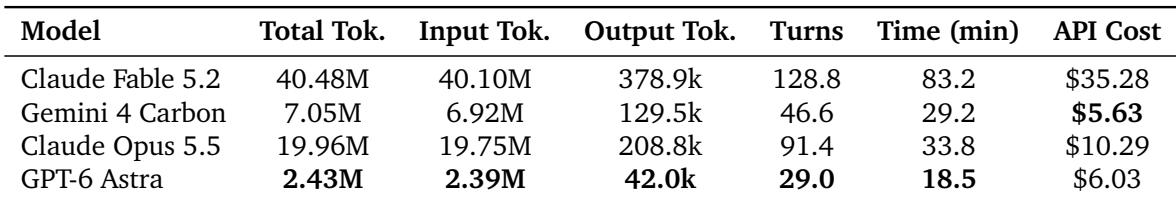
Efficiency varies widely across these frontier models on the MKA benchmark. Gemini 4 Carbon is the most cost-efficient per task and also delivers the best quality-per-token among the top scoring models. Several higher-cost models consume substantially more tokens, turns, and runtime without improving Climb-WSR, and even the most token-lean model costs slightly more than Gemini 4 Carbon because of higher per-token pricing. Gemini 4 Carbon achieves the lowest API cost per task while offering the best quality-per-token among the top scoring models. Claude Fable 5.2 uses substantially more total tokens, output tokens, turns, and wall-clock time than Gemini 4 Carbon, but its Climb-WSR difference is statistically non-significant. GPT-6 Astra has the fewest tokens and turns and the fastest runtime, yet its higher per-token list pricing makes it slightly more expensive per task than Gemini 4 Carbon despite lower Climb-WSR.
Removing the view_image tool has little effect on GDPval quality or compute, consistent with its reliance on machine-readable spreadsheet and text inputs. On MKA, the same ablation lowers success rates, especially on climb-focused tasks, while substantially increasing input tokens, output tokens, and turns. The agent compensates through code-based workarounds such as ASCII rendering and OpenCV pipelines, but these recover visual understanding only partially and at higher cost. On GDPval, removing view_image leaves analytical quality and compute essentially unchanged. On MKA, removing view_image causes a larger drop in climb-related success than regression success and sharply inflates trajectory length and token use. Without view_image, the model resorts to code-based visual workarounds like ASCII art, Braille rendering, and OpenCV pipelines, but still misses subtle perceptual details.
This set of experiments evaluates MKA, a benchmark that uniquely combines load-bearing visual perception, multi-step tool use, heterogeneous multi-file inputs, open-ended deliverables, and visual plus code grading, against existing benchmarks and through ablations and model comparisons. The autorater validation shows low overall disagreement with human judgments but a leniency bias toward false passes. On MKA, frontier models saturate regression quality, so climbing quality drives differentiation, with Claude Fable 5.2 and Gemini 4 Carbon leading overall while the top three remain statistically similar on climb quality. Efficiency results highlight Gemini 4 Carbon as the most cost-efficient per task, and removing the view_image tool leaves GDPval nearly unchanged but lowers MKA success, especially on climbing, as agents fall back on costly code-based visual workarounds.