Command Palette
Search for a command to run...
Genie: Generative Interactive Environments
Genie: Generative Interactive Environments
概要
本論文では、インターネット上のアノテーションなし動画から教師なしで学習された初の生成型対話的環境であるGenieを提案する。本モデルは、テキスト、合成画像、実写写真、スケッチなどにより記述された、行動制御可能な仮想世界を無限に生成することが可能である。110億パラメータを有するGenieは、基盤的世界モデルと見なすことができる。Genieは、時空間ビデオトークナイザ、自己回帰的動力学モデル、およびシンプルかつスケーラブルな潜在行動モデルから構成される。世界モデルの先行研究で通常必要とされる正解行動ラベルやドメイン固有の要件なしに学習されているにもかかわらず、Genieは生成された環境内でのフレーム単位の行動操作を可能にする。さらに、学習された潜在行動空間は、未見の動画から行動を模倣するエージェントの学習を促進し、将来の汎用エージェントの学習への道を開くものである。
One-sentence Summary
the paper introduce Genie, an 11B-parameter foundation world model comprising a spatiotemporal video tokenizer, an autoregressive dynamics model, and a latent action model that generates action-controllable interactive environments from unlabelled Internet videos, enabling frame-by-frame interaction and imitation learning from unseen videos without ground-truth action labels.
Key Contributions
- Genie is an 11B-parameter generative interactive environment trained from unlabelled Internet videos using a spatiotemporal video tokenizer, an autoregressive dynamics model, and a scalable latent action model, producing action-controllable virtual worlds from text, synthetic images, photographs, or sketches.
- The latent action learning mechanism enables frame-by-frame control of generated environments without ground-truth action labels, extending prior video models and playable video generation methods that typically rely on labeled data or domain-specific assumptions.
- The learned latent action space supports imitation of behaviors from unseen videos and video-only environment generation, offering a path toward training generalist agents without costly action annotations.
Introduction
Generative AI has advanced quickly in language and image generation, and video models are improving, yet many systems still produce passive media rather than interactive experiences. This gap matters because interactive environments could support creative tools, games, simulations, robotics, and agent training at broad scale. Prior approaches face constraints: world models often require action labels or text annotations collected from controlled environments, video generation models usually lack explicit action control, and playable video generation or procedural content methods are often limited to narrow domains, static scenes, or domain specific knowledge. The authors introduce Genie, a generative interactive environment built as a foundation world model. They leverage more than 200,000 hours of internet gaming videos without action or text annotations, learn a latent action space from video, and use spatiotemporal transformers with a video tokenizer, causal action model, and MaskGIT dynamics model. The model scales up to 11B parameters and can generate playable worlds from text or image prompts, with demonstrations on gameplay, robot videos, and reinforcement learning inference.
Dataset
-
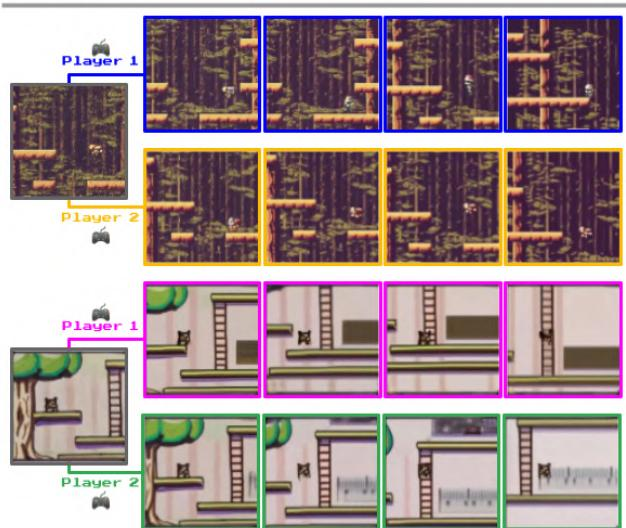
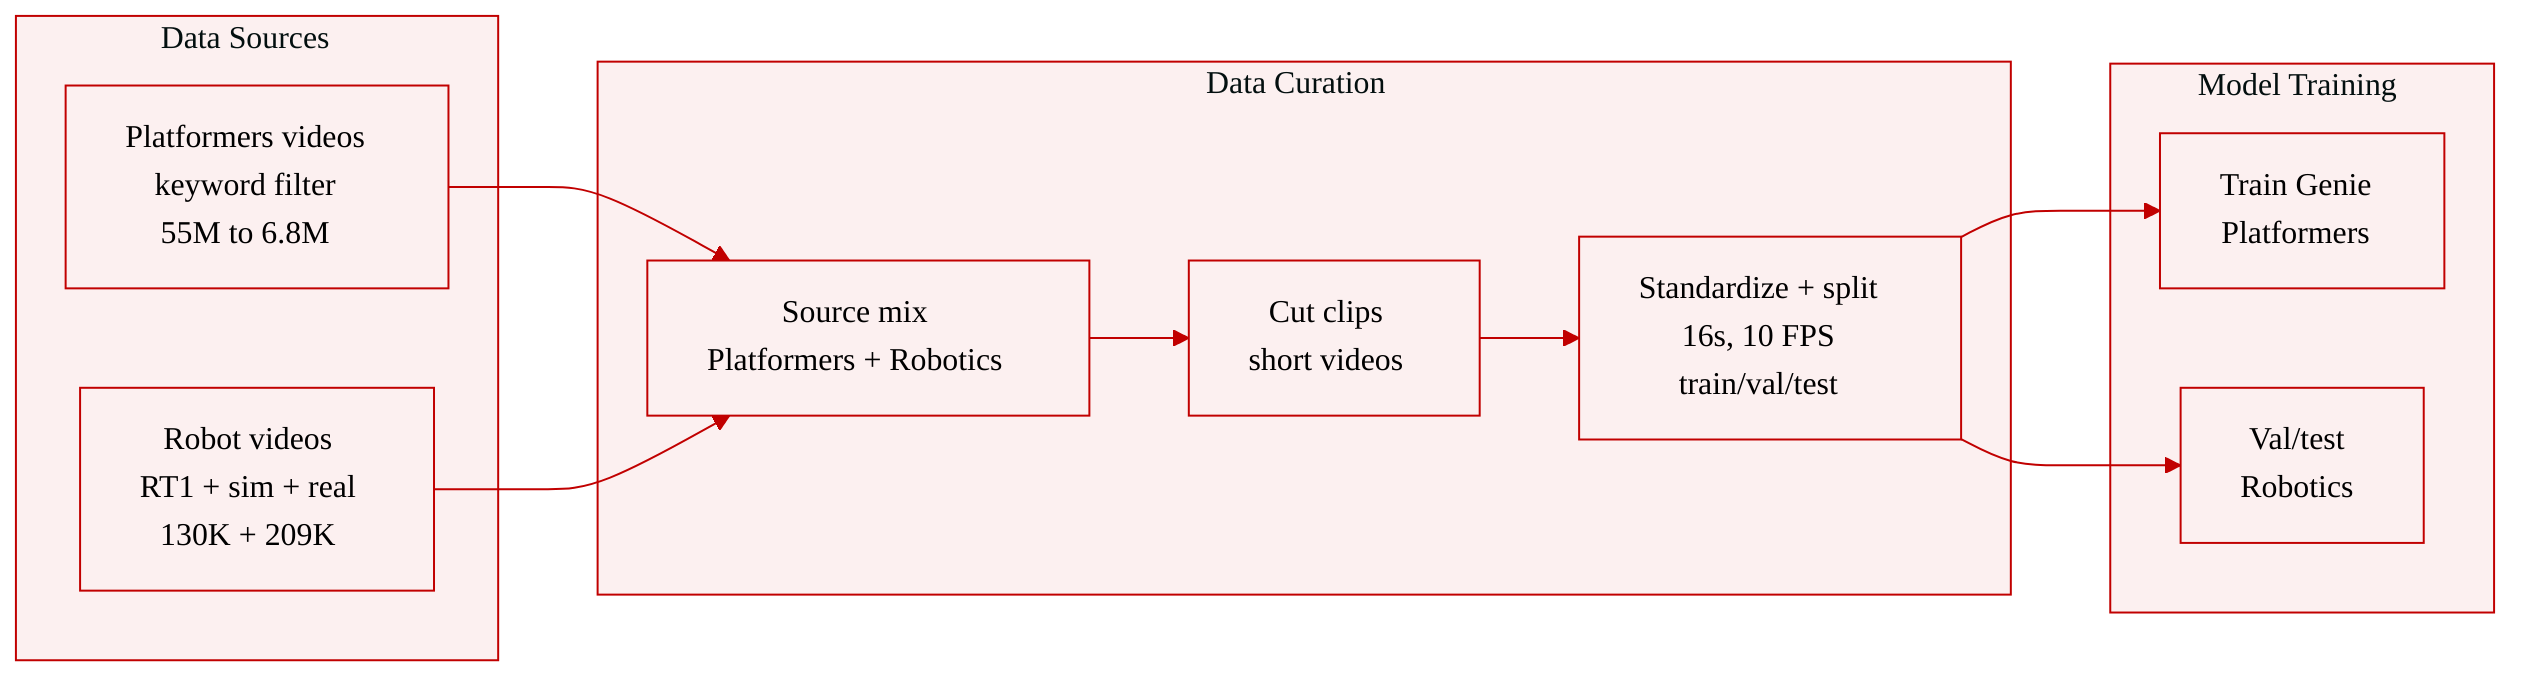
The authors train Genie primarily on a large-scale “Platformers” dataset built from publicly available Internet videos of 2D platformer games.
-
Platformers construction:
- Source: public Internet videos.
- Filtering rule: videos are selected using keywords related to platformer games.
- Initial filtered set: 55M 16-second clips at 10 FPS and 160 x 90 resolution.
- Final Platformers set: 6.8M 16-second clips, totaling about 30,000 hours.
- Scale: within an order of magnitude of other large Internet video datasets.
- Default usage: unless stated otherwise, reported results use an 11B-parameter model trained on this Platformers set.
-
The authors also evaluate on a “Robotics” dataset to test generality:
- Sources: the robotics dataset used to train RT1, a separate simulation dataset, and 209K real-robot episodes from prior work.
- Composition: approximately 130K RT1 robot demonstrations plus the additional simulation and real-robot data.
- Filtering/usage rule: robot actions are not used; all sequences are treated purely as videos.
- No specific resolution, clip length, or mixture ratio is described in the provided text.
-
Dataset processing and usage details:
- Clips are standardized to 10 FPS.
- Modeling uses sequences of 16 frames.
- The video tokenizer is trained to reconstruct frames into discrete latent tokens, but the provided text does not describe a special cropping strategy.
- No explicit metadata schema or additional annotation is described beyond keyword filtering and conversion into short video clips.
- The Platformers dataset is used for the main training and evaluation results, while the Robotics dataset is used for cross-domain validation.
Method
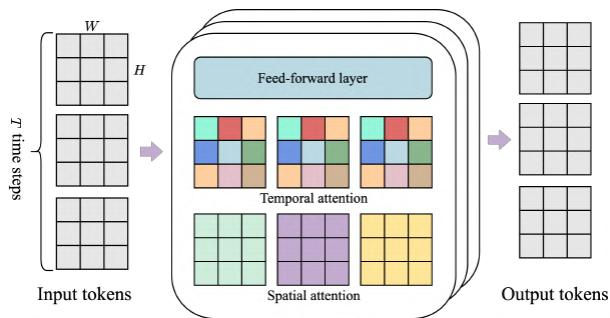
Genie is a generative interactive environment trained from video without explicit action labels. Its architecture uses a memory efficient ST-transformer backbone for all major components, which allows long video sequences to be processed while controlling computational cost. Unlike a standard transformer where every token attends to every other token, the ST-transformer interleaves spatial attention and temporal attention inside each spatiotemporal block. Spatial attention operates over the H×W visual tokens of a single frame, while temporal attention operates across the same spatial location through T frames and applies a causal mask. The authors also omit the feed-forward layer after spatial attention and keep only one feed-forward layer after the temporal component, which improves the tradeoff between model capacity and scaling. Refer to the architecture diagram below.
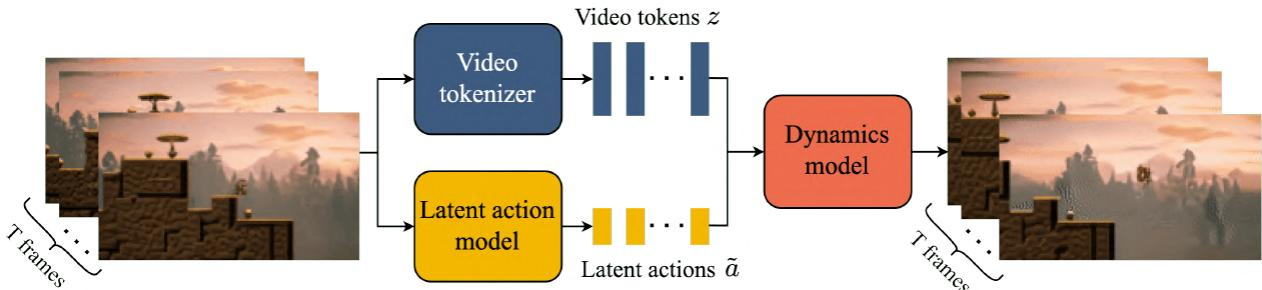
The complete model is built around three modules: a latent action model, a video tokenizer, and a dynamics model. During training, T input frames are first tokenized by the video tokenizer, and the latent action model infers the latent actions that explain frame transitions. The dynamics model then consumes these tokens and latent actions to predict future frame content in an iterative manner. The system follows a two-stage training strategy. The video tokenizer is trained first, after which the latent action model and the dynamics model are co-trained. The latent action model is trained directly from pixels, while the dynamics model operates on the discrete video tokens produced by the tokenizer. As shown in the framework diagram below:
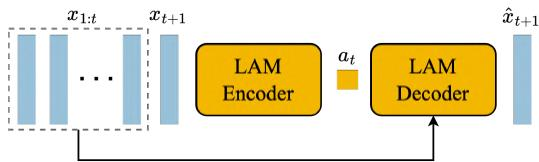
The latent action model learns controllable signals in a fully unsupervised way. Its encoder receives all previous frames and the next frame, then outputs a continuous latent action for each transition. A lightweight decoder receives the past frames and the inferred latent action, and tries to predict the next frame. The training objective is based on a VQ-VAE formulation, which quantizes the continuous latent actions into a small codebook. This bounded action vocabulary is important because it supports human playability and controllability; in the experiments, the codebook size is ∣A∣=8. Because the decoder can only reconstruct the future frame using the history and the latent action, each a~t is encouraged to capture the most meaningful change between the past and future. The causal temporal structure of the ST-transformer also allows the model to process the full sequence x1:T and generate latent actions for all frame pairs. At inference time, most of the latent action model is discarded, while the codebook remains useful for mapping discrete actions selected by a user. The unsupervised training mechanism of the latent action model is shown in the figure below:
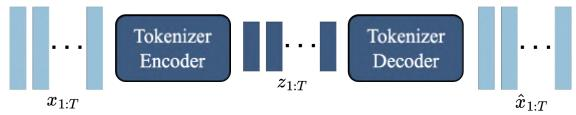
The video tokenizer compresses raw video into discrete tokens to reduce dimensionality and make video generation more tractable. It is implemented as a VQ-VAE with ST-transformer components in both the encoder and decoder. Given frames x1:T=(x1,…,xT), the tokenizer produces discrete representations z1:T=(z1,…,zT), where each frame is represented by tokens in a discrete latent space. The tokenizer is trained with a standard VQ-VAE reconstruction objective over the video sequence. Using the ST-transformer is a deliberate design choice: it injects temporal context into the latent codes, so each zt reflects information from the observed video prefix. At the same time, the architecture avoids the high cost of full space-time attention, because the dominant attention operation scales with the number of frames more efficiently than a fully spatiotemporal transformer. The tokenizer structure is shown in the figure below:
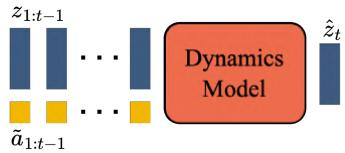
The dynamics model is a decoder-only MaskGIT transformer. At each time step t, it receives the previous token sequence z1:t−1 and stop-gradient latent actions a~1:t−1, then predicts the next frame tokens z^t. In training, the model predicts z^2:T from z1:T−1 and a~1:T−1, and is optimized with a cross-entropy loss between the predicted tokens and the ground-truth tokens z2:T. To support MaskGIT-style training, the input tokens z2:T−1 are randomly masked according to a Bernoulli distribution whose masking rate is sampled uniformly from the interval [0.5,1]. The authors found that treating latent actions as additive embeddings, rather than concatenating them with frame tokens, improves controllability. The dynamics model input and prediction path is shown in the figure below:
At inference time, Genie behaves like a controllable video environment. A player begins with a prompt image x1, which is passed through the tokenizer encoder to produce initial tokens z1. The player then selects a discrete latent action a1∈[0,∣A∣). This discrete index is mapped to an action embedding through the VQ codebook, and the dynamics model predicts the next token set z^2. The process repeats autoregressively as more actions are supplied, producing z^2:T. The generated tokens are decoded by the tokenizer decoder into video frames x^2:T. Because the learned latent action semantics remain consistent across inputs, a user can explore the model much like learning the buttons on a controller: the same action tends to induce similar transitions in different contexts. The same mechanism also allows ground-truth videos to be regenerated by feeding the model the initial frame and inferred actions, or by changing the action sequence to generate new trajectories.
Experiment
The experiments evaluate Genie on large-scale Internet platformer videos and robotics video data, using video fidelity and latent-action controllability to assess whether unsupervised latent actions support high-quality, interactive generation. Scaling studies show consistent performance gains as model size and batch size increase, while qualitative results demonstrate robust controllability on out-of-distribution prompts and emergent behaviors such as parallax and object manipulation. Additional experiments on latent-action-based imitation and ablations indicate that raw pixels and the chosen spatiotemporal tokenizer preserve movement information better than alternatives, supporting Genie's potential as a foundation world model for agent training.
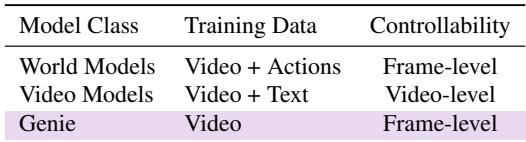
Genie is described as a generative video and world model trained only on video data, without explicit action or text annotations. Compared with prior model classes, it uses a learned latent action space to enable frame-level controllability, whereas video models typically provide only video-level control and world models rely on action-labeled data. Genie requires only video data for training. Genie supports frame-level control through learned latent actions. Prior world models need video plus actions, while video models need video plus text and offer video-level control.
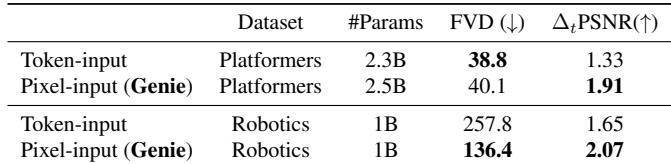
Comparing latent action model inputs, the token-input variant gives marginally better video quality on Platformers but much worse video quality on Robotics. Pixel-input Genie provides higher controllability in both environments, indicating raw video input is more beneficial overall. Token-input has a slight FVD advantage only on Platformers. Pixel-input Genie improves controllability in both datasets.
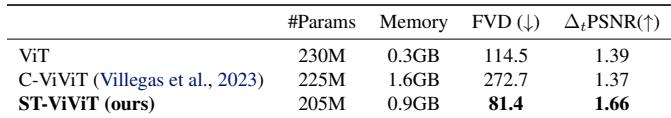
Across spatial-only ViT, C-ViViT, and ST-ViViT tokenizers with similar parameter counts, ST-ViViT achieves the best video generation and controllability metrics. It also uses less memory than C-ViViT and avoids C-ViViT's poor generation quality, suggesting that spatial-temporal attention in ST-ViViT is effective without the cost of full space-time attention. ST-ViViT gives the lowest FVD and highest delta_t PSNR among the compared tokenizers. C-ViViT has much higher memory use than ST-ViViT while producing considerably worse generation results. ST-ViViT provides a practical balance of fidelity, controllability, and memory.
Experiments compare Genie against prior video and world models and evaluate it across Platformers and Robotics settings to assess controllability and generation quality. Results show that learned latent actions support frame-level control without explicit action or text annotations, and pixel-input variants generally yield better controllability than token-input variants. Tokenizer comparisons further indicate that the spatial-temporal ViViT achieves the best practical balance of video fidelity, controllability, and memory usage among the evaluated architectures.