Command Palette
Search for a command to run...
Polar Express:最適行列符号手法とそのMuonアルゴリズムへの応用
Polar Express:最適行列符号手法とそのMuonアルゴリズムへの応用
Noah Amsel David Persson Christopher Musco Robert M. Gower
概要
極分解およびそれに関連する行列符号関数の計算は、数値解析において長年にわたり広く研究されてきた問題である。近年、これは深層ニューラルネットワークの学習に用いられるMuonオプティマイザの重要なサブルーチンとして注目されている。しかし、この応用の要求は古典的な設定とは大きく異なる。すなわち、深層学習では高精密よりも高スループットを優先するGPU向けアルゴリズムが求められる。本論文では、極分解の計算に対する新しい手法であるPolar Expressを提案する。Newton-Schulz法をはじめとする古典的な多項式手法と同様に、本手法は行列-行列積のみを用いるため、GPU上で極めて効率的に動作する。Chen & ChowやNakatsukasa & Freundの先行研究に着想を得て、Polar Expressは各反復においてミニマックス最適化問題を解くことで更新則を適応的に決定する。この戦略が最悪ケースの意味で誤差を最小化することを証明し、Polar Expressが初期反復においても漸近的にも可能な限り急速に収束することを示す。さらに、有限精度の問題にも対処し、bfloat16での実用的な使用を可能にした。Muonに統合した結果、FineWebデータセットから10億から100億トークンで学習したGPT-2モデルにおいて、検証損失の一貫した改善が得られ、幅広い学習率にわたって近年の代替手法を上回る性能を示した。
One-sentence Summary
Researchers at New York University and the Flatiron Institute propose Polar Express, a GPU-friendly polar decomposition method that solves a minimax optimization problem at each iteration to achieve provably optimal worst-case convergence in both early and asymptotic regimes, and demonstrate consistent validation loss improvements over recent alternatives when integrated into the Muon optimizer for GPT-2 training.
Key Contributions
- Polar Express introduces a polar decomposition method that adapts polynomial updates at each iteration by solving a minimax problem and uses only matrix-matrix multiplications, making it efficient for GPU-based Muon optimizers.
- The polynomial sequence is proved to give a worst-case optimal approximation to the sign function, with super-exponential convergence and rapid progress within just five to ten iterations.
- An implementation compatible with bfloat16 is evaluated on synthetic matrices, GPT-2 gradient matrices, and Muon-trained GPT-2 models on one to ten billion FineWeb tokens, improving validation loss across learning rates and being adopted in the NanoGPT speedrun.
Introduction
Advanced linear algebra is increasingly central to deep learning, especially in optimizers like Muon, which replaces the usual momentum direction with the polar factor of a gradient-based matrix. This polar factor is equivalent to a matrix sign function for square matrices and gives a steepest-descent direction under the spectral norm. For large language model training, the computation must be fast, GPU-friendly, memory efficient, and mainly useful at low or moderate accuracy.
Prior methods face practical limitations. A direct SVD is too expensive on GPUs, and many classical polar-decomposition methods require matrix inverses, QR factorizations, or other operations that do not parallelize well. Newton-Schulz is attractive because it uses only matrix-matrix products, but it converges slowly at first. Recent heuristic polynomial iterations reach low-accuracy estimates quickly, but they do not converge to the true polar factor.
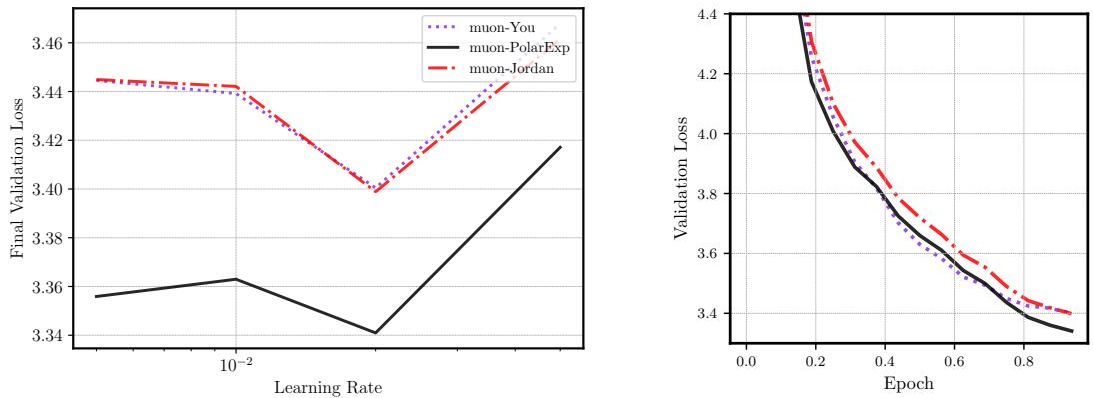
The authors introduce Polar Express, a new GPU-friendly iterative method for approximating the matrix polar factor. It adapts the polynomial update rule at each iteration, balancing fast early progress and later accuracy. The method uses polynomials designed to optimize the worst-case approximation of the sign function, converges super-exponentially, and can produce useful approximations within a small number of iterations. Applied inside Muon, Polar Express improves GPT-2 training validation loss across learning rates and has been adopted in optimized NanoGPT training workflows.
Method
The authors design the method to compute polar(M) through operations that are efficient on GPUs: linear combinations of matrices and matrix-matrix products. Since matrix products are more expensive than linear combinations, the algorithm is structured to use as few matrix products as possible. For a matrix with singular value decomposition M=UΣV⊤, odd powers can be written as
M2q+1=UΣ2q+1V⊤=M(M⊤M)q.Therefore, for an odd polynomial
p(x)=a0x+a1x3+⋯+aqx2q+1,the matrix polynomial can be evaluated as
p(M)=a0M+a1M(M⊤M)+⋯+aqM(M⊤M)q.The central design choice is to approximate polar(M) using a composition of lower-degree odd polynomials. The full approximation has the form
p=pT∘pT−1∘⋯∘p1,and the matrix iterate is generated recursively by
X0=M,Xt=pt(Xt−1)for t=1,…,T.The final matrix XT is the approximation to polar(M). If each component polynomial has odd degree d, this composition requires only O(Td) matrix products. A standard Newton-Schulz iteration is a special case of this framework, but the authors choose the polynomials to minimize the worst-case approximation error.
Given known or estimated lower and upper bounds ℓ and u on the singular values of M, the goal is to find the composition that minimizes the spectral norm error in the worst case. Because
polar(M)−p(M)=U(I−p(Σ))V⊤,and the spectral norm is unitarily invariant, this reduces to a scalar uniform approximation problem: find a composed odd polynomial p such that p(x) stays as close as possible to 1 for all x∈[ℓ,u]. Formally,
p⋆=argp=pT∘pT−1∘⋯∘p1pt∈Pdoddminx∈[ℓ,u]max∣1−p(x)∣.The method solves this problem greedily across iterations. For the current interval [ℓt,ut], one odd-degree-d polynomial is chosen to minimize
x∈[ℓt,ut]max∣1−p(x)∣.This polynomial maps the current interval to a new interval
[ℓt+1,ut+1],which then becomes the target interval for the next polynomial. The bounds can be updated using
ℓt+1=pt(ℓt),ut+1=2−ℓt+1.The resulting composition is optimal among all compositions of T odd polynomials of degree d. The final approximation satisfies
∥polar(M)−XT∥2≤x∈[ℓ,u]max∣1−p⋆(x)∣=1−ℓT+1.When the singular values are normalized so that σ(M)⊂[ℓ,1] and d=2q+1, the error bound takes the stronger form
∥polar(M)−XT∥2≤∣1−ℓ2∣(q+1)T,which shows rapidly improving convergence as T grows.
As shown in the figure below:
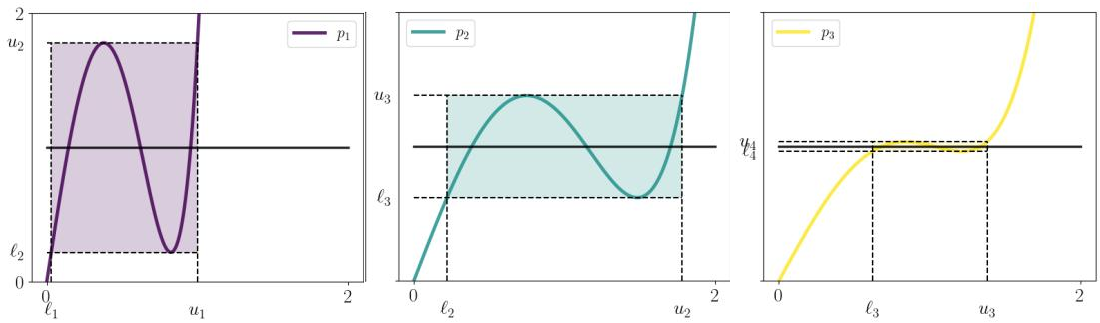
The evolution of the intervals shows how each polynomial narrows the range of singular values that still deviate from 1. The first polynomial maps the original singular value interval into a new interval closer to 1, the second polynomial acts on that updated interval, and subsequent polynomials continue refining the approximation. This interval-based view is what makes the greedy construction optimal for the spectral norm error.
To find each polynomial pt, the method solves a minimax approximation problem: among all odd polynomials of the chosen degree, it selects the one that uniformly approximates the constant function 1 on the current interval [ℓt,ut]. For the low degrees used in practice, this can be done explicitly or with a simplified solver derived from the equioscillation property of minimax approximations. A full Remez-style procedure would also solve the problem, but because the target function is constant and the degree is small, the method uses a specialized low-degree construction that is simpler to implement and mathematically equivalent in the relevant setting.
The method also requires practical bounds on the singular values. A simple upper bound is ∥M∥F, the Frobenius norm of the matrix. In practice, the input matrix is rescaled by a quantity proportional to this norm, and the upper bound is set to u=1. The lower bound ℓ is harder to estimate efficiently, so the authors choose a small value such as ℓ=10−3 for floating-point workloads, particularly when operating in bfloat16. A poor lower-bound estimate does not destroy convergence; it mainly delays it by a small number of iterations.
There are also numerical safeguards for finite-precision arithmetic. If roundoff causes singular values to appear slightly above the current upper bound, each polynomial can be replaced by x↦pt(x/1.01), which effectively enlarges the interval and avoids instability. Because some optimal polynomials can be non-monotone near the beginning of the process, the early iterations can also use slightly suboptimal but less oscillatory polynomials. These changes stabilize the offline coefficient computation with negligible loss of approximation quality.
The overall pipeline has an offline stage and an online stage. During the offline stage, the polynomials p1,…,pT are precomputed once for fixed bounds ℓ and u. During the online stage, these stored coefficients are reused for every matrix update. For a degree-5 polynomial
pt(x)=ax+bx3+cx5,the matrix iteration can be evaluated efficiently with a Horner-like form. Setting
Yt−1=Xt−1⊤Xt−1,the update is
Xt=Xt−1(aI+Yt−1(bI+cYt−1)).In the recommended implementation, the composition is applied to a normalized matrix of the form
∥M∥F+10−2M,and a small number of iterations, typically five or six, are sufficient for the deep learning use case.
Experiment
The experiments evaluate Polar Express both as an iterative polar-factor approximation and as the matrix sign subroutine in Muon, comparing it with Newton-Schulz, Jordan’s method, and You’s method. On synthetic and real matrix approximations, Polar Express converges more reliably and faster than the baselines when its lower singular value bound is reasonable, while remaining competitive when that bound is misestimated. In GPT-2 training, replacing these polar approximation subroutines with Polar Express consistently improves validation and training loss without extra cost, and ablations show that using only a few Polar Express iterations is sufficient, with further accuracy or exact SVD-based computation not helping optimization. The gains persist under weight decay and longer training, though the margin narrows.