Command Palette
Search for a command to run...
頑健なエージェントは因果的世界モデルを学習する
頑健なエージェントは因果的世界モデルを学習する
Jonathan Richens Tom Everitt
概要
因果的推論が頑健かつ汎用的な知能において本質的な役割を果たすという仮説は古くから提唱されている。しかし、エージェントが新たな領域に汎化するために因果モデルの学習が必須なのか、それとも他の帰納的バイアスで十分なのかは不明であった。本研究はこの問いに対する解答を与え、広範な分布シフトに対してレグレットの上限を満たすことができるエージェントは、データ生成過程の近似的な因果モデルを学習していなければならず、最適なエージェントではそのモデルが真の因果モデルに収束することを示す。また、この結果が転移学習や因果推論を含む複数の研究領域に与える示唆について議論する。
One-sentence Summary
Google DeepMind proves that any agent satisfying a regret bound across a large set of distributional shifts must learn an approximate causal model of the data-generating process, which converges to the true causal model for optimal agents, formally linking robust generalization to causal reasoning with implications for transfer learning and causal inference.
Key Contributions
-
For unmediated decision tasks, the paper proves that any agent capable of satisfying a regret bound over a large set of distributional shifts must have learned an approximate causal model of the data generating process. This learned model converges to the true causal model for optimal agents.
-
The paper resolves a model independent version of the causality and generalisation conjecture by showing that robust performance across domain shifts forces an agent’s internal world model to go beyond surface statistics. Causal world models are therefore necessary for agents that generalise to new domains under the stated assumptions.
-
The paper connects decision robustness to causal inference by showing that the set of optimal policies under distributional shifts is almost always sufficient to identify causal relations between environment variables. This complements the causal hierarchy theorem and clarifies when robust learning entails learning the data generating process.
Introduction
Causal reasoning is important for general intelligence because it helps systems make reliable decisions after changes in the environment, such as shifts in data distribution, features, labels, or task conditions. This matters for domain adaptation, transfer learning, robust classification, and other decision tasks where agents must maintain low regret when the data generating process changes.
Prior work leaves an open question: if modern deep learning agents can adapt to new environments without explicitly learning causal models, are causal models truly necessary? Causal transportability theory gives useful conditions for transfer, but it often assumes that all inductive biases can be represented as causal structure. Real deep learning systems can exploit many other biases, so it is unclear whether robust adaptation inherently requires causal knowledge.
The authors resolve this by proving a necessity result. They show that any agent capable of solving a decision task with bounded regret under sufficiently many local intervention-based distribution shifts must have learned an approximate causal model of the data generating process. Their approach leverages causal Bayesian networks, decision theory, and policy behavior under interventions to connect robust adaptation to causal world model learning.
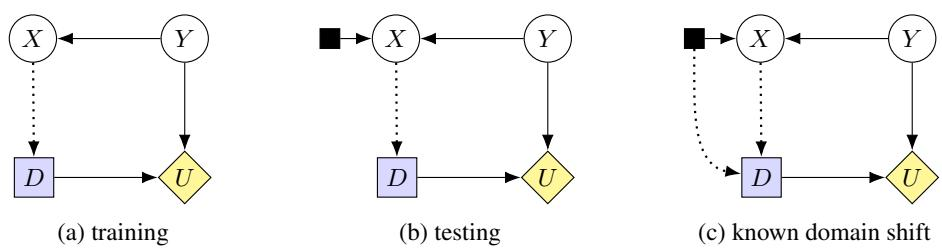
Method
The authors model decision tasks through a causal influence diagram, which augments an underlying causal Bayesian network over environment variables with a decision node and a utility node. In the single decision case, the variable set is partitioned as
V=({D},{U},C),where D is the decision chosen by the agent, U is a real valued utility function, and C denotes the chance variables that describe the environment. The chance variables are assumed to satisfy causal sufficiency, meaning that C contains all relevant common causes of the observed behavior. The agent is not assumed to know the underlying causal graph, but it can observe some subset of the environment variables,
PaD⊆C,and it selects a policy
π(d∣PaD).The expected utility of a policy is defined through an intervention on the decision node,
Eπ[U]=E[U∣do(D=π(PaD))].An optimal policy π∗ maximizes this quantity. In practical settings, the agent may not behave optimally, and its regret is quantified as
δ=Eπ∗[U]−Eπ[U].The framework focuses on unmediated decision tasks, where the agent’s decision does not causally influence the environment variables that enter the utility function. Formally, the authors impose the condition
DescD∩AncU=∅,which excludes settings such as Markov decision processes in which the agent’s action changes future environment states before the utility is realized. This assumption covers prediction tasks such as classification and regression, where the goal is to choose a decision based on observed information in order to optimize a loss or reward function.
Refer to the framework diagram.
In the illustrative supervised learning task, the label variable Y causes the feature variable X, the agent conditions on X to choose a prediction D, and the utility is a negative loss function. Under a distributional shift, a regime node induces an intervention on X. If the domain shift is known, the policy may condition on the shift indicator,
πσ(d∣PaD,σ).The key methodological claim is that optimal behavior under such shifts reveals information about the underlying causal structure. Specifically, the authors construct a procedure that queries an oracle for optimal policies under mixtures of local interventions on a causally sufficient set of variables C. The algorithm identifies the intervention mixtures for which the optimal decision changes. Those critical intervention mixtures are then used to recover both the directed acyclic graph and the joint distribution over the ancestors of the utility variable,
AncU.For almost all causal influence diagrams satisfying the technical assumptions, the optimal policy family
{πσ∗(d∣PaD)}σ∈Σis sufficient to identify the environment causal model over AncU, where Σ denotes the set of mixtures of local interventions. This establishes that exact optimal policies under a broad set of domain shifts encode the full causal model of the relevant environment variables.
The authors then relax the idealized assumption of optimal behavior and study agents whose policies satisfy a regret bound,
Eπσ[U]≥Eπσ∗[U]−δ.Under this assumption, they show that one can identify an approximate causal model
M′=(G′,P′)rather than the exact environment model. The parameters of the learned model satisfy
∣P′(vi∣pai)−P(vi∣pai)∣≤γ(δ),where γ(0)=0 and, for sufficiently small regret, γ(δ) grows linearly in δ. When regret is strictly positive, some weak causal relations may not be resolvable, so the recovered graph G′ can be a sparse subgraph of the true graph G. The authors evaluate this recovery process in simulated environments with binary decisions and binary latent variables. The following result summarizes the relationship between model error and normalized regret.
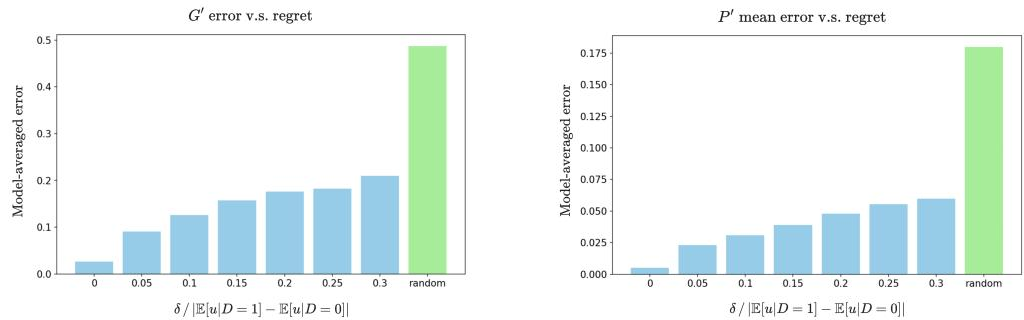
The authors also prove the reverse direction. If an agent has access to a causally sufficient environment model M=(P,G), then it can identify optimal policies under soft interventions for any utility function whose parents lie in C. If the agent instead has an approximate causal model M′=(P′,G′) with parameter error bounded by ϵ, then the authors show that it can identify policies with regret that grows linearly in ϵ. Thus, the method identifies two sides of a theoretical equivalence: robust policy learning under local domain shifts implies recovery of an approximate causal model, while an approximate causal model is sufficient to produce low regret policies.