Command Palette
Search for a command to run...
GOLDCOIN:文脈的整合性理論によるプライバシー法への大規模言語モデルの接地
GOLDCOIN:文脈的整合性理論によるプライバシー法への大規模言語モデルの接地
Wei Fan Haoran Li Zheye Deng Weiqi Wang Yangqiu Song
概要
プライバシー問題は、エンティティ間で情報が不適切に送信される際に顕著に生じる。既存研究は、狭く事前に定義されたパターン内での各種プライバシー攻撃、防御手法、評価の探求を中心にプライバシーを研究しており、プライバシーは社会保険番号など伝統的に機密とされるデータに限定された孤立した文脈非依存の概念ではなく、複雑な社会的文脈と不可分に結びついており、潜在的なプライバシー侵害の同定と分析を困難にしているという点を見落としている。大規模言語モデル(LLM)の登場は、プライバシー法に規定される微妙なシナリオを組み込み、こうした複雑なプライバシー問題に対処するための前例のない機会を提供する。しかし、関連するオープンソースの判例研究の不足が、LLMが具体的な法律規定に整合する上での効率を制約している。この課題に対処するため、我々はプライバシー侵害の司法的判断のためにLLMをプライバシー法に効率的に接地させるための新たなフレームワークGOLDCOINを提案する。本フレームワークは文脈的整合性理論を橋渡しとして活用し、関連するプライバシー法規(例:HIPAA)に根ざした多数の合成シナリオを生成することで、実世界におけるプライバシーリスクの同定に必要な複雑な文脈の理解をLLMに支援する。広範な実験結果により、GOLDCOINが実際の裁判例におけるプライバシーリスク認識能力を著しく向上させ、様々な司法タスクにおいてベースラインを上回ることが示された。
One-sentence Summary
HKUST proposes GOLDCOIN, a framework that grounds LLMs in privacy laws by leveraging contextual integrity theory to synthesize scenarios aligned with statutes such as HIPAA, enabling judicial assessment of privacy violations in real court cases beyond narrowly predefined privacy patterns.
Key Contributions
-
The paper introduces GOLDCOIN, a framework that grounds large language models in privacy laws by translating legal statutes such as the HIPAA Privacy Rule into contextual-integrity norms that model senders, recipients, subjects, information types, and transmission principles.
-
The paper constructs a synthetic-case generation and evaluation pipeline for HIPAA, producing the GOLDCOIN-HIPAA dataset and a benchmark sourced from real U.S. court cases in the Caselaw Access Project, with automatic filtering and diversity ranking used to improve generated case quality.
-
Experiments with instruction-tuned transformer-based LLMs show that GOLDCOIN improves HIPAA applicability assessment by 8% to 23% and privacy-risk detection by 8% to 18% over baselines on real court cases, while ablation studies and human analysis support the contribution of contextual integrity and data-quality components.
Introduction
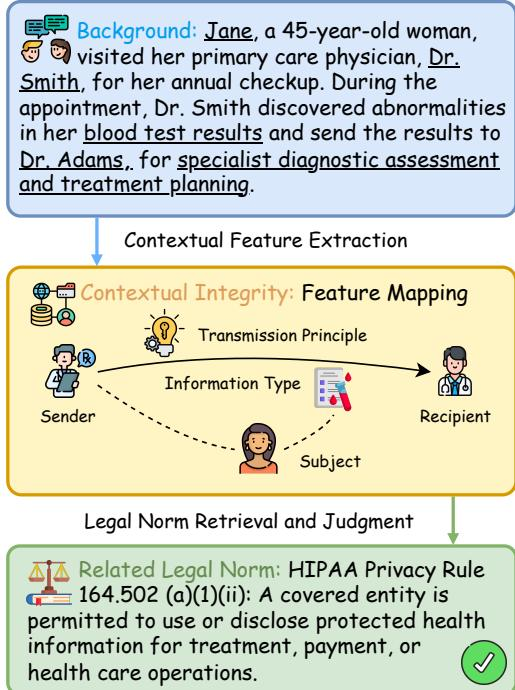
Automated privacy compliance matters because violations often arise from improper information transmission across regulated contexts such as healthcare, education, and employment, and laws like HIPAA, COPPA, and GDPR set norms for when such flows are allowed. Prior approaches often relied on predefined patterns, manual rules, or formalized legal logic, which are narrow and expert dependent, while legal LLMs trained on statutes or scarce open court cases generalize poorly and yield unstable improvements on privacy tasks. The authors leverage contextual integrity to abstract privacy clauses into structured norms involving sender, recipient, information subject, information type, and transmission principles. Their GOLDCOIN framework uses GPT-4, automatic filtering, and diversity ranking to generate synthetic court-case-like backgrounds from seed privacy-law norms, and instruction-tuned LLMs improve HIPAA applicability judgment by 8% to 23% and privacy risk detection by 8% to 18% over baselines.
Dataset
-
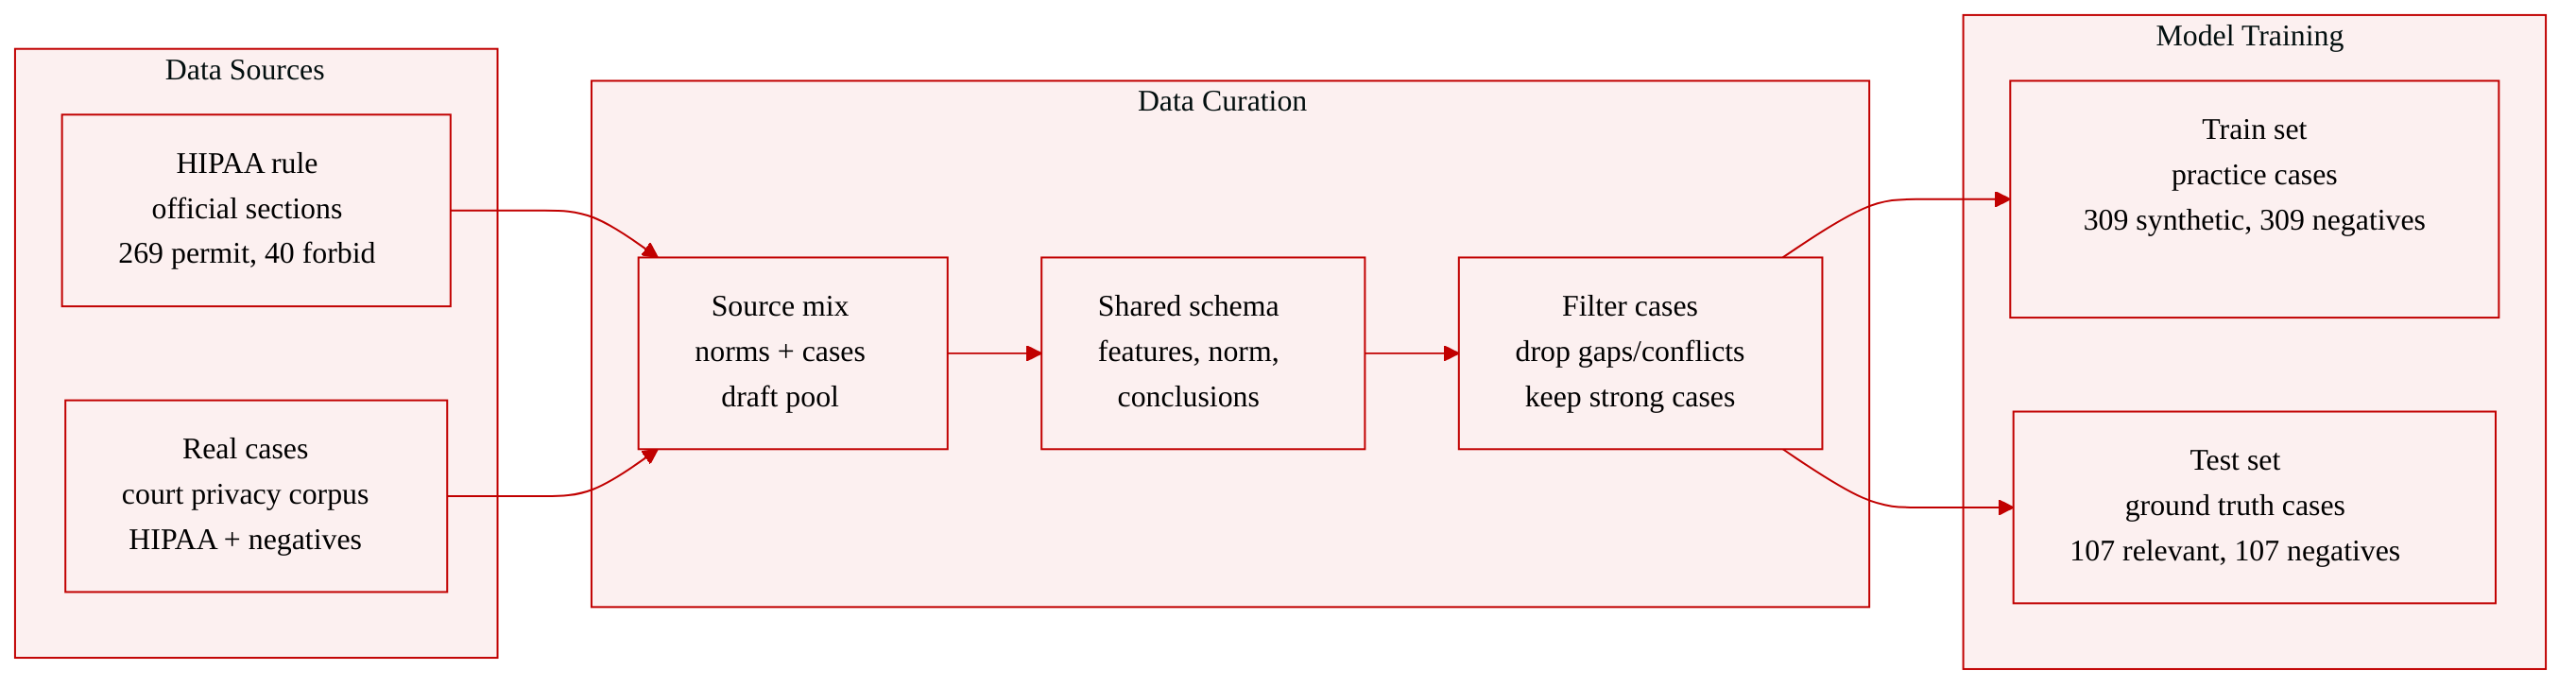
The authors use GOLDCOIN-HIPAA, a legal grounding dataset built from two sources: the HIPAA Privacy Rule statute text and real privacy-related court cases from the Caselaw Access Project.
-
For the statute source, the authors download the HIPAA Privacy Rule from the official Code of Federal Regulations website and convert it into a structured graph. Nodes represent regulation sections, with each node containing a labeled section identifier and paragraph content. Edges capture two relation types: subsume, for hierarchical section relationships, and refer, for cross-references between sections.
-
The authors derive legal norms by aggregating content along each root-to-leaf path in the graph. Each norm is labeled as permit, forbid, or other. Only permit and forbid norms are retained for case generation. The resulting seed set contains 269 permit norms and 40 forbid norms.
-
For the synthetic case subset, the authors use GPT-4 to generate multiple cases from each filtered norm. Each case is parsed into a fixed schema with five components: a background description, contextual features, the related norm, an applicability conclusion, and a compliance conclusion.
-
The contextual features include key privacy transmission elements such as sender, sender role, recipient, recipient role, subject, subject role, and information type. This structured metadata is used to keep each generated case aligned with the HIPAA privacy context.
-
The authors apply three postprocessing steps to the synthetic cases. First, they remove cases that omit vital contextual features. Second, they remove cases whose parsed norm, applicability conclusion, or compliance conclusion conflicts with the seed norm. Third, they use ROUGE-L based diversity ranking to select one case for each norm. After filtering, the synthetic subset contains 309 cases.
-
For real court cases, the authors collect privacy-related cases from the Caselaw Access Project, a corpus developed by Harvard Law School. They convert these real cases into the same schema as the synthetic cases using GPT-4 and manual annotation.
-
The real-case subset is divided by label. The authors collect 309 HIPAA-irrelevant privacy violation cases for training the applicability task as negative examples. For evaluation, they identify 107 HIPAA-relevant court cases as ground truth for compliance evaluation, and they sample an equal number of HIPAA-irrelevant cases to form the applicability test set together with those 107 relevant cases.
-
The authors combine the synthetic norm-grounded cases and the real court case pool into the final GOLDCOIN-HIPAA dataset. The cases are used for applicability and compliance tasks, where the model or system determines whether a case applies to the HIPAA Privacy Rule and whether the relevant norm permits or forbids the described privacy transmission.
-
The paper does not report an explicit mixture ratio between synthetic and real cases, and no cropping strategy is described. Dataset construction relies mainly on graph-based norm extraction, GPT-4 generation, schema parsing, consistency filtering, contextual feature filtering, and diversity-based selection.
Method
GOLD-COIN is a law-grounded pipeline for generating privacy judgment data and instruction tuning language models on legal applicability and compliance tasks. The method targets two decisions: applicability, which asks whether a privacy law L applies to a case background s, and compliance, which asks whether the information transmission described in s satisfies L. The framework combines statutory preprocessing, law-grounded case generation, quality filtering, real case alignment, and stepwise instruction construction. As shown in the figure below:
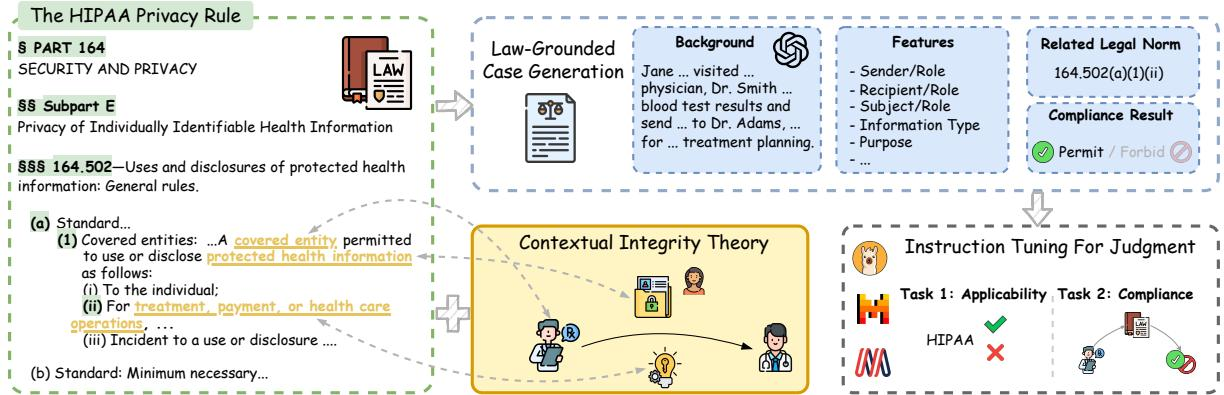
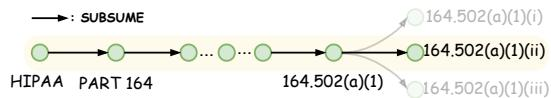
The first module preprocesses the legal statute before any case synthesis. The authors apply the method to the HIPAA Privacy Rule and convert the legal text into a structured graph G. Nodes correspond to statutory sections, and edges encode two kinds of relations. The subsume relation captures hierarchical containment, while the refer relation captures cross references between sections. Each node contains a labeled identifier and the corresponding paragraph content. Starting from a leaf node vil, the system recursively follows parent nodes until the root, aggregating all content along that path. Such a leaf-to-root path is treated as a norm, which is then used as a legal seed for case generation.
The norm construction process is shown in the figure below:
After norms are extracted, the pipeline classifies and filters them. The authors use GPT-4 to label leaf norms and retain those that express permission or prohibition under the law. Norms that define general terms, exceptions, or requirements are excluded from generation because they do not directly specify whether a transmission is allowed or forbidden. The resulting norm set N={n1,n2,…,nm} becomes the source material for synthetic case creation. Each case ki∈K is anchored to one selected norm ni, which makes the downstream legal grounding explicit.
Case generation is guided by contextual integrity theory, which models privacy violations through structured transmission features. Given a seed norm and its associated conclusion type, the authors compile instructions that instruct GPT-4 to produce a case background consistent with the legal rule. The prompt asks the model to preserve the transmission context, including entities, roles, information type, and transmission principles. Multiple responses are sampled for each norm, and the outputs are parsed into a fixed schema. The parsed components include the background description si, contextual features {(Pi,Ri),Ti,Ωi}, the related legal norm ni, the applicability conclusion ciappl, and the compliance conclusion cicomp.
The postprocessing module improves consistency, completeness, and diversity. First, a contextual feature integrity filter removes cases that omit required transmission elements such as sender, sender role, recipient, recipient role, subject, subject role, or information type. This ensures that each background contains enough structure for contextual integrity reasoning. Second, a consistency filter checks whether the generated case aligns with its seed norm and expected conclusion. The authors define
fnorm(n,n^)=1(n=n^),where n is the seed norm and n^ is the norm identified in the generated case. They also require the applicability and compliance conclusions to match the intended legal category:
fconc(cappl)=1(cappl=applicable),fconc(n+/−,ccomp)=1(n+/−=ccomp).Cases that fail these checks are discarded. Third, a diversity ranking step uses pairwise ROUGE-L similarity to reduce redundant backgrounds and preserve semantic variation across generated cases.
For validation and grounding, the authors also retrieve real court cases involving the HIPAA Privacy Rule and transform them into the same structured format used for synthetic cases. These cases are processed with model-assisted extraction and manual annotation. In addition, they collect privacy-related cases that do not fall under HIPAA, providing negative examples for the applicability task and discouraging overgeneralization of HIPAA judgments.
The final training stage compiles instruction-response pairs from the filtered case pool. The instructions are designed as multi-step chain-of-thought prompts. For applicability, the target response first extracts context-specific features and then decides whether HIPAA applies. For compliance, the response extracts the relevant transmission features, retrieves the related legal norm, and determines whether that norm permits or forbids the transmission. These structured instruction datasets are used to instruction tune LLMs, enabling them to perform the two privacy judgment tasks through explicit legal reasoning steps.
Experiment
Experiments evaluate GOLDCOIN for grounding LLMs in HIPAA judgments using synthetic cases and real court cases, comparing instruction-tuned open-source models with baselines and GPT-series models on applicability and compliance tasks. The results show that synthetic, law-grounded case tuning and multi-step reasoning improve LLMs’ ability to determine HIPAA relevance and legal outcomes, while simpler baselines offer limited or unstable gains. Ablation studies further confirm that contextual feature filtering, consistency checks, diversity ranking, and contextual integrity features are important for high-quality judgments.
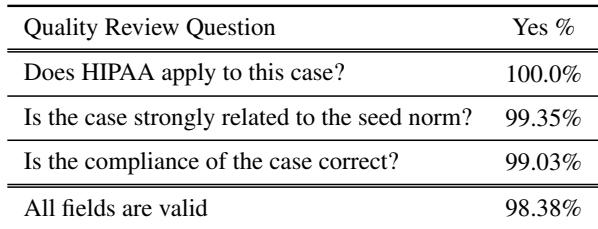
Expert human review indicates that the synthetic cases are highly consistent with HIPAA and closely aligned with their seed norms. The evaluation also shows that compliance labels and field validity are nearly always correct. All cases were judged to fall under HIPAA. Cases are almost always strongly related to their seed norms. Compliance judgments and field validity receive near full agreement.
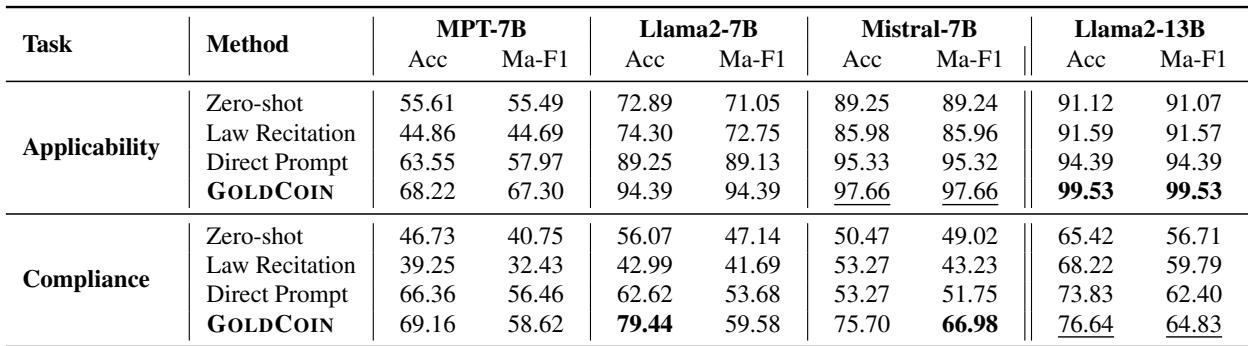
GOLDCOIN generally improves reported accuracy and Macro F1 for HIPAA applicability tasks across four open-source LLMs relative to zero-shot, law recitation, and direct prompting. For compliance tasks, it also produces notable Macro F1 gains, although the benefits vary by model and are less uniform than in applicability. The results support grounding model alignment in law-aligned synthetic cases rather than relying on abstract legal text or prompt-only instructions. GOLDCOIN gives the strongest reported applicability performance among the compared methods, especially for Mistral-7B and Llama2-13B. MPT-7B shows clear Macro F1 gains when using GOLDCOIN despite its weaker baseline behavior. Direct prompting can improve some applicability scores but is less reliable for compliance judgments. Detailed instructions alone do not consistently stabilize performance without case-grounded alignment.
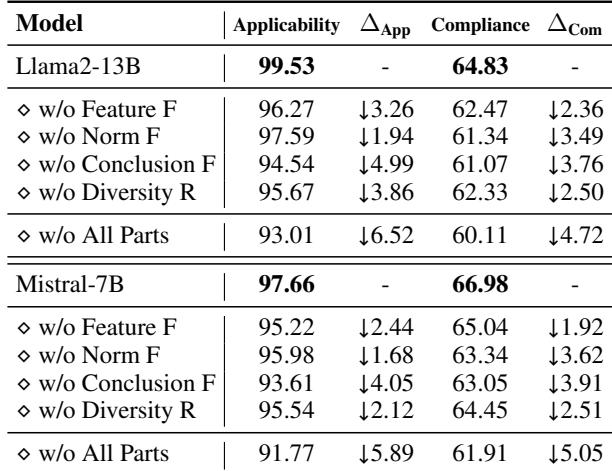
The ablation results show that contextual feature filtering, consistency checks, and diversity ranking help preserve Macro F1 performance for privacy-law judgments. Removing these components lowers scores on both applicability and compliance, with the largest declines appearing when all safeguards are disabled. Conclusion filtering and diversity ranking are especially important for stable applicability judgments, while norm consistency supports reliable compliance judgments. Cases missing key contextual features produce weaker applicability and compliance performance. Incorrect conclusions and reduced case diversity lead to more noticeable performance drops, particularly in applicability judgments.
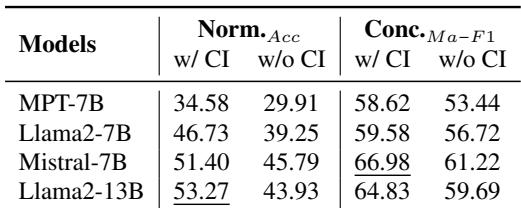
Omitting contextual feature extraction reduces norm retrieval accuracy for all listed open-source LLMs and also lowers conclusion Macro F1 scores. Llama2-13B shows the strongest norm retrieval with contextual features and a noticeable decline in conclusion performance when those features are removed. The results indicate that contextual features help models connect case details to relevant privacy norms and make better compliance judgments. Contextual feature extraction improves norm retrieval accuracy across MPT-7B, Llama2-7B, Mistral-7B, and Llama2-13B. Removing contextual features also reduces conclusion Macro F1 scores for all models. Llama2-13B has the best norm retrieval with contextual features and experiences a clear conclusion performance drop without them.
Expert review validates that the generated HIPAA cases are closely aligned with seed norms, with compliance labels and field validity judged as correct in nearly all instances. Across open-source LLMs, grounding alignment with law-related synthetic cases via GOLDCOIN improves HIPAA applicability and compliance judgments over prompting-only approaches, especially for applicability tasks. Ablations further show that contextual features, consistency filtering, and diversity preservation are important for stable performance, as removing them reduces norm retrieval and judgment quality.