Command Palette
Search for a command to run...
LLMとシンボリック定理証明による自然言語説明の検証と精緻化
LLMとシンボリック定理証明による自然言語説明の検証と精緻化
Xin Quan Marco Valentino Louise A. Dennis André Freitas
概要
自然言語による説明は、説明に基づく段階的推論を要する自然言語推論(NLI)モデルの評価の代替指標として用いられる。しかし、NLIにおける説明の妥当性評価は、通常、適切なデータセットのクラウドソーシングを必要とし、時間がかかるとともに論理的な誤りが生じやすい点で困難を伴う。本論文は、これらの既存の限界に対処するため、大規模言語モデル(LLM)と定理証明器(TP)の統合による自然言語説明の検証と精緻化を研究する。具体的には、TPとLLMを統合し、説明文の生成および形式化を行い、NLIに対する潜在的な推論戦略を提案するニューロ・シンボリックフレームワーク「Explanation-Refiner」を提示する。TPは、説明の論理的妥当性に対する形式的保証を提供し、以降の改善のためのフィードバックを生成する役割を担う。Explanation-Refinerを用いることで、最先端のLLMにおける説明的推論の能力、自動形式化、エラー修正機構を同時に評価できるとともに、異なる分野において複雑性が varied な説明の品質を自動的に向上できることを示す。
One-sentence Summary
Researchers at the University of Manchester, Idiap Research Institute, and collaborating institutions propose Explanation-Refiner, a neuro-symbolic framework that integrates large language models with theorem provers to verify and refine natural language explanations for NLI, providing formal guarantees of logical validity and iterative feedback to enhance explanation quality across diverse domains.
Key Contributions
-
Explanation-Refiner is a neuro-symbolic framework that combines large language models with theorem provers to generate, formalise, and iteratively refine natural language explanations for natural language inference while checking their logical validity.
-
An autoformalisation and error correction mechanism uses Neo-Davidsonian event semantics to preserve sentence-level semantic content during translation into logical forms and uses theorem prover feedback to identify and correct erroneous inference steps.
-
Experiments on textual entailment and multiple-choice question answering tasks show improved logical validity of human-annotated explanations across varying explanation complexities, supporting automated enhancement of explanatory reasoning.
Introduction
Natural Language Inference models increasingly generate explanations to make their reasoning more transparent, and those explanations can serve as evidence of whether a model has captured the needed logical steps. However, prior evaluation is limited because language generation metrics require costly and error-prone crowd-sourced explanation corpora, and those metrics often miss fine-grained properties such as logical validity, faithfulness, and robustness. Human-annotated explanations also tend to be incomplete or contain logical errors, which can bias evaluation.
The authors present Explanation-Refiner, a neuro-symbolic framework that combines large language models with a theorem prover to verify and refine natural language explanations. They use LLMs to generate and autoformalise explanatory sentences, Neo-Davidsonian event semantics with first-order logic to reduce semantic loss, and Isabelle/HOL to check deductive validity and provide feedback. In experiments, this approach improves the logical validity of explanations and reduces syntax errors from autoformalisation, revealing both the promise and limits of current LLMs for verifiable reasoning.
Dataset
-
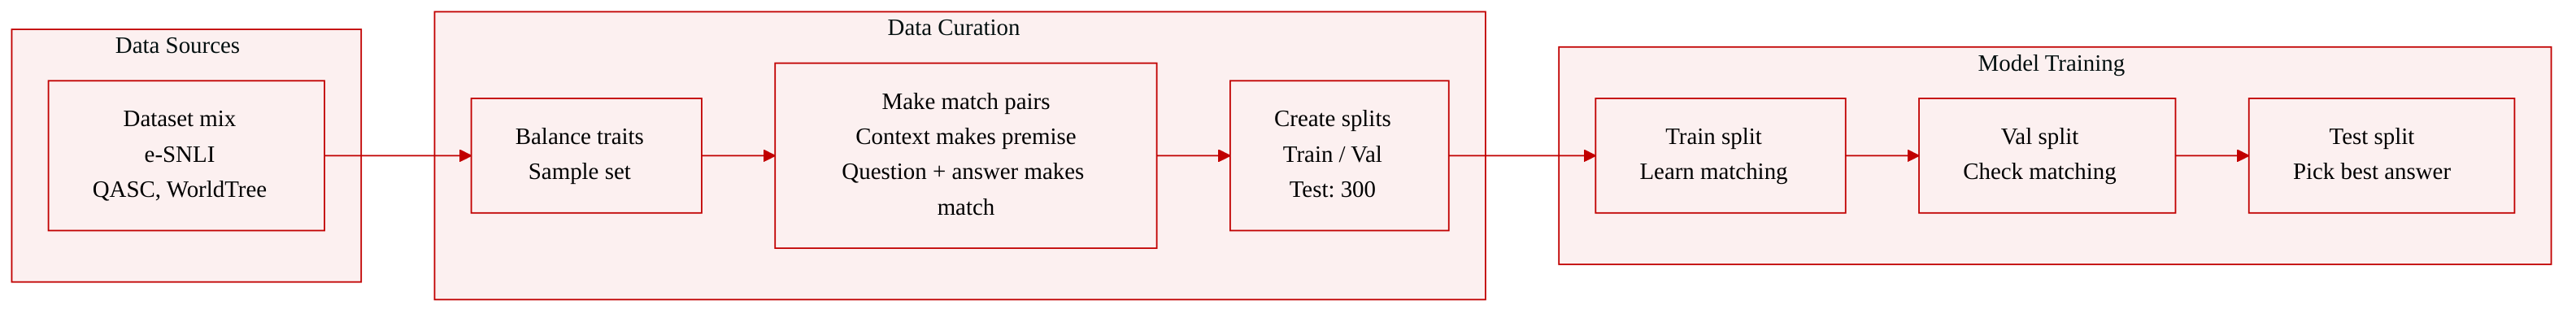
The authors use three NLI datasets for evaluation: e-SNLI, QASC, and WorldTree.
-
The evaluation set contains 300 samples in total, selected using the sampling strategy from Valentino et al. (2021), which aims to maximize representativeness and mutual exclusivity across syntactic and semantic features in the datasets.
-
The paper casts multiple-choice question answering into an NLI setting. Each task instance includes a question q and a set of candidate answers C = {c1, c2, ..., cn}, where one candidate answer is the correct answer.
-
To convert a multiple-choice question into an NLI example, the question and the correct candidate answer are combined into a hypothesis h_i.
-
If the question includes a context, the authors use that context to construct the premise p_i for the NLI formulation.
Method
The authors propose Explanation-Refiner, a neuro-symbolic framework that verifies whether explanatory sentences for NLI tasks are logically valid and, when they are not, iteratively repairs the errors. The method treats natural-language explanations as candidate logical evidence and then uses a theorem prover as an external verifier. Given a premise pi, a hypothesis hi, and an explanation Ei, the LLM is prompted to perform autoformalisation, converting each explanatory fact f∈Ei into an axiom ai. The axioms form a set A={a1,a2,…,an}. The system then asks the theorem prover to prove a goal of the form
pi∧B→hi,where B⊆A contains the axioms needed for the entailment. Refer to the framework diagram.
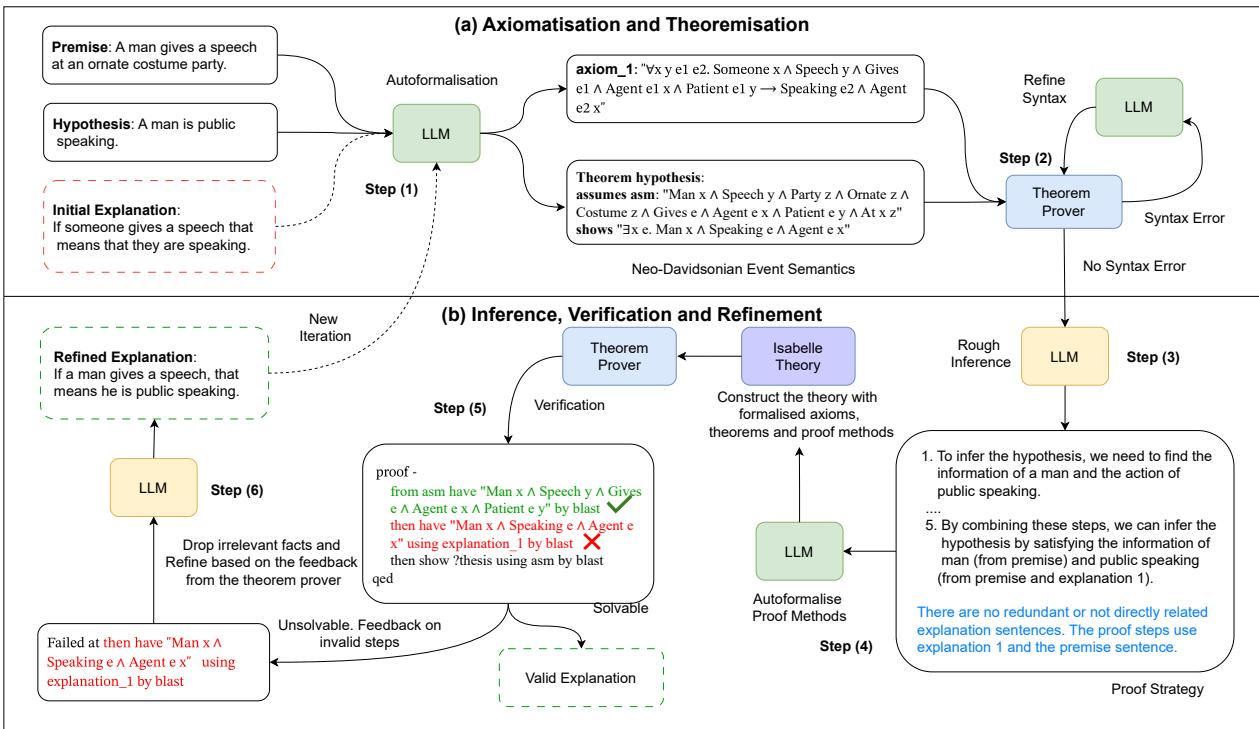
The pipeline is organized around three major modules: autoformalisation, proof construction, and verification with refinement. In the first stage, the LLM translates the premise, hypothesis, and explanation into an Isabelle/HOL theory. The explanation sentences become axioms, the premise becomes assumed known propositions, and the hypothesis becomes the theorem to be proved. This converts the natural-language reasoning task into a formal deductive setting where logical validity can be checked mechanically.
To preserve semantic information from complex natural-language sentences, the authors adopt Neo-Davidsonian event semantics together with first-order logic. Instead of collapsing a sentence into a flat predicate structure, verbs are reified as event variables, and their participants are attached through semantic roles such as agent and patient. For example, a sentence describing a wolf eating a sheep as an example of predator hunting prey can be formalised as a statement in which eating and hunting are events, wolf and predator describe the agent, sheep and prey describe the patient, and an example relation connects the two events:
∀xye1(wolf(x)∧sheep(y)∧eating(e1)∧agent(e1,x)∧patient(e1,y)→∃e2(predator(x)∧prey(y)∧hunting(e2)∧agent(e2,x)∧patient(e2,y)∧example(e1,e2))).For static or descriptive statements that do not involve events, the system uses ordinary FOL forms such as
∀x(gravity(x)→force(x))and
∀xy(greater(x,y)→larger(x,y)).Because LLMs can produce syntactically invalid symbolic output, the framework includes a syntax refinement mechanism before the theorem prover attempts semantic reasoning. The theorem prover acts as a checker and returns error messages when the generated Isabelle/HOL theory cannot be parsed or type-checked. These errors are grouped into type unification errors, which arise when declared argument types do not match the actual argument types in logical clauses, and other syntax errors, such as missing brackets, undefined entity names, or invalid logical symbols. The LLM is then prompted with the generated theory, the prover error, and examples of how to repair that error type. This iterative syntax correction improves the formal encoding until the theory is structurally well formed.
After the theory is syntactically valid, the system moves to proof construction. The LLM first produces a rough inference in natural language, which serves as a preliminary proof strategy. This inference identifies which explanatory sentences are sufficient and necessary for deriving the hypothesis, and which are redundant or unrelated. Based on this preliminary reasoning, the LLM constructs formal proof steps that can be submitted to Isabelle/HOL. A typical proof step follows the schema
show X using Y by Z,where X is the target proposition, Y denotes the assumptions used, and Z is an automated proof tactic. In practice, the tactic blast is often used because it is a general Isabelle tactic for first-order logic theorem proving.
The final stage performs verification and refinement. The constructed theory, including axioms, theorem statement, and proof steps, is given to the theorem prover. If the prover succeeds, the explanation is treated as logically valid. If the proof fails or times out, the system extracts the first relevant error from the solver, locates the failed proof step, and identifies the axioms B⊆A that were applied in that step. It then removes redundant or irrelevant facts, especially those not referenced by the successful proof steps or those marked as unnecessary in the preliminary inference. The LLM receives a refined feedback package containing the error message, the failed proof step, the associated proof strategy, and the explanatory sentences corresponding to the axioms. This feedback guides the LLM to revise the original explanation Ei, correcting logical omissions, invalid inferences, or misformalised facts. The loop then repeats. With each iteration, the framework narrows the set of logical errors and progressively refines the explanatory sentences until the resulting theory is verifiable and the explanation can be regarded as logically sound.
Experiment
The experiments evaluate five LLMs on three NLI-style datasets, where explanations are formally verified and iteratively refined using an external theorem prover. The results show that prover-guided feedback consistently improves logical validity and reduces syntactic errors, with autoformalisation quality strongly influencing model performance. Stronger models, especially GPT-4, benefit most from refinement, although explanation complexity, occasional factual inaccuracies, and rare trivial explanations remain challenges.