Command Palette
Search for a command to run...
Llama見て、Llama做う:大規模言語モデルにおける文脈的同調と注意散乱の機構論的考察
Llama見て、Llama做う:大規模言語モデルにおける文脈的同調と注意散乱の機構論的考察
Jingcheng Niu Xingdi Yuan Tong Wang Hamidreza Saghir Amir H. Abdi
概要
本論文では、多様な言語モデル(LM)およびプロンプト設定にわたって、文脈的同調(コンテクスト・エントレーンメント)という新たな現象を観察する。これは、入力プロンプト中の「無関係な」文脈情報によってLMが注意散乱を引き起こされる仕組みに対する、新たな機構論的視点を提供するものである。具体的には、LMは文脈プロンプト中に以前に出現したあらゆるトークンに対して、それがランダムなトークンであっても、有意に高いログジット(または確率)を割り当てる。これは、文脈的同調が、トークンと質問文や文の残りの部分との関連性や意味的関係とは独立して生じる機構論的現象であることを示唆している。我々は、文脈的同調の大きさが意味論的要因の影響を受けるという統計的に有意な証拠を発見した。反事実的プロンプトは事実的プロンプトよりも大きな影響を及ぼすことが示され、文脈的同調が機構論的現象であるにもかかわらず意味論的要因によって変調を受けることが示唆される。我々は、文脈的同調現象に対応するアテンションヘッドの回路群——同調ヘッド——が存在するという仮説を立てる。微分可能マスキングに基づく新たな同調ヘッド発見手法を用いて、Various settingsにわたってこれらのヘッドを特定する。これらのヘッドを「オフ」にし、すなわちその出力をゼロに設定すると、文脈的同調の効果は著しく減衰し、モデルは注意散乱を起こす文脈が存在しない場合に生成する出力に一致する出力を生成するようになる。文脈的同調の発見と、同調ヘッドを介したLMの注意散乱に関する本研究の調査は、注意散乱問題の機構論的分析とその緩和に向けた重要な一歩を印すものである。
One-sentence Summary
University of Toronto, TU Darmstadt, and Microsoft Research identify contextual entrainment, a mechanistic phenomenon in which LMs assign inflated logits to tokens appearing earlier in the context prompt regardless of their semantic relevance, and localize this effect to specific attention heads via a differentiable masking method, demonstrating that ablating these heads significantly attenuates distraction.
Key Contributions
-
The work identifies and characterizes contextual entrainment, where language models assign higher logits to tokens that appeared earlier in the prompt, even for random tokens, and finds that counterfactual contexts strengthen the effect relative to factual contexts.
-
The paper introduces a method based on differentiable masking for discovering entrainment heads, revealing attention-head circuits associated with contextual entrainment more effectively than analyzing attention heads in isolation.
-
Ablating the discovered entrainment heads, by setting their outputs to zero, significantly reduces contextual entrainment and yields outputs closer to those produced without distracting context, offering a mechanistic account and a potential mitigation strategy for distraction.
Introduction
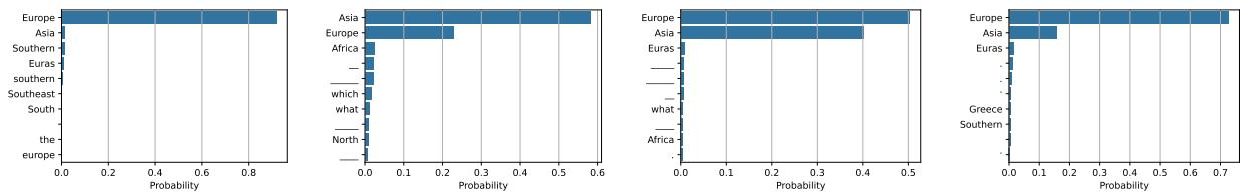
Large language models can use prompt context through in-context learning, which matters for retrieval augmented generation because added context can both help and distort model outputs. Prior work describes distraction mainly as irrelevant context, but that definition is too coarse to explain why different irrelevant prompts have different effects or how models internally misuse context. The authors identify contextual entrainment, where any token that appeared earlier in the prompt receives higher logits regardless of relevance, a phenomenon amplified by counterfactual content. They also locate a small set of entrainment heads using differentiable masking, showing that disabling them suppresses the effect.
Method
Discovering Entrainment Heads
The authors leverage a differentiable circuit discovery approach to identify which attention heads are responsible for contextual entrainment. Instead of analyzing each attention head in isolation, they formulate the problem as finding a small subset of heads whose removal suppresses the model’s tendency to follow counterfactual information from the context, even when the evaluated question is not directly related to that counterfactual information.
At a high level, the method works by selectively disabling attention heads inside a pretrained transformer language model and learning which heads are most important for propagating contextual information through the network. For each attention head, the authors introduce a learnable mask that controls whether the head contributes to the residual stream. When the mask is active, the head behaves normally; when it is inactive, its contribution is effectively removed.
For a given transformer block, the masked head contribution can be written as:
zi=hj∈Hi∑mjhj(xi),where hj denotes the j-th attention head, Hi is the set of heads in block or layer i, xi is the input to that block, and mj is the binary mask associated with head hj.
Because binary masks are not differentiable, the authors use a Gumbel sigmoid relaxation with a straight through estimator. Each mask is generated from a learnable logit li, a temperature τ, and two uniform random variables. The sampled mask is computed as:
si=σ(τli−loglogU2logU1), mi=[1si>21−si]detach+si.Here, σ(⋅) is the sigmoid function, τ∈(0,∞) controls the sharpness of the sampled mask, li is the learnable logit for the i-th head mask, and U1,U2∼Uniform(0,1) provide stochasticity for mask sampling. The first term, 1si>1/2, produces a hard binary mask during the forward pass, while the second term allows gradients to flow through si during the backward pass.
The optimization objective has two competing goals. The first goal is to suppress the contextual entrainment signal, meaning the masked model should reduce or remove the effect of the counterfactual context on the target output. The second goal is to keep the discovered circuit sparse, so that only a small number of important attention heads are selected. These objectives are combined into the following loss:
L=Logits Δℓmasked−ℓbaseline+Sparsity Lossλ⋅∣H∣1i=1∑∣H∣σ(li).In this formulation, ℓmasked represents the relevant logits when the learned masks are applied, ℓbaseline represents the relevant logits under the corresponding baseline setting, and Δlogits captures the effect of disabling the selected heads. The sparsity term penalizes using too many active heads, where ∣H∣ is the total number of candidate heads, li is the mask logit for head i, and λ controls the strength of the sparsity penalty. By optimizing this objective, the method learns a compact set of heads whose contribution is strongly associated with contextual entrainment.
The training procedure treats the original transformer parameters as fixed and learns the mask logits li for the attention heads. The method is applied to each task configuration separately, allowing the discovered head set to reflect the structure of that specific entrainment setting. In the reported setup, the authors use Llama 3.1 8B, which contains 1024 attention heads organized into 32 layers with 32 heads per layer. Each relation type is divided into training, development, and test splits with proportions of 80%, 10%, and 10%, respectively.
The head masks are optimized on the training set over 500 epochs. During this process, multiple checkpoints are considered, and the final set of entrainment heads is selected using both performance and parsimony. The selected checkpoint is the one that shows the strongest entrainment suppression effect while using the fewest active heads. The resulting entrainment heads are then evaluated on the held out test set, which is not used for mask optimization, hyperparameter search, or checkpoint selection.
Experiment
The experiments evaluate several language models on relation prompting with related, irrelevant, random, and counterfactual contexts, measuring how these contexts change logits and probabilities for distracting, correct, and counterfactual tokens. Results show that models consistently favor tokens appearing in context, even when the context is random, indicating a mechanistic contextual entrainment effect, while semantic content modulates the effect, with counterfactual contexts causing stronger distraction. Further interventions identify task-specific attention heads whose removal substantially suppresses entrainment with little loss to factual recall or in-context learning, supporting the conclusion that contextual entrainment is a separable internal mechanism amenable to targeted mitigation.
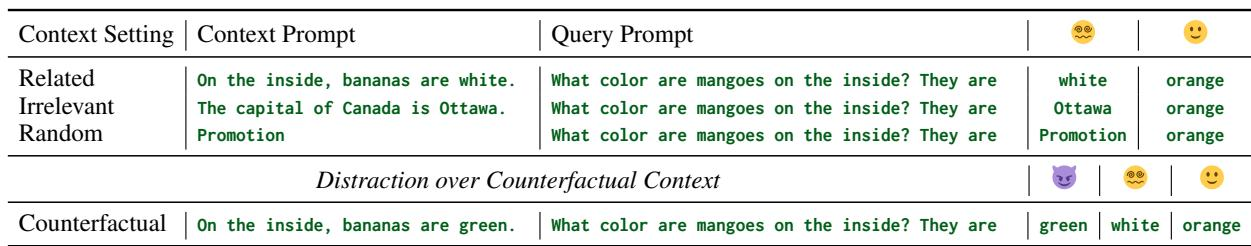
The prompt setup combines context facts with a factual query to test how different context types influence the answer space. It contrasts related, irrelevant, random, and counterfactual contexts, marking correct, distracting, and counterfactual target tokens for each query. Related contexts share the same relation type as the query, while irrelevant contexts use a different relation and random contexts use a single token. Counterfactual contexts introduce an altered fact that supports a target token competing with the factual answer.
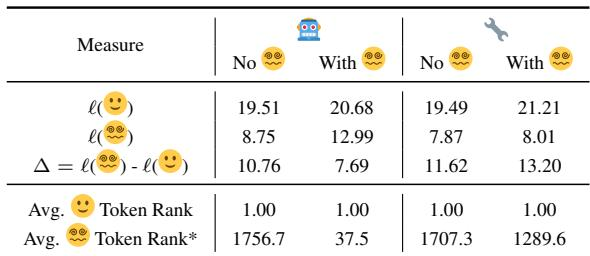
Removing the identified entrainment heads substantially weakens the influence of distracting counterfactual context in the country-capital-city setting. The correct answer remains top ranked, while distracting tokens move much lower in the token distribution and are separated from the correct answer by larger logit margins. This suggests that entrainment heads specifically support contextual distraction rather than general factual recall. Turning off entrainment heads attenuates contextual entrainment in the country-capital-city test set. Distracting answer tokens fall sharply in rank after the heads are removed. Logit differences between correct and distracting tokens increase by a large margin. The observed effect is reported as statistically significant under paired tests.
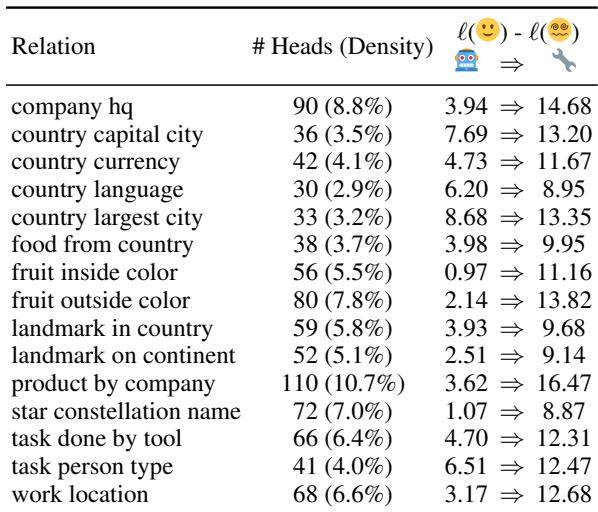
A small set of attention heads across several LRE relations can greatly widen the logit gap between correct and distracting tokens when their outputs are disabled. The effect appears for varied relations, but the number and selection of heads change by relation, indicating relation-specific entrainment rather than a fixed model-wide set. Removing these heads mainly reduces contextual entrainment while leaving factual recall and in-context learning largely intact. Disabling identified heads substantially attenuates distraction and increases correct-token logit margins. Different LRE relations require different numbers of entrainment heads, suggesting task-specific mechanisms. The heads have a relatively isolated effect, with only small impact on other language-model capabilities.
Removing the country-capital entrainment heads leaves performance on other relations broadly unchanged. Accuracy remains high under both strict and credulous evaluation, with only minor shifts between the original model and the modified model. The results suggest that these heads mainly affect entrainment rather than general factual recall. Accuracy on other relations remains high after head removal. Strict and credulous results show no clear large drop. Country-capital performance remains perfect. Other factual capabilities are only slightly affected.
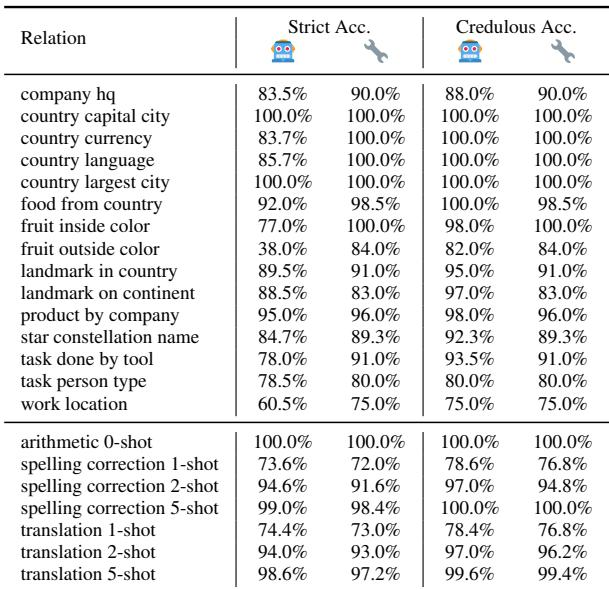
The experiments use prompts that pair factual queries with related, irrelevant, random, and counterfactual contexts to examine how context influences answer predictions. Removing a small, relation-specific set of attention heads sharply weakens the model’s susceptibility to distracting or counterfactual context, increasing the separation between correct and competing tokens. These effects are observed across several relation types while largely preserving factual recall and other language capabilities, indicating that the heads primarily mediate contextual entrainment rather than core knowledge.