Command Palette
Search for a command to run...
指示追従能力を考慮した大規模言語モデルの構成的一般化能力の再検討
指示追従能力を考慮した大規模言語モデルの構成的一般化能力の再検討
Yusuke Sakai Hidetaka Kamigaito Taro Watanabe
概要
CommonGenに代表される生成的常識推論タスクでは、生成型大規模言語モデル(LLM)は与えられた全概念を含む文を生成する。しかし、指示追従能力に焦点を当てると、プロンプトで概念の順序が指定された場合、LLMは指定された順序に従う文を生成しなければならない。この課題に対応するため、我々はLLMの構成的一般化能力と指示追従能力を評価するためのベンチマークとしてOrdered CommonGenを提案する。本ベンチマークは順序カバレッジを測定し、概念が指定された順序で生成されているかを確認することで、両能力の同時評価を可能にする。36のLLMを用いた包括的な分析の結果、LLMは一般的に指示の意図を理解しているものの、特定の概念順序パターンへのバイアスにより、概念順序を変えても出力の多様性が低くなるか、同一の結果が得られることが明らかになった。さらに、最も指示追従性が高いLLMであっても順序カバレッジは約75%に留まり、指示追従能力と構成的一般化能力の両方における改善が必要であることが示された。
One-sentence Summary
Researchers at Nara Institute of Science and Technology propose Ordered CommonGen, a benchmark that uses ordered coverage to simultaneously evaluate compositional generalization and instruction-following abilities of LLMs, and their analysis of 36 models reveals that concept-order biases cause low-diversity outputs with even the best model achieving only ∼75% ordered coverage.
Key Contributions
- Ordered CommonGen extends CommonGen by requiring generated sentences to include a four-concept set in a specified order, using ordered coverage to evaluate compositional generalization and instruction following together.
- The benchmark creates permutations of unique four-concept sets and appends the phrase “in the specified order” to instruction templates, enabling systematic assessment of whether LLMs respect arbitrary concept orders rather than only unordered inclusion.
- Experiments with 36 LLMs show that models understand instruction intent but bias toward frequent concept-order patterns, causing low-diversity or identical outputs, and even the most instruction-compliant model achieves only about 75% ordered coverage.
Introduction
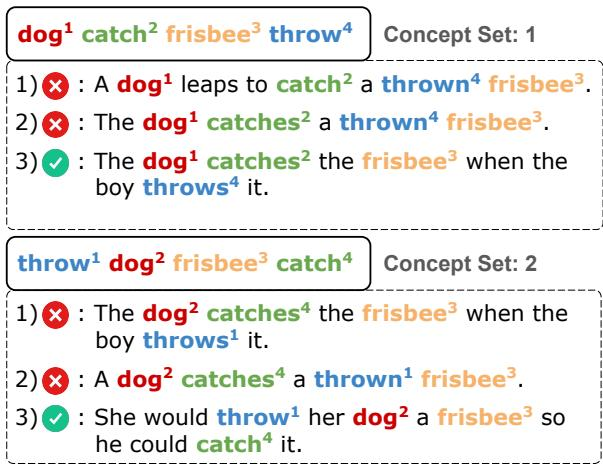
Instruction-following LLMs matter for creative generation because changes in wording or order can alter meaning in tasks such as chronology, planning, lyrics, and advertisements. Prior generative commonsense reasoning benchmarks largely measured coverage, meaning models could satisfy the prompt by including all concepts in any order, which hides their ability to obey a specific concept sequence. The authors leverage CommonGen to propose Ordered CommonGen, a benchmark that permutes concept sets and adds the instruction to follow the specified order. This setup tests compositional generalization and instruction following together, and the authors’ benchmark of 36 LLMs finds limited order control, with the best model reaching about 75% adherence and showing biases toward familiar patterns.
Dataset
-
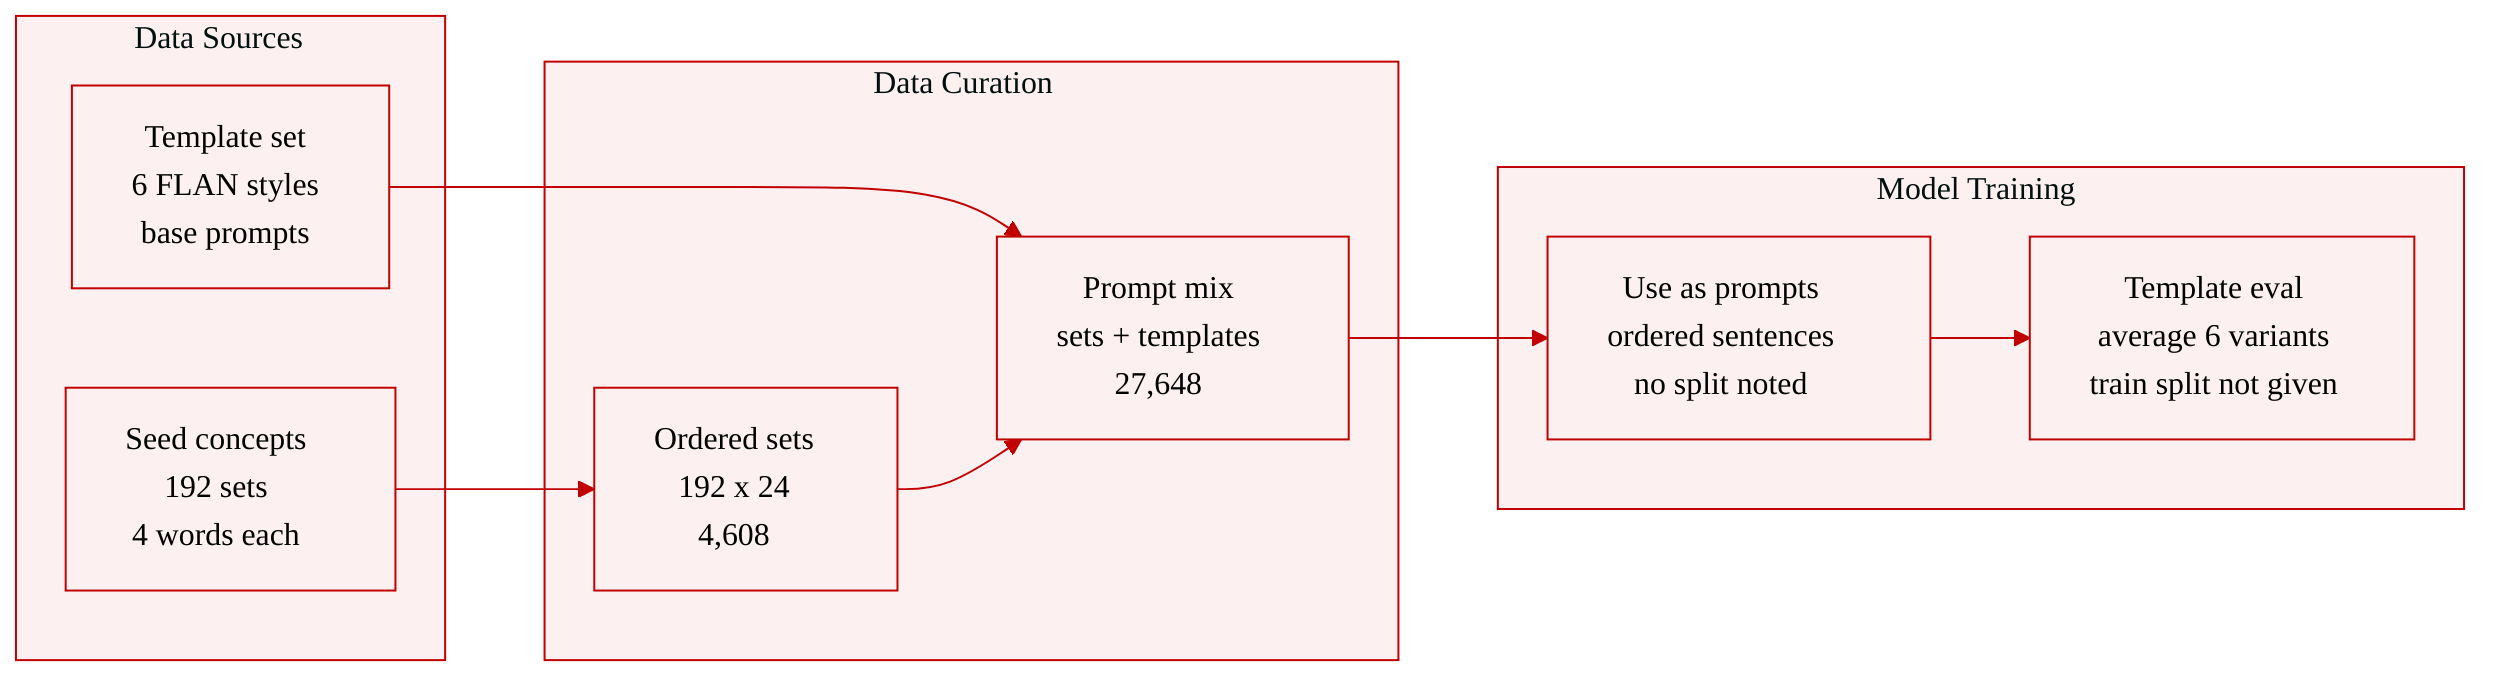
The authors construct the Ordered CommonGen dataset from two components: concept sets that act as seeds for sentence generation and instruction templates that format these seeds as prompts for LLMs.
-
The seed concepts come from CommonGen-lite, a subset of the CommonGen test data. The authors extract all 192 seed concept sets, where each set contains four concepts.
-
They expand each four-concept set into all possible orderings, giving 4! = 24 permutations per seed set. This produces 192 × 4! = 4,608 ordered concept sets.
-
Instruction templates are curated from FLAN, specifically the six manually created FLAN templates associated with CommonGen.
-
The authors modify the base templates by appending the phrase “in the specified order,” so that LLMs are instructed to generate sentences using the concepts in the given order.
-
Combining the six modified instruction templates with the 4,608 ordered concept sets yields 6 × 4,608 = 27,648 instances.
-
The resulting dataset is used as LLM input prompts. The six template variants also allow the evaluation to account for template performance variance by averaging scores across templates.
-
The provided text does not specify a train-validation-test split, mixture ratios, or additional filtering beyond the fixed seed set, permutations, and template construction.
Experiment
Across 36 instruction tuned LLMs, Ordered CommonGen evaluates whether explicitly specified concept order improves order sensitive generation, measuring concept coverage, order adherence, naturalness, and diversity across permutation templates. The results show that explicit order instructions generally increase concept order compliance and syntactic diversity while only modestly degrading naturalness, although many models still omit concepts or produce non compliant outputs. Further analyses validate that verb heavy concept sets, prompt phrasing, and one-shot priming strongly affect behavior, with learned natural word patterns often overriding specified order, though the strongest models can partially adapt their generation to the instruction.
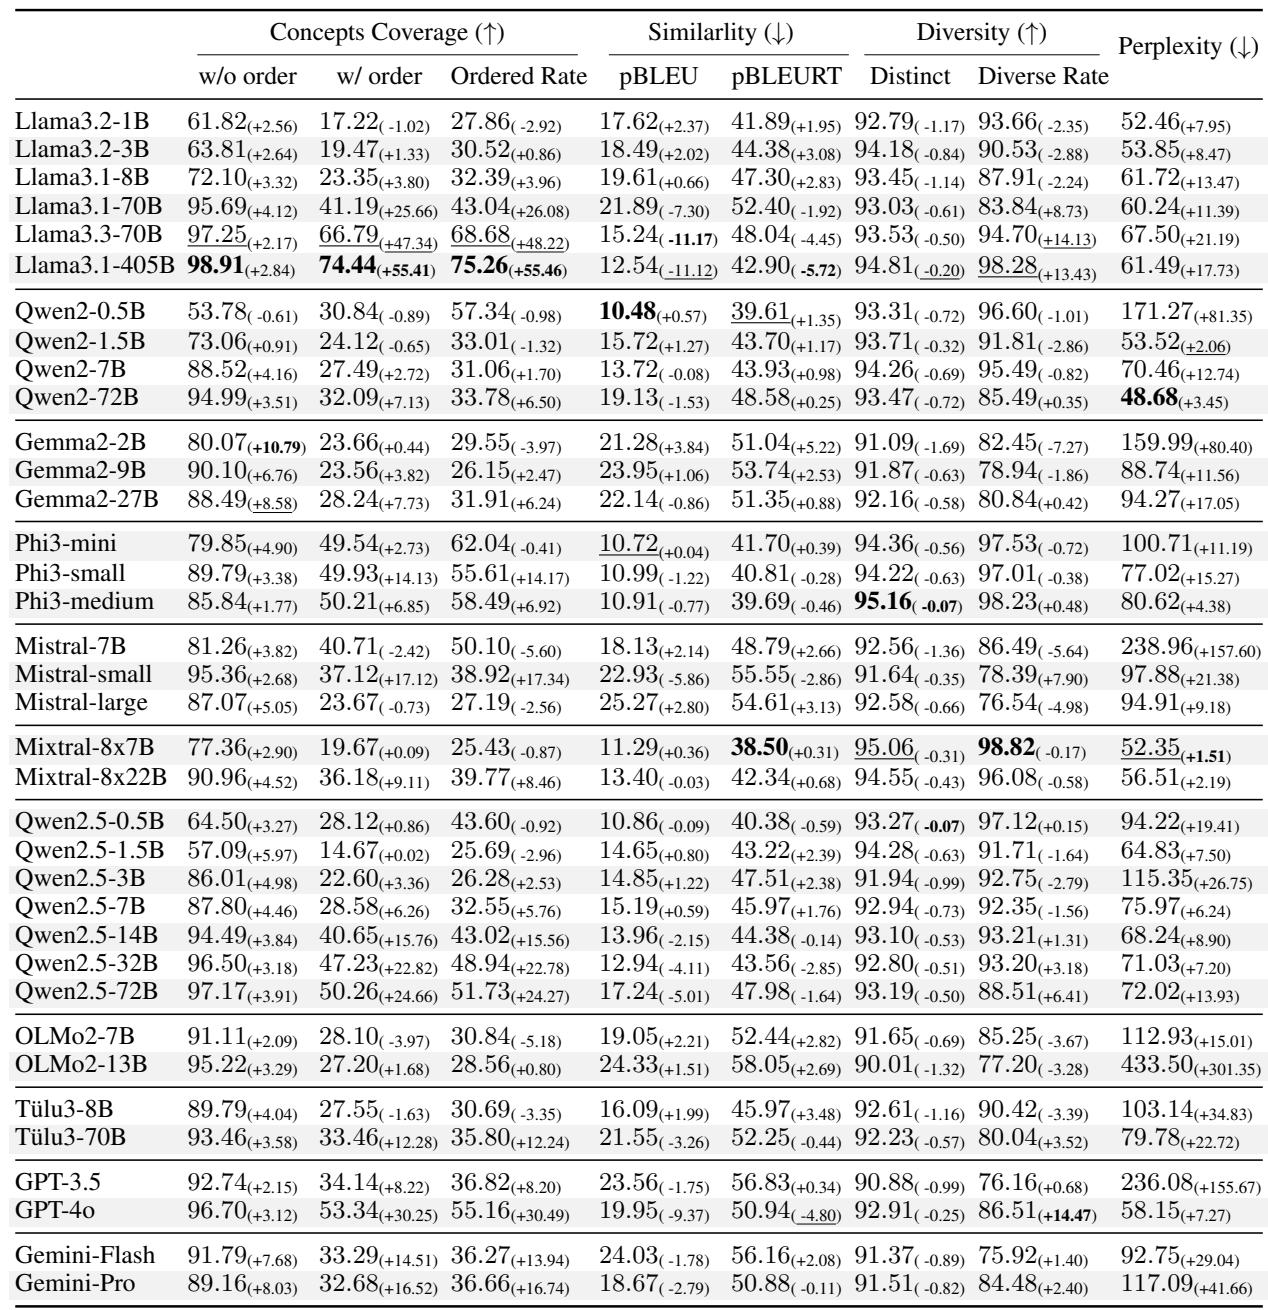
Specifying the concept order generally increases concept coverage and ordered compliance for the evaluated Llama models, with the largest variants showing the clearest gains. Smaller Llama variants follow the requested order less reliably, and ordering can introduce modest changes in related generation quality or diversity metrics. Overall, the main observed trend is stronger instruction following when explicit order information is added to the prompt. Larger Llama models achieve much stronger ordered concept coverage when concept order is specified. Smaller Llama models gain less from ordering instructions and may regress in ordered-rate scores.
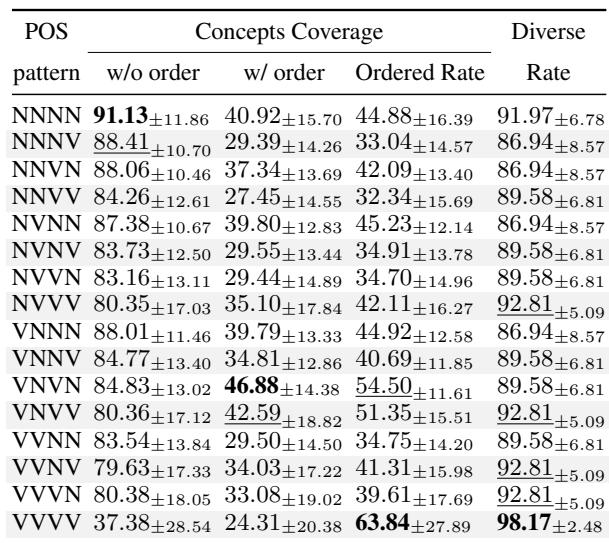
In noun only POS patterns, LLMs achieve the highest concepts coverage, indicating easier inclusion of common objects. In verb only patterns, coverage falls substantially and variability rises, while ordered and diverse rates are highest, revealing a tradeoff between coverage reliability and controlled diversity. Noun only concept sets yield the highest concepts coverage across models. Verb only concept sets show the lowest concepts coverage and the greatest variability, despite reaching the highest ordered and diverse rates.
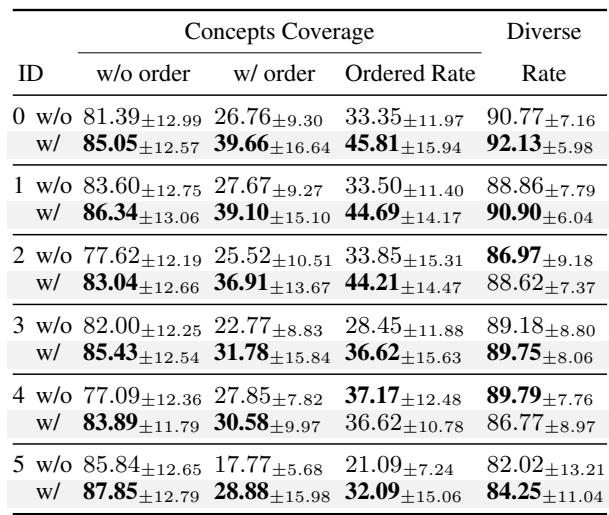
Prompt phrasing affects instruction following across multiple large language models. Adding the phrase that specifies the required order generally improves average performance on Concepts Coverage, Diverse Rate, and Ordered Rate, but the gains vary by prompt template and are not uniform for every model. Large score ranges indicate that no single prompt consistently produces the best results. Specifying the order in the prompt generally leads to higher average Concepts Coverage than omitting it. The order specification also tends to increase Diverse Rate across the tested prompts. Ordered Rate improves with the order phrase in most cases, but the effect is not always consistent. Performance differences remain across prompt templates, making it difficult to identify a universally best prompt.
In the ideal one-shot priming evaluation, ordered concept coverage improves most for larger well-instructed Llama models, while several smaller models lose ordered accuracy. Most models improve when concept order is not required, but diversity falls and similarity increases, showing that the example makes outputs more formulaic. The results suggest that one-shot patterns can guide instruction following but often suppress varied sentence generation. Ordered concept coverage rises for Llama3.3-70B and Llama3.1-405B but falls for several other models. Unordered concept coverage improves for most models, while diversity and similarity trends show more monotonic outputs.
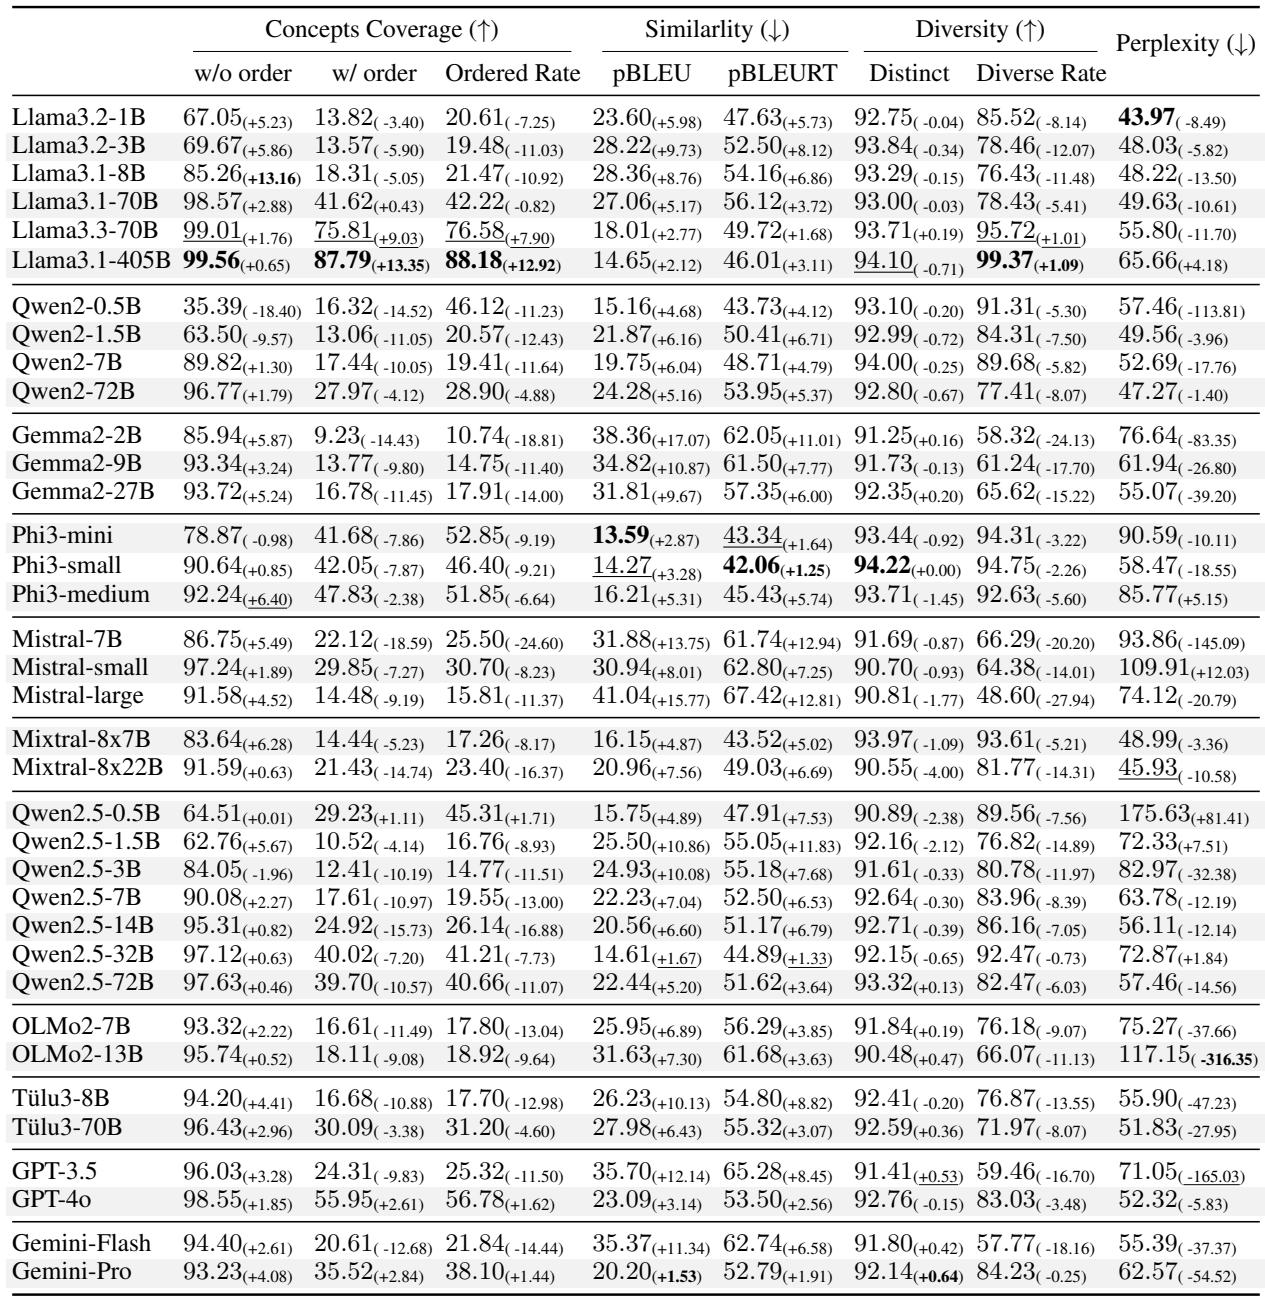
Experiments evaluate how explicit concept-order instructions, concept-set part-of-speech patterns, prompt phrasing, and one-shot priming affect instruction following in Llama models. Adding order information generally improves concept coverage and ordered compliance, especially for larger models, while smaller models respond less reliably and may show tradeoffs in diversity or quality. Concept composition also matters: noun-based sets are easier to cover, whereas verb-based sets are less reliable but can yield more ordered and diverse outputs. Overall, explicit structure and priming can strengthen ordered control, but benefits are model-dependent and often come with reduced diversity or less consistent generation quality.