Command Palette
Search for a command to run...
LLM MapReduce:大規模言語モデルを用いた簡素化された長文シーケンス処理
LLM MapReduce:大規模言語モデルを用いた簡素化された長文シーケンス処理
概要
本稿では、大規模言語モデル(LLM)が長文を効果的に処理できるようにする、トレーニング不要のフレームワークを提案する。このフレームワークは、文書全体を包括的に理解するための分割統治戦略を採用している。提案するLLM MapReduceフレームワークは、文書全体を複数のチャンクに分割してLLMに読み取らせ、その中間出力を集約して最終的な応答を生成する。分割統治型の長文テキスト処理フレームワークにおける主な課題は、文書分割によって重要な長距離情報が失われるリスクであり、その結果、モデルが分割されたテキストに基づいて不完全または不正確な回答を生成する可能性があることである。分断された長距離情報は、チャンク間依存性とチャンク間競合の2つのカテゴリに分類できる。我々は、チャンク間依存性にうまく対処するための構造化情報プロトコルと、チャンク間競合を解決するためのコンテキスト内信頼度キャリブレーション機構を設計する。実験により、LLM MapReduceは代表的なオープンソースおよび商用の長文コンテキストLLMよりも優れた性能を発揮し、複数のモデルと互換性があることが実証された。また、本フレームワークはデータ合成エンジンとしても機能し、短いコンテキストのLLMのみを使用して高品質な長文アライメントデータを生成できる。
One-sentence Summary
Researchers from Xiamen University, Tsinghua University, and other Chinese institutions propose LLM MapReduce, a training-free divide-and-conquer framework for long-text processing that chunks documents, aggregates intermediate outputs, and introduces a structured information protocol and in-context confidence calibration to address inter-chunk dependency and conflict, outperforming representative long-context LLMs while also enabling high-quality data synthesis using only short-context models.
Key Contributions
- Introduces LLM MapReduce, a training-free divide-and-conquer framework that splits long documents into chunks for LLMs to read and then aggregates intermediate outputs, enabling processing of texts that far exceed the model's effective context window.
- Addresses the loss of long-range information from chunking through a structured information protocol for inter-chunk dependency and an in-context confidence calibration mechanism for inter-chunk conflicts, overcoming limitations in LongAgent, Chain-of-Agents, and LC-Boost.
- Outperforms representative open-source and commercial long-context LLMs, remains compatible with multiple models, and also serves as a data synthesis engine that generates the Pyramid-Align dataset using only short-context LLMs.
Introduction
Large language models are limited by fixed context windows, a constraint driven by quadratic computational costs and the scarcity of high quality long training examples, which restricts their use in tasks like long document comprehension. Prior efforts to extend context fall into two categories: training based methods that demand substantial computational resources and long data, and training free divide and conquer approaches that split text into chunks but risk breaking long range information, specifically causing inter chunk dependencies where evidence spans multiple chunks and inter chunk conflicts where evidence contradicts. The authors introduce LLM MapReduce, a training free framework that addresses these issues through a structured information protocol for aggregating chunk outputs and an in-context confidence calibration mechanism to resolve contradictions. Additionally, they extend the framework into a data synthesis engine, creating the Pyramid-Align dataset that enables an 8B model to surpass GPT-4 on long sequence benchmarks, demonstrating both performance and efficiency gains.
Dataset
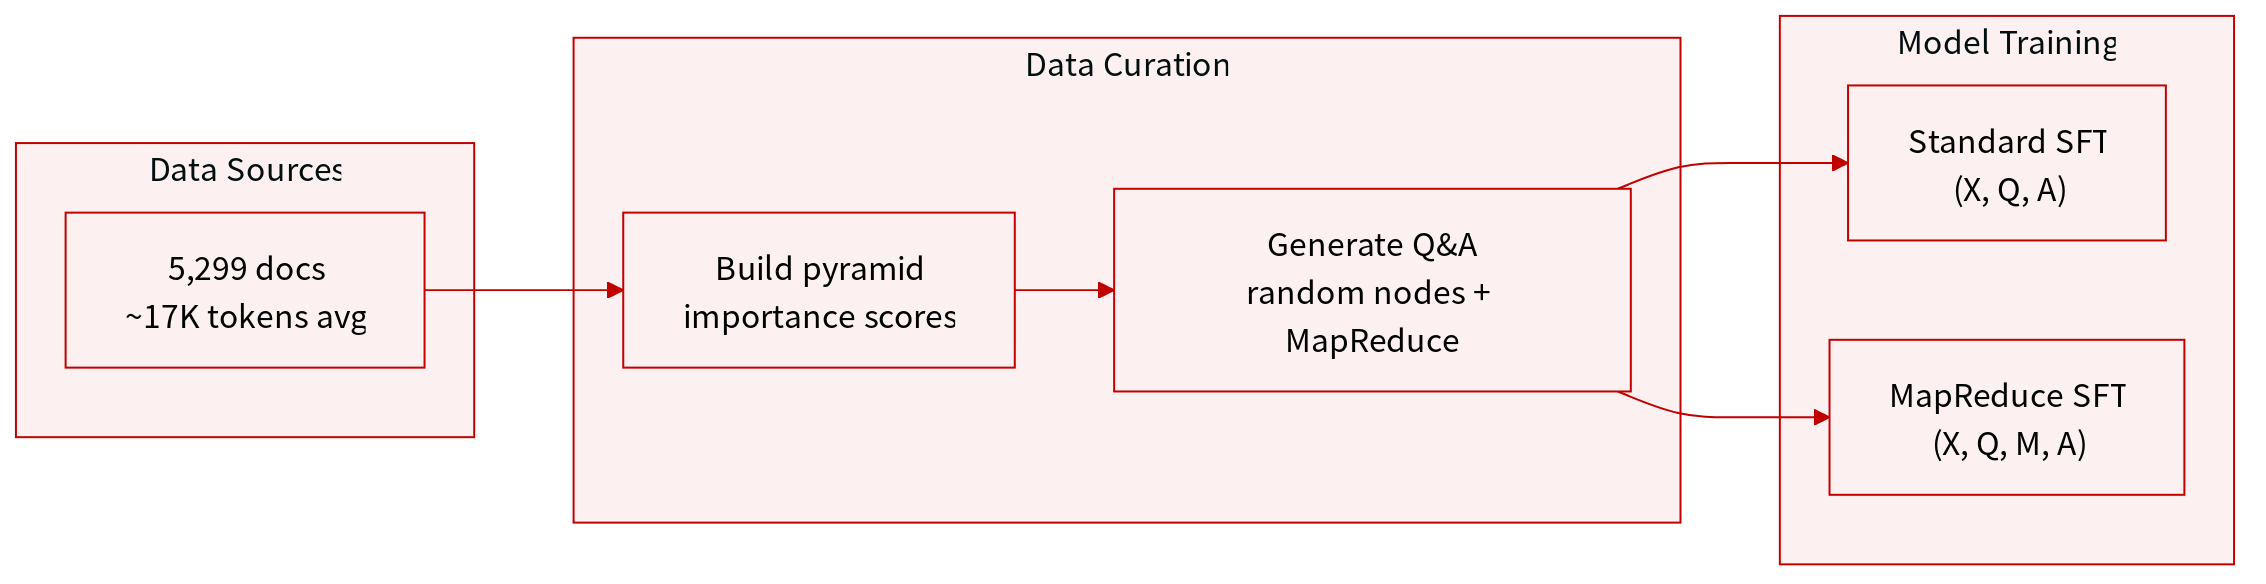
The authors introduce Pyramid-Align, a long-context supervised fine-tuning (SFT) dataset created through a divide-and-conquer approach that distills capabilities from short-context LLMs into long-context LLMs.
Dataset sources and composition
- The dataset is built from the same 5,299 English documents used in the LongAlign dataset, ensuring fair comparison between data construction methods.
- Average document length is approximately 17K tokens, with a maximum of 74K tokens.
- The final dataset contains 4,927 question-answer entries.
Pyramid construction
- Documents are abstracted into hierarchical nodes using LLMs. Each leaf node represents an individual chunk, while higher-level nodes compress information from multiple chunks.
- To form upper-level nodes, three lower-level nodes are typically combined, with the group size adjusted downward if needed to fit within the context window L.
- The number of hierarchy levels is determined dynamically by document length, ranging from 1 to 3 with an average of 1.99.
- To preserve key content in upper nodes, the authors implement a bottom-up importance propagation mechanism. Sentence-level importance scores are computed and passed upward, prompting the LLM to prioritize important sentences when summarizing.
Question and answer generation
- Questions are generated from randomly selected nodes: selecting leaf nodes mimics the IN2 approach, while selecting the root node aligns with LongAlign.
- The LLM is guided to prioritize important sentences when formulating questions, ensuring key information is considered.
- Answers are produced using an LLM MapReduce framework applied to the long document and question.
- Each dataset example is represented as (X, Q, M, A), where X is the long document, Q is the question, M contains intermediate MapReduce outputs (mapped and collapsed results), and A is the final answer.
How the data is used
- For standard long-context training, the authors train Llama3.1-8B on both LongAlign and Pyramid-Align, using standard decoding without LLM MapReduce. The model trained on Pyramid-Align outperforms the one trained on LongAlign.
- The intermediate outputs M allow a second training mode: the model is trained on (X, Q, M, A) to align with the LLM MapReduce framework. This trained 8B model outperforms GPT-4 on the evaluated tasks.
- Evaluation is conducted on four English tasks from InfiniteBench, since only English documents are used in training.
Method
The authors propose an LLM MapReduce framework designed to process documents that significantly exceed the model's effective context window. The workflow operates on a divide-and-conquer principle, comprising three sequential stages: map, collapse, and reduce. Refer to the framework diagram.
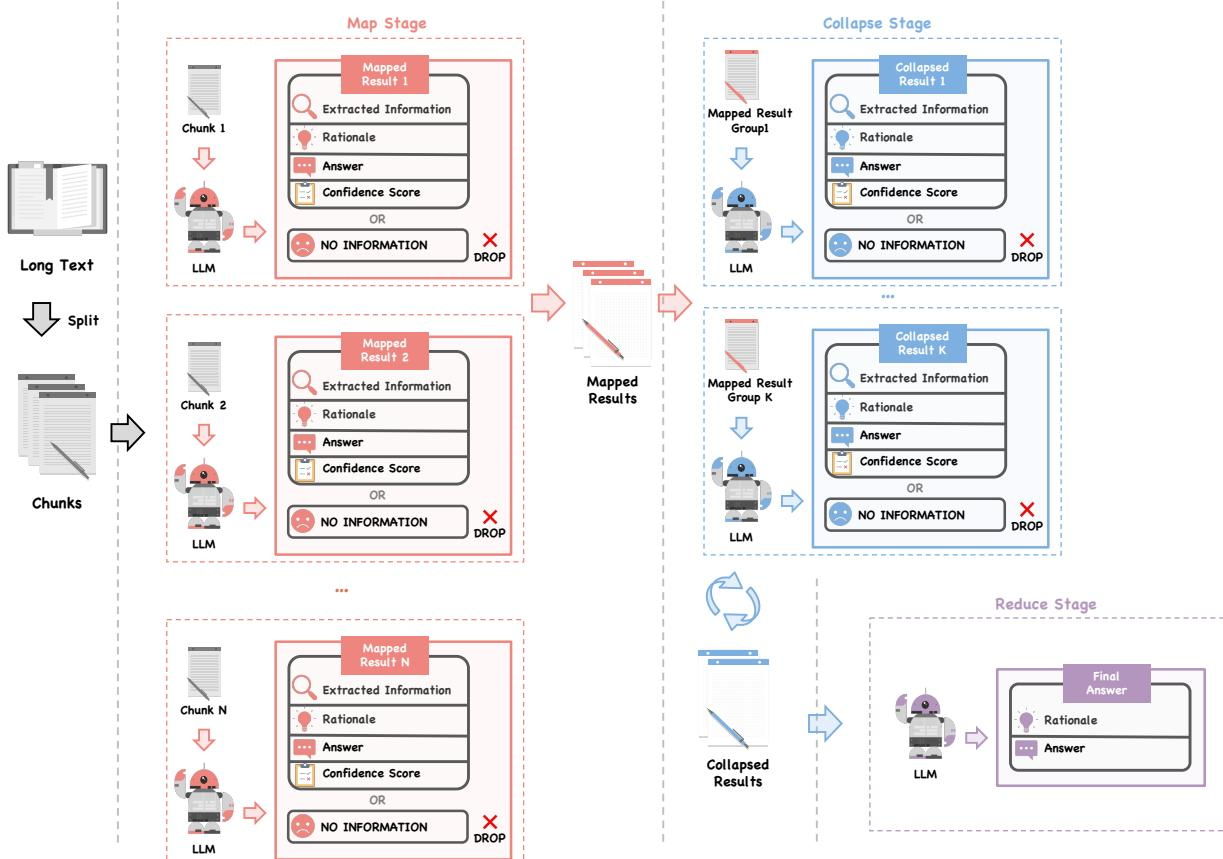
In the map stage, the input text X is partitioned into chunks {x1,x2,…,xN} based on token length and natural semantic boundaries. An LLM, parameterized by θ, processes each chunk to extract intermediate outputs defined by the map function: si=fmap(xi,Q;θ), where Q represents the user query. To ensure efficient communication between stages, the framework employs a structured information protocol rather than raw text summaries.
To address inter-chunk dependencies and conflicts, the mapped results consist of four specific components. The Extracted Information captures key facts relevant to the query. The Rationale provides the inference process, mitigating hallucination risks during aggregation. The Answer contains the intermediate response, or a "NO INFORMATION" flag if the chunk lacks relevance. Finally, the Confidence Score, ranging from 0 to 5, evaluates the completeness and reliability of the extracted information. This score is critical for resolving discrepancies in the subsequent stages.
When the volume of mapped results exceeds the context limit L, the framework enters the collapse stage. The N mapped results are grouped into K sets, and the collapse function cj=fcollapse(gj,Q;θ) compresses these groups iteratively until the output fits within the context window. The structure of collapsed results mirrors that of the mapped results. To ensure that confidence scores remain comparable across different chunks, the authors implement an in-context confidence calibration mechanism. Instead of fine-tuning model parameters, the system provides estimation principles and typical examples for various confidence levels. Refer to the calibration prompt.
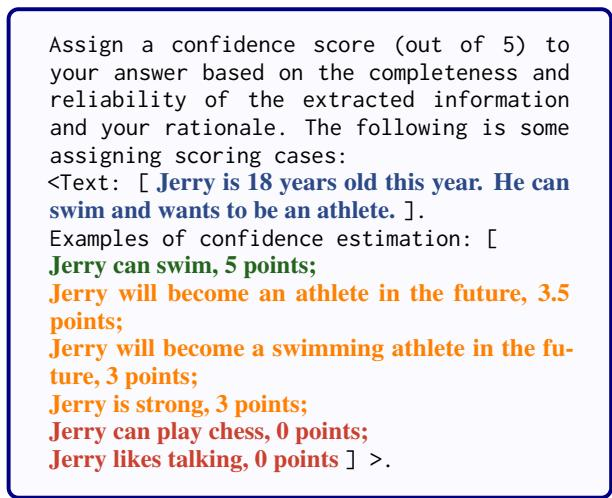
This approach guides the model to assign high confidence to claims fully supported by the text, medium confidence to inferred claims, and low confidence to unrelated information, establishing a consistent standard for conflict resolution.
Beyond inference, the divide-and-conquer architecture facilitates the distillation of long-context capabilities into short-context models through a dataset named Pyramid-Align. The construction begins by abstracting chunks into a hierarchical pyramid structure. Refer to the pyramid illustration.
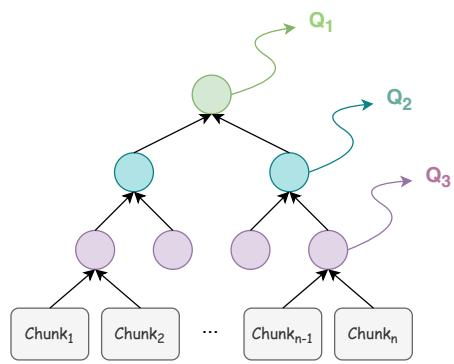
Leaf nodes represent individual chunks, while higher-level nodes synthesize content from multiple lower-level nodes. To prevent information loss as the hierarchy ascends, a bottom-up importance propagation mechanism is employed. Refer to the propagation procedure.
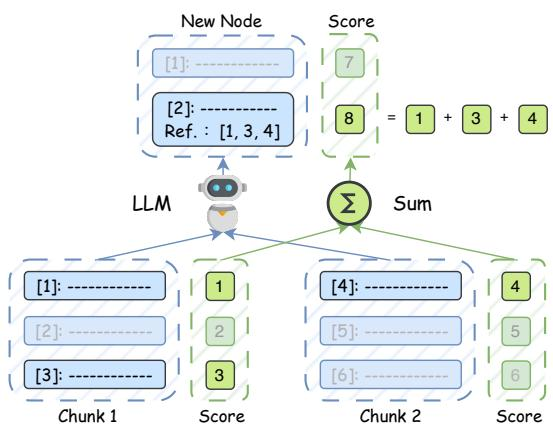
Sentence-level importance scores are calculated at the leaf level and propagated upward. When generating upper-level nodes, the LLM is prompted to prioritize sentences with higher importance scores, thereby improving information coverage. Questions are then generated by randomly selecting nodes across different hierarchy levels, ensuring the model learns to comprehend varying spans of text. Answers are derived using the LLM MapReduce framework, producing training examples in the format (X,Q,M,A), where M denotes the intermediate mapped and collapsed results. This format enables supervised fine-tuning that aligns the model's behavior closely with the MapReduce pipeline.
Experiment
The evaluation used Llama3-70B-Instruct and Qwen2-72B-Instruct on InfiniteBench, excluding two low-performing subsets, and compared against closed-source models and divide-and-conquer baselines like LongAgent and Chain-of-Agents. The proposed LLM MapReduce framework achieved the highest average accuracy across subtasks, outperforming all baselines and generalizing to both backbone models. Ablation studies showed that both the structured information protocol and in-context confidence calibration are crucial for maintaining performance, as removing either degrades results. In extremely long NIAH tests up to 1280K tokens, the framework enabled models with 8K context to handle sequences effectively, and it also proved faster than standard decoding and other divide-and-conquer methods while requiring fewer GPUs.
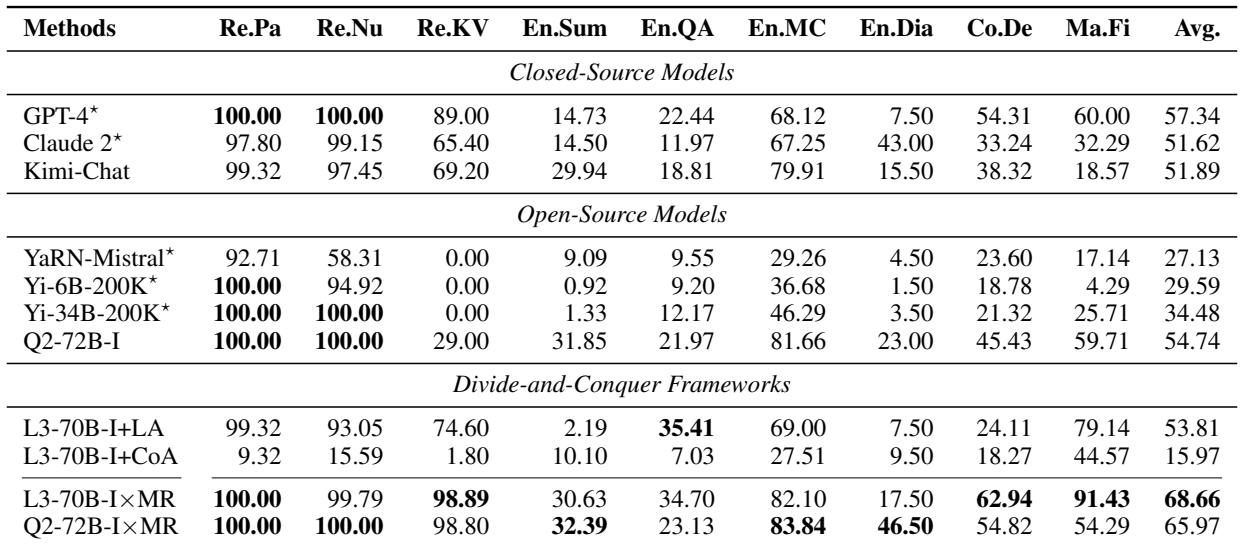
The proposed LLM MapReduce method achieves the highest average score on InfiniteBench, surpassing both closed-source models and divide-and-conquer baselines. It is compatible with multiple backbone models, including Llama3-70B-Instruct and Qwen2-72B-Instruct, and performs well across all subtasks. Among divide-and-conquer baselines, LongAgent outperforms Chain-of-Agents on nearly every subtask. The proposed method outperforms all baselines and closed-source models in average score. LongAgent achieves better results than Chain-of-Agents on nearly all subtasks. The method generalizes across different backbone models, showing strong performance with both Llama3-70B and Qwen2-72B.
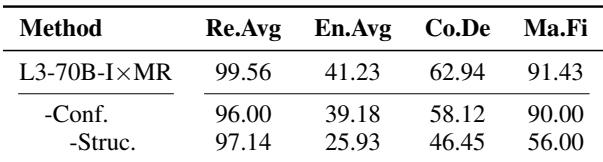
The ablation study shows that both the structured information protocol and in-context confidence calibration are essential for the LLM MapReduce framework's performance. Removing confidence calibration causes a decline across all tasks, especially in English language understanding, while disabling the structured protocol leads to an even more significant drop in performance. The full framework with both mechanisms achieves the highest average scores on retrieval and English understanding tasks compared to the ablation variants. Removing confidence calibration reduces performance on all tasks, with the most pronounced decrease in English language understanding. Disabling the structured protocol results in a much larger performance degradation, particularly in English understanding and factual or mathematical tasks.
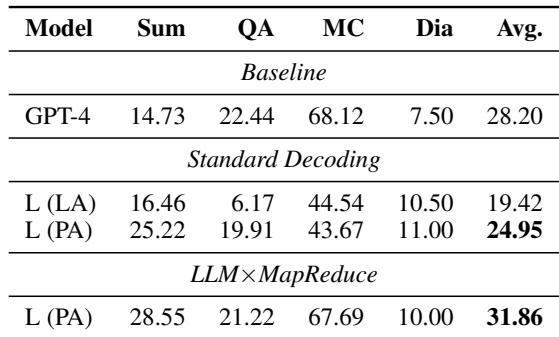
Pyramid-Align training consistently outperforms LongAlign on English tasks from InfiniteBench, particularly in summarization and question answering. Applying LLM MapReduce decoding further boosts Pyramid-Align's performance, surpassing the GPT-4 baseline on average. The results suggest that generating SFT data from varying context lengths yields stronger long-context models. Pyramid-Align improves average score over LongAlign from 19.42 to 24.95 with standard decoding. LLM MapReduce with Pyramid-Align reaches an average score of 31.86, exceeding the GPT-4 baseline of 28.20. The largest gains from Pyramid-Align are in summarization and QA tasks, with smaller changes in multiple-choice and dialogue.
The evaluation of the proposed LLM MapReduce method on InfiniteBench shows that it outperforms closed-source models and divide-and-conquer baselines, and generalizes across backbone models such as Llama3-70B and Qwen2-72B. Ablation studies confirm that both the structured information protocol and in-context confidence calibration are critical, with removing either causing performance drops, especially in English understanding and factual tasks. Additionally, Pyramid-Align training consistently improves over LongAlign on long-context English tasks, and combining it with LLM MapReduce decoding exceeds the GPT-4 baseline, highlighting the benefit of generating SFT data with varied context lengths.