Command Palette
Search for a command to run...
活動指向のRGB-熱映像におけるマルチモーダル口への手の動き認識(学生アブストラクト)
活動指向のRGB-熱映像におけるマルチモーダル口への手の動き認識(学生アブストラクト)
Glenn Fernandes Meixi Lu Farzad Shahabi Jiayi Zheng Aggelos Katsaggelos Nabil Alshurafa
概要
過食や喫煙などの健康リスク行動は公衆衛生に深刻な影響を与えるため、これらの行動のモニタリングと軽減は極めて重要である。ウェアラブルなRGB-熱画像カメラは、口への手の動き(HTM)ジェスチャを捉えることでこれらの行動をモニタリングするために用いられている。しかし、RGBまたは熱画像のいずれか単一のモダリティに依存する検出モデルは、照明条件への感度や熱画像の遮蔽など、センサ固有の制限により、食事や喫煙に関連する紛らわしいジェスチャを正確に識別することが困難な場合が多い。本研究では、食事および喫煙に関連するHTMジェスチャの認識を強化するために設計された、早期融合・決定レベル融合、および新規の中間融合アーキテクチャであるRGB-Thermal Fusion Video Network (RTFVNet)を用いた融合モデル群を提案する。評価の結果、決定レベル融合は最高F1スコア88%(0.44 TFLOPs)を達成したものの、RTFVNetは食事・喫煙・非ジェスチャ活動の分類において、性能(85%)と計算量(0.37 TFLOPs)の最適バランスを提供することが示された。
One-sentence Summary
Northwestern University proposes RTFVNet, a novel mid-fusion architecture within a family of early-, decision-, and mid-fusion RGB-Thermal models that recognizes hand-to-mouth gestures for eating and smoking monitoring in wearable footage, achieving an optimal balance between 85% F1-score and 0.37 TFLOPs computational cost.
Key Contributions
- An RGB-Thermal video dataset of 441.9 hours captured in free-living environments is provided for multi-class hand-to-mouth gesture recognition of eating, smoking, and non-gesture activities.
- A family of early-, mid-, and decision-fusion models combines RGB visual detail with thermal heat cues to distinguish confounding eating, smoking, and non-gesture hand-to-mouth gestures.
- RGB-Thermal Fusion Video Network (RTFVNet), a novel mid-fusion architecture, is presented for multi-class hand-to-mouth gesture recognition in activity-oriented camera footage; RTFVNet reaches 85% F1 at 0.37 TFLOPs, offering an optimal balance of accuracy and computational complexity compared with decision fusion at 88% F1 and 0.44 TFLOPs.
Introduction
RGB-Thermal wearable Activity-Oriented Camera systems are necklace-mounted devices that monitor health-risk behaviors such as eating and smoking from a non-egocentric perspective. This matters because reliable detection of hand-to-mouth gestures can support behavior tracking, health monitoring, and intervention. Prior work usually relied on RGB or thermal data alone, but RGB struggles in low light while thermal can be affected by ambient temperature changes and occlusions. To address these limitations, the authors contribute a large free-living RGB-Thermal video dataset, a family of fusion models for distinguishing eating, smoking, and non-gesture activities, and RTFVNet, a mid-fusion architecture designed for efficient multi-class gesture recognition.
Dataset
-
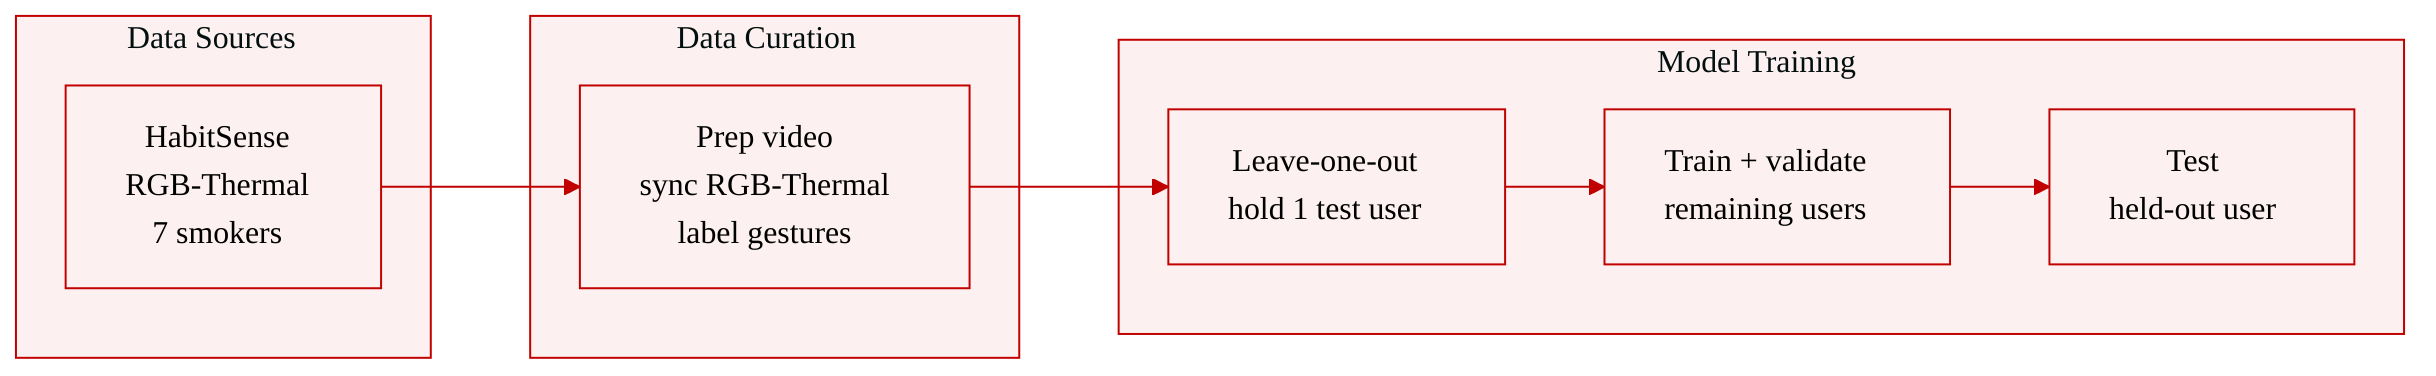
Dataset source: The authors collected the dataset using HabitSense, a neck-worn RGB-Thermal camera system designed to record activity-oriented video from the wearer’s face.
-
Dataset scale and composition: The dataset contains 441.9 hours of paired RGB and thermal video, collected from 7 smokers.
-
Modality setup: Each sample includes synchronized RGB and Thermal streams, reflecting the RGB-Thermal nature of the sensing system.
-
Annotation schema: The dataset is annotated with start and end points for eating and smoking gestures, providing temporal segment labels for these target actions.
-
Subset details: The provided text describes a single RGB-Thermal dataset rather than multiple labeled subsets, with participant information limited to the number of subjects.
-
Data usage in evaluation: The authors use the dataset for gesture recognition experiments and evaluate models using leave-one-participant-out cross-validation.
-
Training/validation strategy: Under this protocol, data from one participant are held out for testing, while the remaining participants are used for training and validation.
Method
The proposed framework uses three fusion strategies to distinguish eating, smoking, and non gesture activities from paired RGB and thermal video streams. For decision fusion, the authors train two independent TimeSformer classifiers, one on the RGB stream and one on the thermal stream, then combine their predicted class outputs. For early fusion, RGB and thermal frames are concatenated before being input into a single TimeSformer model, allowing the video transformer to process the combined visual signal from the beginning.
The core contribution is RTFVNet, a novel mid fusion architecture adapted for multiclass gesture classification. The design is inspired by RGB thermal segmentation networks, but it removes the shortcut connections that transfer thermal encoder features into the RGB encoder. This modification allows each encoder branch to specialize in extracting features from its own modality, reducing cross modal interference before fusion and improving the use of modality specific evidence.
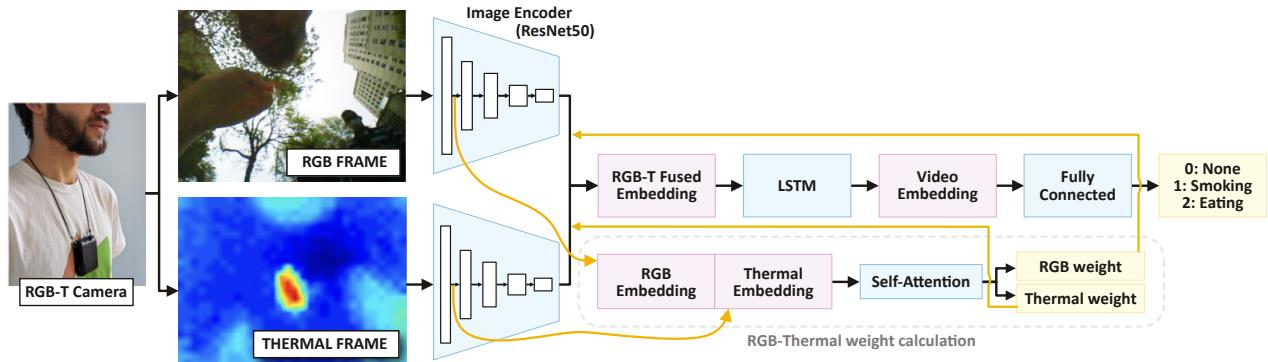
As shown in the architecture diagram:
In this module, RGB and thermal frames are first processed by separate early ResNet50 encoders. These encoders extract spatial embeddings from each modality independently. The RGB and thermal embeddings are then concatenated to form a joint representation. A self attention mechanism estimates the relative importance of the RGB and thermal streams for each frame pair. If zRGB and zT denote the latent features and wRGB and wT denote the learned modality weights, the fused representation can be expressed as:
z=wRGBzRGB+wTzTThe weighted features are then combined and passed through an LSTM layer to capture temporal dependencies across frames. A fully connected layer finally maps the resulting video embedding into three classes: none, smoking, or eating. The complete model family is trained and evaluated using leave one participant out cross validation, with performance assessed through classification metrics and computational cost.
Experiment
The experiments evaluate RGB-Thermal eating and smoking gesture recognition on a multi-participant dataset collected with a neck-worn HabitSense system, using leave-one-participant-out validation to compare single-modality and fusion approaches. These tests show that thermal and RGB streams each capture useful but incomplete cues, while decision fusion can improve accuracy at the expense of much higher computation. The proposed mid-fusion RTFVNet is validated as a more efficient alternative that retains strong recognition performance without the heavy cost of decision-level fusion.
The results compare single-modality RGB and thermal models with early, mid, and decision fusion approaches for detecting gestures. Decision fusion achieves the highest overall accuracy but has the highest computational cost, while mid fusion with RTFVNet provides a strong balance of performance and efficiency. RGB-based models generally outperform thermal-only models in the reported metrics. Decision fusion gives the best F1-score but requires about twice the compute of the single-modality models. Mid fusion with RTFVNet improves on RGB, thermal, and early fusion while using less compute than decision fusion. Thermal-only modeling has the lowest reported performance among the compared architectures.
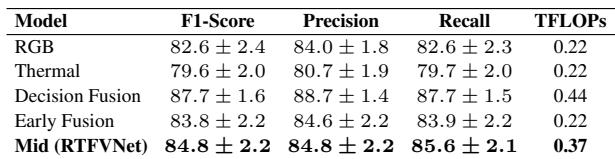
The experiments evaluate RGB, thermal, and fused models for gesture detection, comparing early, mid, and decision fusion. Decision fusion achieves the best overall accuracy and F1-score but requires roughly twice the compute of single-modality models. Mid fusion with RTFVNet provides a stronger performance efficiency balance than RGB, thermal, and early fusion, while RGB models generally outperform thermal-only models, which show the weakest results.