Command Palette
Search for a command to run...
GxVAEs: 二つの連合変分自己符号化器が遺伝子発現プロファイルからヒット様分子を生成する
GxVAEs: 二つの連合変分自己符号化器が遺伝子発現プロファイルからヒット様分子を生成する
Chen Li Yoshihiro Yamanishi
概要
生物学的活性や薬物様性を示すヒット様分子のデノボ生成は、コンピュータ支援創薬における重要な課題である。人工知能は所望の化学的特性を持つ分子を生成できるものの、従来の研究の多くは疾患関連の細胞環境の影響を考慮していない。本研究では、二つの連合変分自己符号化器(VAE)を活用し、遺伝子発現プロファイルからヒット様分子を生成する新規深層生成モデルGxVAEsを提案する。第1のVAEであるProfileVAEは、遺伝子発現プロファイルから潜在特徴を抽出する。抽出された特徴は、第2のVAEであるMolVAEがヒット様分子を生成する際の条件として機能する。GxVAEsは分子生成と生体内の細胞環境の間のギャップを橋渡しし、特定の疾患の文脈において生物学的意味を持つ分子を生成する。治療用分子の生成に関する実験およびケーススタディにおいて、GxVAEsは現在の最先端ベースラインを上回り、潜在的な生物学的活性と薬物様性を有するヒット様分子を得た。患者の疾患プロファイルから、様々な疾患に対する治療的効果を持つ可能性のある分子構造を成功裏に生成することができた。
One-sentence Summary
Nagoya University proposes GxVAEs, a deep generative model that leverages two joint variational autoencoders, ProfileVAE and MolVAE, to bridge molecular generation and cellular environments by generating hit-like molecules with bioactivity and drug-like properties directly from gene expression profiles, outperforming state-of-the-art baselines in therapeutic molecule generation.
Key Contributions
-
GxVAEs is a deep generative model composed of two joint variational autoencoders, ProfileVAE and MolVAE, designed to generate hit-like molecules from gene expression profiles.
-
ProfileVAE extracts latent features from gene expression profiles, and MolVAE uses those features as conditioning signals to produce biologically meaningful molecules in disease-specific cellular contexts.
-
Experiments and case studies show that GxVAEs outperform current state-of-the-art baselines, yield hit-like molecules with potential bioactivity and drug-like properties, and generate candidate therapeutic molecular structures from patients’ disease profiles.
Introduction
Hit identification seeks molecules with desired bioactivity within an enormous chemical space, but traditional high throughput screening is slow, costly, and has low hit rates, while de novo AI generation can create molecules but often optimizes chemical properties without considering cellular disease context. Gene expression and other omics data can capture disease related cellular responses, yet high quality omics data is limited, integrating such data is complex, and earlier hit like generation methods produce molecules with low validity, weak ligand target association, or only partial use of expression profiles. The authors leverage two joint variational autoencoders, ProfileVAE and MolVAE, to extract features from gene expression profiles and use them as conditions to generate hit like molecules, thereby connecting molecular generation with disease specific biological context and outperforming prior baselines.
Dataset
-
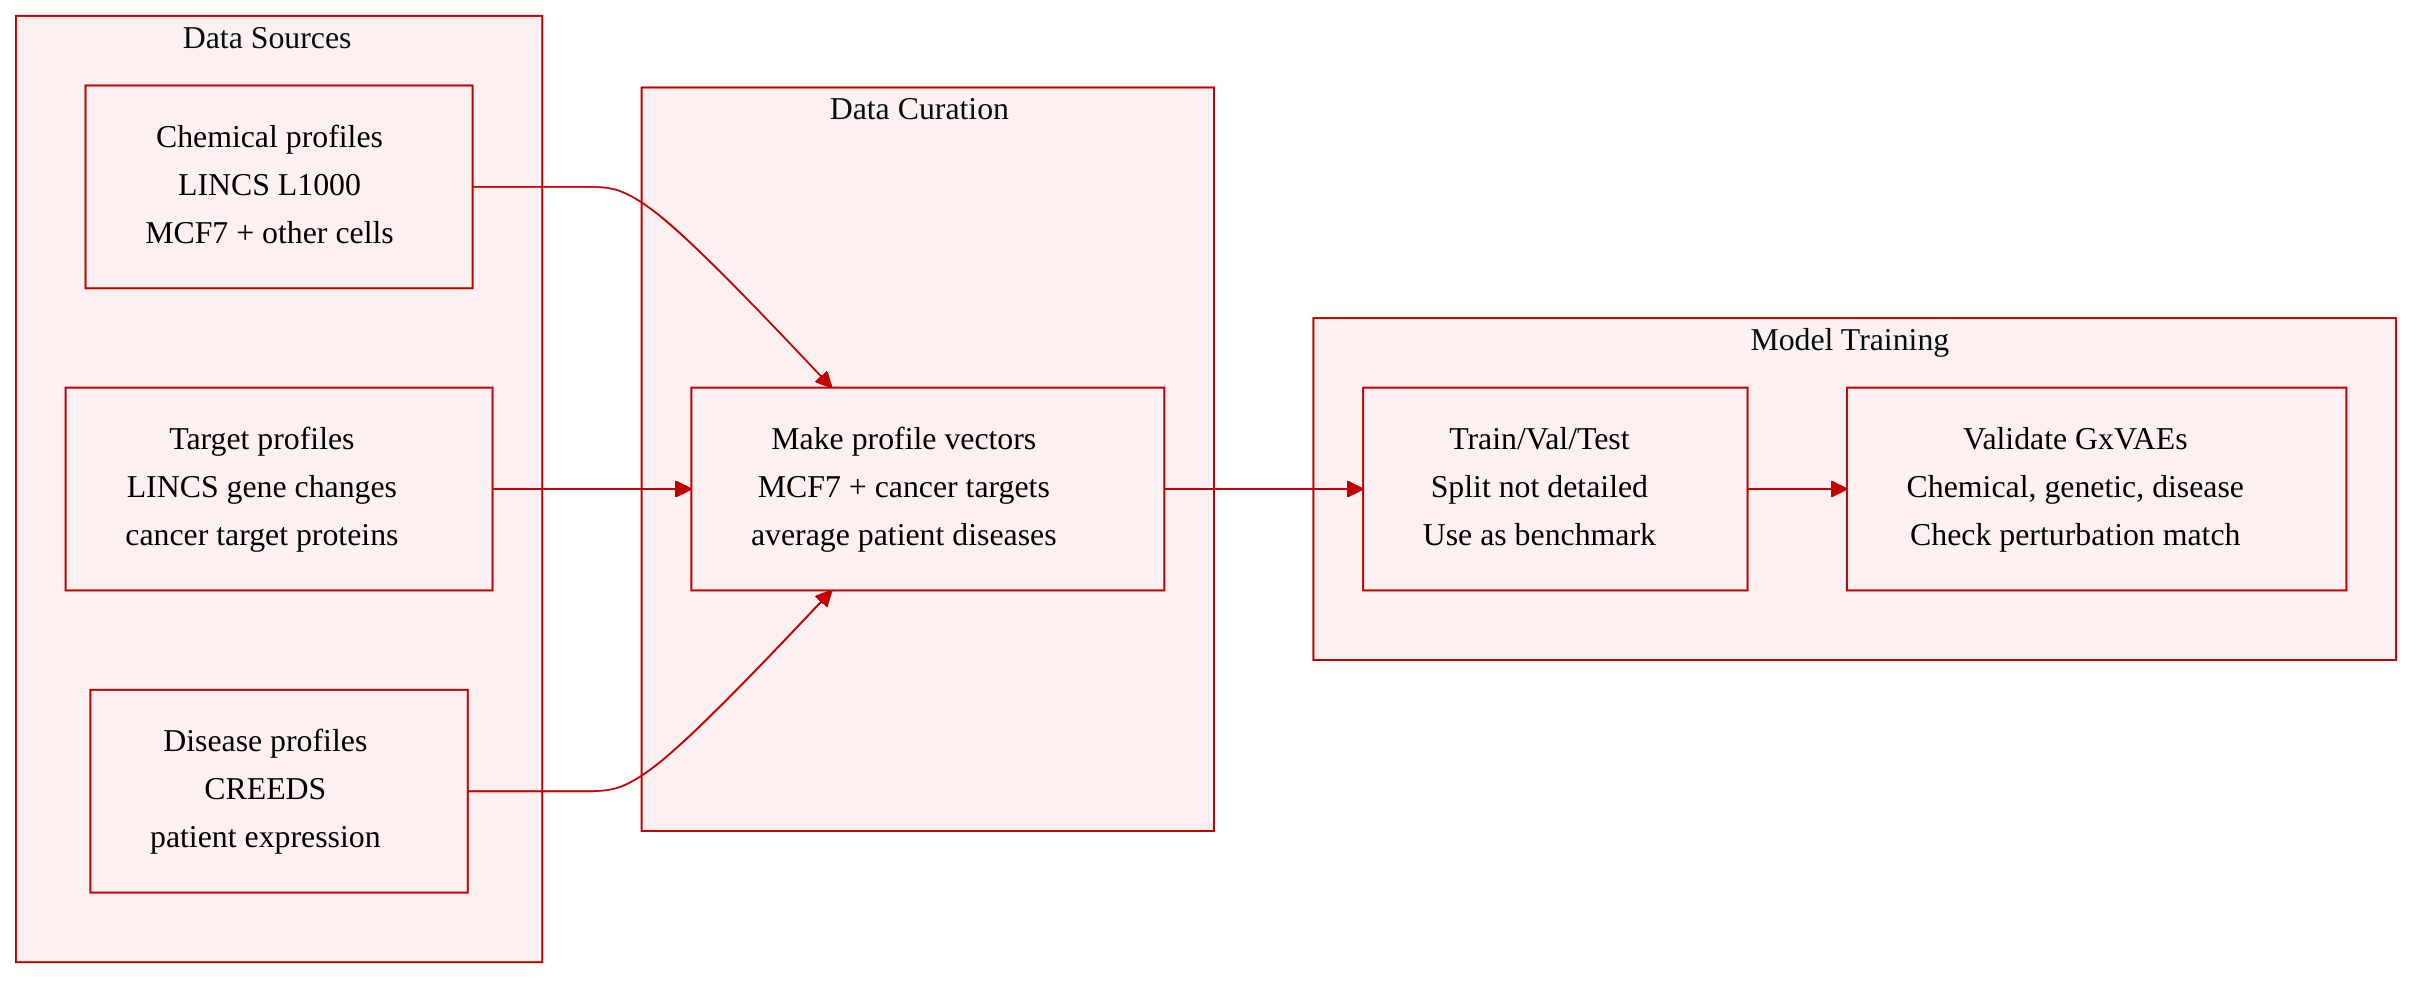
The authors build the evaluation data from three types of gene expression profiles used to test the GxVAEs:
- Chemically induced profiles: taken from the LINCS L1000 database, with chemical perturbations represented by expression profiles of 77 human cell lines; the paper focuses on the MCF7 cell line treated with 13,755 molecules.
- Target perturbation profiles: taken from the LINCS database, representing gene knockdown or overexpression of target proteins across the same 77 human cell lines.
- Disease-specific profiles: taken from the CREEDS database, representing diseases by expression profiles containing 14,804 genes; examples include gastric cancer, atopic dermatitis, and Alzheimer’s disease.
-
Key dataset details:
- Chemical subset scale: 13,755 MCF7 perturbation profiles.
- Target subset filtering: uses the same target proteins as earlier studies for fair comparison, including AKT1, AKT2, AURKB, CTSK, EGFR, HDAC1, MTOR, PIK3CA, SMAD3, and TP53.
- Disease subset construction: gene expression profiles are averaged across multiple patients to form a single profile for each disease.
-
Schema and representation:
- Each sample is represented as a gene expression profile, effectively a vector over measured genes.
- Chemical perturbation data connect expression profiles to compound treatments, while target perturbation data connect expression profiles to genetic perturbations of specific therapeutic proteins.
- Disease profiles aggregate patient-level expression signals into disease-level profiles.
-
How the authors use the data:
- The three profile types are used to validate the proposed GxVAEs across chemical, genetic, and disease perturbation settings.
- The target perturbation subset is filtered by known cancer-related proteins to align with previous methods.
- The paper does not report a detailed train/validation/test split, so the described datasets primarily serve as benchmark inputs for model evaluation.
Method
The authors leverage a two-stage joint VAE architecture called GxVAEs. The system connects a gene expression representation module with a molecule generation module. ProfileVAE acts as a feature extractor that compresses high-dimensional gene expression profiles into compact latent vectors. MolVAE then uses those latent vectors as conditions to generate molecule strings. Refer to the framework diagram.
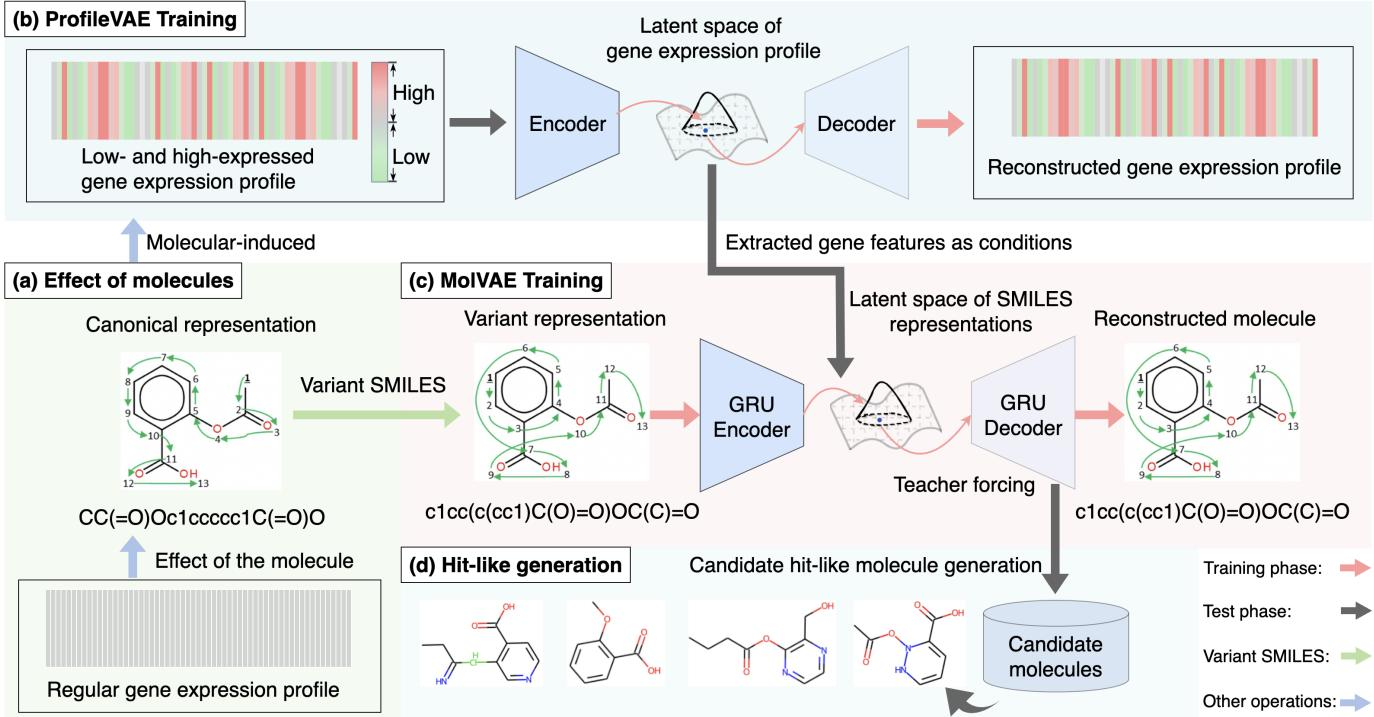
ProfileVAE is trained on gene expression profiles. A profile containing K genes is represented as X=[x1,x2,…,xK], where xk denotes the expression value of the k-th gene. The encoder maps X to a latent variable C, and the decoder reconstructs X from C. The intended objective is to maximize the marginal likelihood of the profile:
θ,ϕmaxEqθ(C∣X)[logpϕ(X∣C)].The corresponding variational loss combines reconstruction and regularization:
LG(θ,ϕ)=Eqθ(C∣X)[logpϕ(X∣C)]−βDKL(qθ(C∣X)∥pϕ(C)).Here β controls the weight of the KL divergence term. During inference, the latent vector is sampled with the reparameterization trick:
C=μ+σϵ,ϵ∼N(0,I),where μ and σ are the predicted mean and standard deviation of the latent Gaussian distribution.
MolVAE generates molecules represented as SMILES strings. Let S=[s1,s2,…,sT] denote a SMILES sequence of length T. The decoder models the molecule as an autoregressive sequence conditioned on the molecular latent variable Z and the gene expression feature C:
pφ(S∣Z)=t=1∏Tpφ(st∣s1:t−1,Z,C).MolVAE optimizes the variational lower bound for molecule reconstruction:
LS(φ,ψ)=Eqψ(Z∣S)[logpφ(S∣Z,C)]−DKL(qψ(Z∣S)∥pφ(Z)).The molecular sequence part uses bidirectional GRU structures. During training, the authors employ variant SMILES, which are non-canonical serializations of the same molecular graph. Because a molecule can be traversed from different starting atoms, multiple valid SMILES strings can represent the same structure. This diversity in the training targets helps encourage diverse generated molecules.
Teacher forcing is used during MolVAE training. At each decoding step, the model is provided with the ground-truth prefix s1:t−1 instead of relying on the model’s own previous outputs. This reduces error accumulation, stabilizes learning, and accelerates convergence.
The full workflow follows a staged pipeline. First, ProfileVAE is trained and only its encoder is retained. The encoder extracts the gene expression feature C from a given profile. Next, MolVAE is trained by conditioning on C while using the corresponding SMILES sequence as the target. After MolVAE training, only its decoder is retained. The final generation model combines the ProfileVAE encoder with the MolVAE decoder. At inference time, an unknown gene expression profile is passed through ProfileVAE encoder to obtain C, and MolVAE decoder generates molecule strings conditioned on that feature vector.
Experiment
Experiments used chemically induced, target perturbation, and disease-specific gene expression profiles from LINCS and CREEDS to assess molecule generation by GxVAEs. Profile reconstruction and molecular generation tests showed that ProfileVAE preserved biological expression patterns and MolVAE produced valid, chemically plausible compounds. Additional target-protein ligand generation and disease reversal case studies demonstrated that GxVAEs generate hit-like therapeutic candidates with strong structural similarity and therapeutic relevance compared with baseline models.
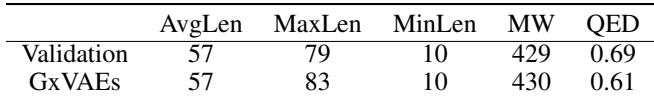
The molecules generated by GxVAEs show SMILES length and molecular weight profiles that closely match the validation set, with essentially the same average length and molecular weight and a slightly wider maximum length. Their QED scores remain comparable to validation molecules, supporting the conclusion that the model preserves key chemical property distributions while generating valid candidates. Generated SMILES have average and minimum lengths and average molecular weights nearly identical to the validation set. Maximum generated SMILES length is slightly higher than in the validation set. QED scores are somewhat lower but distributionally similar, indicating plausible chemical quality.
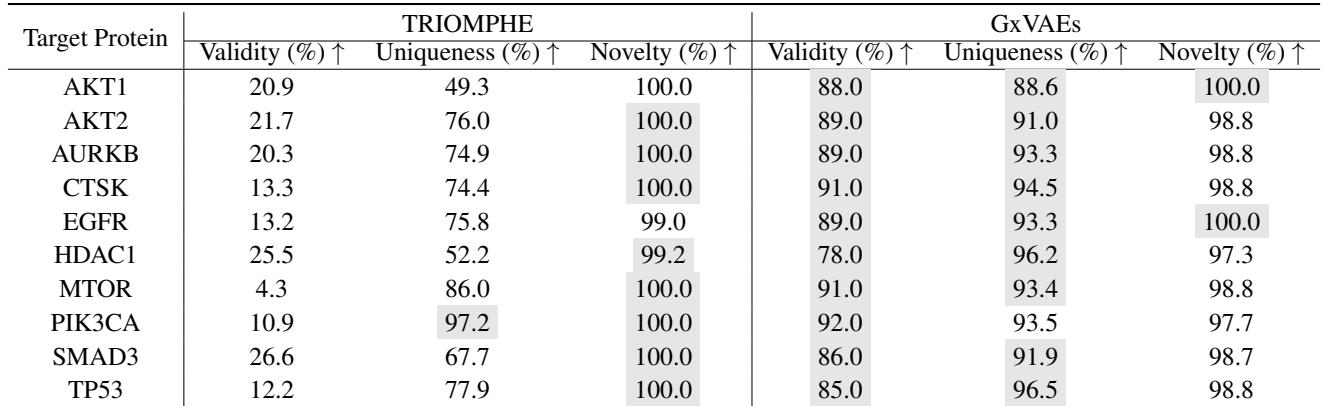
Across the reported target proteins, GxVAEs produce substantially more valid molecules than TRIOMPHE while also generating candidates with higher uniqueness. Novelty remains very high for both methods, with GxVAEs staying competitive in most cases despite not always exceeding the baseline. These results suggest that GxVAEs can use gene expression profiles to generate more usable and diverse ligand-like candidates. GxVAEs show markedly higher validity than TRIOMPHE across the evaluated targets. GxVAEs improve uniqueness while maintaining strong diversity in generated molecules. Novelty stays high for both methods, with GxVAEs matching or remaining close to the baseline in most cases.
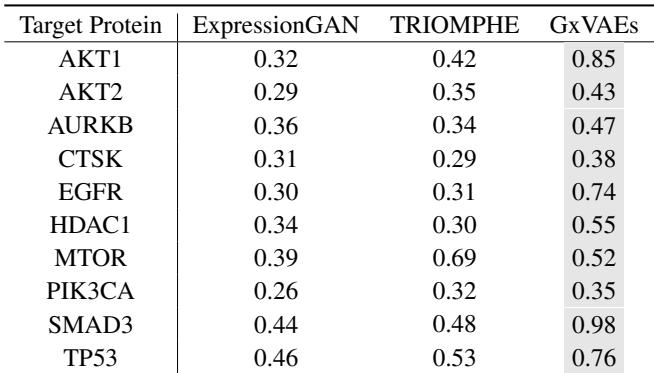
The comparison shows Tanimoto coefficients for ligand-like molecules generated by ExpressionGAN, TRIOMPHE, and GxVAEs across several protein targets. GxVAEs achieve the highest scores for most listed targets, with especially large gains on AKT1 and EGFR, while one target, MTOR, shows a lower score for GxVAEs. These patterns support the claim that GxVAEs can often generate candidate molecules with stronger structural similarity to known ligands than the compared baselines. GxVAEs produce higher Tanimoto coefficients on most listed protein targets than both baselines. The proposed model shows especially strong improvements for AKT1 and EGFR. Performance is not uniform across all targets, as MTOR shows a lower GxVAE score than TRIOMPHE.
The comparison focuses on hit-like molecules generated for known ligands across several therapeutic targets, specifically the cases with the highest structural similarity. GxVAEs generate molecules that more closely resemble the corresponding known ligands than the ExpressionGAN and TRIOMPHE baselines in the shown target examples. This suggests more consistent preservation of ligand-like structural features across the compared targets. GxVAE molecules are shown to be structurally closer to known ligands than those generated by the two baselines. The comparison covers multiple therapeutic targets, including AKT1, AKT2, EGFR, and MTOR. The highlighted examples represent the highest similarity molecules for each corresponding known ligand.
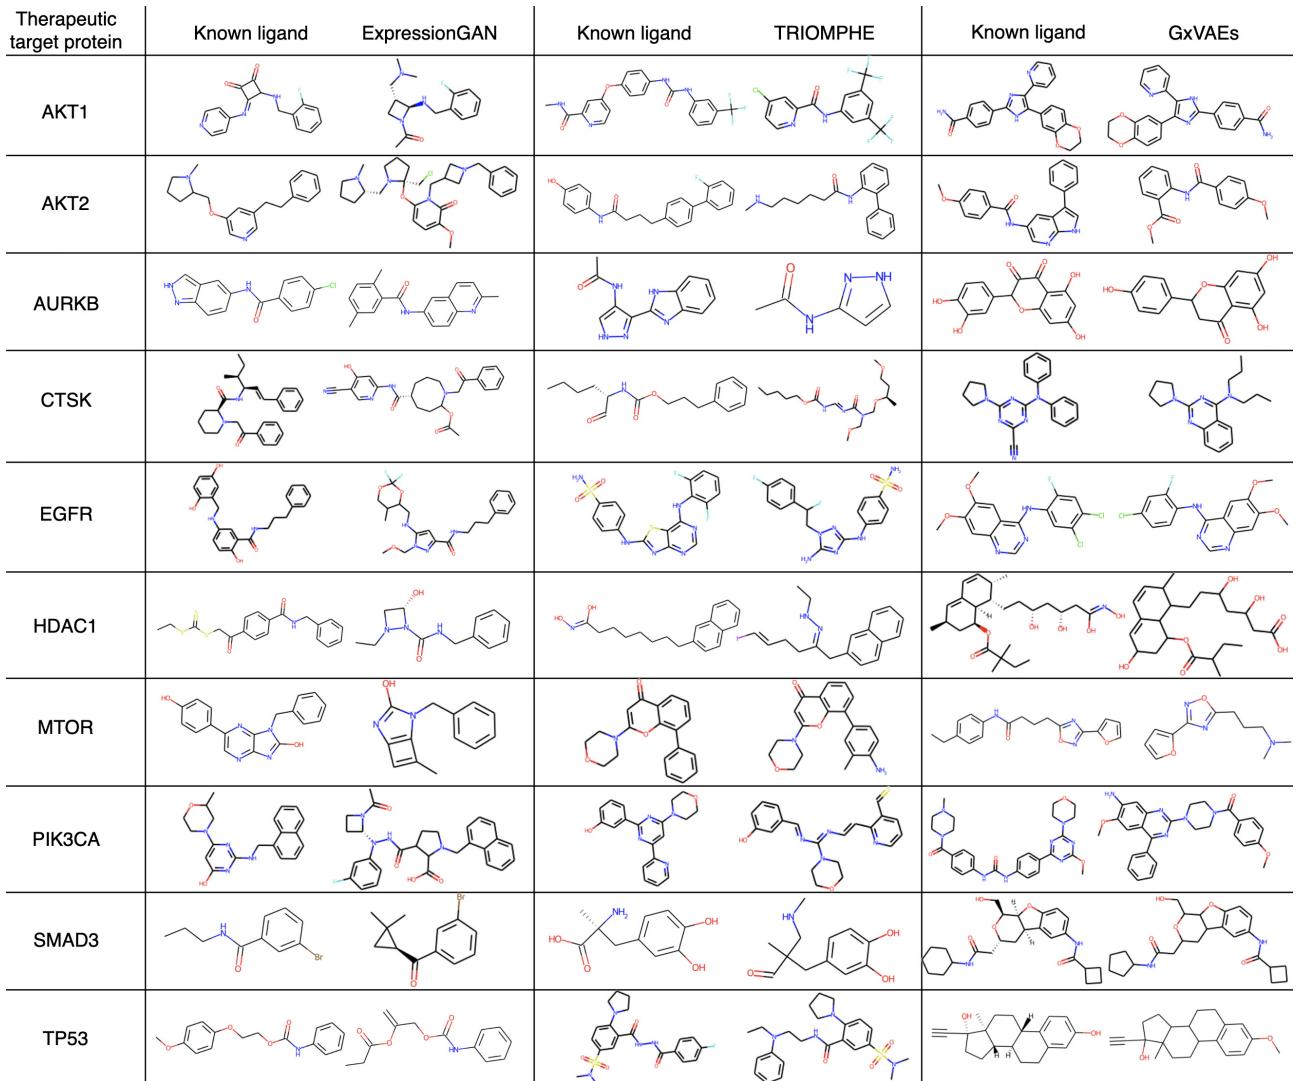
Experiments evaluate GxVAE generated molecules against validation sets and baselines ExpressionGAN and TRIOMPHE across multiple protein targets. GxVAE output preserves realistic chemical distributions, including SMILES length, molecular weight, and QED quality, while yielding substantially more valid and unique molecules with high novelty. Comparative Tanimoto analysis shows that GxVAEs often produce ligand-like candidates with stronger structural similarity to known ligands than baselines, especially for AKT1 and EGFR, although performance is not uniformly highest across every target.