Command Palette
Search for a command to run...
事後分布マッチング蒸留
事後分布マッチング蒸留
Hidir Yesiltepe Julius Berner Arash Vahdat Pinar Yanardag
概要
拡散蒸留は、事前学習済みの教師モデルによる反復的なサンプリング過程を少数のネットワーク評価に圧縮することで、画像および動画生成を高速化する。分布ベースの手法は、生徒モデルの出力分布を教師モデルの分布に一致させることでこれを実現する。この一致は多くの場合、逆KLダイバージェンスに基づく目的関数によって駆動されるが、そのモード追従バイアスはサンプル全体の多様性を犠牲にして教師分布の優勢なモードを優先する傾向がある。本論文では、分布ベース蒸留ファミリーの新たな一員として、モードを網羅する事後サンプリングと任意ステップ生成を組み合わせたPosterior Matching Distillation(PMD)を提案する。母集団損失がゼロのとき、PMDは学習された各ノイズレベルにおいて、クリーン画像に関する教師モデルの完全な事後分布を回復する。その確率的生徒モデルは、追加の学習なしに、学習済みタイムステップグリッド内の任意のサンプリングステップ数に対応する。これらの事後分布を学習するため、PMDは固定されたノイズ状態に条件付けられた生徒サンプルの指数関数的に重み付けし直した平均を、対応する教師の事後平均に一致させる。ガウスノイズによる劣化の下では、指数関数的に傾けた事後平均は、入力をシフトした1回の教師評価に等しい。開近傍上で傾けた平均を一致させることが、完全な事後分布を一意に同定することを証明する。したがってPMDは、補助的な生徒スコアネットワークを用いることなく、平均制約の族を通じて条件付き分布全体を教師信号として学習する。SDXLおよびFLUX.2 [klein] 4Bを用いた実験により、PMDは両モデルにおいて4ステップ手法の中で最良のFIDを達成し、プロンプト整合性および知覚品質の指標においても競争力のある、あるいは最先端の性能を維持することを示す。
One-sentence Summary
Researchers from Virginia Tech and NVIDIA introduce Posterior Matching Distillation (PMD), a distribution-based diffusion distillation method that matches exponentially reweighted student-sample averages to teacher posterior means and thereby uniquely identifies the full posterior without an auxiliary student-score network, achieving the best 4-step FID on both SDXL and FLUX.2 [klein] 4B.
Key Contributions
- The paper introduces Posterior Matching Distillation (PMD), a distribution-based distillation method that combines mode-covering posterior sampling with any-step generation. At zero population loss, PMD recovers the teacher's full posterior of clean images at each trained noise level, and its stochastic student supports any-step sampling within the trained timestep grid without further training.
- PMD supervises the full conditional posterior by matching exponentially reweighted averages of student samples conditioned on a fixed noisy state to corresponding teacher posterior means. Under Gaussian corruption, each exponentially tilted posterior mean is obtained from a single frozen-teacher evaluation at a shifted input, and matching these tilted means over an open neighborhood is proven to uniquely identify the full posterior without an auxiliary student-score network.
- Experiments on SDXL and FLUX.2 [klein] 4B show that PMD attains the best FID among 4-step methods on both models while remaining competitive or leading on prompt-alignment and perceptual-quality metrics.
Introduction
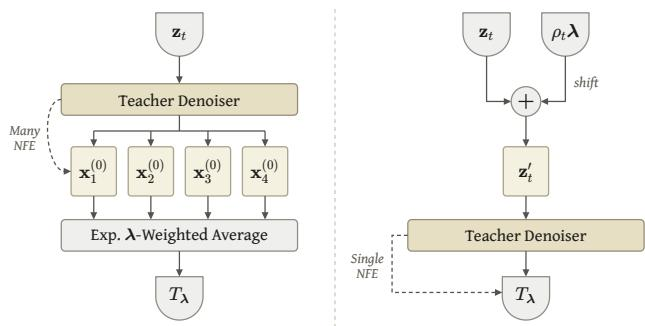
Diffusion and flow models are powerful generative models for images, video, and text, but their iterative denoising process typically requires many neural network evaluations. Distillation reduces this cost by training a one- or few-step student, yet prior work differs in what it preserves: trajectory-based methods compress the teacher’s sampling path, while distribution-based methods such as Distribution Matching Distillation and Moment Matching align generated marginals or conditional means. These approaches can still miss conditional structure, for example DMD’s approximate reverse-KL objective can be mode-seeking and reduce diversity, and Moment Matching compares means at a re-noised student prediction rather than at the original noisy input. The authors propose Posterior Matching Distillation (PMD), which directly matches the teacher’s conditional posterior at each noise level using exponentially tilted means. A key Tilt=Shift identity allows each target to be obtained from a single frozen-teacher evaluation at a shifted noisy input, avoiding expensive teacher posterior sampling while providing constraints that uniquely identify the full multimodal conditional posterior.
Method
The authors introduce Posterior Matching Distillation (PMD) to distill a diffusion teacher into a few-step student by matching the full conditional denoising posterior rather than just the posterior mean. Under the Gaussian corruption process, the conditional distribution over clean images for a noisy observation zt is given by q(x∣zt)∝q0(x)exp(−∥zt−αtx∥2/2σt2). At high noise levels, this posterior can be broad or multimodal, making it crucial to model the conditional uncertainty for few-step generation.
To capture information beyond the posterior mean, the authors consider an exponential tilt of the teacher's conditional distribution using a tilt vector λ∈Rd. The tilted distribution is defined as qλ(x∣zt)=Eq(x∣zt)[eλ⊤x]eλ⊤xq(x∣zt). As shown in the figure below:
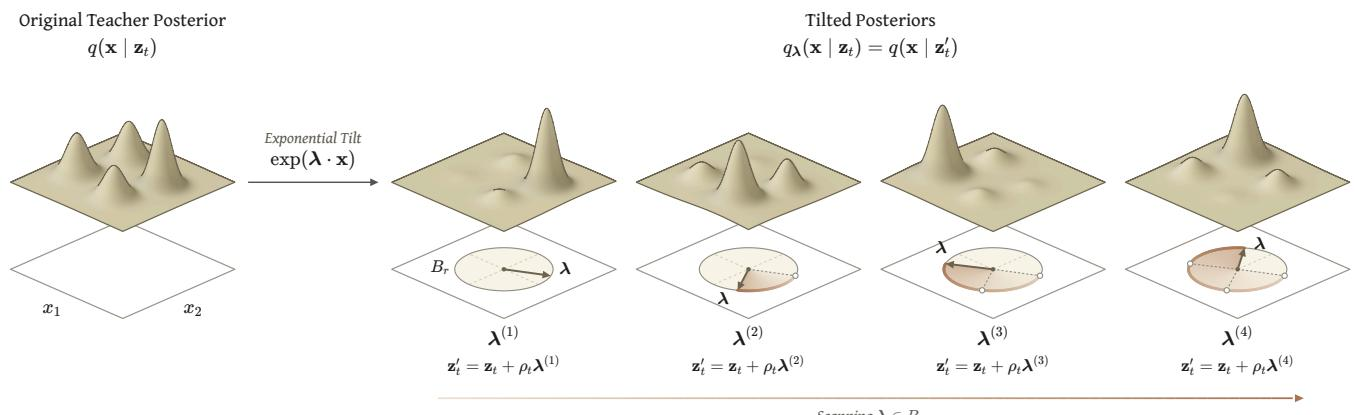
The exponential reweighting factor eλ⊤x changes the relative prominence of the posterior's modes, giving greater weight to samples aligned with λ. Different tilts emphasize different modes of the same posterior. Computing the means of these tilted distributions would typically require sampling and reweighting. However, the authors establish the Tilt=Shift Identity, which states that for a fixed noise level, exponentially tilting the posterior is exactly equivalent to shifting the noisy input to the denoiser: qλ(x∣zt)=q(x∣zt+ρtλ), where ρt=σt2/αt. Consequently, the mean of the tilted posterior is obtained directly from the frozen teacher denoiser as Eqλ(x∣zt)[x]=Dt(zt+ρtλ).
The authors prove that matching these tilted means over an open neighborhood of λ=0 is sufficient to identify the entire conditional distribution. Let Gθ denote a stochastic student that predicts a clean image x^=Gθ(zt,u,t) with random input u∼N(0,I). PMD requires the student's exponentially weighted mean to match the teacher's tilted mean:
Eu[eλ⊤x^]Eu[x^eλ⊤x^]=Dt(zt+ρtλ)If this holds for every tilt in the neighborhood, the student recovers the teacher's full conditional posterior pGθ(⋅∣zt)=q(⋅∣zt).
To operationalize this, the authors define the posterior matching residual r(zt,λ) as the difference between the student's and teacher's tilted means. The Posterior Matching Loss minimizes the expected squared residual over noise levels, noisy inputs, and tilts:
LPMD(θ)=Et,zt,λ[∥r(zt,λ)∥22]This objective matches a property of the student's conditional distribution rather than forcing individual predictions to equal the teacher's mean.
During training, PMD is trained on noisy states encountered during the student's own sampling process. At each iteration, a training noise level t is selected, and zt is obtained through backward simulation from Gaussian noise zT, with preceding steps detached from the gradient graph. Given zt, a tilt vector λ is sampled, and the frozen teacher is evaluated at the shifted input zt+ρtλ to obtain the teacher's tilted posterior mean. The student generates M independent predictions x^(m)=Gθ(zt,u(m),t). The student's tilted mean is estimated using weighted Monte Carlo samples, where weights are derived from a softmax over the dot products λ⊤x^(m). The final student objective augments the PMD loss with an auxiliary non-saturating logistic GAN loss:
Lstudent=LPMD+γGANLGANwhere the discriminator operates on caption-conditioned features extracted by the frozen teacher.
Finally, the authors design PMD to support any-step sampling without training separate students for different step counts. Because PMD learns the conditional posterior of clean images at each noise level rather than explicit transitions between noise levels, the student can predict a clean image from the current noisy state. If further steps are required, this prediction is re-noised to the next selected level using the Gaussian corruption schedule, and the student is evaluated again.
Experiment
The experiments evaluate Posterior Matching Distillation on SDXL and FLUX.2 4B text-to-image models, primarily with four sampling steps, against several few-step baselines and an undistilled reference. Qualitative comparisons show PMD generates more varied subject appearance, scene composition, and backgrounds while preserving prompt semantics, and it supports diverse sampling at different inference step counts. The results also indicate PMD achieves strong distributional quality and prompt adherence, and intra-prompt diversity experiments consistently favor PMD across feature-space, perceptual, and Vendi metrics. Ablations further show that coarse tilt sampling improves diversity and that the stochastic student draw budget affects diversity metrics during training.
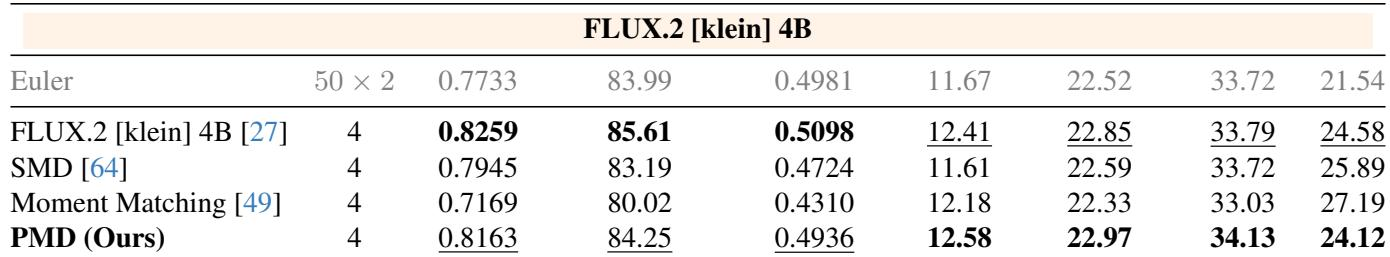
On FLUX.2 [klein] 4B, PMD achieves the best FID among four-step methods and leads in HPSv3, PickScore, and CLIP-S. The FLUX.2 reference model posts higher GenEval, DPG-Bench, and OneIG-EN than PMD, revealing a trade-off in prompt-alignment metrics. Moment Matching trails the other four-step approaches on most reported quality and fidelity measures. PMD has the best FID and the highest HPSv3, PickScore, and CLIP-S among the four-step FLUX.2 methods shown. The FLUX.2 reference model outperforms PMD in GenEval, DPG-Bench, and OneIG-EN, while PMD improves FID over that reference.
PMD achieves the strongest diversity results on PartiPrompts among the compared methods, with the highest scores on Vendi, LPIPS, DINOv2, and DreamSim. The gains are most pronounced for DINOv2, DreamSim, and Vendi diversity, while LPIPS improves more modestly. Reported comparisons across SDXL and FLUX.2 indicate a consistent advantage in intra-prompt diversity under fixed prompts and noise. PMD records the highest diversity values across all four metrics for SDXL, surpassing LCM-LoRA, SDXL-Turbo, SDXL-Lightning, Flash, PCM, and DMD2. The relative improvement over the strongest baseline is largest for DINOv2 and DreamSim, while LPIPS shows a smaller gain. A similar diversity advantage is reported for FLUX.2, where PMD improves over baselines across all metrics.
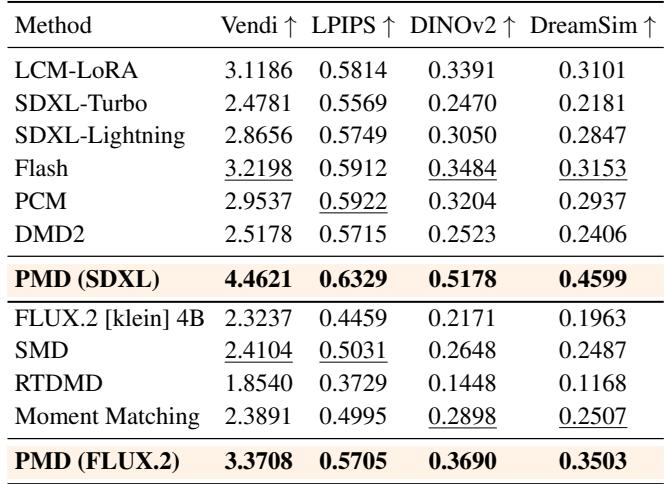
The experiments evaluate four-step text-to-image methods on FLUX.2 and SDXL using quality, prompt-alignment, and diversity benchmarks. PMD achieves the best FID and top HPSv3, PickScore, and CLIP-S among four-step FLUX.2 methods, while the FLUX.2 reference model scores higher on GenEval, DPG-Bench, and OneIG-EN, indicating a trade-off in prompt-alignment metrics; Moment Matching generally trails. On PartiPrompts, PMD consistently yields the highest intra-prompt diversity across Vendi, LPIPS, DINOv2, and DreamSim for both SDXL and FLUX.2, with the largest gains in DINOv2, DreamSim, and Vendi and more modest LPIPS improvement.