Command Palette
Search for a command to run...
Jeveration:System Oneモデルが生成を実現する
Jeveration:System Oneモデルが生成を実現する
Yuhe Liu Qi Li Shihua Zhang Xinchao Wang
概要
Jevに代表されるSystem Oneモデルは、高速な並列予測によって意思決定を行う。本論文では、この意思決定パラダイムが単一の順伝播で高品質な画像を生成できることを示すJeverationを提案する。Jeverationは凍結された視覚言語モデルを基盤とし、その視覚意味知識を全体論的な画像生成に再利用する。主要な課題は大域的一貫性の維持である。単一のプロンプトに対して多数の妥当な画像が存在する一方で、並列予測は首尾一貫した全体像へと収束しなければならない。そこで我々は、すべての位置を共有乱数状態に条件付けることで並列予測を協調させ、各サンプリングが異なるが一貫性のある画像を生成するようにする。直接的な画像教師信号の下ではモデルがこの状態を無視する傾向があるため、まず離散画像コード上の分布を学習し、単一パス生成を誘導する。テキストからの画像生成に加えて、画像からの画像生成と密な予測を同一アーキテクチャ内で統合し、単一のチェックポイントで3つのタスクすべてをそれぞれ1回の順伝播で実行可能にする。実験の結果、Jeverationは512×512の画像を78 msで生成し、既存の統合モデルと比較して最大122倍高速でありながら、競争力のある画質と密な予測性能を維持することが示された。
One-sentence Summary
Researchers at the National University of Singapore propose Jeveration, a System One model that repurposes a frozen vision-language model with a shared random state and a learned distribution over discrete image codes to generate coherent images in a single forward pass, unifying text-to-image generation, image-to-image generation, and dense prediction while producing 512×512 images in 78 ms, up to 122× faster than existing unified models.
Key Contributions
- Jeveration is introduced as a parallel decision model that generates 512×512 images in a single forward pass by repurposing a frozen vision-language model's visual-semantic knowledge.
- To maintain global consistency, the method conditions all image code positions on a shared random state and learns a distribution over discrete image codes through token-level conditional matching with a masked model, avoiding the tendency to ignore the state under direct image supervision.
- A single checkpoint unifies text-to-image generation, image-to-image generation, and dense prediction through shared adapters and task-specific output heads; experiments report 78 ms generation, up to 122× faster than existing unified models, with competitive image quality and dense prediction performance.
Introduction
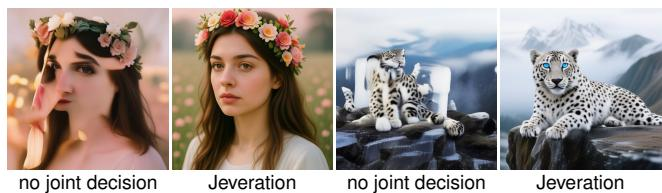
Image generation is currently dominated by autoregressive and diffusion models, but both rely on many sequential model evaluations, which increases inference latency. Prior System One models can return typed visual decisions in parallel, but they have been applied mainly to understanding and scoring tasks rather than synthesis, and naive parallel image prediction tends to produce spatially incoherent regions. The authors introduce Jeveration, which adapts a frozen vision-language model with LoRA adapters and output heads to return an entire image as one joint decision in a single forward pass. To achieve coherence, all code positions are conditioned on a shared random state, and a masked model trained to learn the image distribution provides target conditionals for guiding the parallel decisions. The resulting single checkpoint covers text-to-image generation, image-to-image generation, and dense prediction tasks.
Method
Jeveration enables a vision-language model (VLM) to generate images through parallel typed decisions in a single forward pass, while simultaneously supporting dense prediction tasks within the same framework. For image synthesis, the model selects a codebook entry at each code position, whereas for dense prediction, it produces task-specific classes or scores. A shared random state provides common stochastic conditioning to all code positions, ensuring that each draw yields a different but globally coherent image.
Given a conditioning input y, such as a text prompt or a source image, Jeveration formulates the output as typed decisions. An image is represented as a joint choice of discrete codes c=(c1,…,cN) from an image tokenizer. A direct approach that predicts a categorical distribution at each code position and samples codes independently in parallel fails to capture dependencies between codes. This independent factorization matches only the marginals, often resulting in codes that do not fit together to form a coherent image.
To overcome this, Jeveration draws one random state sequence ξ per image and conditions every code position on this shared state:
qθ(c∣y)=Eξ∼p0[i=1∏Nqθ,i(ci∣y,ξ)]Although the codes are sampled independently given (y,ξ), their shared dependence on ξ allows the resulting image distribution to capture dependencies between positions. This enables the model to coordinate its code choices while deciding all positions in a single forward pass.
The authors implement these visual decisions by appending decision tokens to the input of a VLM. Text tokens encode the prompt and task instruction, and a frozen vision tower encodes any input image into visual tokens. The decision tokens are initialized from a sampled random state for image generation and serve as spatial queries for dense prediction. A frozen backbone with shared LoRA adapters processes the input and decision tokens in a single forward pass. In its full-attention layers, decision tokens attend to each other bidirectionally while the input prefix remains causal. Finally, task-specific heads map the decision tokens' final hidden states to image codes or dense predictions.
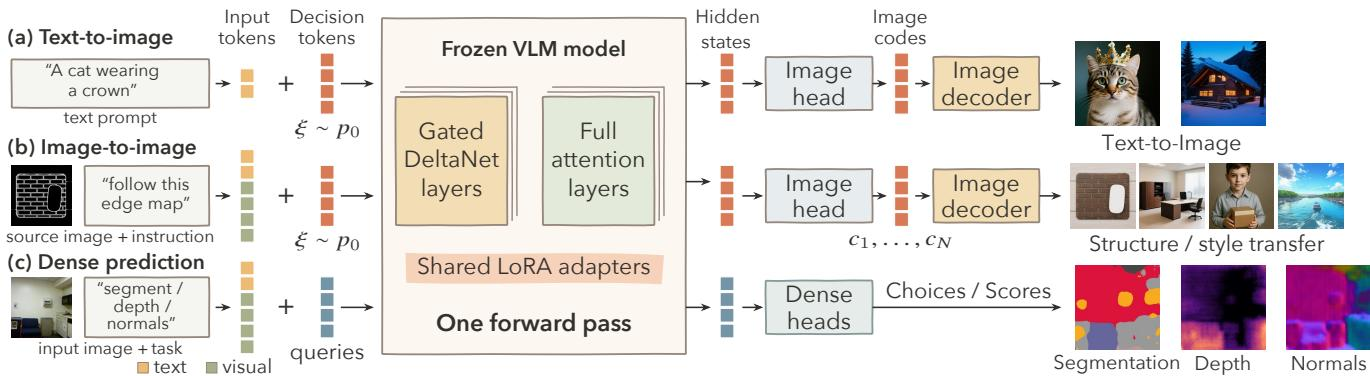
For image generation, the image tokenizer is a frozen TA-TiTok with N=128 codes per image. The initial embeddings of the decision tokens encode the random state ξ∼p0, which masks each position with probability ρ, fills the remaining positions with uniformly random codes, and adds Gaussian noise of scale σ to all embeddings. A transformer head reads the final hidden states of these tokens together with ξ and outputs a feature ui for each position. Each code is predicted from ui using two branches. The codebook branch fcb projects ui to the code space and applies a classifier initialized from the tokenizer's codebook. The wide branch fwide, initialized at zero, maps ui directly to the code logits. The code distribution sums the two:
qθ,i(⋅∣y,ξ)=softmax(fcb(ui)+fwide(ui))At inference, all codes are sampled in parallel as one joint decision and rendered by the tokenizer's decoder. For dense prediction, the decision tokens act as spatial queries aligned with the visual tokens of the input image, and task-specific heads decode each query's final hidden state into segmentation, depth, or surface-normal predictions.
The training procedure teaches the model to use ξ to make coherent image decisions. Direct supervision on target codes does not encourage the model to use ξ, since the random state is sampled independently of the target image. Therefore, the authors first learn a model of the image distribution through masked prediction, then use it to guide image decisions from random states.
In the first phase, the architecture is trained as a masked model with the VLM frozen. For target codes c, a random set M is masked, and the hidden codes are predicted from the visible codes cMˉ and condition y:
Lmask(ϕ)=E[∣M∣1i∈M∑−logpϕ,i(ci∣cMˉ,y)]The visible codes supply image-specific context, enabling the model to learn dependencies between positions.
In the second phase, the decision model θ starts from the first-phase model and learns to turn random states into whole images. From (y,ξ), θ predicts logits and samples a code sequence c^ in a single pass. A random subset M of c^ is re-masked, and two masked models predict the hidden codes from the same visible codes. The frozen first-phase model ϕ represents the image distribution, while an auxiliary model ψ tracks the current distribution of θ. The auxiliary model begins as a copy of ϕ and continues training on θ's samples. The two predictions agree when θ matches the image distribution. The authors use their difference to update θ by minimizing:
LDM(θ)=E[∣M∣1i∈M∑sg(pψ,i−pϕ,i)⊤ℓθ,i]where sg stops gradients. This pushes θ to coordinate its codes through the shared state ξ.
In the final part of the second phase, confidence-guided correction adds direct supervision on generated samples. For some samples in each batch, the half of the positions with the lowest confidence are re-masked, and the frozen model completes them over several rounds into cref. The model θ is then trained to predict these corrected codes from the same (y,ξ):
Lgen=LDM+λLcorr,Lcorr=Eselected[∣R∣1∑i∈R−logqθ,i(ciref∣y,ξ)].Dense tasks are supervised with ground truth, using cross-entropy for segmentation, an ℓ1 depth error, and 1−cos for surface normals. The frozen model, the auxiliary model, and the correction are used only in training, ensuring that inference remains a single forward pass of θ.
Experiment
The experiments evaluate a single Jeveration checkpoint trained with rank-256 LoRA adapters on a frozen VLM for text-to-image generation, image-to-image tasks, and dense prediction, using generation benchmarks such as GenEval, DPG-Bench, and HPSv2.1, along with structure fidelity, NYUv2, and latency metrics. Text-to-image results show that the model generates coherent images in one forward pass and is faster than both unified and generation-only baselines while maintaining competitive quality. Image-to-image and dense prediction experiments demonstrate that the same checkpoint handles controllable generation, segmentation, and depth estimation with strong structural fidelity and little added latency. Ablations confirm that the shared random state, correction target, dual image-head branches, source conditioning, and joint training each contribute to image quality, controllability, or task flexibility.
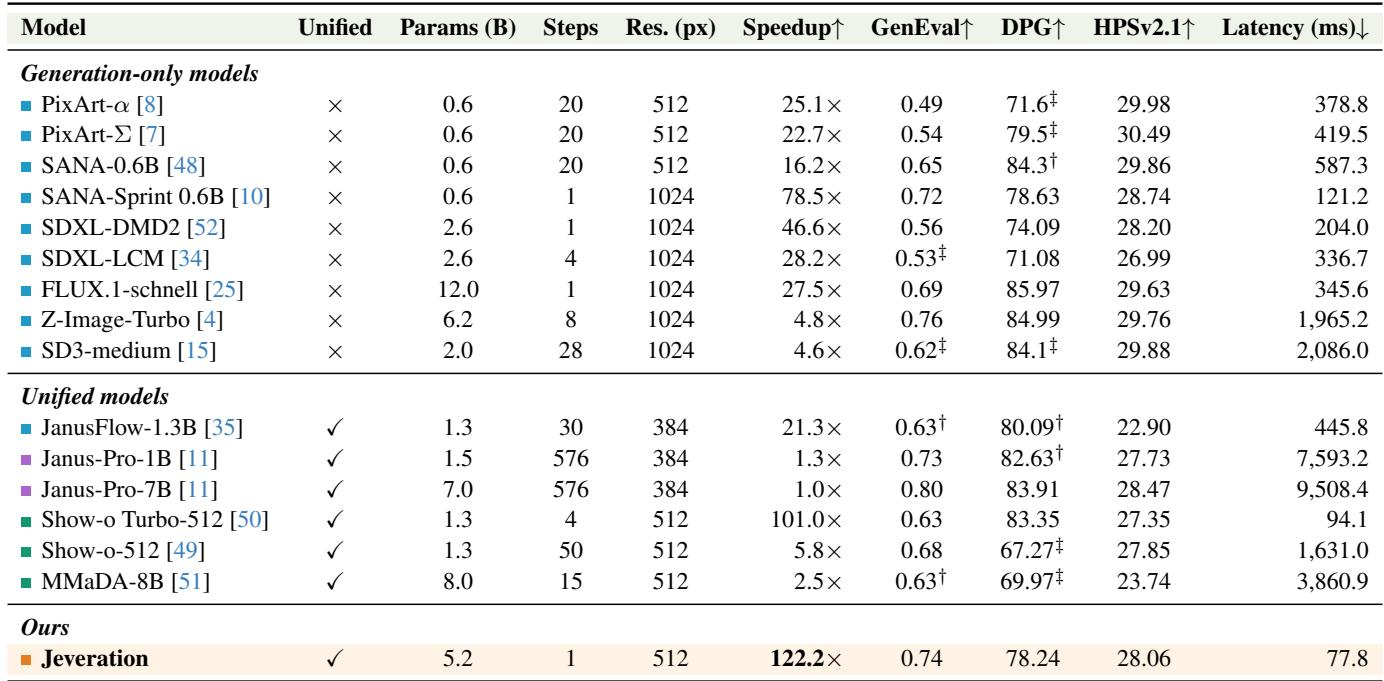
Jeveration generates 512x512 images in a single forward pass with the lowest end-to-end latency in the comparison and stronger GenEval than the listed unified and same-resolution generation-only baselines. It is roughly two orders of magnitude faster than autoregressive Janus-Pro baselines and outperforms several one-step generation-only models on GenEval despite their higher output resolution. The results indicate a frozen vision-language backbone can provide competitive text-to-image quality without iterative sampling. At 512-px resolution, it achieves higher GenEval than multi-step generation-only models while being several times faster end to end. It is roughly two orders of magnitude faster than the autoregressive Janus-Pro baselines at batch 1 on the same hardware.
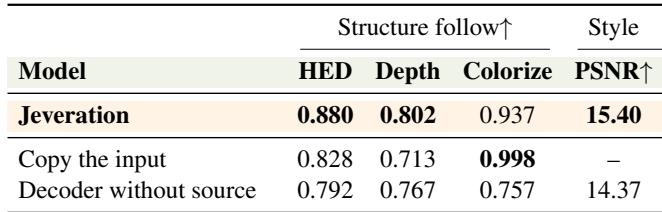
On held-out image-to-image examples, Jeveration achieves strong structure fidelity across edge, depth, and colorization tasks. It improves over a decoder without source conditioning, particularly in colorization and edge fidelity, and achieves higher style PSNR. Jeveration attains the best edge and depth fidelity among the compared conditions. Source-image conditioning sharply improves colorization fidelity over source-free decoding and lifts edge fidelity above direct input copying. Jeveration achieves better style PSNR than the decoder without source, indicating closer alignment with paired style targets.
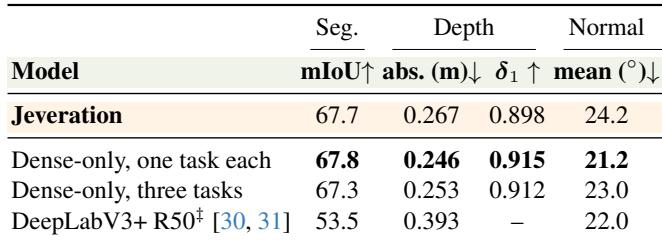
On NYUv2 dense prediction, the unified model matches dense-only segmentation accuracy from the same backbone and far exceeds DeepLabV3+. Depth accuracy is close to the dense-only baselines, while surface normal error is somewhat higher. Each prediction is produced in a single forward pass, supporting one checkpoint for both image generation and dense prediction. The unified model matches dense-only segmentation scores from the same backbone while outperforming DeepLabV3+ by a wide margin. Depth error is close to the dense-only baselines and much lower than DeepLabV3+, but surface normal accuracy trails the dense-only models.
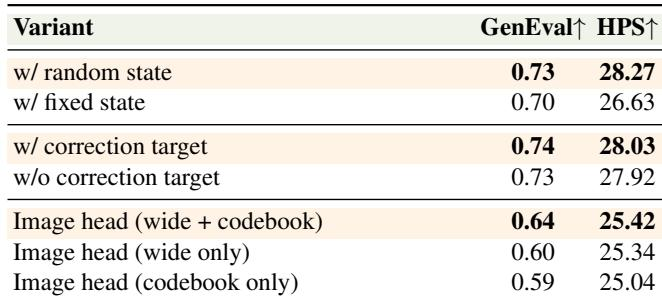
Ablations indicate that a shared random state improves both composition and image quality over a fixed state. A correction target adds a further small quality gain while leaving composition similar, and combining wide and codebook image-head branches outperforms either branch alone. The results support the selected configuration for coherent, high-quality generation. A shared random state yields higher GenEval and HPS than a fixed state, indicating better coherence and image quality. Using a correction target improves HPS while GenEval remains similar, suggesting it refines details rather than composition. Removing the correction target slightly lowers image quality with no meaningful change in composition. The wide plus codebook image-head combination outperforms the wide-only and codebook-only variants.
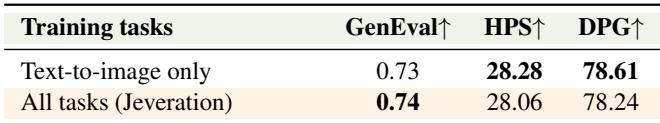
Joint training across text-to-image, image-to-image, and dense prediction tasks preserves text-to-image quality almost entirely. The all-task model performs on par with a text-to-image only baseline on GenEval, HPS, and DPG metrics. The added tasks introduce little interference while enabling dense prediction and image-to-image generation. All-task training matches text-to-image-only quality, with only marginal differences across GenEval, HPS, and DPG. Adding image-to-image and dense tasks comes at almost no cost to text-to-image performance. For dense prediction, joint training matches dense-only segmentation and shows only a modest decline in depth and normal accuracy.
Jeveration is evaluated as a unified vision-language model across text-to-image, image-to-image, and dense prediction tasks. It produces 512x512 images in a single forward pass with lower latency and stronger GenEval than several generation-only baselines, while image-to-image experiments show high edge, depth, and colorization fidelity that improves with source conditioning. For dense prediction, the unified model matches segmentation quality from the same backbone and outperforms DeepLabV3+, with depth close to dense-only baselines; ablations confirm that shared random states, the correction target, and combined image-head branches improve quality, and joint training preserves text-to-image performance with little interference.