Command Palette
Search for a command to run...
HiFOR: Vision-Language-Actionモデルのための行動誘導型世界グラウンディングを備えた階層的先見
HiFOR: Vision-Language-Actionモデルのための行動誘導型世界グラウンディングを備えた階層的先見
Rongxing Ding Hongyu Qu Kehong Wu Xudong Wang Fan Zhang Xinguang Xiang Xiangbo Shu
概要
Vision-Language-Action(VLA)モデルは、視覚認識、言語理解、行動生成を統合することにより、ロボット操作において有望な能力を示してきた。近年の研究では、環境動態やタスク進行の理解を高めるために未来予測をさらに取り入れることが進んでいる。しかし、既存手法は短期的な動特性と長期的なタスク目標を別々にモデル化することが多く、予測された未来を行動方策に直接組み込む一方で、現在の行動要求との関連性を十分に考慮していない。これらの限界に対処するため、我々は行動誘導型世界検索を備えた階層的先見フレームワークであるHiFORを提案する。具体的には、Hierarchical Foresight Predictionが、Hierarchical Dependency Mask(HDM)を通じて短期的状態変化、意味的マイルストーン、最終目標状態を統合的に予測し、時間的視野にまたがる依存関係を確立する。これらの予測に基づき、Structure-Aware Latent World Modelingは将来の潜在表現を時間軸・視点・空間の各次元に沿って整理し、細粒度な検索を促進する。さらに、Action-Guided Factorized World Retrievalは、デノイジング中に変化する行動表現に基づいて、構造化された潜在世界から関連する未来情報を適応的に検索し、行動生成のための的確な指針を提供する。2つのシミュレーションベンチマークと6つの実世界ロボット操作タスクにおける広範な実験により、本手法の有効性が示される。
One-sentence Summary
Researchers from Nanjing University of Science and Technology, National University of Singapore, Shenyang Institute of Automation, Chinese Academy of Sciences, and The Chinese University of Hong Kong propose HiFOR, a hierarchical foresight framework that jointly predicts short-term state evolution, semantic milestones, and final goal states through a Hierarchical Dependency Mask, and that combines structure-aware latent world modeling with action-guided factorized world retrieval to provide targeted guidance for action generation, as validated on two simulation benchmarks and six real-world robotic manipulation tasks.
Key Contributions
- The paper introduces HiFOR, a hierarchical foresight framework that jointly predicts short-term state evolution, semantic milestones, and final goal states through a Hierarchical Dependency Mask, linking local world dynamics with long-term task objectives.
- The paper develops a structure-aware latent world modeling mechanism that organizes predicted futures along horizon, view, and spatial dimensions, and an action-guided factorized world retrieval mechanism that retrieves action-relevant future information based on evolving action representations during denoising.
- Experiments on LIBERO, RoboTwin 2.0, and six real-world robotic manipulation tasks demonstrate HiFOR's effectiveness, and ablation studies validate the contributions of its key components.
Introduction
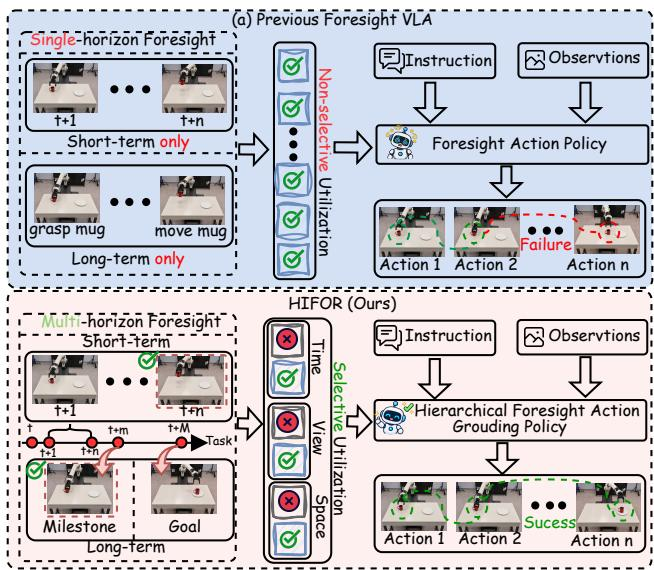
Vision-language-action (VLA) models have become central to robotic manipulation by unifying visual perception, language understanding, and action generation, but complex tasks increasingly require policies that can anticipate future environmental changes and task progression. Prior foresight-based methods often model either short-term dynamics or long-term goals in isolation, and they typically inject predicted future states, latents, images, or videos into action policies without selectively weighting their relevance to the current action. This limits coherent temporal reasoning and fails to account for how the importance of future information varies across prediction horizons, camera views, and spatial regions. The authors propose HiFOR, a hierarchical foresight framework that jointly predicts short-term state evolution, semantic milestones, and final goals, organizes these predictions into a structured latent world, and applies action-guided factorized retrieval during action denoising to adaptively select the most relevant future information for decision making.
Dataset
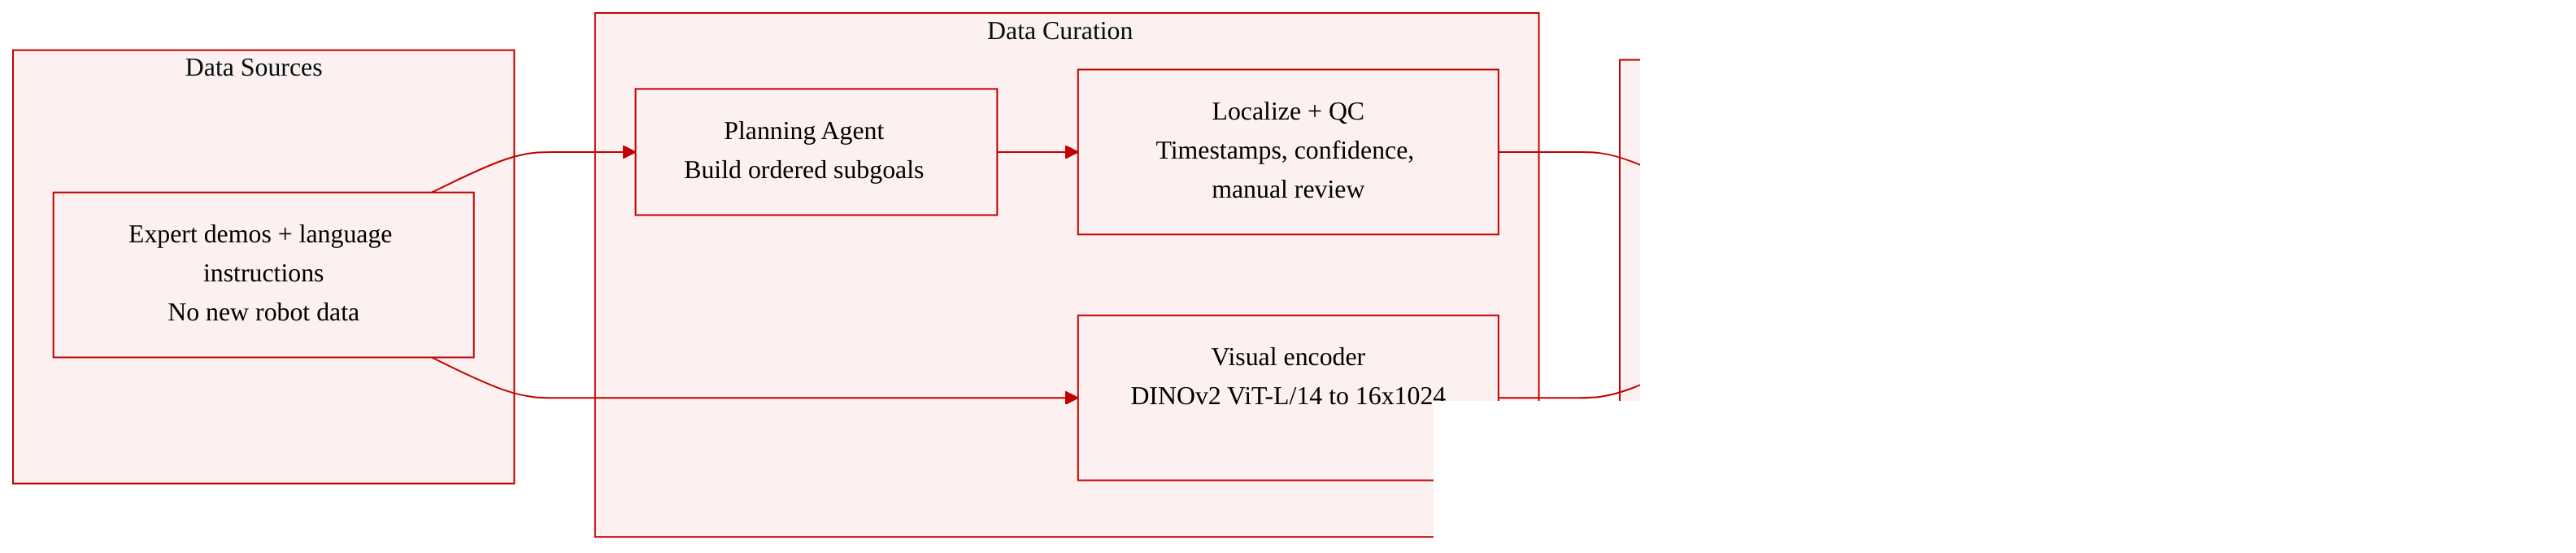
The authors construct a hierarchical planning dataset from existing successful expert demonstrations, without collecting additional robot trajectories. The goal is to replace uniform future-frame sampling with semantically meaningful milestone supervision for vision-language-action training.
- Sources and composition: existing successful expert demonstration trajectories; no new robot data collection is performed.
- Annotation schema: For each language instruction, a Planning Agent generates an ordered sequence of subgoals G1,G2,...,GK. Each subgoal specifies a semantic stage, an event type, and a completion verification criterion.
- Timestamp localization: The method automatically finds completion timestamps for each subgoal in expert demonstrations. Candidate event boundaries are identified from gripper transitions, robot motion phases, and state information.
- Event handling: Stable-state events, such as grasping and placement, use the earliest frame where the target condition remains persistently satisfied. Dynamic events are localized using motion or state transition boundaries.
- Quality control: Temporal consistency is enforced as t1<t2<...<tK. Confidence scores are assigned to milestones, and ambiguous or low-confidence cases are flagged for manual review. Annotations are stored as M={(Gk,tk)}k=1K.
- Visual supervision: Multiview frames are encoded with a frozen DINOv2 ViT-L/14 model. Prefix tokens are removed, and patch features are adaptively pooled into a 4x4 spatial grid, producing Ftv=ϕDINO(Itv)∈R16×1024.
- Use in the model: The milestone annotations and DINOv2 visual features provide structured future supervision for hierarchical foresight prediction during VLA training.
- Reported scale and splits: The provided excerpt does not specify dataset size, training split ratios, or mixture weights.
Method
The authors formulate robotic manipulation with Vision-Language-Action (VLA) models as a language-conditioned sequential decision-making problem. At each timestep t, the policy receives multi-view visual observations Ot={Itv}v=1V, a language instruction L, and the robot state st, predicting a future action chunk:
At={at+h}h=0H−1=πθ(Ot,L,st)where each action consists of relative end-effector translation, rotation, and gripper control.
The overall framework of the proposed method, HiFOR, is illustrated below.
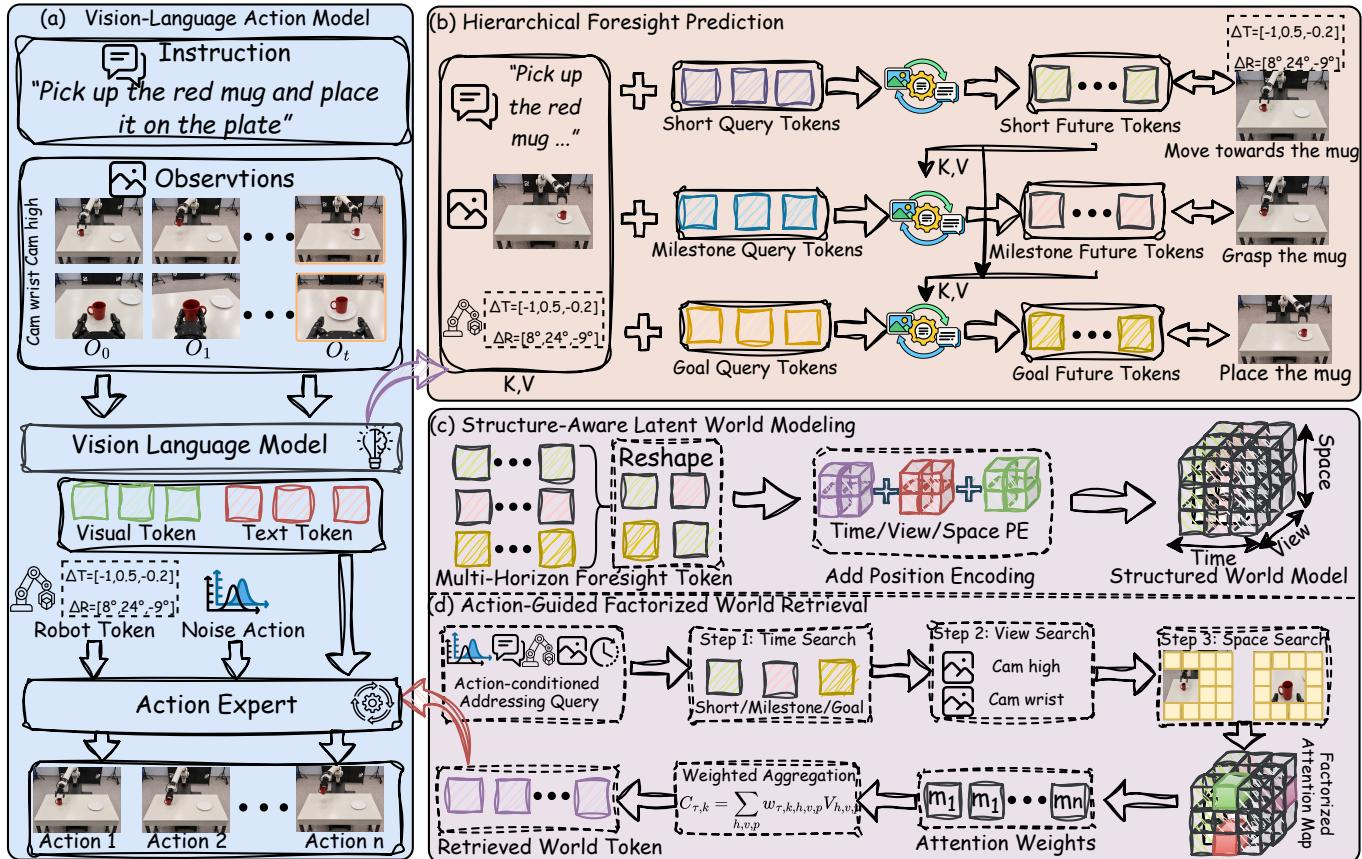
Given the multimodal inputs, a VLA backbone encodes the current context to generate action representations. The authors then introduce Hierarchical Foresight Prediction to jointly predict short-term state evolution, intermediate semantic milestones, and final goal states. Building upon these predictions, Structure-Aware Latent World Modeling organizes the future latent representations along the horizon, view, and spatial dimensions. Finally, Action-Guided Factorized World Retrieval selectively retrieves action-relevant future information to guide the action expert.
To provide structured future supervision for VLA training without collecting additional trajectories, the authors construct a hierarchical planning dataset from existing expert demonstrations.
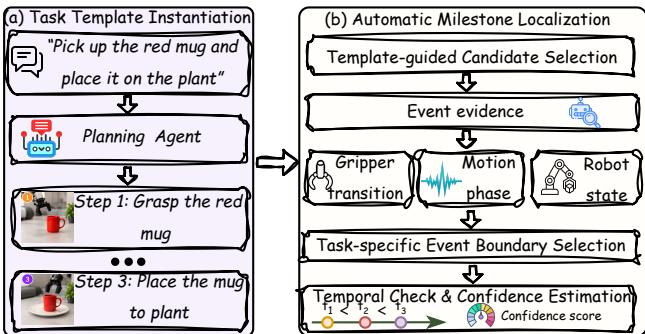
As shown in the figure above, a Planning Agent first generates a task-specific semantic template from the language instruction L, decomposing it into an ordered sequence of subgoals G={G1,G2,…,GK}. Each subgoal specifies a semantic stage, event type, and completion criterion. Given this template, the system automatically localizes the completion timestamps of each subgoal in expert demonstrations by identifying candidate event boundaries using gripper transitions, robot motion phases, and state information. Temporal consistency is enforced, and confidence scores are assigned. For future visual supervision, multi-view semantic features are extracted from all trajectory frames using a frozen DINOv2 ViT-L/14 encoder. After removing prefix tokens, the patch features are adaptively pooled into a 4×4 spatial grid:
Ftv=ϕDINO(Itv)∈R16×1024The Hierarchical Foresight Prediction module defines three complementary prediction horizons for each timestep t<tK: the short-term target tts=min(t+Δ,tK), the milestone target ttm=mink:tk>ttk, and the goal target ttg=tK. Corresponding visual supervision Zth∈RV×S×D is constructed for each horizon h∈{s,m,g}. Short-term prediction additionally incorporates the future robot state sequence Sts=(st+1,st+2,…,stts) to constrain fine-grained motion dynamics.
To predict these targets, the current observations and instruction are encoded into visual tokens Vt and language tokens EL. Three groups of learnable future queries, Qs,Qm, and Qg, are introduced. A Hierarchical Dependency Mask (HDM) progressively expands attention visibility from short-term to goal queries, establishing cross-horizon dependencies:
Uth=Hθ(Qh;[Vt;EL;Q≤h]),h∈{s,m,g}where Q≤h represents the concatenation of query groups up to horizon h. The predicted features are projected into the DINOv2 feature space via visual prediction heads Z^th=Pvish(Uth), and an additional state prediction head estimates S^ts=Pstate(Uts). The foresight prediction loss is defined as:
LHFP=λmDv(Z^th,Zth)+λnDs(S^ts,Sts)To effectively utilize these multi-horizon predictions, the authors propose Structure-Aware Latent World Modeling. The predicted future features are organized into structured world tokens through feature projection and structural positional embeddings:
wth,v,p=Pw(Z^th[v,p,:])+ehhor+evview+epspaThese tokens form a unified structured latent world representation Wt∈R3×V×S×dw, explicitly preserving horizon, view, and spatial dimensions. Horizon-level and view-level features are further derived through spatial aggregation to support different granularities.
Finally, Action-Guided Factorized World Retrieval (AWR) is introduced to selectively retrieve future information. Since the relevance of future information varies across denoising steps, dynamic retrieval queries qt,τa=Q(Ht,τa) are constructed from the action expert's hidden representations at each denoising step τ. Independent linear projections generate queries for temporal horizons, camera views, and spatial locations. A unified factorized attention operation is then formulated across these dimensions:
at,τℓ(i∣c)=Softmaxi(d(qt,τℓ)⊤ktℓ(i∣c)),ℓ∈{H,V,S}The resulting attention weights are combined to aggregate the latent world values, yielding the action-relevant future representation ft,τ. As the action-conditioned queries evolve, the model dynamically adjusts its attention across prediction horizons, camera views, and spatial regions. The retrieved features are fused with action representations and injected into the action expert via residual connections.
The overall training objective jointly optimizes action generation and hierarchical foresight prediction through the flow-matching loss LACT and the foresight prediction loss LHFP:
L=LACT+LHFPExperiment
The evaluation spans simulation benchmarks on LIBERO and RoboTwin 2.0, real-world manipulation tasks with a single-arm robot, ablation studies, and qualitative attention visualization. Across these settings, HiFOR consistently outperforms the baseline, with particularly notable gains on long-horizon and complex manipulation tasks. Ablations show that hierarchical foresight prediction and action-guided retrieval provide complementary benefits, while attention analysis indicates the model adaptively shifts focus across temporal horizons and camera views depending on the task stage.
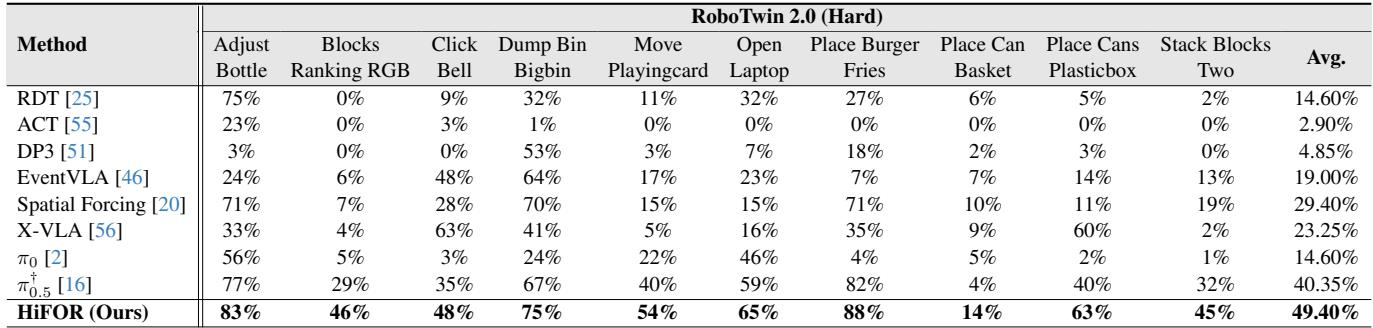
On the RoboTwin 2.0 Hard benchmark, HiFOR achieves the highest average success rate of 49.40% across 20 tasks, exceeding the pi0.5 baseline by 9.05 percentage points. Other reported methods are substantially lower, with Spatial Forcing averaging 29.40%, X-VLA 23.25%, and EventVLA 19.00%. Task-level gains are especially strong on Blocks Ranking RGB, Place Cans Plasticbox, Move Playingcard, and Stack Blocks Two. HiFOR attains the best overall average success rate of 49.40% across 20 RoboTwin 2.0 Hard tasks. It outperforms the pi0.5 baseline by 9.05 percentage points. Task-level improvements include Blocks Ranking RGB rising from 29% to 46% and Place Cans Plasticbox from 40% to 63%. HiFOR surpasses the baseline on Move Playingcard and Stack Blocks Two by 14% and 13%, respectively.
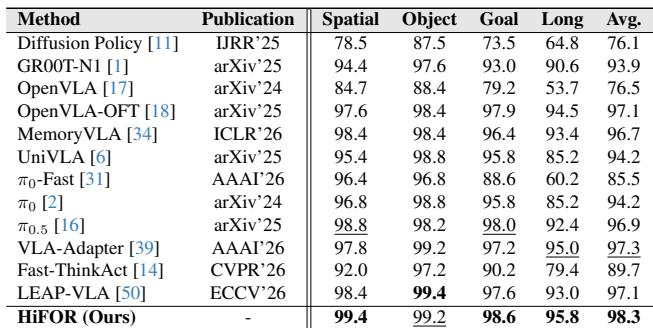
On LIBERO, HiFOR attains the highest overall average success rate at 98.3%, with leading results on the Spatial, Goal, and Long task suites. Long-horizon tasks show the largest relative gain, improving by 3.4 percentage points over the cited baseline. Prior vision-language-action methods such as OpenVLA-OFT and MemoryVLA are competitive, but HiFOR remains stronger overall and on long-horizon manipulation. HiFOR records the best overall LIBERO average and leads on Spatial, Goal, and Long suites while remaining competitive on Object tasks. Long-horizon performance differentiates HiFOR, reaching 95.8% on the Long suite compared with much lower scores from earlier methods such as OpenVLA and Diffusion Policy. The largest improvement over the cited baseline is on long-horizon tasks, with a gain of 3.4 percentage points. OpenVLA-OFT and MemoryVLA are among the stronger prior methods, but their overall averages trail HiFOR.
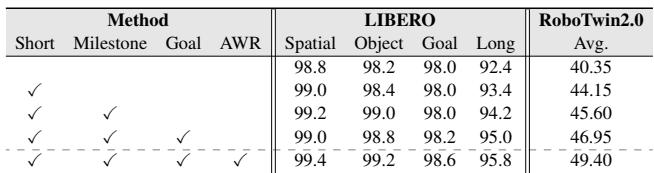
Ablations show that each core component adds successive gains in manipulation success, with the largest improvements on long-horizon LIBERO and RoboTwin 2.0. Short-term foresight provides an initial boost, milestone and goal predictions add further accuracy, and action-guided world retrieval contributes an additional gain. Semantic feature-based future prediction also outperforms direct RGB pixel prediction, especially on long-horizon tasks. Adding short-term foresight improves RoboTwin 2.0 success markedly over the baseline, and subsequent milestone, goal, and retrieval components each provide further gains. On LIBERO-Long, the full model improves success by several points over the baseline, with semantic feature-based prediction surpassing RGB-based prediction.
HiFOR is evaluated on RoboTwin 2.0 Hard and LIBERO benchmarks, where it achieves the highest average success rates of 49.40% and 98.3%, respectively. It outperforms the pi0.5 baseline by 9.05 percentage points on RoboTwin, with notable gains on tasks such as Blocks Ranking RGB and Place Cans Plasticbox, and shows the largest relative improvement on LIBERO long-horizon tasks. Ablation studies confirm that short-term foresight, milestone and goal prediction, and action-guided retrieval each contribute successive gains, while semantic feature-based future prediction outperforms direct RGB pixel prediction, especially for long-horizon manipulation.