Command Palette
Search for a command to run...
ChronoReplay: ストリーミング空間知能には単一の回答インターフェースでは不十分
ChronoReplay: ストリーミング空間知能には単一の回答インターフェースでは不十分
概要
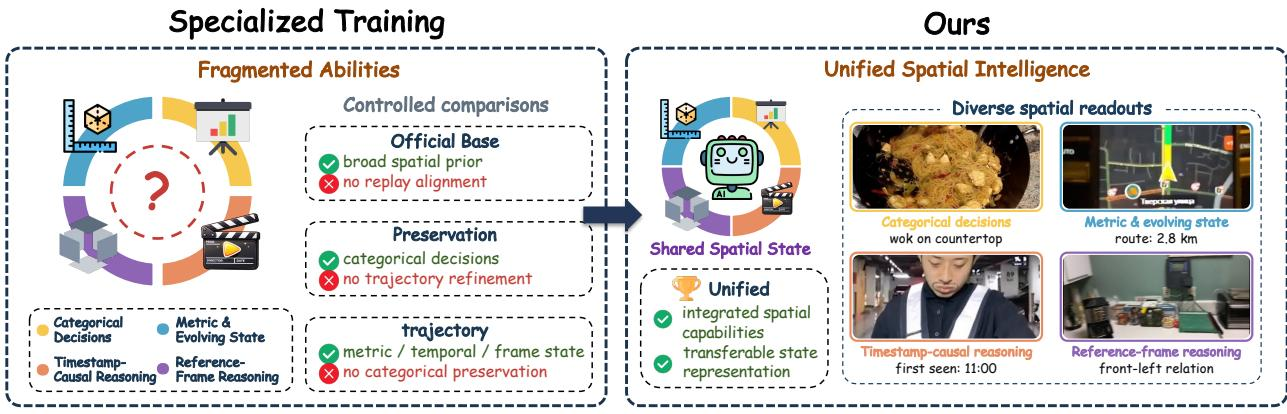
空間VLMを、物体がどちら側にあるかを答えるよう学習させる場合、その回答を決定する計量的変位を保持する必要はない。一方、距離推定の教師信号はカテゴリカルな関係をほとんど制約しない可能性がある。ポストトレーニングで一つの読み出しが強調されると、改善はそのインターフェースに集中し、他への転移は弱いまま、あるいはむしろ低下することがある。我々はこの観測された特化をインターフェース・ロックインと呼ぶ。ChronoReplayは、異種の空間的教師信号を時系列順のエピソードとして再生し、ソース本来のターゲットを保持し、系統(ファミリー)間で教師信号のバランスを取ることで、この問題に対処する。同じ観測アクセスの下で、単一のChronoReplayチェックポイントがOVO-S-Bench、OST-Bench、UCS-Benchを同時に改善し、OST-Benchでは13.41ポイントの向上を含み、ここで比較した教師信号設定の中で最高の3ベンチマーク平均を達成する。同一データを用いた対照実験は、この転移の要因をさらに切り分ける。回答の直列化はOSTとUCSの間で利得を再配分し、ファミリーバランス学習は通常の同時SFTや自然なターン重み付けを上回り、時系列リプレイは順序をずらした対照を、2つの対応するシードにわたりOSTで約2.41ポイント上回る。さらに適応的フレーム選択は、学習済みモデルを固定したまま証拠へのアクセスを変更し、より低い視覚コストで推論時に追加の利得をもたらす。ストリーミング空間性能は、教師信号がどのような区別を保持するか、学習中に異種の履歴がどのように組織化されるか、そしてテスト時に推論がどのような因果的証拠を利用できるかに依存する。
One-sentence Summary
Westlake University, ZJU, USTC, et al. propose ChronoReplay, which mitigates interface lock-in in streaming spatial VLMs by replaying heterogeneous spatial supervision as chronologically ordered episodes with source-native targets and family-balanced learning, jointly improving OVO-S-Bench, OST-Bench, and UCS-Bench, including a 13.41-point gain on OST-Bench and the highest three-benchmark mean among the supervision settings compared.
Key Contributions
- The paper identifies an empirical pattern called interface lock-in, in which single-family spatial supervision improves one readout while limiting or degrading transfer to other spatial readouts.
- The paper introduces ChronoReplay, a training recipe that replays heterogeneous spatial supervision in chronological episodes, retains source-native targets, and balances supervision across categorical, metric, and temporal families. Under matched observation access, a single ChronoReplay checkpoint improves OVO-S-Bench, OST-Bench, and UCS-Bench together, with a 13.41-point OST-Bench gain and the highest three-benchmark mean among the compared settings.
- The paper presents same-data controls separating transfer components: answer serialization redistributes gains across OST and UCS, family-balanced learning improves over ordinary joint SFT and natural turn weighting, and chronological replay exceeds a shifted-order control by about 2.41 OST points across paired seeds. Adaptive frame selection adds an inference-time gain at lower visual cost while keeping the trained model fixed.
Introduction
The authors address streaming spatial intelligence, where an egocentric observer must answer categorical, metric, and temporal spatial questions from a causal video history using only past observations. This is challenging because a single history must support multiple answer formats while preserving object associations, accumulated motion, and relations under changing reference frames. Prior work typically supervises one answer format at a time, leaving untested whether one model can serve all formats over the same causal stream. The authors document an interface lock-in problem, where single-family training improves its native readout but transfers unevenly to other formats, and they note that metric or temporal targets become ambiguous when detached from the history that produced them. Their main contribution is ChronoReplay, which combines family-balanced learning that keeps targets in their native formats with Causal Replay construction that replays heterogeneous supervision as chronologically ordered episodes tied to their valid causal prefixes. This approach improves OVO-S, OST, and UCS benchmarks under matched observation access.
Dataset
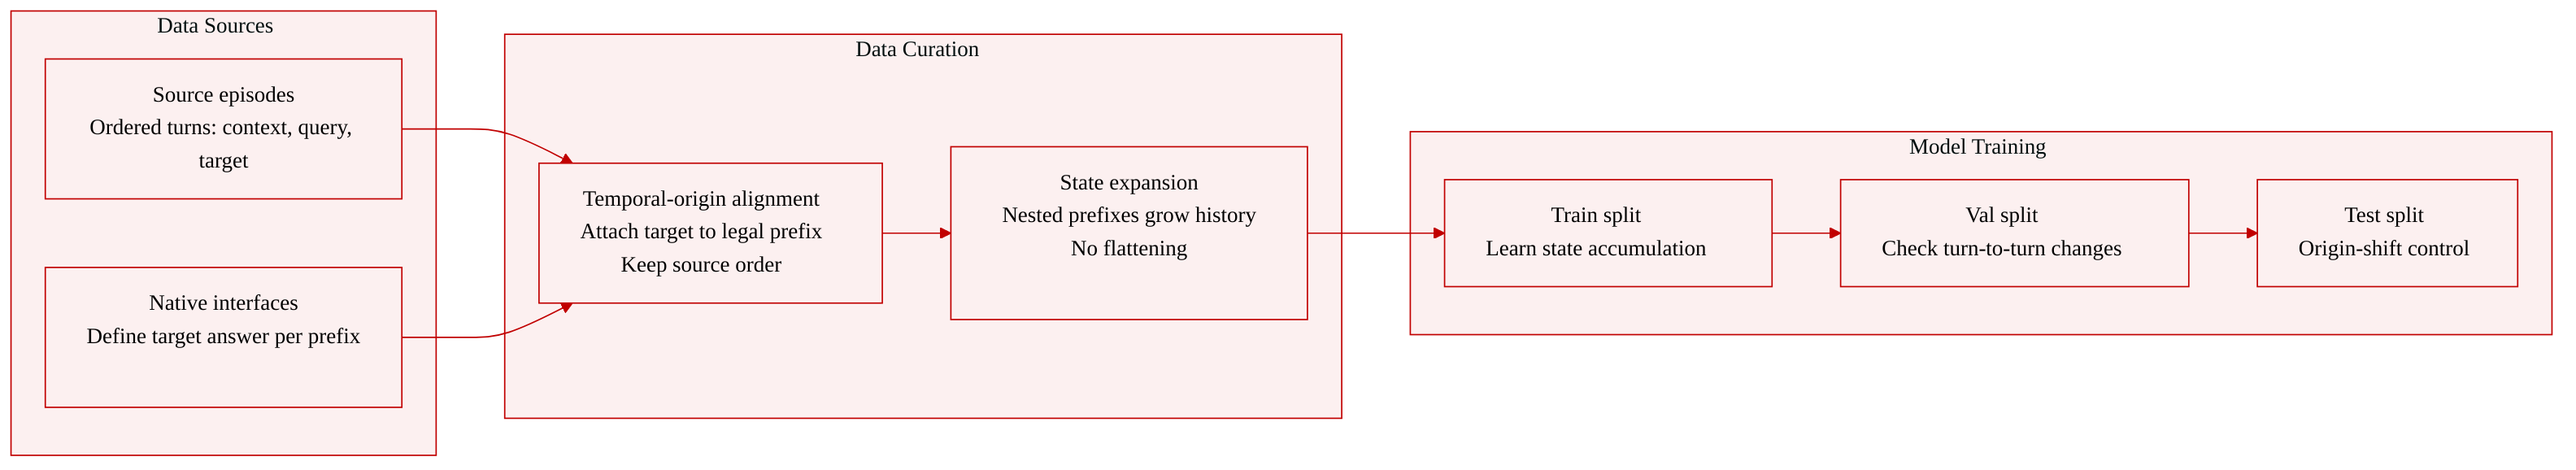
The authors describe a dataset construction rule called temporal-origin alignment. The data is organized as ordered episodes rather than independent question-answer pairs.
Sources and composition
- Supervision comes from source episodes and the interfaces present in those episodes.
- Each episode is written as
E_i = (c_ij, q_ij, y_ij, κ_ij)for turnsj = 1 ... m_i. c_ijis the legal causal prefix at turnj: all observations available at that turn plus preceding interaction history.q_ijis a spatial query.κ_ijidentifies the native interface that produces the query.y_ijis the target answer produced by that interface at the current prefix.- Prefixes are nested, so
c_ijis included inc_{i,j+1}.
Processing rules
- Each target is attached to its legal causal prefix.
- Multi-round annotations are not flattened into isolated pairs.
- The source order and conditioning history are preserved on the original video time axis.
- One episode yields
m_isupervised states that share an origin and grow in history length. - Single-turn examples correspond to
m_i = 1, while multi-round metric-temporal examples form longer episodes.
Usage in the model
- The model is trained on state accumulation itself, learning how a displacement or event order changes from turn to turn.
- Applying the VLM to successive prefixes induces an implicit state trajectory.
- No map, memory module, or auxiliary state loss is added.
- The first prefix defines the episode origin.
- An origin-shift control changes the ordering and preceding context while keeping each turn block and its local supervision, testing the overall contribution of the chronological replay rule.
Method
The authors propose ChronoReplay, a post-training framework for Vision-Language Models (VLMs) that enables a single shared representation to support native spatial readouts while preserving the historical context each readout depends upon. The methodology operates in two primary stages: Causal Replay construction and Family-balanced learning.
As shown in the figure below, the framework processes heterogeneous data into a unified replay pool and optimizes the model using a balanced objective.
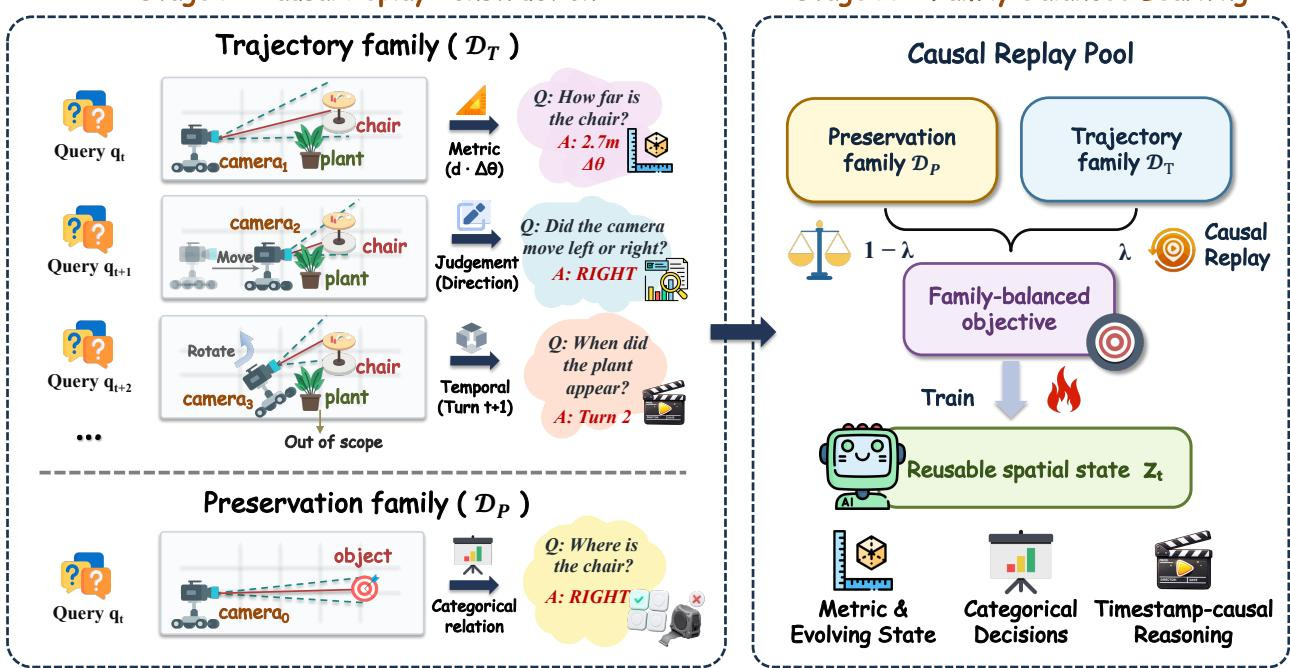
In the first stage, Causal Replay construction, the authors ensure that heterogeneous answer spaces are combined without losing task-specific semantics. Rather than applying an additional answer-space transformation, each target is retained in the native value space of its source interface. Categorical targets maintain their candidate structure, metric targets preserve magnitude, sign, units, and precision, and temporal targets retain timestamps and event indices. For a given interface κ, the population risk for the native target Yκ given the VLM representation Z=Fθ(C) of a causal prefix C is defined as:
Rκ(Fθ,Gκ)=E[−logGκ(Yκ∣Z,Q)]To resolve the ambiguity of metric or temporal targets detached from their history, the authors enforce temporal-origin alignment. Supervision is placed on the video-time axis of the source episode and replayed in its original chronological order. An episode Ei is represented as a sequence of legal causal prefixes, spatial queries, native targets, and interface identifiers:
Ei=(cij,qij,yij,κij)j=1mi,cij⪯ci,j+1where the causal prefix inclusion cij⪯ci,j+1 ensures that the model is trained on the accumulation of history rather than isolated snapshots. Applying the VLM to these successive prefixes induces an implicit state trajectory zij=Fθ(cij) without requiring auxiliary memory modules or state losses.
In the second stage, Family-balanced learning, the authors address the disparity in size between the preservation family DP (comprising 33,180 single-turn examples) and the trajectory family DT (comprising 6,381 ordered episodes yielding 45,006 supervised turns). To prevent one family from dominating the shared parameters, the authors normalize the risk within each family. The preservation risk LP and the trajectory risk LT are formulated as:
LP=∑r∈DPwr∑r∈DPwrℓrP,LT=∣T∣∑(i,j)∈TℓijTwhere ℓrP and ℓijT represent the native losses for the respective examples, and wr denotes source-defined weights. The final balanced objective combines these normalized risks:
Lreplay=(1−λ)LP+λLT,λ=1+ααHere, α controls the relative loss mass of the trajectory family compared to the preservation family. By setting α=0.5, the trajectory family receives one-third of the total mass, while the preservation family receives two-thirds. Furthermore, answer-length normalization assigns each supervised turn an average token loss to prevent long responses from dominating the optimization solely through token count.
Experiment
The experiments evaluate ChronoReplay on OVO-S-Bench, OST-Bench, and UCS-Bench using a fixed Qwen3-VL-8B base, with controlled comparisons for training variants, answer formats, training order, and observation access. Results show that ChronoReplay transfers across categorical, continuous, and timestamp-causal reasoning, with the largest gains when answers require composing accumulated multi-turn state. Diagnostic analyses attribute the effect to the full chronological replay recipe rather than single-family training, and show that native targets and chronological order redistribute or improve transfer across readouts. Observation access is further isolated as an orthogonal factor, where adaptive access adds benefits beyond the training gain.
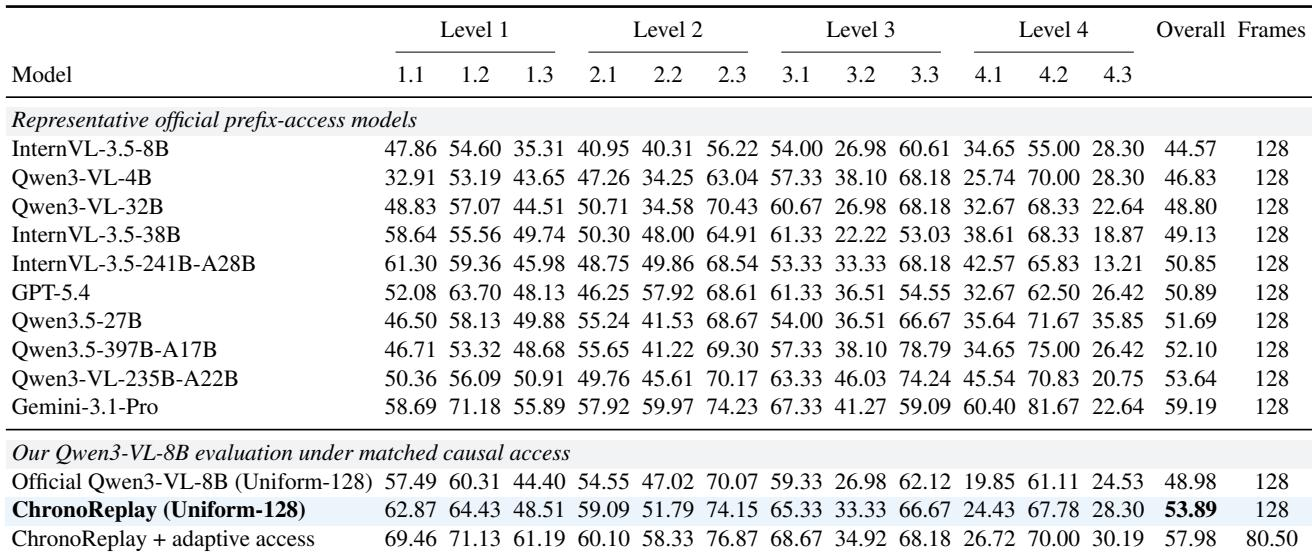
Among the representative official prefix-access models, overall accuracy is relatively close, with the largest InternVL model leading and the smallest InternVL model trailing. Task-family scores vary widely, and the final Level 4.3 task family is among the weakest across the listed models. Training and adaptive access contribute separate gains, with adaptive access helping most on Level 1 while Level 4 remains the hardest. The largest listed InternVL model achieves the highest overall accuracy, while the smallest listed InternVL model records the lowest overall. The final Level 4.3 task family is among the weakest for every listed model, and several other task families fall well below the strongest families. Training improves all four levels, while adaptive access adds the largest additional lift on Level 1 and also improves Level 4, which remains the hardest level.
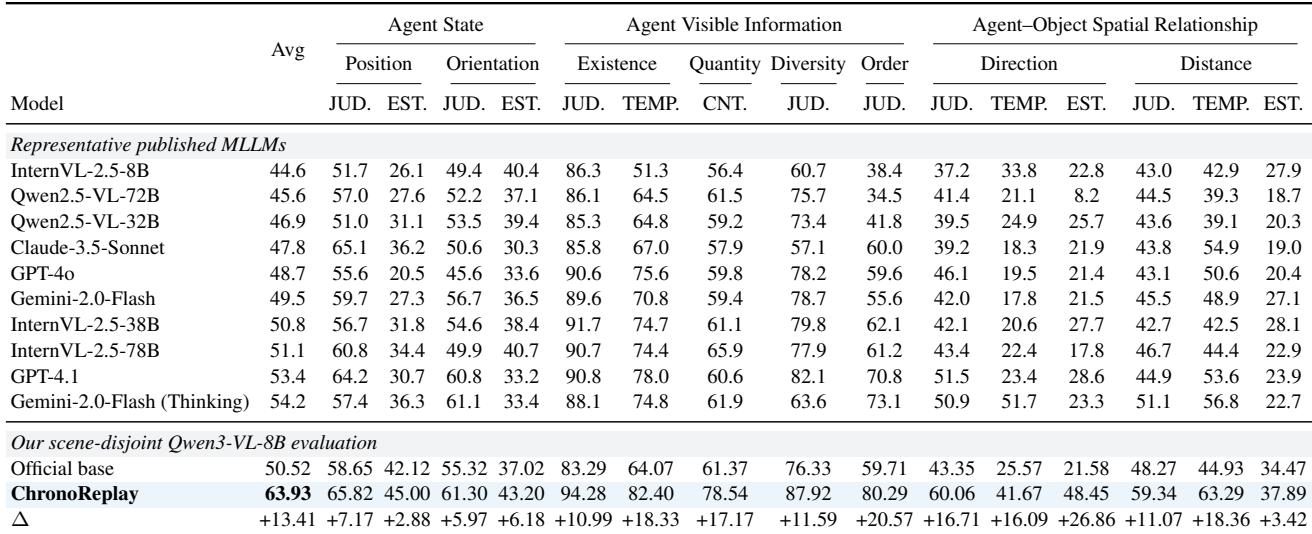
ChronoReplay improves fine-grained OST-Bench performance relative to the base model under matched scene-disjoint evaluation, with positive transfer across all fifteen subtypes. Gains are largest for direction estimation, order judgement, and distance temporal localization, tasks that require composing answers from accumulated multi-turn state. Lower-scoring difficulty levels also improve, though the hardest level remains the lowest. Overall OST-Bench accuracy rises by 13.41 points over the base under the scene-disjoint protocol. All fifteen fine-grained subtypes improve, and the largest gains appear in direction estimation, order judgement, and distance temporal localization. Improvements concentrate where answers depend on accumulated multi-turn state rather than only the current view. All twelve difficulty families improve, but the lowest-scoring level remains the hardest.
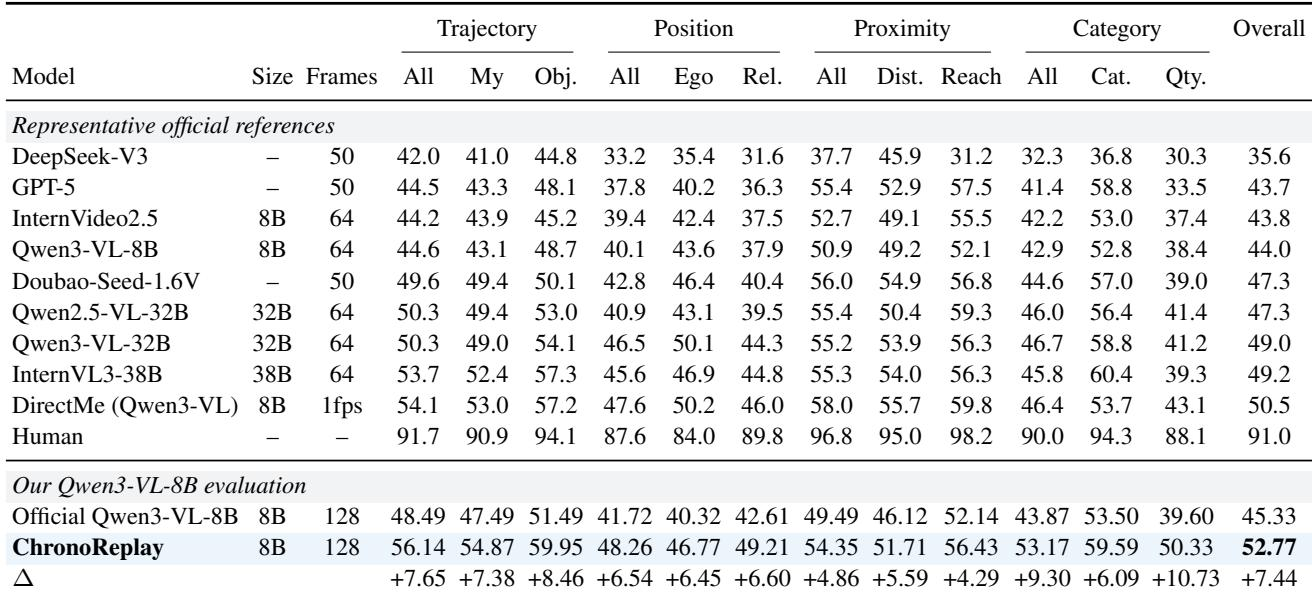
Reference models are consistently stronger on trajectory and proximity questions than on position and category questions, with object and reach subcategories often contributing to the higher scores. Doubao-Seed-1.6V leads the listed models overall and across aggregate groups, while the remaining reference models cluster near one another. The category group shows the largest internal spread, with categorical questions far ahead of quantity questions. Trajectory and proximity aggregates score highest, whereas position and category aggregates are consistently lower across reference models. Doubao-Seed-1.6V is the strongest listed model overall and in every aggregate group, while the other models are closely grouped and remain weak on relational and quantity subcategories.
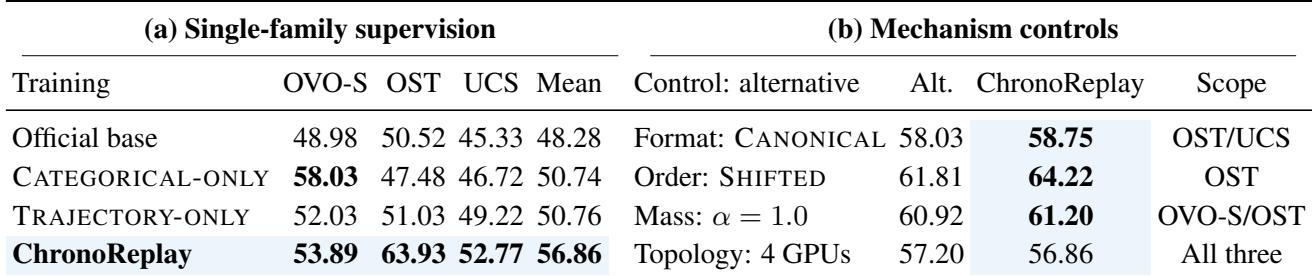
The diagnostic analysis shows that full ChronoReplay achieves the strongest overall three-benchmark result, while single-family supervision creates uneven cross-readout transfer. Control experiments attribute gains to the balanced objective and chronological ordering, while answer format mainly redistributes performance between OST and UCS rather than improving all endpoints uniformly. Full ChronoReplay attains the highest three-benchmark mean, clearly above categorical-only, trajectory-only, and the official base. Categorical-only supervision improves OVO-S but sharply reduces OST, while trajectory-only supervision yields more balanced but lower results. ChronoReplay outperforms ordinary token SFT and natural turn weighting on all three evaluated endpoints. Native answer format favors UCS and the two-benchmark mean, whereas canonical format favors OST, indicating redistribution rather than uniform gains. Chronological replay leads shifted training order on OST in both seed pairs, supporting the temporal-origin alignment.
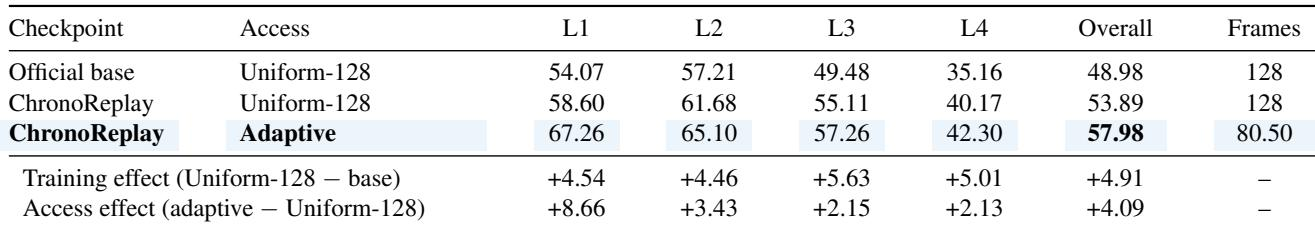
ChronoReplay training raises accuracy over the official base at every difficulty level and overall, with the overall training gain just under five points. Adaptive observation access then adds a further overall gain just over four points, with the largest level benefit on L1 and the smallest on L4. L4 remains the hardest level even after both interventions. ChronoReplay training improves every difficulty level, with an overall gain just under five points over the official base. Adaptive access adds an overall gain just over four points, with the largest improvement on L1 and a smaller improvement on L4, while using fewer frames.
The experiments compare representative prefix-access models, then evaluate ChronoReplay against its base model under scene-disjoint OST-Bench, followed by reference-model and diagnostic analyses. Prefix-access baselines show close overall accuracy but wide task-family gaps, with Level 4.3 consistently weak and adaptive access helping most at Level 1 while Level 4 remains hardest. ChronoReplay improves all fifteen fine-grained OST-Bench subtypes and all difficulty families, especially direction estimation, order judgement, and distance temporal localization, indicating gains where answers depend on accumulated multi-turn state. Reference models are strongest on trajectory and proximity and weakest on position and category, with Doubao-Seed-1.6V leading overall; diagnostic ablations attribute ChronoReplay's gains to the balanced objective and chronological ordering, while answer format mainly redistributes performance between OST and UCS, and training plus adaptive access improve all levels but leave L4 hardest.