Command Palette
Search for a command to run...
PaperScorer: 論文の採択はどの程度予測可能か
PaperScorer: 論文の採択はどの程度予測可能か
Sachin Konan Jonathan Liu Zhuang Liu
概要
自動化された研究は主にベンチマーク性能で評価されるが、研究の価値が単一のスコアに還元されることはほとんどない。人間は研究の全体的な貢献を査読によって判断するが、査読はノイズが多く多くの要因に依存するため、モデル化が難しい。しかし、論文そのものだけから査読の判定を直接予測できるとしたらどうだろうか。本研究では、抽出されたテキストまたはページのスクリーンショットから論文の採録・不採録判定を予測するモデル群PaperScorerを提案する。著者情報や書式上の手がかりを除去した上で、判定のみを学習する。視覚モデルが最も高い予測力を示し(ICLR論文で68%、arXivのML論文で77%の精度)、テキストのみのモデルや最先端推論モデルを上回った。プレーンテキストとは異なり、ページ画像は図、レイアウト、体裁を保持している。このシグナルは頑健であり、より小型のモデルでも、さらには論文全体を1枚の画像に圧縮しても維持される。しかし、正確な予測は一様に分布しているわけではない。PaperScorerは最低評価と最高評価の論文で最も強く、中間評価の論文は我々のモデルと最先端システムのいずれにとっても予測困難なままである。さらに、その確信度は較正されており、最も確信度の高い予測が最も正確でもある。全体として、PaperScorerは論文がそれ自体で採否判定のどの程度を担っているかを示しており、AI駆動型の研究評価に向けた第一歩となる。
One-sentence Summary
Researchers at Princeton University introduce PaperScorer, a family of models that predict paper accept or reject decisions from extracted text or page screenshots after removing author identity and formatting shortcuts; vision models achieve 68% accuracy on ICLR papers and 77% on ML papers from arXiv, with calibrated confidence that is strongest on the lowest- and highest-rated papers, marking a first step toward AI-driven research evaluation.
Key Contributions
- The paper introduces PaperScorer, a family of text and vision models that predict a paper’s final accept or reject decision directly from extracted text or page screenshots, using datasets where labels are recoverable only from paper content. Vision-based PaperScorer models achieve 68% accuracy on ICLR papers and 77% on arXiv ML papers, outperforming text-only and frontier reasoning baselines.
- The paper shows that page screenshots provide a stronger decision signal than plain text because they preserve layout, figures, and presentation cues, and this signal remains robust with smaller models and even when a whole paper is compressed into a single image. Predictions are most accurate for the lowest and highest rated papers, and model confidence is calibrated.
- The paper demonstrates PaperScorer as a calibrated acceptance probability prior in scientific workflows: combining PaperScorer-Vision with dense retrieval improves top-10 citation recall on the LitSearch benchmark by 8.7%, and conditioning an agentic reviewer on this prior raises decision accuracy from 63.0% to 70.6%.
Introduction
Large language model agents increasingly automate research end to end, so evaluation must scale beyond benchmarks and reflect human peer review. However, peer review is noisy and poorly understood: consistency experiments show committees often disagree, and LLM-assisted reviews can add further variation. Prior work on predicting paper outcomes often leaked labels through formatting, author-identifying text, source artifacts, or majority-class shortcuts rather than isolating the paper’s own content. The authors address this by introducing PaperScorer, a family of text and vision models trained on fully anonymized, balanced ICLR and arXiv papers to predict final accept or reject decisions from paper content alone. Their main contribution is showing that documents contain recoverable but limited decision signal, with the top vision model reaching 68% accuracy on ICLR and 77% on arXiv, outperforming frontier baselines while producing calibrated acceptance probabilities.
Dataset
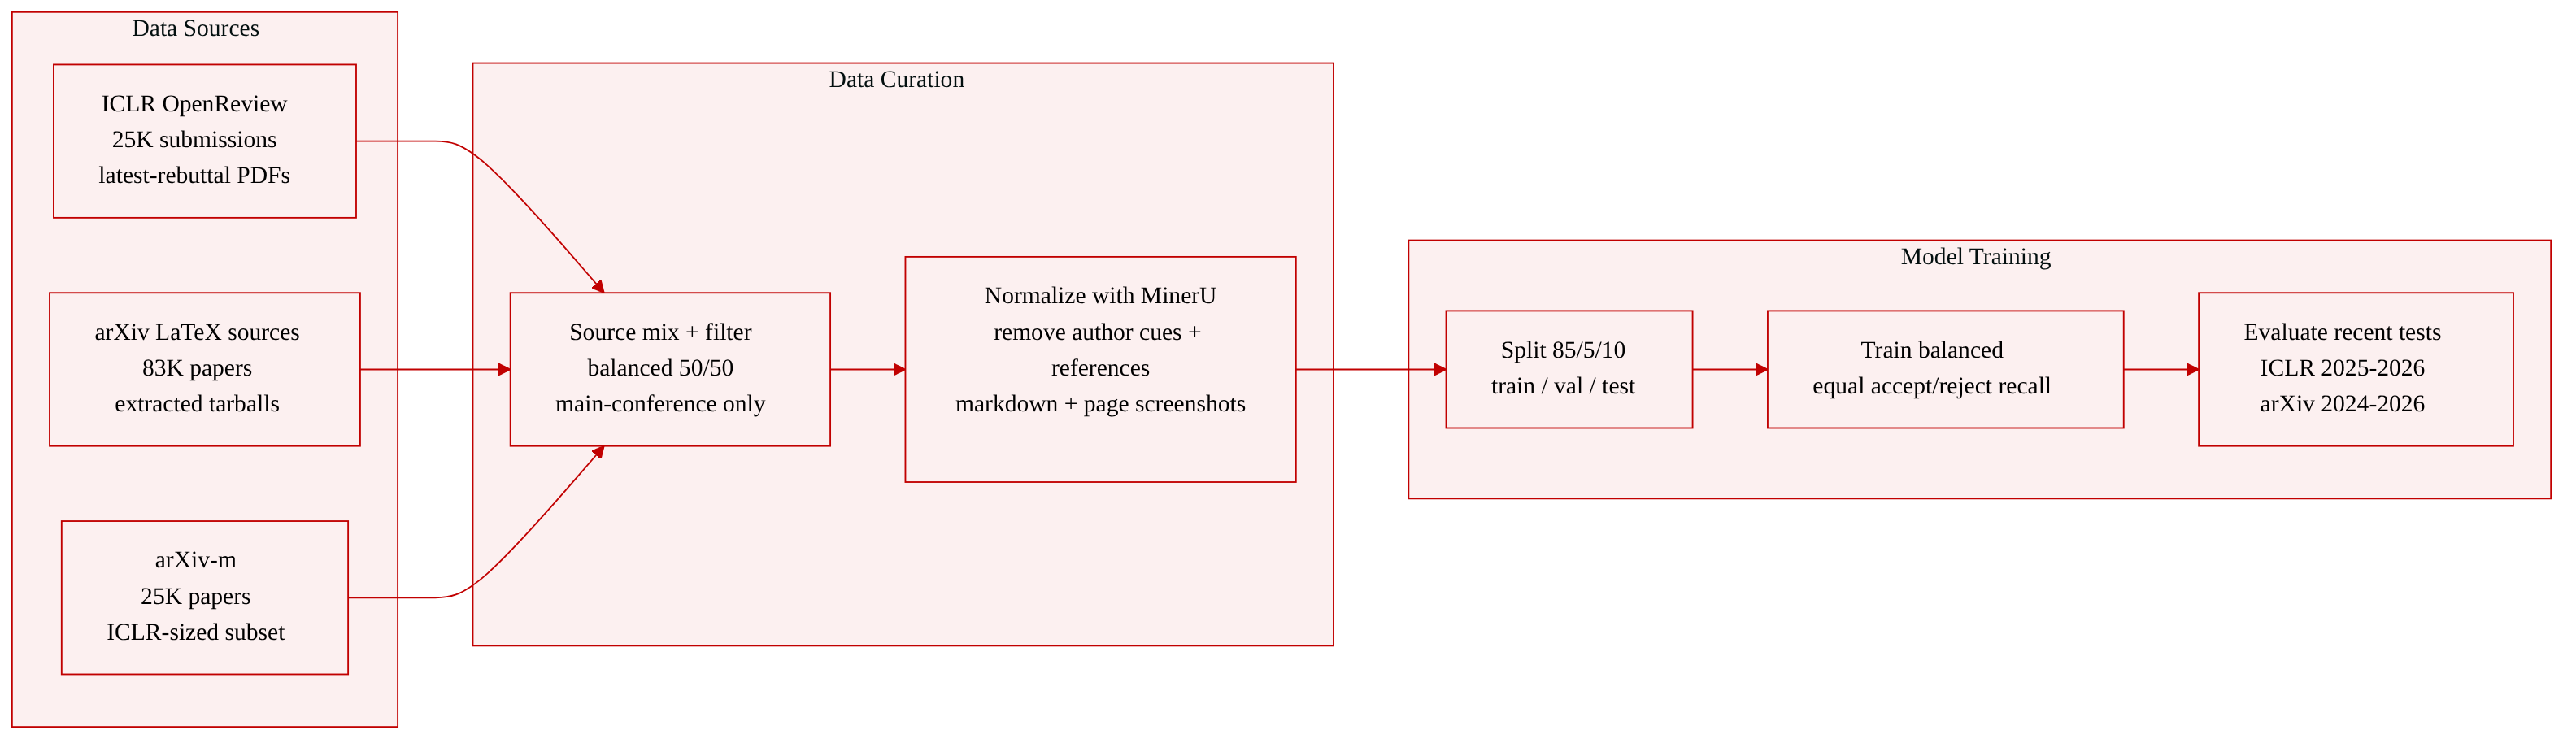
The authors describe two balanced accept/reject datasets used for PaperScorer. Each dataset pairs anonymized markdown text with page screenshots and an accept/reject label.
Dataset composition and sources
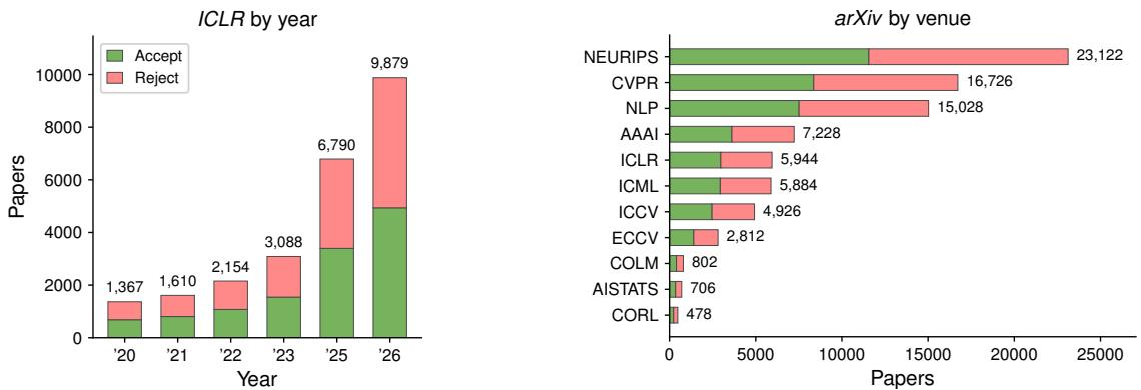
- ICLR: 25K submissions from OpenReview, balanced 50/50, split 85/5/10, evaluated on ICLR 2025-2026.
- arXiv: LaTeX-source-derived proceedings papers, balanced 50/50, split 85/5/10, evaluated on 2024-2026 to include biannual venues like ECCV.
- arXiv training uses an 83K set (arXiv) and a smaller 25K set proportional to ICLR (arXiv-m).
ICLR subset
- Uses ICLR 2020-2023, 2025, and 2026; ICLR 2024 is excluded because accepts are only camera-ready.
- Latest-rebuttal PDFs are used as anonymized artifacts.
- Filtering requires anonymity, main-conference scope, and consistent processing of accepts and rejects; rejects are subsampled to balance within year while keeping the annual distribution.
arXiv subset
- Starts from 434,579 machine learning arXiv papers; 434,443 LaTeX source tarballs are extracted with NeMo Curator.
- Accept labels come from title matches to conference proceedings.
- Implied rejects are LaTeX-compiling papers using covered venue templates that pass main-conference filters but do not appear in proceedings.
- Filtering removes non-main-conference, workshop, withdrawn, industry-track, and short-format papers; an anonymous render, references section, and 6 to 30 main content pages are required.
- 101,659 filtered papers are subsampled to 83,656 balanced papers, preserving the starting venue distribution rather than year-balancing.
Processing and input schema
- Both sources use the same MinerU normalization and remove headers, line-numbering asides, author-identifying spans, and content in or after references.
- Text inputs use markdown with excluded regions omitted, up to a 24,480 max context length.
- Vision inputs use page screenshots with the same excluded regions whitened; each page is downscaled to at most 1,003,520 pixels, roughly 1,240 vision tokens per page.
- A typical paper is about 10 pages, up to 33, so vision input averages around 12,420 tokens.
Use in training and evaluation
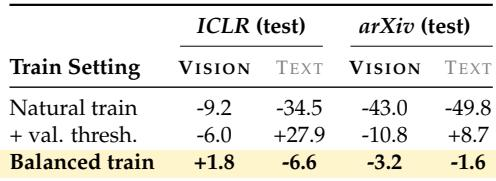
- Training uses balanced 50/50 splits so accept and reject recall are equally weighted and the model does not default to over-predicting rejection.
- Evaluation uses the most recent test years: ICLR 2025-2026 and arXiv 2024-2026.
- arXiv is also used for transfer experiments: within arXiv to assess diverse supervision, and across sources by testing arXiv-trained models on ICLR and ICLR-trained models on arXiv.
Method
The authors build PaperScorer on two balanced, anonymous accept/reject corpora derived from ICLR and arXiv. To ensure the model evaluates the same evidence available to a final decision maker, the data pipeline enforces strict anonymity, restricts inputs to main-conference submissions, and ensures consistent processing for both accepted and rejected papers. For the arXiv corpus, the authors extract LaTeX source tarballs, detect venue-specific style files, and compile anonymous review-mode PDFs. Both sources then pass through a MinerU normalization pipeline. Headers, line-numbering asides, and author-identifying spans are removed. Text models receive the cleaned markdown, while vision models receive page screenshots with excluded regions whitened.
As shown in the figure below:
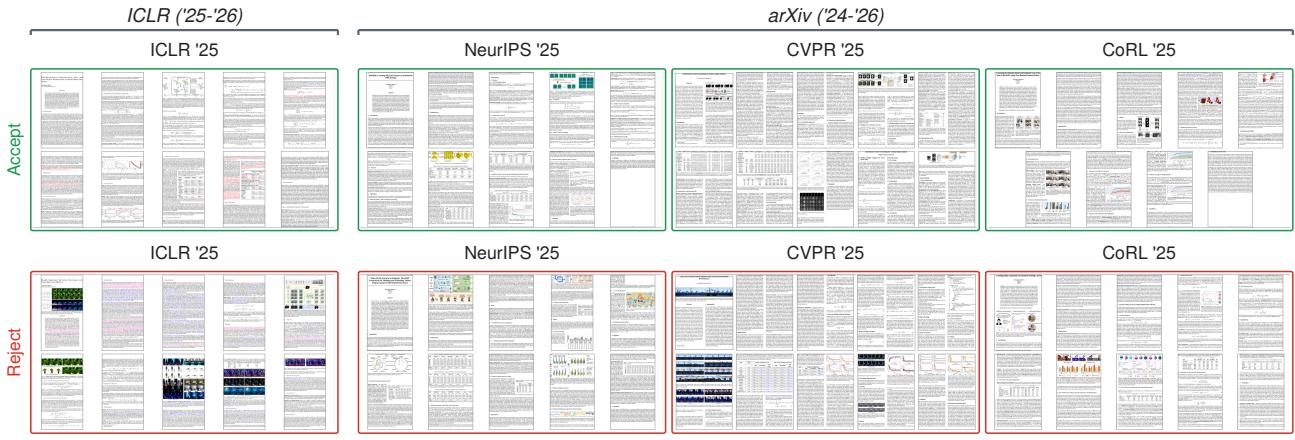
The coverage of these datasets is carefully managed to support transfer learning experiments. The ICLR pool subsamples rejects to maintain a balanced distribution across years, while the arXiv pool is subsampled to preserve the starting venue distribution.
As shown in the figure below:
The authors leverage Qwen2.5 text and Qwen2.5-VL vision backbones for their primary models. For text inputs, the full markdown is used up to a maximum context length of 24,480 tokens. For vision inputs, each page is rendered and downscaled to approximately 1,240 vision tokens. Given that a typical paper runs about ten pages, the total vision input averages roughly 12,420 tokens.
Supervised fine-tuning (SFT) serves as the primary method for studying data representation and calibration. The authors fine-tune Qwen2.5 text models at 3B, 7B, and 14B scales, and Qwen2.5-VL models at 3B and 7B scales. Let Pθ(⋅∣x) denote the model’s next-token distribution at the decision token for a paper x. Since Accept and Reject are individual tokens in the Qwen2.5 vocabulary, the authors read off the probability of each and normalize over the two to compute the acceptance probability:
paccept=Pθ(Accept∣x)+Pθ(Reject∣x)Pθ(Accept∣x).After SFT, the decision mass lies almost entirely on these two tokens, allowing paccept to function as a usable binary accept probability.
For reinforcement learning variants, the authors fine-tune the policy using Group Relative Policy Optimization (GRPO). The policy utilizes a reasoning prompt, samples a group of completions for each paper, and updates using within-group relative rewards rather than a learned reward model. This allows the model to reason before producing its final label. Each completion y for a paper x is scored with the following reward function:
r(y,x)=0.8⋅1[d(y)=d⋆(x)]+0.2⋅1[FORMAT(y)],where d(y) extracts the boxed Accept/Reject decision, d⋆(x) is the ground-truth decision, and FORMAT(y) verifies that the completion contains the required thinking block followed by the boxed answer.
The authors compare their approach against several baselines, including DeepReview, Gemini, GPT, and frontier coding-agent harnesses. They observe that several baseline models exhibit a strong bias toward one decision class under default prompts. To address this, the authors tune a threshold on the baseline scores using a small held-out sample of papers. This calibrated threshold is used as the hard label when it improves accuracy, correcting for the skewed out-of-the-box decision thresholds while preserving the well-ordered nature of the predicted ratings. Balanced training and evaluation are employed throughout to ensure accuracy equally weights accept and reject recall, preventing predictors from achieving high scores simply by rejecting the majority of papers.
Experiment
The evaluation tests PaperScorer on ICLR and arXiv accept/reject prediction and ranking, using accuracy, AUC, calibration, and reviewer-rating correlation, with comparisons to simple paper-feature logistic models, frontier prompting models, and coding agents. Direct accept/reject supervision yields the strongest decision and ranking signal, and the vision variant consistently beats text and frontier baselines, likely because visual layout and presentation cues carry recoverable decision signal even under heavy compression. After temperature scaling, PaperScorer confidence tracks accuracy and covers more confident predictions than Jev, while venue analysis shows it matches or beats frontier models on most high-coverage venues except vision-heavy CV conferences where general vision models compete.
Balanced training yields the smallest absolute accept-reject recall gap across every test configuration, bringing bias close to zero. Natural training produces large negative recall gaps, especially for text and arXiv, while adding a validation threshold reduces several gaps but leaves sign direction inconsistent across modalities. Balanced training has the lowest absolute accept-reject recall gap across ICLR and arXiv, for both vision and text. Natural training shows large negative recall gaps, with the most severe bias on arXiv text. Adding a validation threshold moderates visual and arXiv-text gaps but shifts text-domain gaps positive.
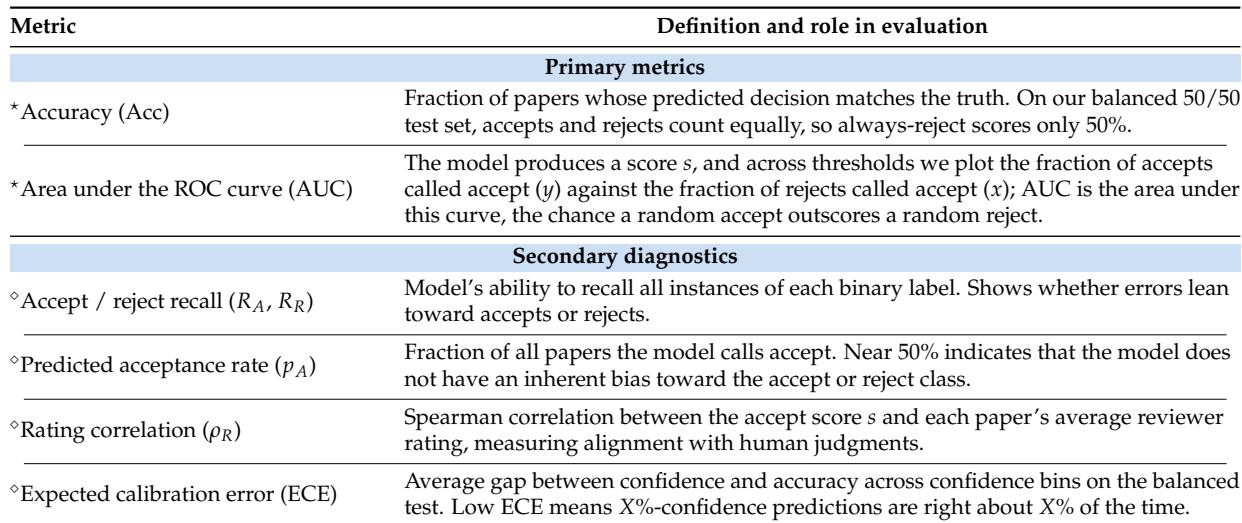
Evaluation separates primary metrics that steer training from secondary diagnostics for behavioral analysis. PaperScorer models are well calibrated and provide selective confidence, covering more papers at high confidence than Jev while remaining accurate. Accuracy varies by human rating and venue, with PaperScorer-Vision competitive except on vision-heavy CV venues. Calibration improves sharply when shifting to a real acceptance rate, and reject calls become more reliable than accept calls. All models are most accurate on the lowest-rated papers and near chance in the middle of the rating range, but PaperScorer-Vision remains accurate on the highest-rated papers. Across high-coverage venues, PaperScorer-Vision matches or beats the best frontier model except on vision-heavy CV venues.
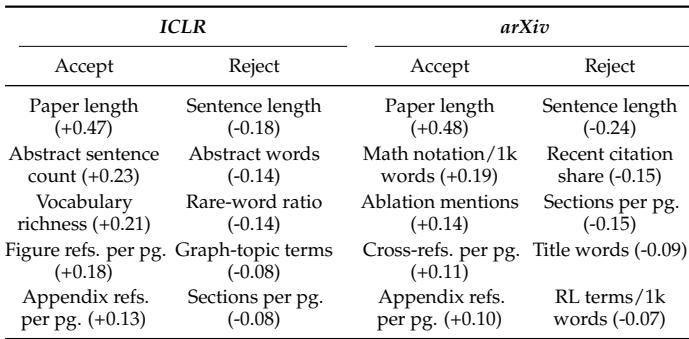
The table reports logistic regression feature weights for predicting accept versus reject decisions on ICLR and arXiv submissions. Longer papers and more structured elements such as figures, appendices, and cross-references tend to increase predicted acceptance, while longer sentences and more sections per page tend to decrease it. Venue-specific patterns include positive weights for math notation and ablation mentions on arXiv and negative weights for recent citation share and RL-related terms. Paper length is the strongest positive feature for both ICLR and arXiv, while sentence length is the strongest negative feature for both. ICLR accept signals include abstract sentence count, vocabulary richness, and figure references per page; arXiv accept signals include math notation, ablation mentions, and cross-references per page.
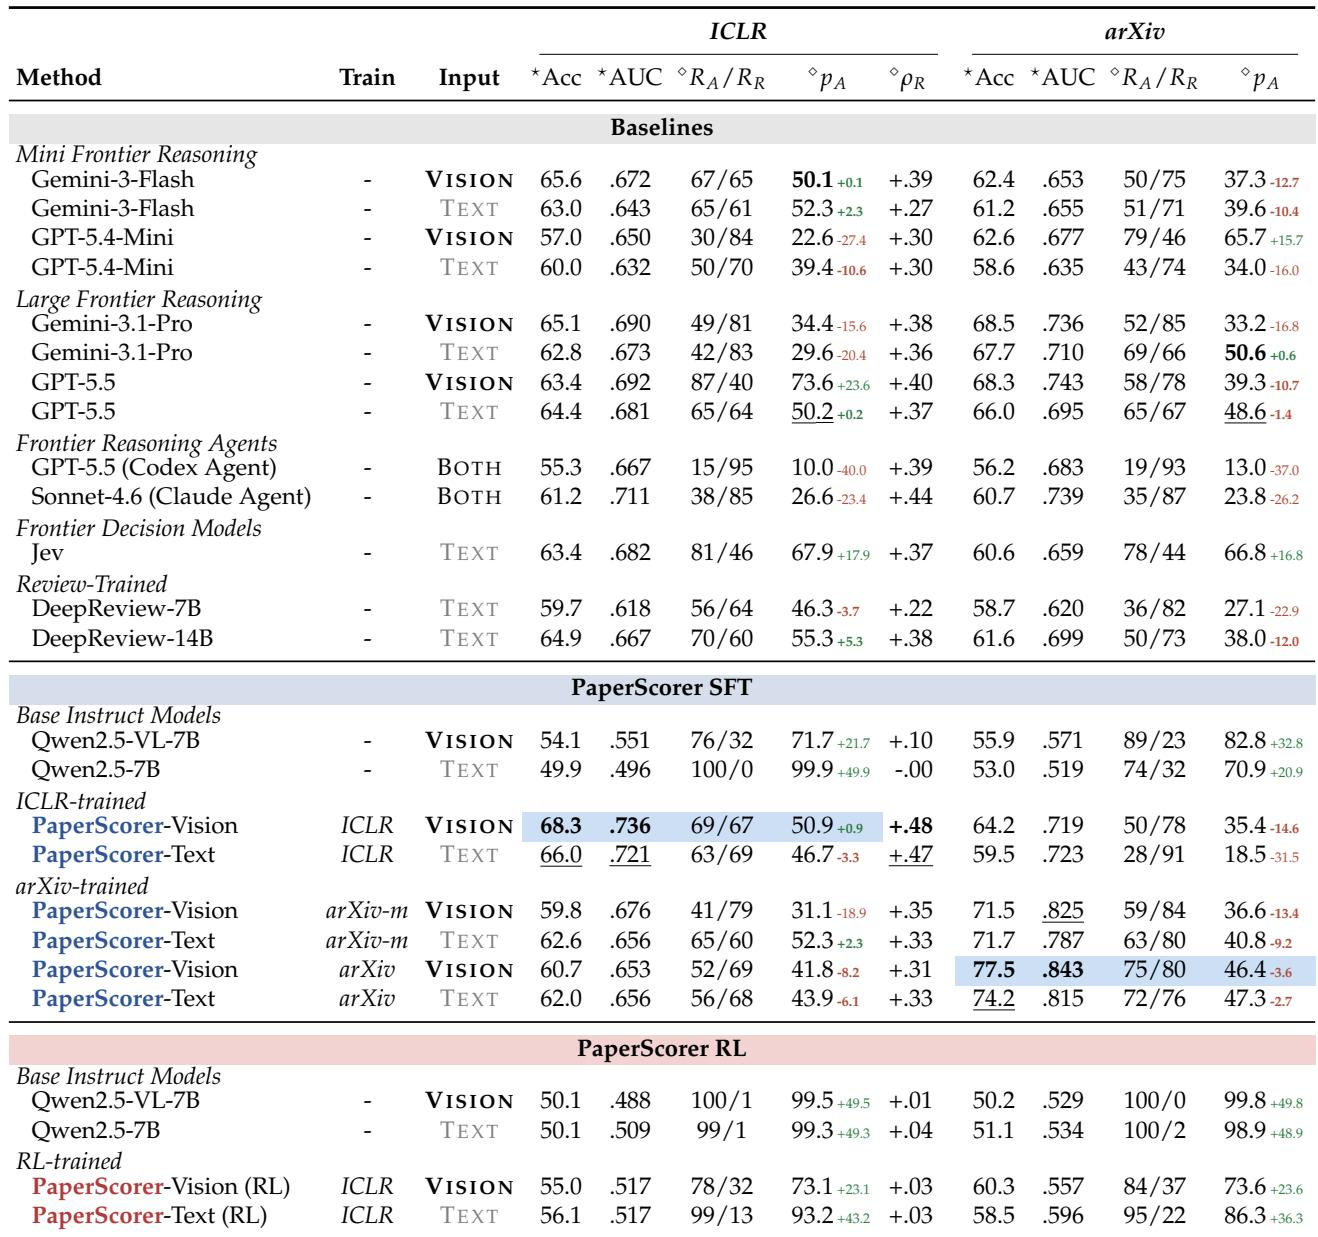
PaperScorer's direct accept/reject supervision produces stronger decision and ranking signals than prompting baselines, trained reviewers, and frontier reasoning systems. Across ICLR and arXiv test sets, PaperScorer variants lead in accuracy and AUC, with vision inputs strongest overall and models performing best on the source domain they were trained on. Frontier and coding-agent baselines can rank papers reasonably well but often turn those rankings into skewed accept/reject decisions. Smaller reasoning models are heavily skewed by default, with one accepting almost every paper and another rejecting almost every paper. Large frontier systems are more accurate but still produce unstable accept rates, swinging between accepting under a third and nearly three quarters of papers depending on the setting. Coding agents achieve strong ranking correlation and competitive AUC, but their accept/reject accuracy remains lower than the best non-agent frontier baselines. PaperScorer-Vision outperforms the best frontier vision model on both datasets, with a larger margin on arXiv when trained on arXiv data. PaperScorer keeps accept and reject recalls balanced, whereas frontier systems rank well but natively skew their decisions. A 7B supervised decision model can beat large frontier reasoning systems by learning a direct decision signal from paper content.
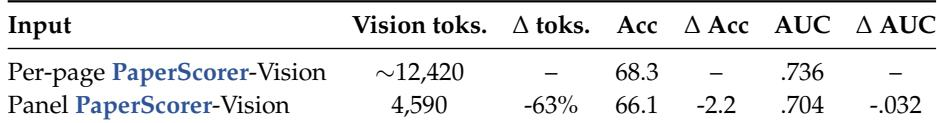
On the ICLR test set, a panel-based input reduces vision-token usage to about one third of the per-page cost while retaining most of the decision quality. The decrease in accuracy and ranking quality is small relative to the token savings. This ablation is limited to the ICLR-trained model, since no arXiv panel model was trained. Tiling ten pages into one panel image cuts vision-token cost by roughly two thirds while accuracy stays within a few points of the per-page baseline. The panel model preserves most ranking quality with only a small AUC decrease, and the findings apply to the ICLR-trained model only.
The experiments evaluate PaperScorer on ICLR and arXiv accept/reject decisions, comparing training strategies, calibration, feature interpretability, baselines, and a panel-image efficiency ablation. Balanced training largely eliminates accept-reject recall bias, while direct supervision yields stronger decisions and rankings than prompting baselines, trained reviewers, and frontier reasoning systems, especially with vision inputs. Qualitative diagnostics show the model is well calibrated and selective, reject calls are more reliable than accept calls, and longer structured papers predict acceptance while longer sentences predict rejection. A panel-image input reduces vision token cost by about two thirds with only small accuracy and ranking losses, though this result is limited to the ICLR-trained model.