Command Palette
Search for a command to run...
実世界Web環境における深層検索
実世界Web環境における深層検索
概要
深層検索エージェントに大きな進展が見られるにもかかわらず、実世界のオープンWeb環境でエンドツーエンドの調査を行う能力は依然として十分に評価されていない。静的検索設定とは異なり、実世界のWeb上の情報は多様な情報源・モダリティ・異種形式に分散しており、しばしば複雑なインタラクション機構を伴うため、エージェントは実行中に関連証拠を自律的に検索・アクセス・統合する必要がある。このギャップに対処するため、我々は、実在するオープンWeb上で多段階の深層検索を実行するエージェントの能力を評価するために設計されたOpenDSタスクを導入する。このタスクは、エージェントが実Webを自律的に探索し、Web検索・ブラウザ操作・証拠処理を通じて複数の独立した情報源から関連証拠を発見・接続し、最終的に一意な事実的解答を決定することを要求する。このタスク設計に基づき、我々はOpenDS-Worldを構築する。これは多様な情報モダリティ・異種ファイル形式・インタラクティブなアクセス要件にまたがる200件の難易度の高いタスクから成り、証拠の妥当性と解答の一意性を保証するために独立した人手検証が行われている。我々は統一されたツール環境と実行プロトコルの下で12の最先端モデルを評価した。最高性能のモデルは39.0%の精度を達成し、一方で1,000回の独立した試行にわたる人間による評価は21.1%の精度であった。ツール使用・検索コスト・終了挙動・失敗回復に関するさらなる分析により、モデル間で調査戦略に大きな差異があること、またツールの協調と長期的な検索管理において根強い課題があることが明らかになった。OpenDS-Worldは、実世界のオープンWeb環境におけるエージェントの自律的な深層検索能力を体系的に評価・向上させるための統一的評価プラットフォームを提供する。
One-sentence Summary
Researchers from HKUST(GZ), FDU, UW, et al. introduce OpenDS-World, a 200-task benchmark for multi-step deep search in the live open Web, and report that the best frontier model achieves only 39.0% accuracy compared with 21.1% for humans, underscoring persistent challenges in tool coordination and long-horizon search management.
Key Contributions
- The paper introduces the OpenDS task for evaluating autonomous multi-step deep search on the live open Web, requiring agents to discover, access, and integrate evidence from multiple independent sources to determine a unique factual answer.
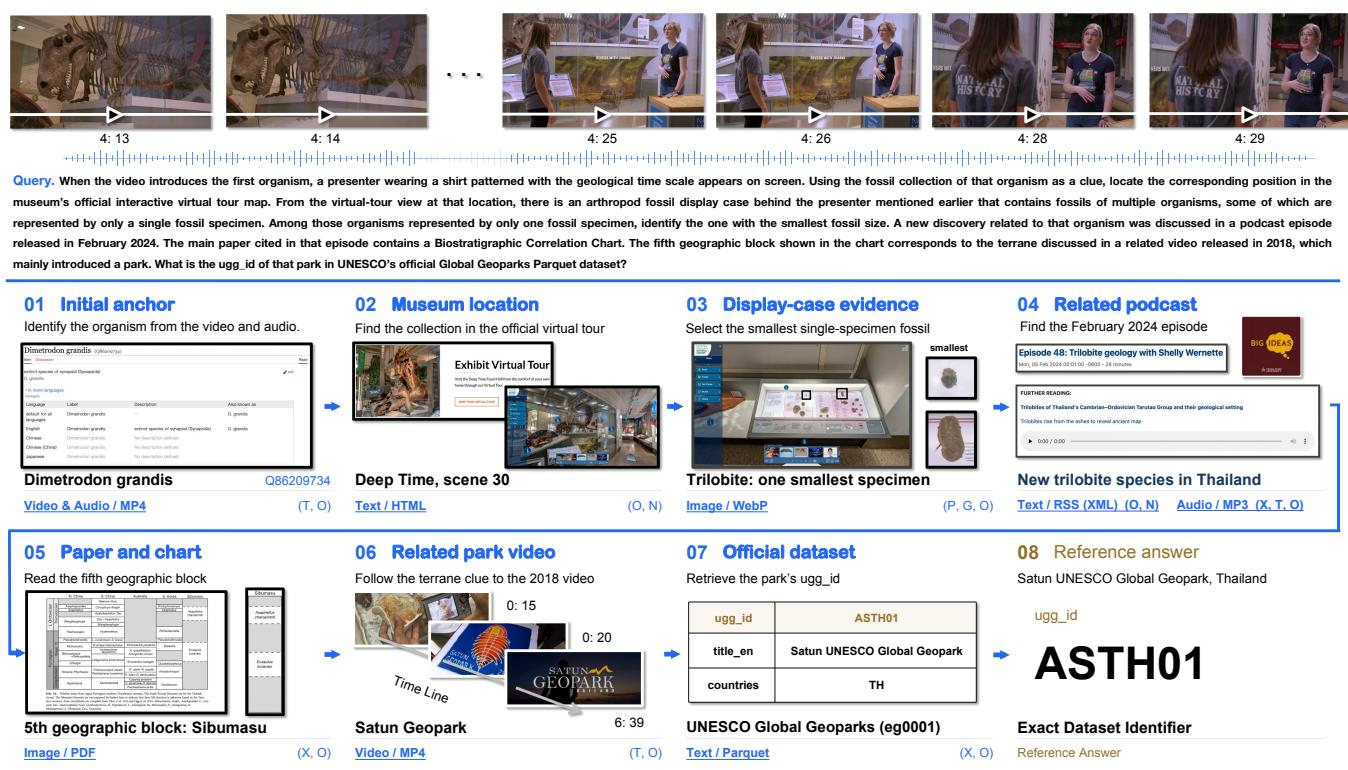
- The paper constructs OpenDS-World, a benchmark of 200 human-verified tasks whose evidence chains span four modalities, 42 file formats, and seven access types, covering heterogeneous online resources and interactive access requirements.
- The paper evaluates 12 frontier models under a unified tool environment and execution protocol. The strongest model achieves 39.0% accuracy, human evaluation across 1,000 independent attempts yields 21.1%, and analyses reveal persistent challenges in tool coordination, search cost, termination behavior, and long-horizon search management.
Introduction
Deep search aims to let AI agents autonomously acquire, analyze, and integrate evidence from the open Web for complex research tasks, and the growth of LLM-based tool-augmented agents has made reliable evaluation in real-world Web environments increasingly important. Existing benchmarks examine tool use, retrieval, persistent search, and Web navigation, but they underrepresent the combined challenges of diverse information modalities, heterogeneous file formats such as HTML, PDF, XML, and Parquet, and interactive access requirements that force agents to navigate, manipulate interfaces, or process artifacts before evidence becomes usable. To close this gap, the authors introduce the OpenDS task and the OpenDS-World benchmark, a human-verified set of 200 tasks across eight domains that require agents to start from a video anchor and connect evidence from multiple open Web sources with different modalities, formats, and access mechanisms. Their evaluation of 12 frontier models shows current systems still struggle, with the best model reaching only 39.0% accuracy.
Dataset
OpenDS-World: Dataset Overview
OpenDS-World is introduced as a factual question answering benchmark for evaluating AI agents on deep search in real world Web environments. It contains 200 tasks spanning culture, daily life, science, economy, history, nature, society, and technology. The provided text names these eight domains but does not report per-domain task counts.
-
Composition and sources:
- 200 benchmark tasks with 787 annotated Web page or online resource entries along evidence chains, averaging 3.94 entries per task.
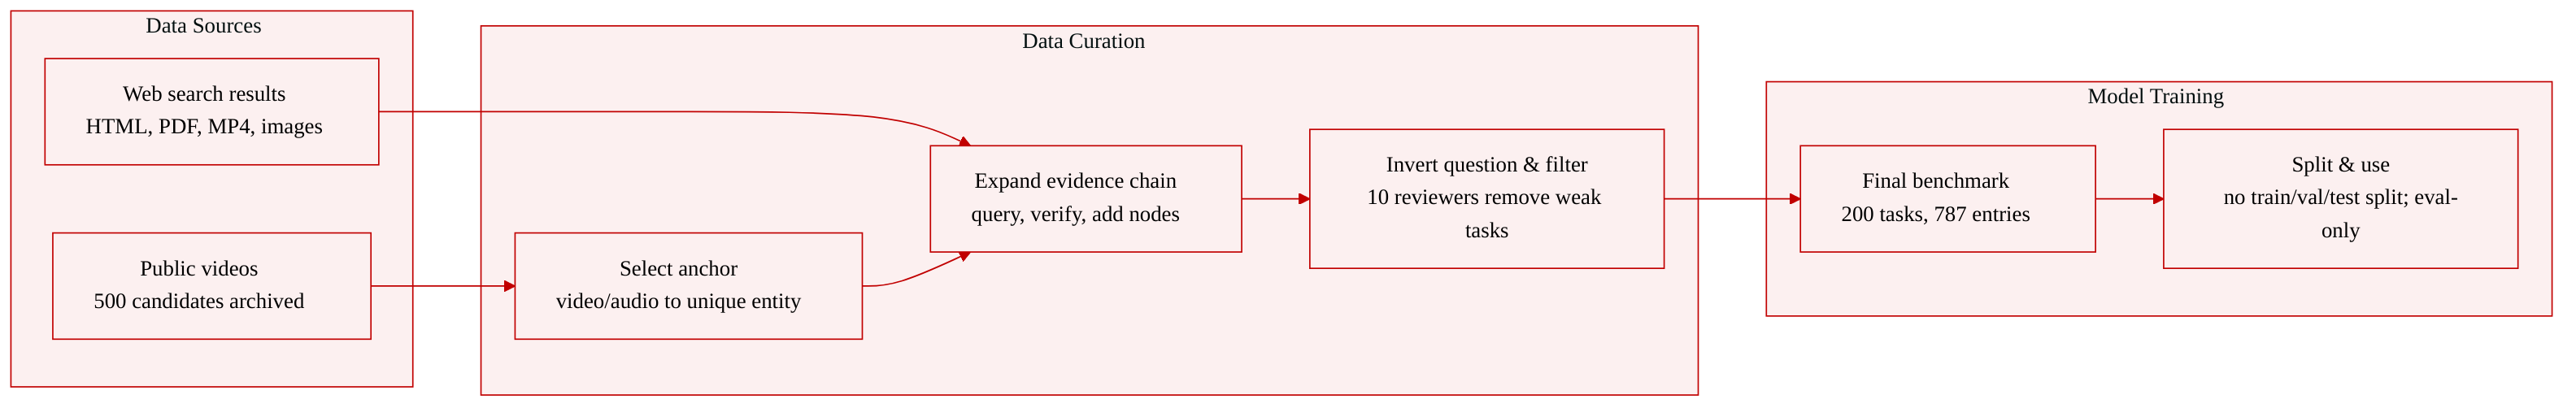
- Initial clues come from publicly accessible videos. The construction stage selected 500 candidate videos, and final tasks use archived video inputs matched by task ID.
- Later evidence sources are discovered through Google Search and include HTML pages, PDFs, WebP images, MP3 audio, MP4 video, RSS/XML, Parquet, and structured interactive resources.
-
Construction:
- Stage 1: annotators select a publicly accessible video and identify an initial anchor from visual and audio content. The anchor must map to a unique valid Wikidata entry, preventing simple textual page search.
- Stage 2: annotators iteratively construct search queries, inspect Google Search results, select verifiable sources, extract new entities, and expand the evidence chain until a unique terminal node is reached. Each node must be independently corroborated by multiple Web sources.
- Stage 3: the terminal node becomes the reference answer. The question is created by inverting the evidence path into interdependent constraints, with intermediate nodes hidden behind indirect referring descriptions.
-
Filtering and verification:
- Ten independent reviewers check evidence validity and task validity.
- They confirm that entities, relations, and answers are factually accurate and supported by accessible, independent Web evidence, and that the initial anchor is uniquely identifiable from video and audio content.
- Tasks with factual errors, insufficient evidence, inconsistent relations, ambiguous questions, or non unique answers are removed.
-
Metadata and processing:
- Each resource entry is annotated with three attributes: evidence modality, resource format, and access type.
- The benchmark covers 4 modalities, 42 formats, and 7 access types.
- Videos are archived and distributed with the benchmark to support reproducibility.
- No cropping strategy is described in the provided sections.
-
Task statistics:
- Text appears in 99.5% of tasks, images in 44.5%, video in 35.5%, and audio in 16.0%.
- 82.5% of tasks involve at least two evidence modalities.
- HTML appears in 98% of tasks, MP4 in 35%, and PDF in 31%.
- 96.0% of tasks involve at least two resource formats.
- Access requirements include direct observation in every task, link or page navigation in 67.0%, artifact transfer in 60.0%, temporal indexing in 47.5%, and parameterized state updates in 42.0%.
- Multiple access types occur in 95.5% of tasks.
-
Use in evaluation:
- The paper uses OpenDS-World to evaluate AI agents on autonomous multi step evidence search and cross-source reasoning.
- In human testing, 50 participants made 1,000 independent attempts, with 21.10% accuracy overall. At the task level, 115 of 200 tasks were solved by at least one solver, showing substantial difficulty.
- The provided sections do not describe a training split, data mixture ratios, or model training use; OpenDS-World is presented as an evaluation benchmark.
Method
The authors construct OpenDS-World through a multi-stage annotation and verification pipeline that produces questions supported by verifiable evidence paths over real web content. The method consists of two main phases: task construction and human verification.
Task Construction Pipeline
Task construction follows three stages: Real-World Anchor, Open-Web Evidence Expansion, and Question Inversion.
Stage 1: Real-World Anchor. Each evidence path begins with a publicly accessible video. Annotators inspect the visual frames and audio content of the video to identify an initial anchor entity whose identification must depend on the audiovisual signal rather than on page-level textual search. The anchor is mapped to a unique Wikidata entry, and the corresponding video is archived and distributed with the benchmark to preserve reproducibility. This anchor serves as the starting point for subsequent evidence expansion.
Stage 2: Open-Web Evidence Expansion. From the current anchor entity, annotators formulate a search query and retrieve candidate web sources through Google Search. They inspect the candidates and select sources that have a clear semantic relation to the current node and provide verifiable evidence. During selection, annotators also consider modality, format, and access-type attributes to increase evidence diversity. From the selected source, they extract a new entity and designate it as the next node in the evidence path.
A key requirement is that each node must be independently corroborated by multiple web sources, not only by the source from which it was first extracted. The expansion process is applied recursively until the evidence path reaches a unique and stable terminal node suitable as the reference answer. This design ensures that the resulting chain is dynamically constructed through iterative search, access, and verification over real web information sources.
Stage 3: Question Inversion. Once the terminal node is determined, the authors designate it as the reference answer and construct the textual question by inverting the complete evidence path into a set of interdependent constraints. The intermediate nodes are not revealed explicitly. Instead, each node is converted into an indirect referring description based on the evidence accumulated earlier in the path. The descriptions are composed so that no single clue directly exposes the target entity, while their combination progressively constrains the candidate space and uniquely determines the answer. Solving the question therefore requires recovering the latent correspondences among intermediate entities and following the underlying evidence chain, rather than retrieving the answer from a single explicit clue.
Human Verification and Filtering
After task construction, each candidate task undergoes independent verification by ten reviewers. The reviewers revisit the preserved evidence path, including the initial anchor, intermediate entities, inter-entity relations, and the final reference answer. Verification covers two aspects: evidence validity and task validity.
Evidence Validity. Reviewers check that the entities, relations, and final answer are factually accurate and supported by authentic, accessible, and independently verifiable web evidence. They cross-check the information against multiple additional sources beyond the original source. Each transition between adjacent nodes must be explicitly supported by evidence, ensuring factual and logical consistency throughout the path. For the initial anchor, reviewers also confirm that the entity can be uniquely identified from the video content, that it is correctly mapped to a Wikidata entry, and that the answer cannot be directly obtained from the textual content on the video page.
Task Validity. Reviewers evaluate whether each candidate task satisfies the construction principles. They verify that the question is clear, that the clues correspond to the evidence path, and that all constraints are supported by verifiable evidence without factual or logical conflicts. They also confirm that the constraints collectively determine a unique factual answer and do not allow multiple plausible solutions. Any candidate task with factual errors, insufficient evidence, inconsistent relations, ambiguous wording, non-unique answers, or violations of the construction principles is excluded.
Through this filtering procedure, the final benchmark is produced with clearly defined reference answers and verifiable evidence paths.
Experiment
The evaluation includes independent human solving of 200 questions split into 10 sets of 20, each attempted by five solvers with web access but no LLM tools, to establish task difficulty and baseline performance. It then assesses 12 frontier models under the same search, GUI, and video tools with a one-hour time limit and 100 tool-call budget, using answer accuracy judged by Qwen3.8-27B. The results show that even the best model reaches only 39.00% accuracy, performance declines as task difficulty increases, and higher token or time consumption does not reliably improve outcomes. Analyses of cost, tool use, errors, and budget exhaustion further identify inefficient search strategies, limited tool-use effectiveness, and frequent failure to complete tasks within constraints as central challenges.
Frontier models remain limited on real-world deep search tasks, with the strongest model achieving only 39.00% overall accuracy. Performance declines substantially as task difficulty increases, and model rankings shift across difficulty levels. Greater token or wall-clock consumption does not consistently correspond to higher accuracy. GPT-6 Astra leads overall at 39.00%, followed closely by Claude Opus 5.5 at 38.00% and Gemini 3.8 Flash at 36.50%. Averaged across evaluated models, accuracy falls from 39.66% on low-difficulty tasks to 23.50% on medium and 16.76% on high-difficulty tasks, while Gemini 3.8 Flash performs best on high difficulty at 28.24%.
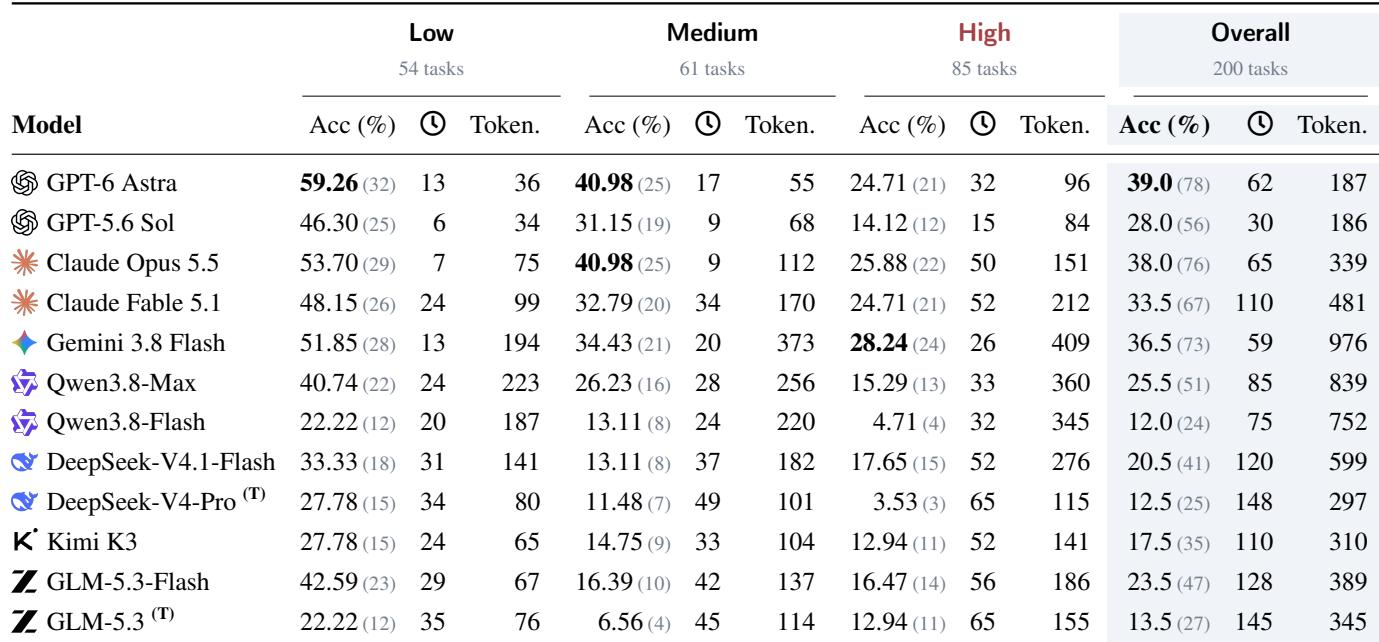
The evaluation benchmarks frontier models on real-world deep search tasks and finds that they remain limited, with GPT-6 Astra leading at only 39.00% overall accuracy, followed by Claude Opus 5.5 and Gemini 3.8 Flash. Average accuracy declines sharply from 39.66% on low-difficulty tasks to 23.50% on medium and 16.76% on high-difficulty tasks, while model rankings shift across difficulty levels. Greater token or wall-clock consumption does not consistently correspond to higher accuracy, and Gemini 3.8 Flash performs best on high-difficulty tasks at 28.24%.