Command Palette
Search for a command to run...
BizAgentBench:実世界ビジネスへの長期的タスク実行エージェント導入における隠れた課題の解明
BizAgentBench:実世界ビジネスへの長期的タスク実行エージェント導入における隠れた課題の解明
Enhan Zhao Yongqi Tong Xuejun Yu Hang Wang Pan Wang Yichao Wang Di He Jianshe Li Wei Wu
概要
既存の長期的タスク実行エージェント向けベンチマークは、最終的なタスク成功率を重視する一方で、中間実行の妥当性に対する評価は限定的である。しかし実世界の業務では、エージェントは膨大で、場合によっては古くなっていたり矛盾したりするポリシーを扱いながら、実行全体を通じて重要な制約を満たす必要がある。この要件は決済のようなハイリスク領域で特に重要であり、中間段階での違反は最終結果にかかわらず金銭的損失や規制上の結果を招く可能性がある。この評価ギャップを埋めるため、我々は大手決済企業の実業務手順に基づくマルチターンベンチマークBizAgentBenchを提案する。その実行可能環境には789件の知識文書と601個の発見可能な業務ツールが統合されており、ポリシー・状態・ツールの挙動が一貫している。ベンチマークは、リソース制約、時間的依存関係、事前コミットメント、矛盾または古くなったガイダンスを含む50のタスクで構成される。各タスクは参照実行によって検証され、決定的チェックが単一の解決経路を規定することなく、目標達成と実行妥当性の両方を評価する。実験により、最先端モデルでさえ大きな限界があることが明らかになった。Claude Opus 5とGPT-6 Solの厳格成功率はそれぞれわずか64.0%、61.3%である。Qwen3.8-27Bでは目標達成率が42.0%に達する一方、厳格成功率は32.7%に低下し、結果ベースの評価が不正な実行を覆い隠す可能性があることを示している。成功率に加えて、DeepSeek-V4.1-Flashは1実行あたり平均191.3回のツール呼び出しを行い、参照実行より約70%多く、かなりの実行オーバーヘッドが明らかになった。総じて、BizAgentBenchは複雑な業務環境においてタスク完了を超えて、信頼性が高く制約に準拠した実行へと長期的タスク実行エージェントを評価・改良するためのテストベッドを確立する。
One-sentence Summary
Researchers from Peking University and Ant International introduce BizAgentBench, a multi-turn benchmark grounded in real-world payment procedures that evaluates long-horizon agents for both goal attainment and execution validity using 789 knowledge documents, 601 tools, and 50 constraint-heavy tasks, revealing that frontier models such as Claude Opus 5 and GPT-6 Sol achieve strict success rates of only 64.0% and 61.3%, respectively.
Key Contributions
- BizAgentBench is a multi-turn benchmark grounded in real-world procedures from a leading payments company, with an executable environment integrating 789 knowledge documents, 601 discoverable business tools, and 50 tasks validated through reference execution.
- The benchmark contributes deterministic checks that assess both goal attainment and intermediate execution validity, including resource constraints, temporal dependencies, prior commitments, conflicting or outdated guidance, approvals, and funds, while allowing multiple valid solution paths.
- Experiments reveal frontier limitations: Claude Opus 5 and GPT-6 Sol achieve strict success rates of 64.0% and 61.3%, respectively; Qwen3.8-27B reaches 42.0% goal attainment but only 32.7% strict success; DeepSeek-V4.1-Flash averages 191.3 tool calls per run, roughly 70% more than reference executions.
Introduction
Advances in AI have shifted customer service from FAQ matching to task-oriented dialogue and, more recently, to LLM-based agents that can autonomously execute complex business workflows. Reliable deployment of such agents is difficult because they must maintain validity at critical intermediate steps, not only reach the correct final outcome, and they must identify authoritative business rules across scattered, versioned, and sometimes outdated sources. Prior long-horizon agent benchmarks tend to emphasize final task success, which can hide intermediate constraint violations and incorrect rule application. The authors introduce BizAgentBench, a benchmark of 50 long-horizon tasks grounded in real-world payment workflows, with stateful shared resources, deadlines, prior commitments, and distributed policy guidance requiring rule selection across scopes and effective periods. Its deterministic evaluator checks both outcomes and recorded execution histories against goals, process compliance, and protection requirements, so successful completion cannot mask earlier invalid actions.
Dataset
Dataset overview
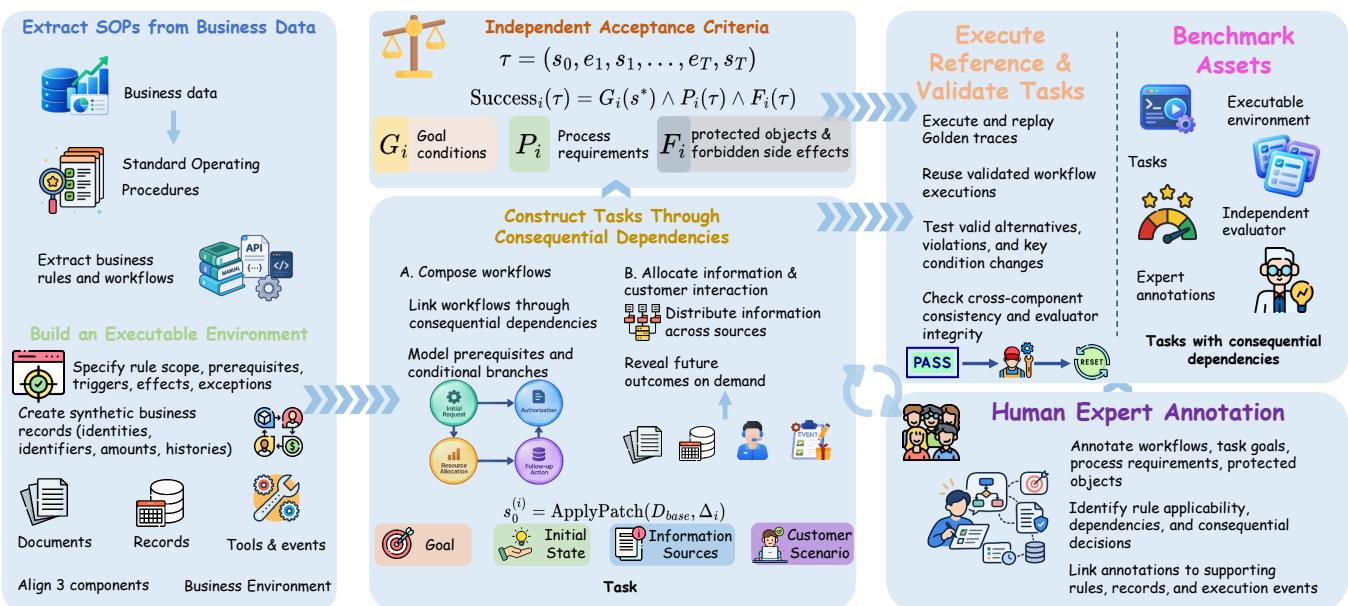
The authors present BizAgentBench as an executable benchmark for agents that handle customer requests in real-world business workflows. Each task includes an objective, an initial business state, a customer scenario, and acceptance criteria.
Composition and scale
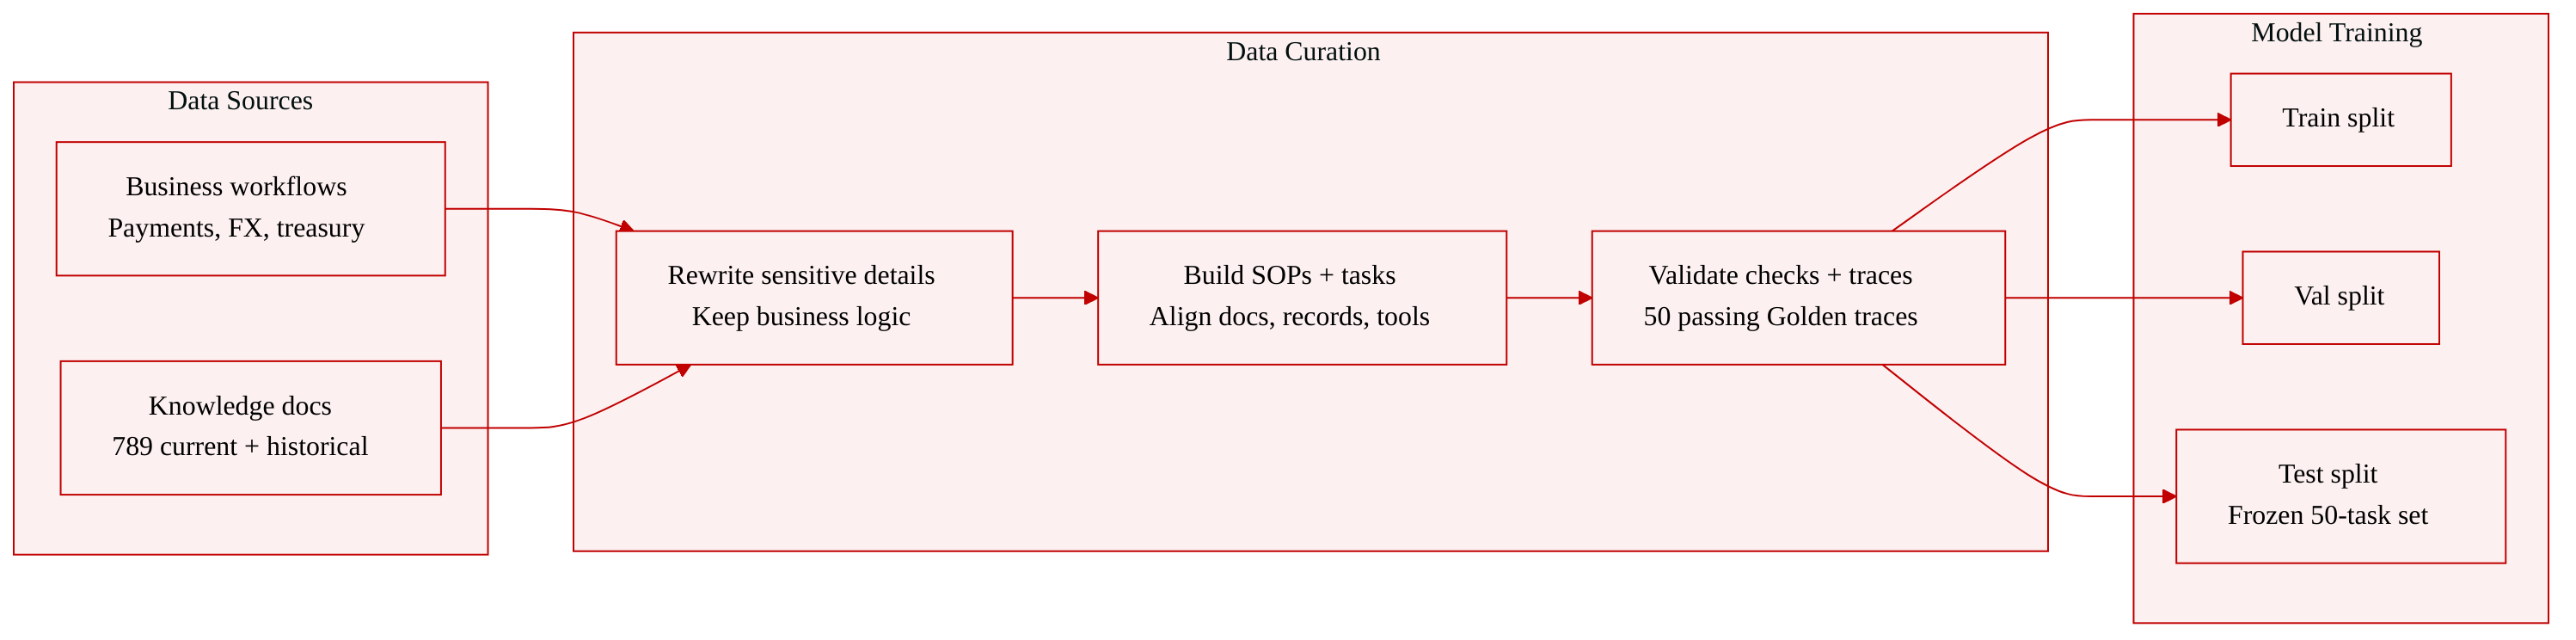
- The frozen release contains 50 tasks and 789 knowledge documents.
- Agents have nine always-available tools through which they discover and invoke 601 business capabilities.
- The user simulator has ten tools.
- Each run uses an independent copy of the database.
Sources and reconstruction
- Source workflows come from a leading payments and financial technology company, spanning cross-border payments, foreign exchange, and treasury services.
- Sensitive business details are abstracted or rewritten, while key business logic and execution mechanisms are reconstructed in an executable environment.
- Business documents are organized into structured SOPs that capture steps, decisions, transitions, rules, dependencies, prerequisites, actions, and exceptions.
- The environment includes current and historical guidance with explicit scopes, versions, and effective periods, making rule selection part of the task.
Processing and task design
- Synthetic records instantiate entities, accounts, obligations, authorizations, and transaction histories.
- For each operation, documented conditions, relevant records, and implemented effects are aligned.
- Tasks combine workflows that share resources, state prerequisites, or timing constraints, creating multi-workflow scenarios with delayed information and time-sensitive decisions.
- Acceptance criteria are defined before Golden traces and include goal checks, process checks, and protection checks.
- Intermediate checks verify approvals and continuous constraints at each relevant state change.
- Golden traces are constructed and replayed from each task’s initial state; all 50 released tasks have a passing Golden trace.
- Validation uses valid alternative executions, targeted violation traces, and modified facts, followed by expert review from researchers and business-domain experts.
How the data is used
- Agents are evaluated in multi-turn interaction with a user simulator to achieve a shared business goal.
- The agent must consult documents, query records, ask for private customer information, obtain approvals, and execute actions through tools.
- Evaluation covers both requested outcomes and intermediate execution validity, including authorization, execution timing, state changes, and protected objects.
Method
The authors structure the benchmark around a deterministic evaluation protocol and a multi-stage data construction pipeline. For an execution history
τ=(s0,e1,s1,…,eT,sT),where each et is a tool execution or environment event, task success is defined as
Successi(τ)=Gi(τ)∧Pi(τ)∧Fi(τ).Here, Gi checks requested outcomes and permitted terminal conditions, Pi checks requirements governing the execution process, and Fi checks protected objects and prohibited side effects. These checks operate over business states, ledgers, receipts, and event histories. They distinguish an executed action from a proposal, an approval, or a rejected call without side effects. The evaluation therefore does not match traces against a single golden path. Instead, the primary score is computed by deterministic executable checks over business states and execution histories, without using an LLM judge.
For data construction, the authors organize the process into five stages. First, source business documents are converted into structured standard operating procedures. Candidate workflows are extracted with supporting evidence, grouped into workflow plans, and translated into SOPs specifying steps, decisions, transitions, and return paths. Extracted rules record their scope, affected objects, prerequisites, actions, and exceptions. Content whose meaning or applicability cannot be established is excluded. Scope, version, and effective-period differences are preserved so that current and historical guidance can coexist. Sensitive details are rewritten consistently while preserving decision logic and dependencies.
Second, executable tasks are built from these SOPs. The environment includes aligned documents, synthetic records, tools, and scheduled events. Documents specify business rules and tool interfaces. Synthetic records instantiate entities, accounts, obligations, authorizations, and transaction histories. Tools and scheduled events implement the corresponding state changes. Tasks are created by selecting workflows that share business objects or resources, or whose outputs create prerequisites for other operations. Each task specifies a customer objective, an initial database state, and scheduled events. Workflows are connected through shared resources, state prerequisites, and timing requirements. Dependency graphs capture these relationships and conditional branches. Acceptance criteria are derived before golden traces are generated, and each criterion is linked to its governing rule or customer requirement.
Third, an LLM-based user simulator is configured for each task. A common interaction protocol defines the customer role, permitted customer-side actions, and turn-taking behavior. A task-specific scenario specifies the customer objective, private facts, preferences, supporting materials, and opening request. The simulator discloses information only when relevant questions or proposals arise, so the agent must elicit constraints and materials. Fixed facts remain consistent across turns. The simulator also performs customer-side operations in the shared environment, such as submitting documents or approving a proposed transaction. Approval is tied to a specific request and its current terms, and changed terms require renewed approval. Each requested write or wait is performed one at a time, and the simulator reports the actual result before returning control to the agent.
Fourth, golden traces are constructed by deriving reference strategies from the SOPs, task conditions, and workflow dependencies. These strategies are executed through the same tools and customer-side actions used in evaluation. Each trace is replayed from the initial state and evaluated using the goal, process, and protection checks defined for the task. Replay covers complete multi-workflow interactions, including shared-resource conflicts and timing constraints. This establishes that at least one executable strategy satisfies all requirements.
Fifth, validation and expert review test whether the evaluator accepts valid executions and detects violations. Valid alternatives using different permitted routes or action orders are checked, along with targeted violation traces. For example, a temporary reserve breach must fail the process check even if later transactions restore the balance. Facts that determine whether an operation is valid are modified to verify that the same checks produce the expected judgments under changed conditions. Operational variations that preserve compliance and business effects should leave evaluation outcomes unchanged. The final benchmark includes only tasks that pass both automated validation and expert review.
Experiment
The evaluation uses 50 BizAgentBench tasks with shared public documents, tools, databases, and acceptance criteria, comparing proprietary and open-source agents under a user simulator while separating goal attainment from process and protection validity. Results show that even the strongest models leave substantial room for valid end-to-end execution, with process compliance generally weaker than protection compliance and with repeated-run reliability declining. Ablations indicate that customer-specific constraint elicitation is harder than document retrieval alone, long-horizon traces often mix redundant or invalid actions with progress, and final goal success overstates valid execution because intermediate violations occur. Simulator prompt refinements reduce protocol violations, and agent performance remains relatively stable across simulator models.
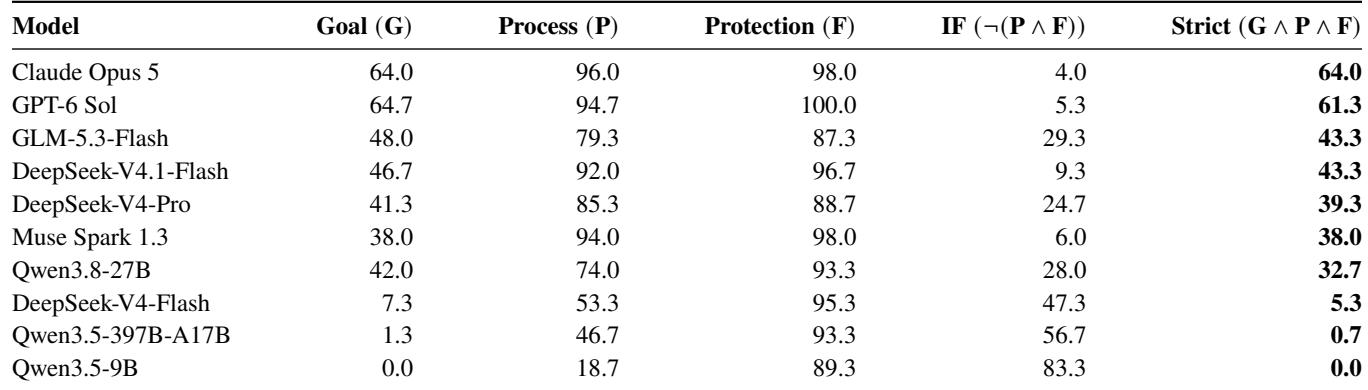
Frontier models achieve moderate strict success, with Claude Opus 5 and GPT-6 Sol leading and most other systems trailing by a wide margin. Process pass rates are consistently lower than protection pass rates, and intermediate failures occur for every model, especially lower-scoring ones. These patterns indicate that valid execution remains substantially harder than achieving the stated goal. Strict success is highest for Claude Opus 5 and GPT-6 Sol, while lower-scoring models trail and one model completes no runs. Intermediate failures are universal and generally increase as overall performance decreases. Process requirements are the main source of invalid execution, with process pass rates below protection pass rates for every model.
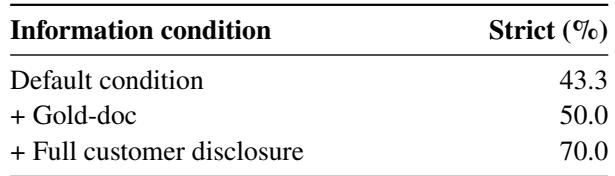
Strict success improves when agents receive applicable documents and improves further when all customer information is provided upfront in the opening request. The larger gain from full customer disclosure suggests that eliciting and retaining customer-specific constraints are especially difficult. A substantial share of tasks remains unsolved even with full disclosure, pointing to remaining planning and execution challenges. Strict success rises from 43.3% under the default condition to 50.0% with Gold-doc and to 70.0% with full customer disclosure. Full customer disclosure yields a larger improvement than providing applicable documents alone. Even with all customer-known facts available at the outset, 30.0% of tasks still fail strict success.
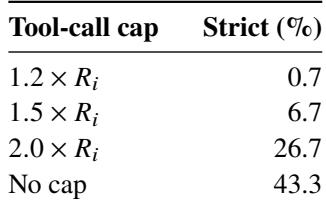
DeepSeek-V4.1-Flash uses considerably more assistant tool calls than the reference traces, with most excess activity concentrated in database queries and knowledge searches or document reads. Retrospective tool-call caps sharply reduce strict success, and even twice the reference call budget recovers only part of the uncapped performance. The results suggest that longer traces often reflect costly information search and repeated checking rather than proportional task progress. Most extra tool calls come from information access, especially database queries and knowledge searches or document reads, while business capability calls and request executions remain similar to the reference. Strict success drops from 43.3% with no cap to 0.7% at 1.2 times the reference call count, and rises only to 26.7% at 2.0 times the reference. Even twice the reference call count excludes many otherwise successful runs, indicating that additional calls do not reliably correspond to better task outcomes.
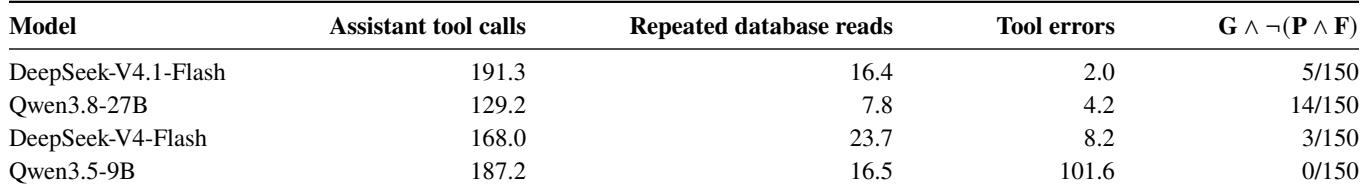
Tool-call volume alone is a weak measure of progress: some models issue many redundant reads or invalid queries, and several runs reach the goal while still violating process or protection requirements. Qwen3.5-9B is an outlier with frequent tool errors and no goal-reaching runs, whereas DeepSeek-V4.1-Flash has fewer intermediate violations than Qwen3.8-27B but reads many more documents than the golden traces. These patterns show final goal checks can overstate valid execution. DeepSeek-V4-Flash repeats identical database reads more often than DeepSeek-V4.1-Flash despite making fewer overall tool calls. Qwen3.5-9B encounters many more tool errors than the other models and reads far fewer distinct documents, indicating its long traces are not productive. A subset of runs reach the requested goal but fail process or protection requirements, with Qwen3.8-27B having the most such runs among the stronger models. Golden traces involve far fewer distinct document reads than DeepSeek-V4.1-Flash, whose additional retrieval often covers related but inapplicable documents.
The experiments evaluate AI agents on a tool-based benchmark using strict success, process compliance, and protection compliance. Frontier models show only moderate strict success, with Claude Opus 5 and GPT-6 Sol leading; process requirements consistently limit valid execution more than protection requirements, and giving agents all customer information upfront improves performance more than providing applicable documents alone. Tool-call analysis indicates that long traces often reflect redundant information retrieval and repeated checking rather than task progress, and that reaching the goal can overstate valid execution because some runs still violate process or protection requirements.