Command Palette
Search for a command to run...
GreenWAM: ロボティクスのための世界基盤モデル
GreenWAM: ロボティクスのための世界基盤モデル
Gennady Sidorov Valerii Kornilov Denis Grankin Polina Fedotova Aleksey Postnikov
概要
ロボットには,自身の行動がシーンをどのように変化させるかを予測する世界モデルと,その行動を選択する方策が必要である.モデルは通常,これらの役割のいずれか一方のみを対象として構築・評価され,また各ロボットは独自の形式で行動を記録する.我々は,異なる身体にまたがって一つのロボット世界モデルがこの両方の役割を担えるか,またそれを可能にする条件は何かを問う.本論文では,ロボティクスのための世界基盤モデル GreenWAM と,それを生み出す手順を提示する:(1) 双腕アームから器用なヒューマノイドまで20のロボットファミリーを共通の関節座標で記述する共有解剖学的行動空間;(2) これらのファミリーに対する視覚・行動条件付き・世界–行動の各モードでの統合学習;(3) 生成器の行動エキスパートを分離する方策.世界モデルとしては,GreenWAM は WorldArena 1.0 において軌道・深度・3D精度で最高水準を達成し,我々の比較におけるすべての世界–行動モデルおよび動画生成器を上回る.方策としては,RoboTwin 2.0 リーダーボードの上位エントリに位置し,比較手法の中で最も高い LIBERO-plus のゼロショット成功率を達成し,CALVIN および LIBERO では専用の視覚–言語–行動方策や世界–行動方策と競合する性能を示す.さらに GreenWAM を実機ヒューマノイドに適応させ,π0.5 および Cosmos 3 Edge から適応させた方策よりも高い成功率を達成し,実時間制御のために単一ステップ方策へ蒸留する.統制実験から以下の3つの知見が得られた:ロボット特化は世界予測と制御を同時に向上させる;行動エキスパートは適応の開始時に分離すると有効である;方策適応中に世界モデルモードを維持することでシーン変化に対する頑健性が保たれる.
One-sentence Summary
Brain Team and Sber Robotics Center present GreenWAM, a world foundation model for robotics built from a shared anatomical action space covering 20 robot families, joint visual, action-conditioned, and world-action training, and action-expert policies split from the generator; the model achieves top-tier trajectory, depth, and 3D accuracy on WorldArena 1.0, reaches the highest zero-shot LIBERO-plus success among compared methods, and outperforms policies adapted from π0.5 on a real humanoid.
Key Contributions
- GreenWAM, a world foundation model for robotics, adapts Cosmos 3 Edge to 20 robot families via a shared anatomical action space and joint training in visual, action-conditioned, and world-action modes, enabling one model to serve as both world model and policy.
- As a world model, GreenWAM attains top-tier trajectory, depth, and 3D accuracy on WorldArena 1.0 ahead of all compared world-action models and video generators; as a policy, it scores among the top RoboTwin 2.0 leaderboard entries, achieves the highest zero-shot LIBERO-plus success among compared methods, and is competitive on CALVIN and LIBERO.
- On a real humanoid, GreenWAM succeeds more often than policies adapted from π₀.₅ and Cosmos 3 Edge and distills into a single-step policy running at 28.3 Hz. Controlled experiments identify robot specialization, an action-expert split at the start of adaptation, and retained world-model modes as key design choices, with released weights and evaluation code for the RoboTwin 2.0, LIBERO, CALVIN, and WorldArena models.
Introduction
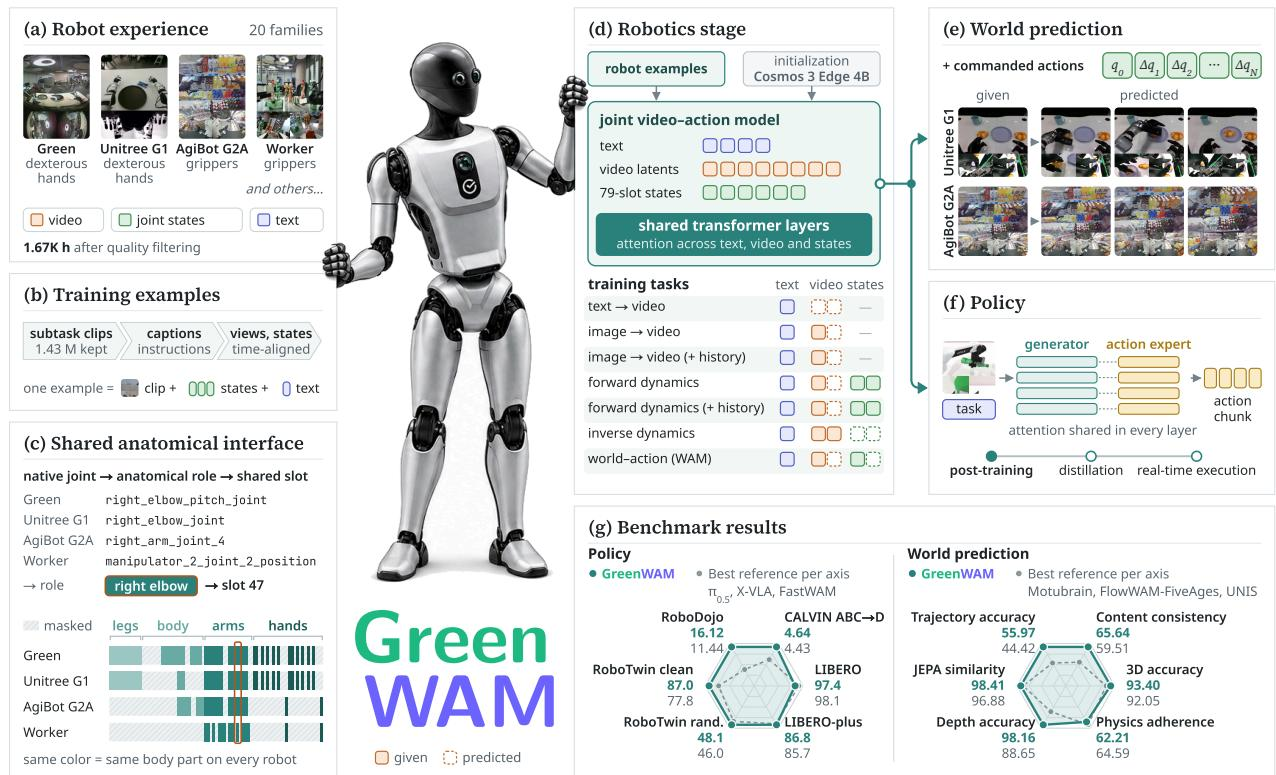
World foundation models learn how scenes evolve from large-scale video, and world-action models reuse this knowledge to jointly predict observations and actions. For robot control, this is especially demanding because the model must both predict how the scene changes when the robot moves and generate that motion itself, so the representation of the robot body is central. Prior work is limited because robot data are fragmented across embodiments, joint layouts, grippers, hands, cameras, frame rates, and task boundaries. Existing models typically describe each robot through per-embodiment action projections, end-effector poses, or padded joint vectors, leaving cross-body anatomical correspondences implicit or absent. The authors introduce GreenWAM, a world foundation model adapted from Cosmos 3 Edge through a shared anatomical action space: per-robot codecs map joints onto common slots for legs, torso, arms, and finger joints, and one model is trained jointly in visual, action-conditioned, and world-action modes. This produces a single model that serves as both a world model and a policy across different robot bodies through one action interface, including control of a held-out Franka arm and a real humanoid.
Dataset
Dataset description
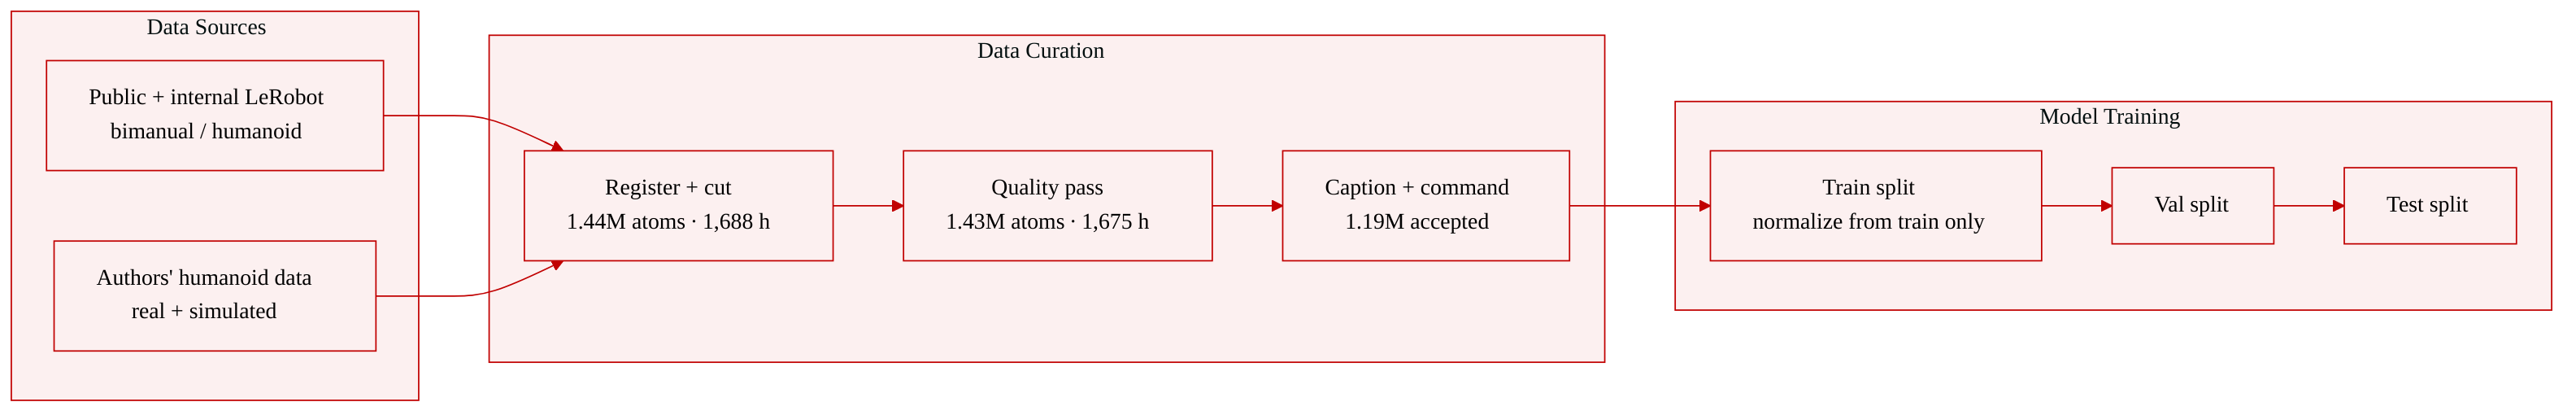
The authors describe the robot experience dataset as a cross-embodiment corpus built from multiple robot sources and prepared as subtask-level training atoms.
Dataset composition and sources
- The corpus spans 20 main robot families, all two-armed:
- bimanual platforms with parallel grippers
- humanoids with grippers or dexterous hands
- real and simulated scenes
- It combines:
- public robot datasets in LeRobot format
- internal robot datasets
- the authors’ humanoid data
- The basic training unit is an atom: a subtask clip from one episode with synchronized views, measured states, text, and provenance.
- Section A of the paper gives the layout descriptions, admission rules, and stage counts.
Corpus size and filtering
- Registration first fixes camera roles, state layout, and robot properties for each source.
- Cutting episodes into atoms yields an admitted corpus of:
- 1.44 million whole-subtask atoms
- 1,688.5 hours
- A quality pass keeps:
- 1.43 million atoms
- 1,674.7 hours
- Captioning and command derivation leave:
- 1.19 million atoms with an accepted command
- Filtering rules include:
- Semantic subtask boundaries are taken from source annotations.
- An episode is used whole only when it has no finer temporal annotation.
- Ambiguous or incomplete boundaries are excluded.
- Overlong atoms are rejected rather than cut into arbitrary windows.
- Idle intervals, duplicated frame runs, temporal cuts, and unreadable clips are removed.
- For text-dependent training modes, an atom also needs an accepted caption or command.
Text and instruction construction
- A video captioner, Qwen3.8-27B, writes structured fields for each atom:
- subjects, background, lighting, aesthetics, context
- attempt record
- timed action phases
- temporal caption
- consistency check
- The source task label supplies the intended goal.
- Registry facts fix the embodiment, effector type, and real or simulated domain.
- The captioner records how far the attempt got by reading the final frame, not only the label.
- Captions whose motion does not match the object and action type from the label are rejected.
- A second text-only stage converts the action phases into a prospective command:
- It preserves observed motions, object references, and phase order.
- It includes partial or failed attempts.
- It does not complete an intended task that the clip does not demonstrate.
- It does not see native dataset instructions.
- The derived text is used differently by training mode:
- visual modes use the visual description
- forward dynamics and WAM use the derived command
- inverse dynamics uses a fixed trajectory-recovery instruction
Video, state alignment, and targets
- Camera selection and ordering are explicit for each source.
- Synchronized RGB views are assembled into one canvas while keeping original episode timestamps.
- Frame-rate reduction selects corresponding video and state times without rescaling physical joint positions or displacements.
- Autoregressive examples join complete adjacent atoms and stop at rejected gaps.
- WAM requires a positive success label:
- failed, unknown, and unlabeled outcomes are excluded from WAM
- they may still enter other eligible modes
- State-derived targets are constructed from measured states using a common trajectory codec:
- q_k = codec_l(s(t0 + Δ_k))
- the codec maps each layout to shared anatomical slots
- Inverse dynamics predicts absolute q_k.
- Forward dynamics and WAM use delta targets from the realized robot motion.
- Normalization statistics are computed on the training split only.
Training mixture
- Sampling chooses a mode, a robot cluster, a dataset, and a window.
- The Worker/ARX5 and Green humanoid clusters receive fixed shares.
- Other clusters and datasets are weighted by the square root of their admissible subtask counts.
- Each source is sampled only in the modes its data support.
Method
The authors present GreenWAM, a world foundation model for robotics that unifies video prediction and action generation across diverse robot embodiments. Initialized from the Cosmos 3 Edge 4B checkpoint, the model employs a mixture-of-transformers backbone that couples a frozen reasoner with a trained generator, alongside a causal video VAE and rectified-flow training. While prior approaches often rely on end-effector pose deltas with embodiment-specific projections, GreenWAM retrains action modes on measured joint and Cartesian states from 20 robot families, mapping them into a shared anatomical action space.
As shown in the framework diagram:
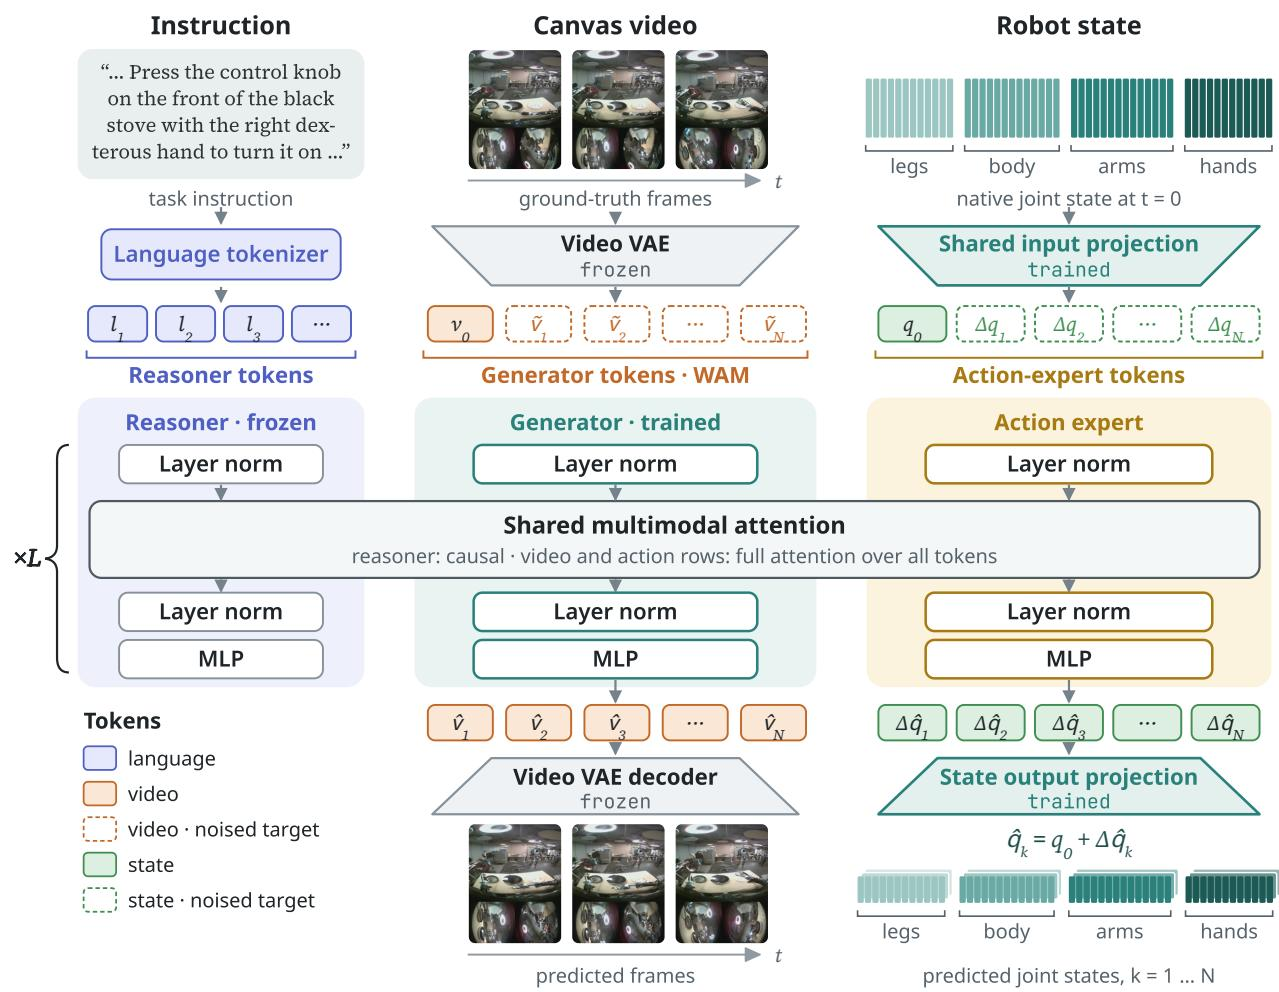
The architecture processes task instructions, multi-camera video canvases, and native joint states. The layout-specific codec maps native joints to shared anatomical slots before they pass through a shared input projection. In the standard GreenWAM configuration, state and action tokens pass through the main generator. For policy adaptation, an action expert is split from the generator to handle state and action tokens separately, while retaining joint attention with the video stream.
Refer to the comparison of action representations and data distribution:
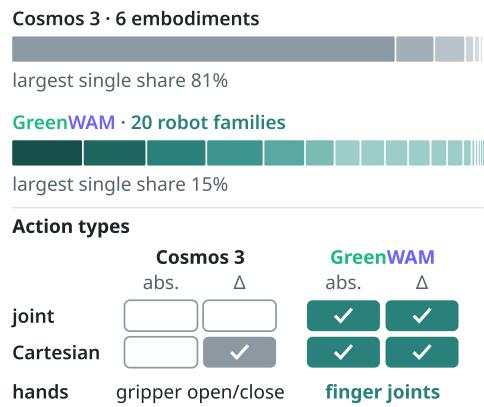
This comparison highlights how GreenWAM expands beyond the six embodiments and gripper open/close actions of its predecessor to support 20 robot families with joint and Cartesian representations, including finger joints for dexterous hands.
To accommodate the significant variation in state layouts, joint orders, and conventions across datasets, the authors establish a shared anatomical action space before projection. Layout-specific codecs map native channels to 79 anatomical coordinates, which are then processed by a single shared input and output projector. This ensures that a specific slot, such as the left elbow, corresponds to the same joint motion across all platforms. The vocabulary is divided into four blocks: legs, body, arms, and hands.
The shared anatomical action space is illustrated below:
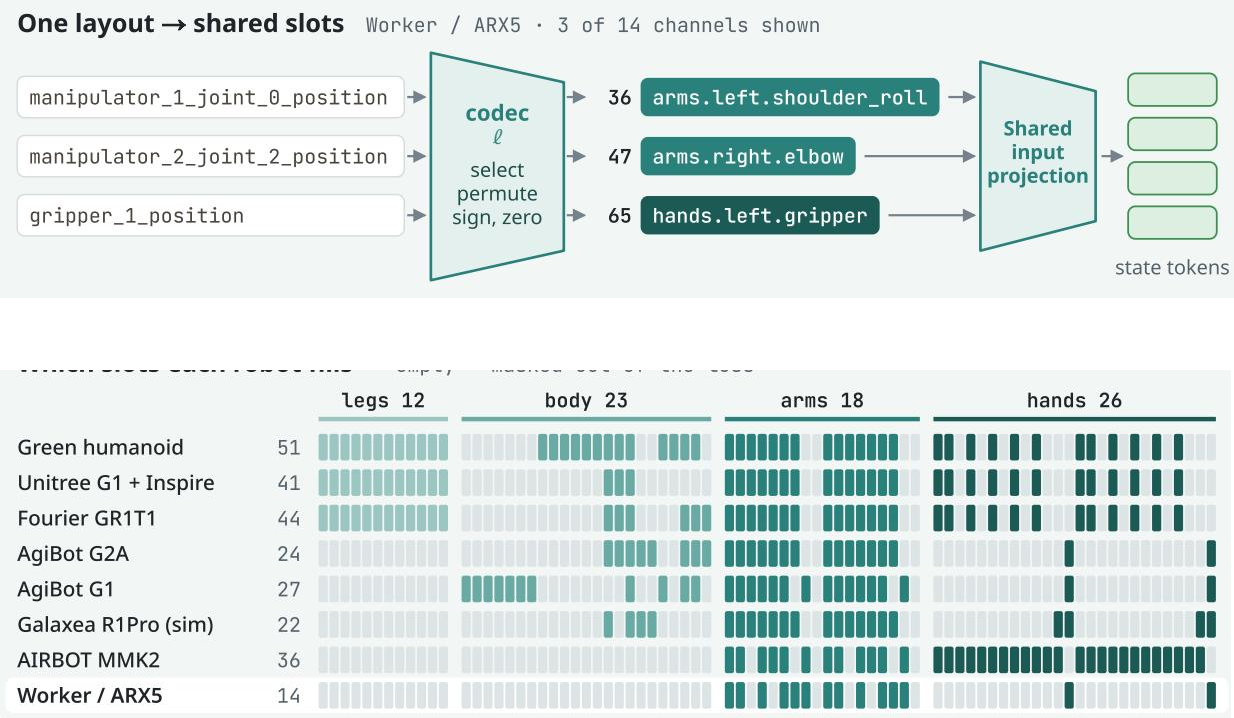
The codec selects, permutes, and adjusts the sign and zero offset of native channels to align with the shared slots. A shared input projection then maps the slot vector to state tokens. The bottom portion of the figure demonstrates how different robot layouts, such as the Green humanoid and Unitree G1, fill specific slots within the legs, body, arms, and hands blocks, while empty slots are masked during loss computation.
GreenWAM is trained jointly on seven modes, allowing a single set of generator weights to predict future video, robot trajectories, or both. A mode is defined by which streams serve as clean conditions and which are noised targets. For a mode m, let cm be the clean conditions and Sm the generated streams. All generated streams share a noise level σ, and a clean target x0 is noised along the rectified-flow path. The generator predicts the velocity v=ϵ−x0, minimizing the loss:
Lm=Eσ,ϵs∈Sm∑λs∥Ms∥1∥Ms⊙(v^θ(xσ,cm,σ)s−vs)∥2where Ms masks valid elements and λs weights the stream. The training mixture allocates three-quarters of examples to video prediction and one-quarter to state production through inverse dynamics and world-action modeling.
The data curation pipeline is depicted here:
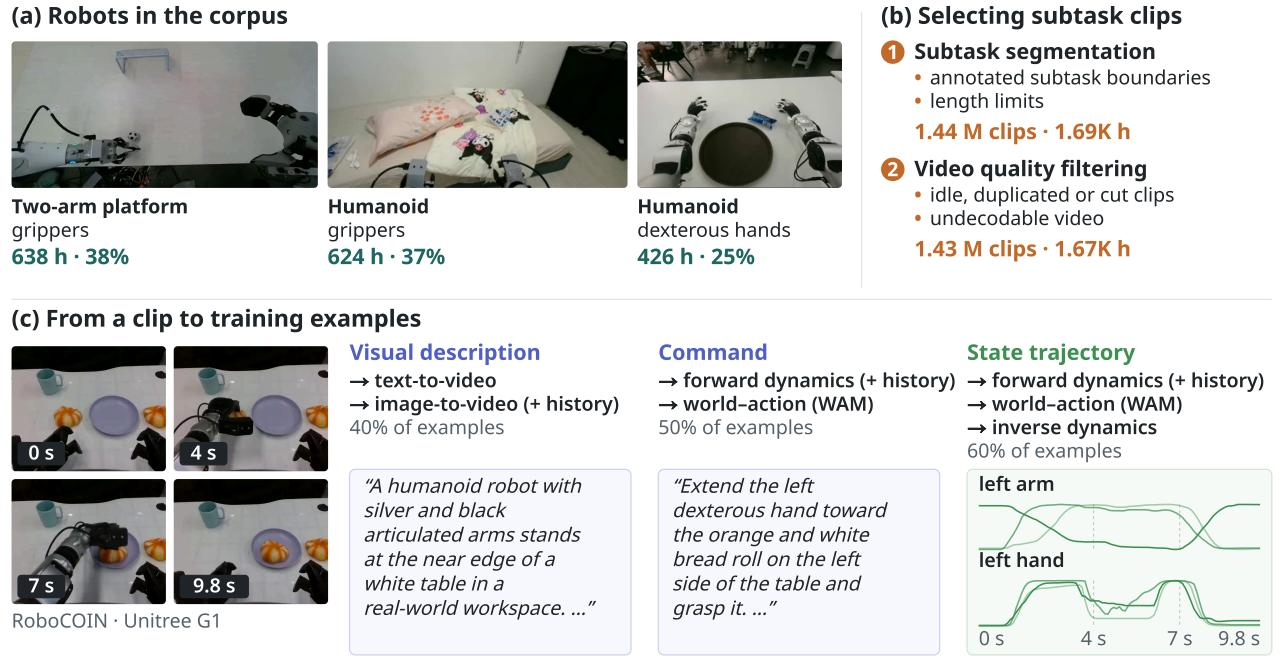
Public robot datasets are processed in stages. Episodes are cut into subtask clips at annotated boundaries, filtered for video quality to remove idle or undecodable segments, and then used to derive visual descriptions and commands. The state trajectory serves multiple action modes, acting as a condition for forward dynamics and a target for world-action prediction and inverse dynamics.
The captioning and command derivation process is shown in the figure:
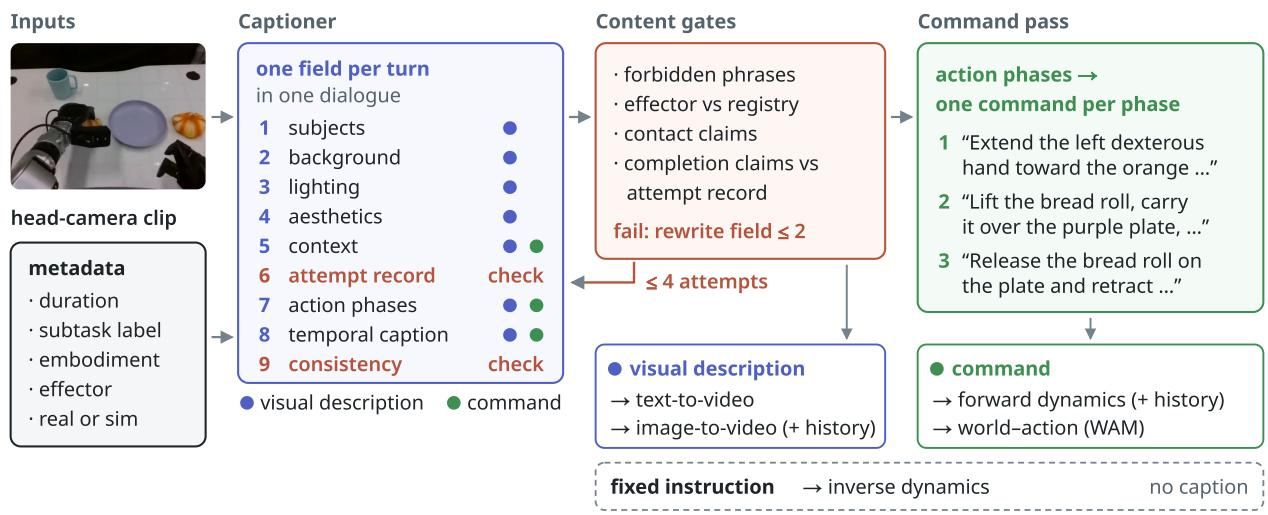
A captioner generates a structured record for each clip, including subjects, background, action phases, and a consistency check. Content gates verify forbidden phrases and completion claims against the attempt record. A subsequent command pass converts the action phases into prospective commands, preserving observed motions and phase order. These visual descriptions condition text-to-video modes, while the derived commands condition forward dynamics and world-action prediction.
For policy adaptation, the authors split the action tokens into a dedicated transformer while keeping video tokens in the generator. Joint attention connects the two streams at every layer, allowing action prediction to retain access to visual dynamics. The action expert is initialized by copying the generator tower, and the towers diverge during post-training. To enable real-time control, the adapted policy is distilled into a one-step student using modality-specific consistency objectives, significantly reducing inference latency while maintaining task success.
Experiment
The experiments evaluate GreenWAM in two roles. As a world model, it is tested on held-out robot recordings and on the WorldArena benchmark, where generated motion follows scaled action commands and it scores highest among compared world-action models on trajectory, depth, and 3D accuracy. As a policy, it is adapted to RoboTwin 2.0, CALVIN, RoboDojo, LIBERO, and a real humanoid packing task, achieving strong clean and randomized success, high zero-shot LIBERO-plus performance, and 95.6% in-distribution real-robot success. Controlled ablations show that robot-specialized initialization, a separate action expert, and retaining world-model prediction modes all improve policy success, with retained video prediction mainly improving robustness to randomized scenes because out-of-distribution success tracks the accuracy of the policy’s imagined video.
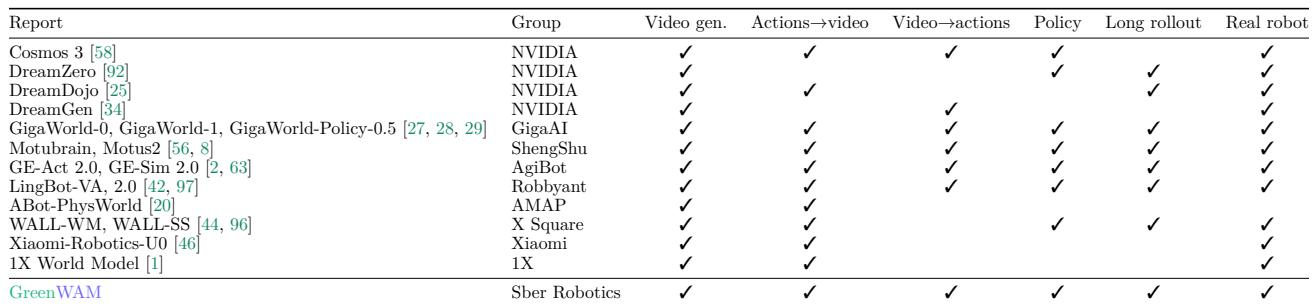
The comparison groups recent technical reports by whether they present video generation, forward and inverse dynamics, policy learning, long rollout, and real robot capabilities. GigaAI, ShengShu, and AgiBot entries are marked across all six listed capabilities, whereas NVIDIA entries cover video generation and dynamics but vary in policy, long rollout, and real robot support. The marks indicate capability coverage rather than quality. GigaWorld, Motubrain/Motus2, and GE-Act/GE-Sim are the only entries marked for every listed capability, including long rollout and real robot experiments. Cosmos 3 is marked for video generation, action-conditioned video, video-to-action, policy, and long rollout but not real robot; DreamZero and DreamDojo have fewer marks, and DreamGen has the fewest among the NVIDIA entries.
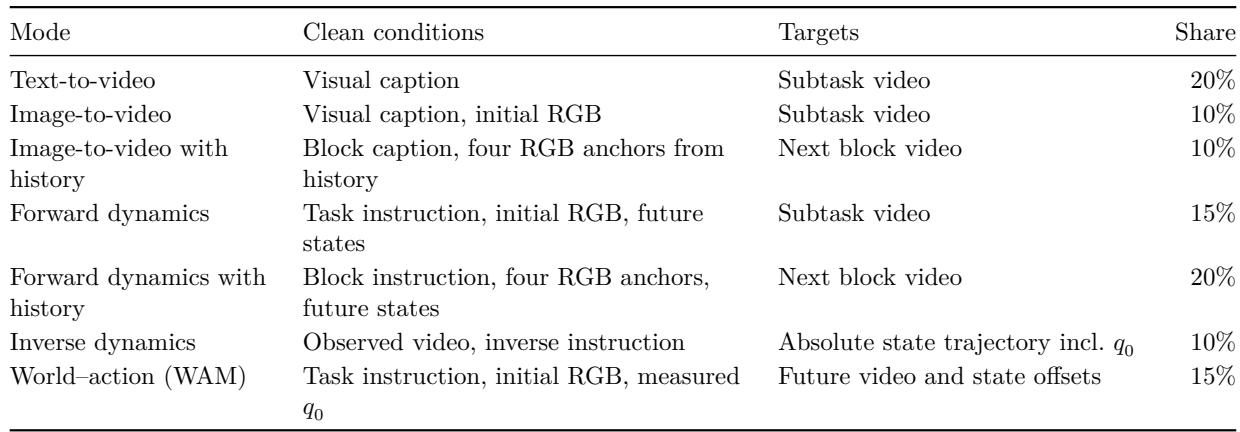
A single generator is trained across seven modes that mix video generation, forward dynamics, inverse dynamics, and world-action modeling. The largest sampling shares go to text-to-video and forward dynamics with history, while image-to-video and inverse dynamics modes are less frequent. The world-action mode conditions on the task instruction, initial RGB image, and measured initial state to predict future video and state offsets. Text-to-video and forward dynamics with history are the most heavily sampled modes, together accounting for 40% of example sampling probability. World-action and forward dynamics without history each account for 15%, while image-to-video, image-to-video with history, and inverse dynamics account for 10% each. History-conditioned video modes use four RGB anchors from prior frames as clean conditions. The world-action mode predicts future video and state offsets from the task instruction, initial RGB, and measured initial state.
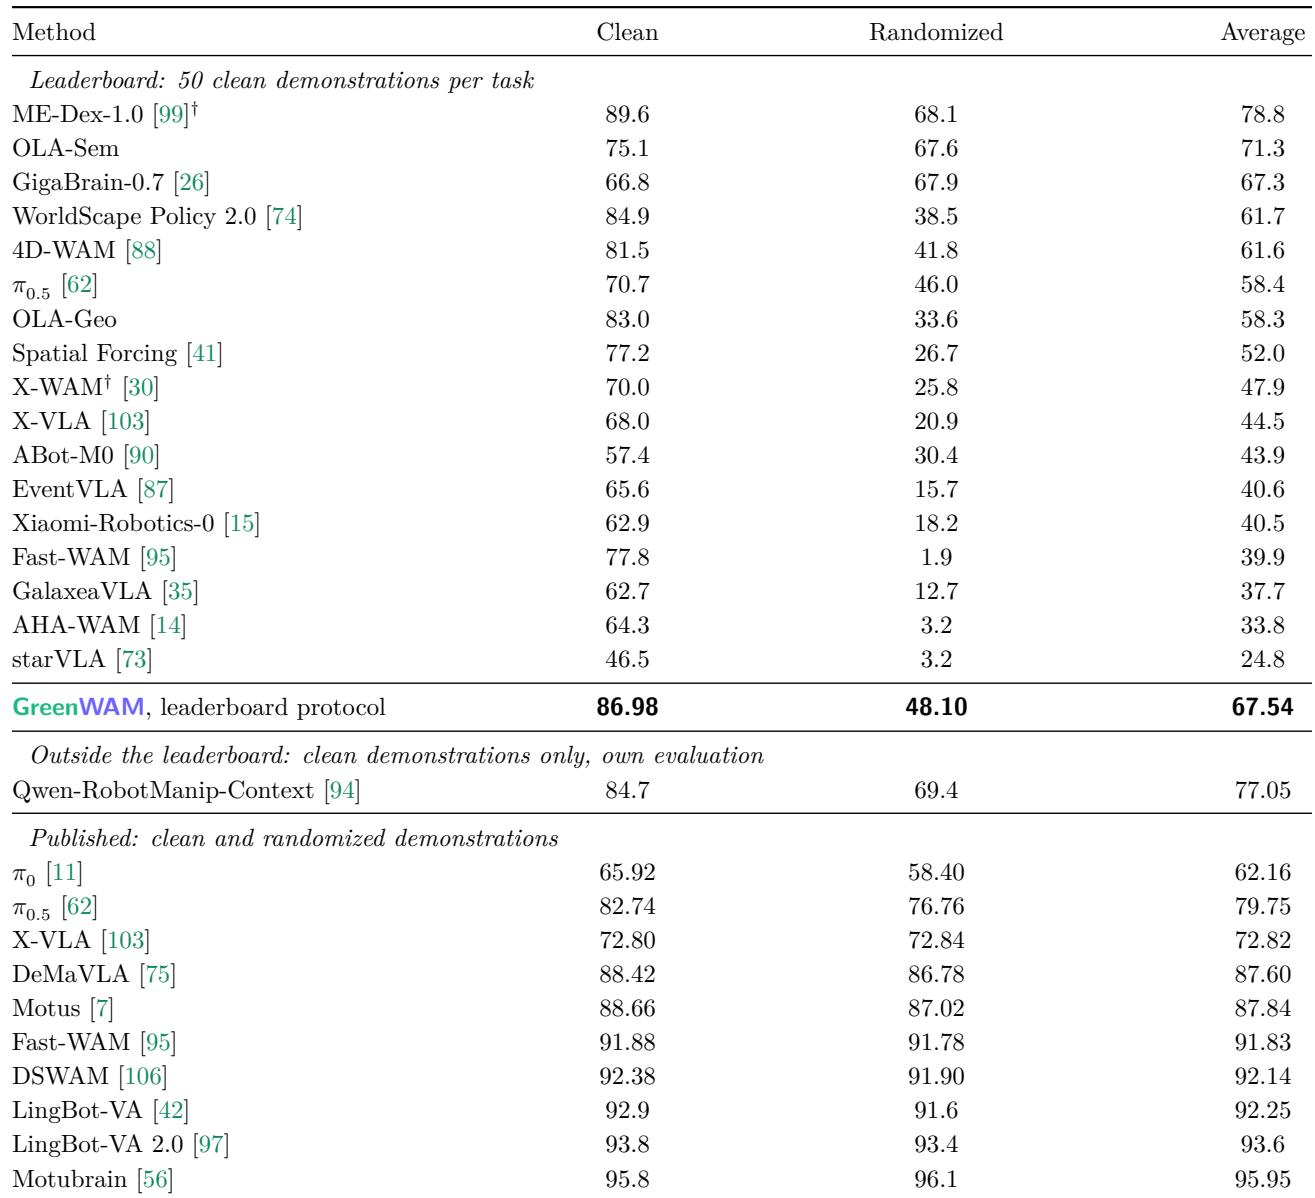
The benchmark shows that clean success is often high, but randomized success varies sharply across methods. ME-Dex-1.0 has the best average and randomized performance among the listed entries, while several models with high clean scores drop substantially under randomization. GreenWAM reaches competitive clean and average success but trails the most robust randomized performance. ME-Dex-1.0 leads the listed methods in both average and randomized success, showing less degradation under randomized scenes than high-clean alternatives. Models such as WorldScape Policy 2.0 and 4D-WAM score strongly on clean demonstrations but fall to much lower randomized success, while GreenWAM has strong clean and average results but only moderate randomized success.
A specialized start with 3,000 adaptation steps improves all three reported evaluation metrics relative to the comparison. Prediction quality sees roughly one-decibel gains on held-out RoboTwin forward frames and first-block WorldArena frames, while the WorldArena EWM score improves by a smaller positive margin. The pattern aligns with the broader finding that stronger forward prediction accompanies better policy success. Specialized adaptation from a world-model start yields positive gains across held-out forward prediction, first-block video prediction, and the WorldArena EWM score. The two frame-prediction metrics improve by roughly one decibel, while the EWM score increase is more modest but still positive.
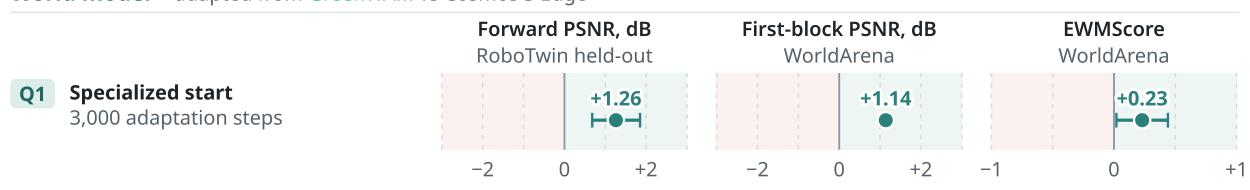
The experiments compare technical reports across video generation, forward and inverse dynamics, policy learning, long rollout, and real robot capabilities; they also examine a seven-mode generator training distribution, clean versus randomized policy success, and adaptation from a world-model start. Qualitatively, only GigaWorld, Motubrain/Motus2, and GE-Act/GE-Sim cover every listed capability, while ME-Dex-1.0 remains the most robust under randomized scenes and several high-clean methods degrade sharply. A 3,000-step specialized adaptation improves forward prediction and WorldArena EWM, supporting the broader conclusion that better forward prediction accompanies better policy success.