Command Palette
Search for a command to run...
Reflex
Reflex
Taoyang Jia Weikai Huang Linxin Song Jared Darlington Jieyu Zhao Yue Wang Jiafei Duan Zhongzheng Ren Ranjay Krishna
概要
人間は世界の出来事に無理なく反応する。テニスの返球を巧みに返し、落ちるカップを掴み、通り過ぎるカートを避け、トラックの荷降ろし中に投げられた箱を受け渡す。こうした日常動作には、動く対象を予測し、約1秒以内に全身で反射的に応答することが求められる。このような視覚に基づく反応的全身制御はヒューマノイドにとって依然困難であり、(1)全身制御の協調、(2)物体動力学への実時間反応、(3)自己中心視覚における知覚の接地、を満たす必要がある。我々は、これら3つの能力すべてを要求する代表的なタスクとして、投げられた箱をキャッチすることを研究する。既存システムはその一部を扱うに留まり、エンドエフェクタ、モーションキャプチャ、マーカー付き物体に依存している。我々は、物体動力学のコンパクトな表現を通じてこれらの能力を接続しながら、段階的に学習する3段階フレームワークであるReflexを提案する。第1に、状態ベースの方策が強化学習によって全身によるキャッチ動作を学習する。第2に、方策は遅延し不完全な観測から移動する箱の動力学を推定することを学習する。第3に、自己中心RGB-Dエンコーダが、全身コントローラを固定したまま、視覚観測からこの動力学表現を直接復元することを学習する。この分解により、各能力は直接的な学習信号を得ることができ、視覚学習のスケーラビリティが大幅に向上する。シミュレーションでは、Reflexは自己中心RGB-Dから85.7%のキャッチ成功率を達成し、特権的な箱の観測を与えた場合の87.9%と比較される。時間的な視覚履歴は重要であり、これを除去すると、中央への投擲と横方向にずれた投擲で成功率がそれぞれ35.6ポイント、39.8ポイント低下する。実機のUnitree G1では、Reflexは2.5 mおよび5 mにおいて、人が投げた箱をそれぞれ65%および40%の成功率でキャッチし、同じ距離における人間の捕球者の成功率の76%および59%に達する。
One-sentence Summary
Researchers from the University of Washington, Stanford University, University of Southern California, et al. propose Reflex, a three-stage framework for visual reactive whole-body catching that separately trains a reinforcement-learning controller, a dynamics inference module, and an egocentric RGB-D encoder while keeping the controller frozen, achieving 85.7% simulation success and 65% real Unitree G1 catch success at 2.5m.
Key Contributions
- Reflex is a three-stage framework for humanoid box catching that learns whole-body control, object-dynamics inference, and egocentric RGB-D perception while connecting them through a compact representation of object dynamics.
- The method trains a state-based reinforcement learning policy for 29-DoF whole-body catching, then learns to infer moving-box dynamics from delayed and incomplete observations, and finally trains an egocentric RGB-D encoder to recover this dynamics representation from visual history and camera ego-motion while keeping the whole-body controller fixed.
- In simulation, Reflex achieves 85.7% catch success from egocentric RGB-D versus 87.9% with privileged box observations, and removing temporal visual history reduces success by 35.6 and 39.8 points on centered and laterally offset throws. On a real Unitree G1, Reflex catches human-thrown boxes at 65% and 40% success for 2.5 m and 5 m, reaching 76% and 59% of human catcher success.
Introduction
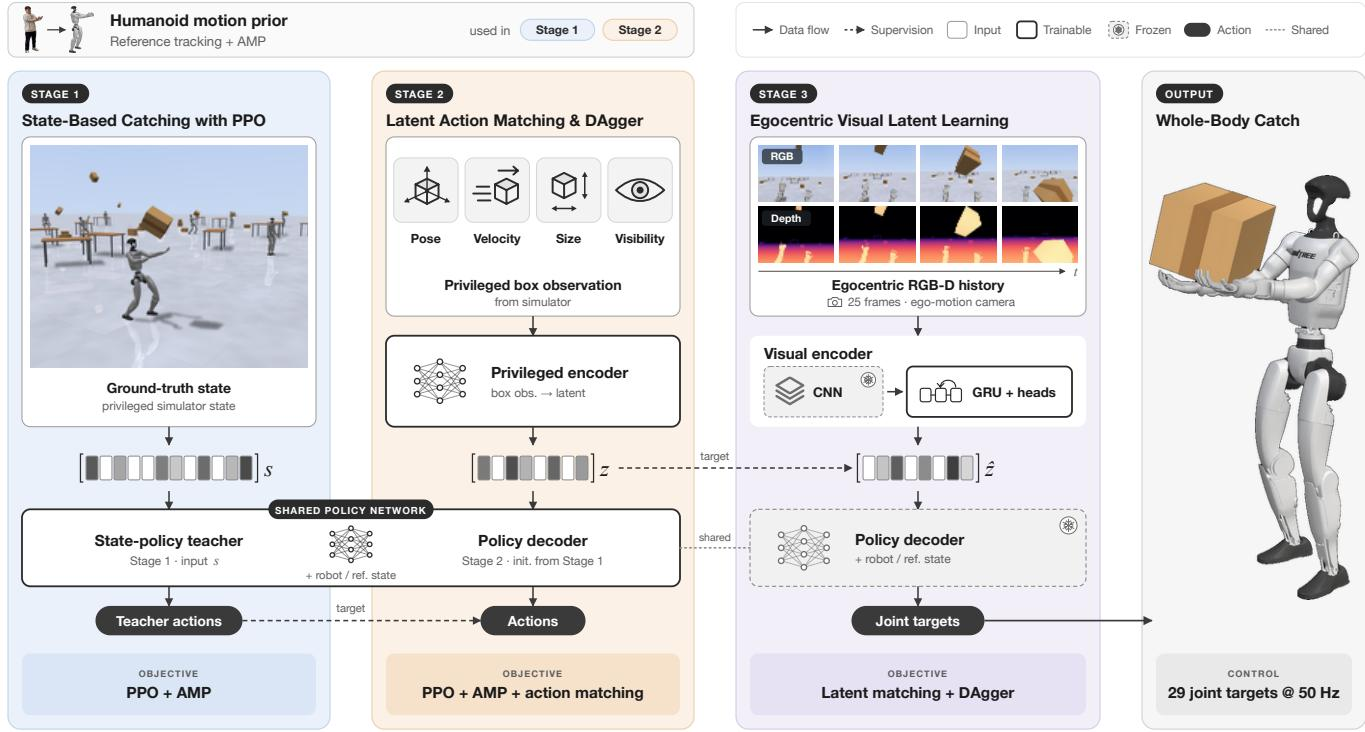
The authors study catching human-thrown boxes on a humanoid as a representative visually reactive whole-body control task. This capability matters because robots must predict where a fast-moving object will go, decide how to meet or avoid it, and coordinate the arms, torso, feet, and balance before contact, often within about a second, using only onboard sensing. Prior work addresses parts of this problem: manipulators catch from fixed or wheeled bases, while humanoid catching systems often rely on motion capture or retroreflective markers rather than onboard vision. As a result, whole-body control, fast object dynamics prediction, and egocentric visual grounding are rarely combined on a real humanoid. The authors introduce Reflex, a three-stage framework that learns whole-body catching from privileged simulation with reinforcement learning and human motion priors, learns a latent representation of moving-box dynamics from delayed and incomplete observations, and then trains a visual model to recover that latent from egocentric RGB-D history and camera egomotion while keeping the whole-body controller fixed.
Method
The authors decompose the deployed policy into a visual perception function Vψ and a whole-body control function πθ. Given a history of K egocentric RGB-D observations and camera ego-motion, Vψ predicts an eight-dimensional object-dynamics latent. The controller combines this latent with the robot and reference observation rt∈R160 to produce a normalized 29-DoF action:
zt=Vψ(It−K+1:t,et−K+1:t),at=πθ(rt,zt).The action is converted to nominal joint-position targets as qtnom=q0+s⊙at, where q0 is the nominal joint configuration and s contains per-joint action scales. To avoid the computational expense and optimization difficulties of joint end-to-end training, the authors organize learning into three distinct stages.
Stage 1 isolates the motor skill by learning whole-body control from box state using Proximal Policy Optimization (PPO). A state-based catching policy πstate is trained with a 170-dimensional observation combining the robot input with ten box-state channels. The actor is a multilayer perceptron producing the 29 outputs. The catching objective includes approach shaping, hold shaping, and a sustained-catch bonus, guided by tracking retargeted human reference motion and an adversarial motion prior (AMP). After training, the teacher policy is frozen to provide action supervision for the next stage.
Stage 2 learns the object dynamics by compressing delayed, partially observed box observations into a latent representation. A privileged encoder Eϕ maps a 26-channel box observation pt to an 8-dimensional latent zt=Eϕ(pt). The encoder processes the freshest visible sample in a delayed window. Initialization is performed via behavior cloning to match the teacher actions:
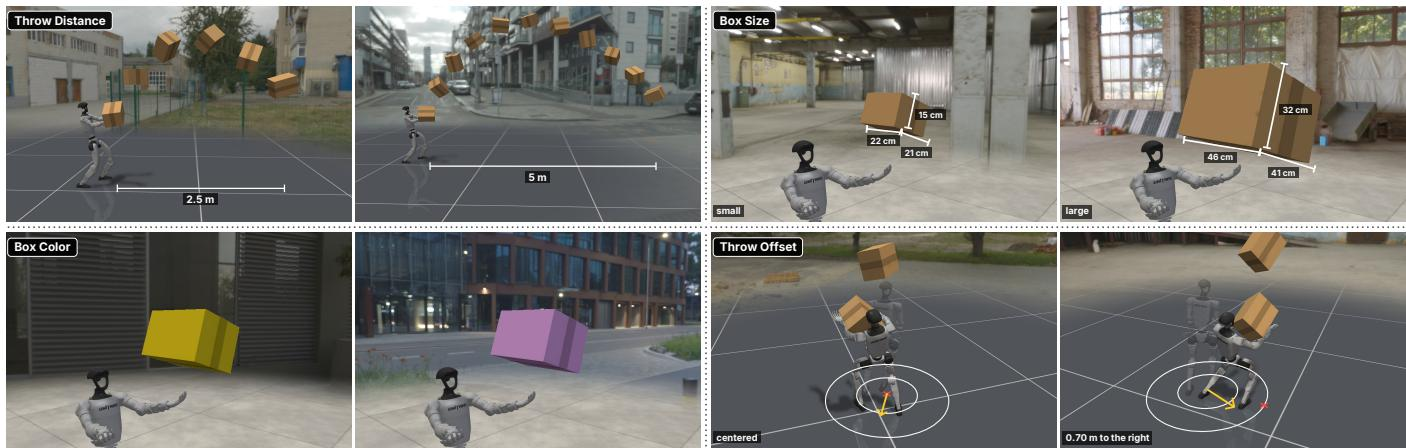
LBC=EDA[wtvisπθ(rt,Eϕ(pt))−atT22].Following action matching and DAgger-style data aggregation, PPO jointly optimizes the privileged encoder and the full decoder. The training incorporates randomized throw distances, box sizes, colors, and landing locations to ensure robustness across varying operating conditions.
Stage 3 grounds the dynamics latent in egocentric vision through supervised regression from RGB-D and ego-motion histories, while keeping the controller fixed. The visual encoder Vψ uses a history length of K=25. A convolutional neural network predicts a box-localization heatmap, from which a fixed geometric layer forms an 8-dimensional feature vector. A gated recurrent unit (GRU) processes these features along with ego-motion vectors to infer object motion. Training occurs in two steps. First, the CNN and heatmap head are trained using Gaussian targets. Second, the GRU is trained to predict the dynamics latent and auxiliary box position and velocity. The temporal-training objective is:
LV=EDV[ωt(ℓz(t)+λauxℓstate(t))]where ℓz(t) measures the normalized latent error and ℓstate(t) measures the auxiliary state error. A second DAgger-style procedure aggregates data from visual controller rollouts to refine the GRU.
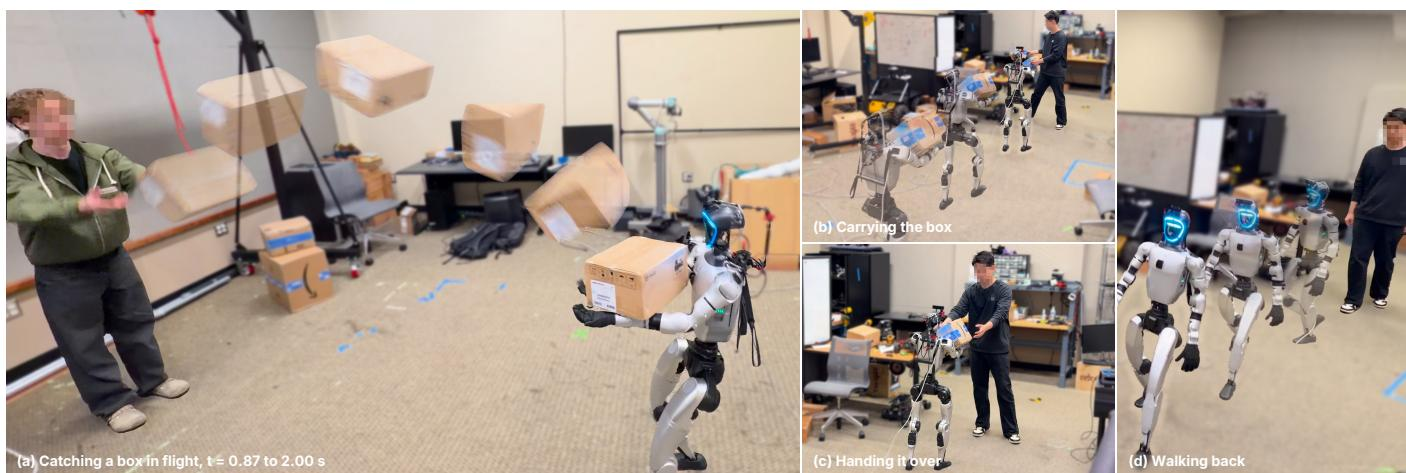
The downstream carrying and handover module connects the catching policy to a pretrained motion controller. A supervisor transfers command authority once a settled hold is established, switching gains and observations to the walking controller. The reference holds the current posture before transitioning to a standing cradle for walking and handover, with visual human detection identifying the recipient.
Experiment
The experiments evaluate Reflex in simulation and on a real Unitree G1 humanoid using separate success criteria for interception, catch retention, and post-catch stability, with comparisons to privileged state inputs, ablations, and human catchers. Whole-body ablations show that task rewards and motion priors are essential, object-dynamics experiments show that behavior cloning initialization and latency randomization improve latent prediction and robustness, and visual-grounding experiments show that temporal history and ego-motion cues matter while color augmentation reduces appearance sensitivity. Overall, visual control preserves most privileged catch performance in simulation and the robot tracks human success at shorter ranges, though long-range visual grounding and out-of-distribution box sizes remain the main limitations.
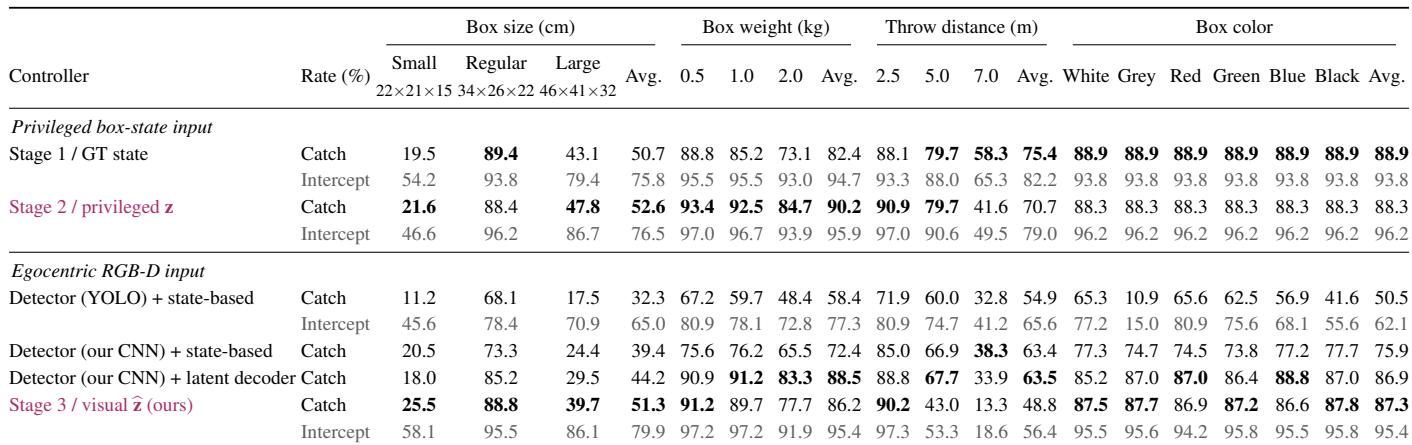
Under privileged box-state input, success is highest for the regular box size and lighter weights, while small boxes, heavier boxes, and longer throws reduce catch and interception. Interception rates are consistently higher than catch rates, and box color does not affect the privileged policies. Visual latent control exceeds detection plus filtering with the same detector within its visual training range. The regular training box size is the strongest condition, while the small box is hardest and the large box is intermediate. Heavier boxes and longer throw distances reduce success, with the longest distance producing the largest decline. Interception is consistently more frequent than catching under the same privileged state input. Box color does not change privileged policy performance, with identical rates across all tested colors. With the same detector, visual latent control outperforms detection plus filtering within its visual training range.
The real-robot catcher performs best with the regular box, a moderate box weight, and a 2.5 m throw distance. Success drops for small or large boxes, the heaviest box, and longer throws. Human reference catch rates are consistently higher, and the robot reaches about three-quarters of human success at 2.5 m and just over half at 5 m. Box size influences the robot strongly, with the regular box yielding the highest catch rate and small boxes causing the largest drop; human success varies less across sizes. For box weight, robot success peaks at 1 kg and declines at 2 kg, while human catch rates remain relatively flat. Throw distance creates a steep decline for the robot from 2.5 m to 7 m, with human performance also dropping but remaining higher. At 2.5 m and 5 m, the robot reaches 76% and 59% of human success, respectively.
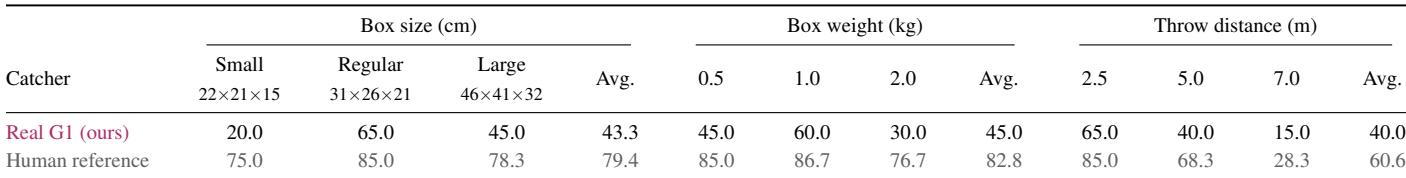
The privileged box-state experiments validate that regular box size and lighter weights give the highest success, while small boxes, heavy boxes, and longer throws reduce catching and interception; interception rates are consistently higher than catches, and box color has no effect. Visual latent control also outperforms detection plus filtering with the same detector within its visual training range. Real-robot tests confirm these trends, with best performance for a regular box, moderate weight, and 2.5 m throws, while small or large boxes, the heaviest weight, and longer distances degrade success. Compared with human reference catches, the robot reaches about three-quarters of human success at 2.5 m and just over half at 5 m.