Command Palette
Search for a command to run...
最適化器を最適化する:言語モデルがより高速な分子構造緩和を発見する
最適化器を最適化する:言語モデルがより高速な分子構造緩和を発見する
Artem Tsypin Vladimir Deshchenya Kuzma Khrabrov Denis Potapov Maxim Radchenko Artur Kadurin Michael G. Medvedev
概要
構造最適化は多くの量子化学ワークフローにおいて主要な計算コストである。各最適化ステップには1回の力評価が必要であり、密度汎関数法レベルではその評価が実時間(wall time)の大半を占める。この分野の研究は多種多様な最適化手法を生み出してきた。我々は、言語モデルが自動研究(autoresearch)を通じてそれらの中で最良のものを改善できるかを問う。エージェントは、力評価の呼び出し回数を最小化するために最適化器そのものを書き換える。この書き換えは、時期尚早な停止と、未見の分子に汎化しない改良を拒否する2つの受理ゲートによって制約される。入手可能な最速のオープンソース最適化器であるSellaを出発点として、探索は2つの最適化器からなるファミリーであるAutoSellaを生み出す。得られた2つの最適化器はいずれも、探索に使用されなかったホールドアウト分子ベンチマークおよびポテンシャルにわたって、Sellaと比較して一貫した力評価回数の削減をもたらす。特筆すべきことに、r2SCAN-3c DFTレベルでは、最良のバリアントは同じエネルギー低下を達成しながら、Sellaの力評価回数のわずか40.2–77.2%しか必要とせず、しかもエージェントはDFT勾配を一切使用していない。
One-sentence Summary
Researchers from AXXX, ITMO University, and N. D. Zelinsky Institute of Organic Chemistry propose AutoSella, a language-model-discovered family of two molecular geometry optimizers that rewrites Sella to minimize force calls under admission gates rejecting premature stopping and non-generalizing improvements; at the r2SCAN-3c DFT level, it requires only 40.2–77.2% of Sella’s force calls while achieving the same energy reduction.
Key Contributions
- An autoresearch loop for molecular geometry optimization allows an agent to rewrite the optimizer to reduce force-call counts, with admission gates that reject premature stopping and improvements that do not generalize to unseen molecules.
- Starting from Sella, the search produces AutoSella-F and AutoSella-A; AutoSella-F achieves consistent force-call reductions across held-out molecular benchmarks and unseen potentials, using 40.2% to 77.2% of Sella's force calls at the r2SCAN-3c DFT level while achieving the same energy reduction without DFT gradients during the search.
- Ablations attribute AutoSella-F's savings to improved curvature models and coordinates, explicit handling of disconnected fragments, and Hessian updates that reuse prior gradient information while accounting for geometry changes; the code is publicly available at https://github.com/vdeshchenya/autosella.
Introduction
Molecular geometry optimization is a core computational chemistry task whose cost at DFT level is dominated by interatomic force evaluations, so reducing optimizer steps directly reduces wall time. Prior work has relied on decades of manual design for quasi-Newton updates, coordinate systems, and Hessian models, but further improvements are difficult because candidate optimizers can overfit to training molecules or stop too early. The authors apply an autonomous research loop that uses LLM-generated code edits to evolve Sella, the fastest optimizer in their benchmark, with cheap GFN2-xTB evaluations plus generalization and validity gates. This produces AutoSella-F and AutoSella-A from two independent LLM-driven runs; AutoSella-F transfers to unseen molecules and r2SCAN-3c DFT, requiring about 23 to 60 percent fewer force calls than Sella while reaching equal or better energy recovery.
Dataset
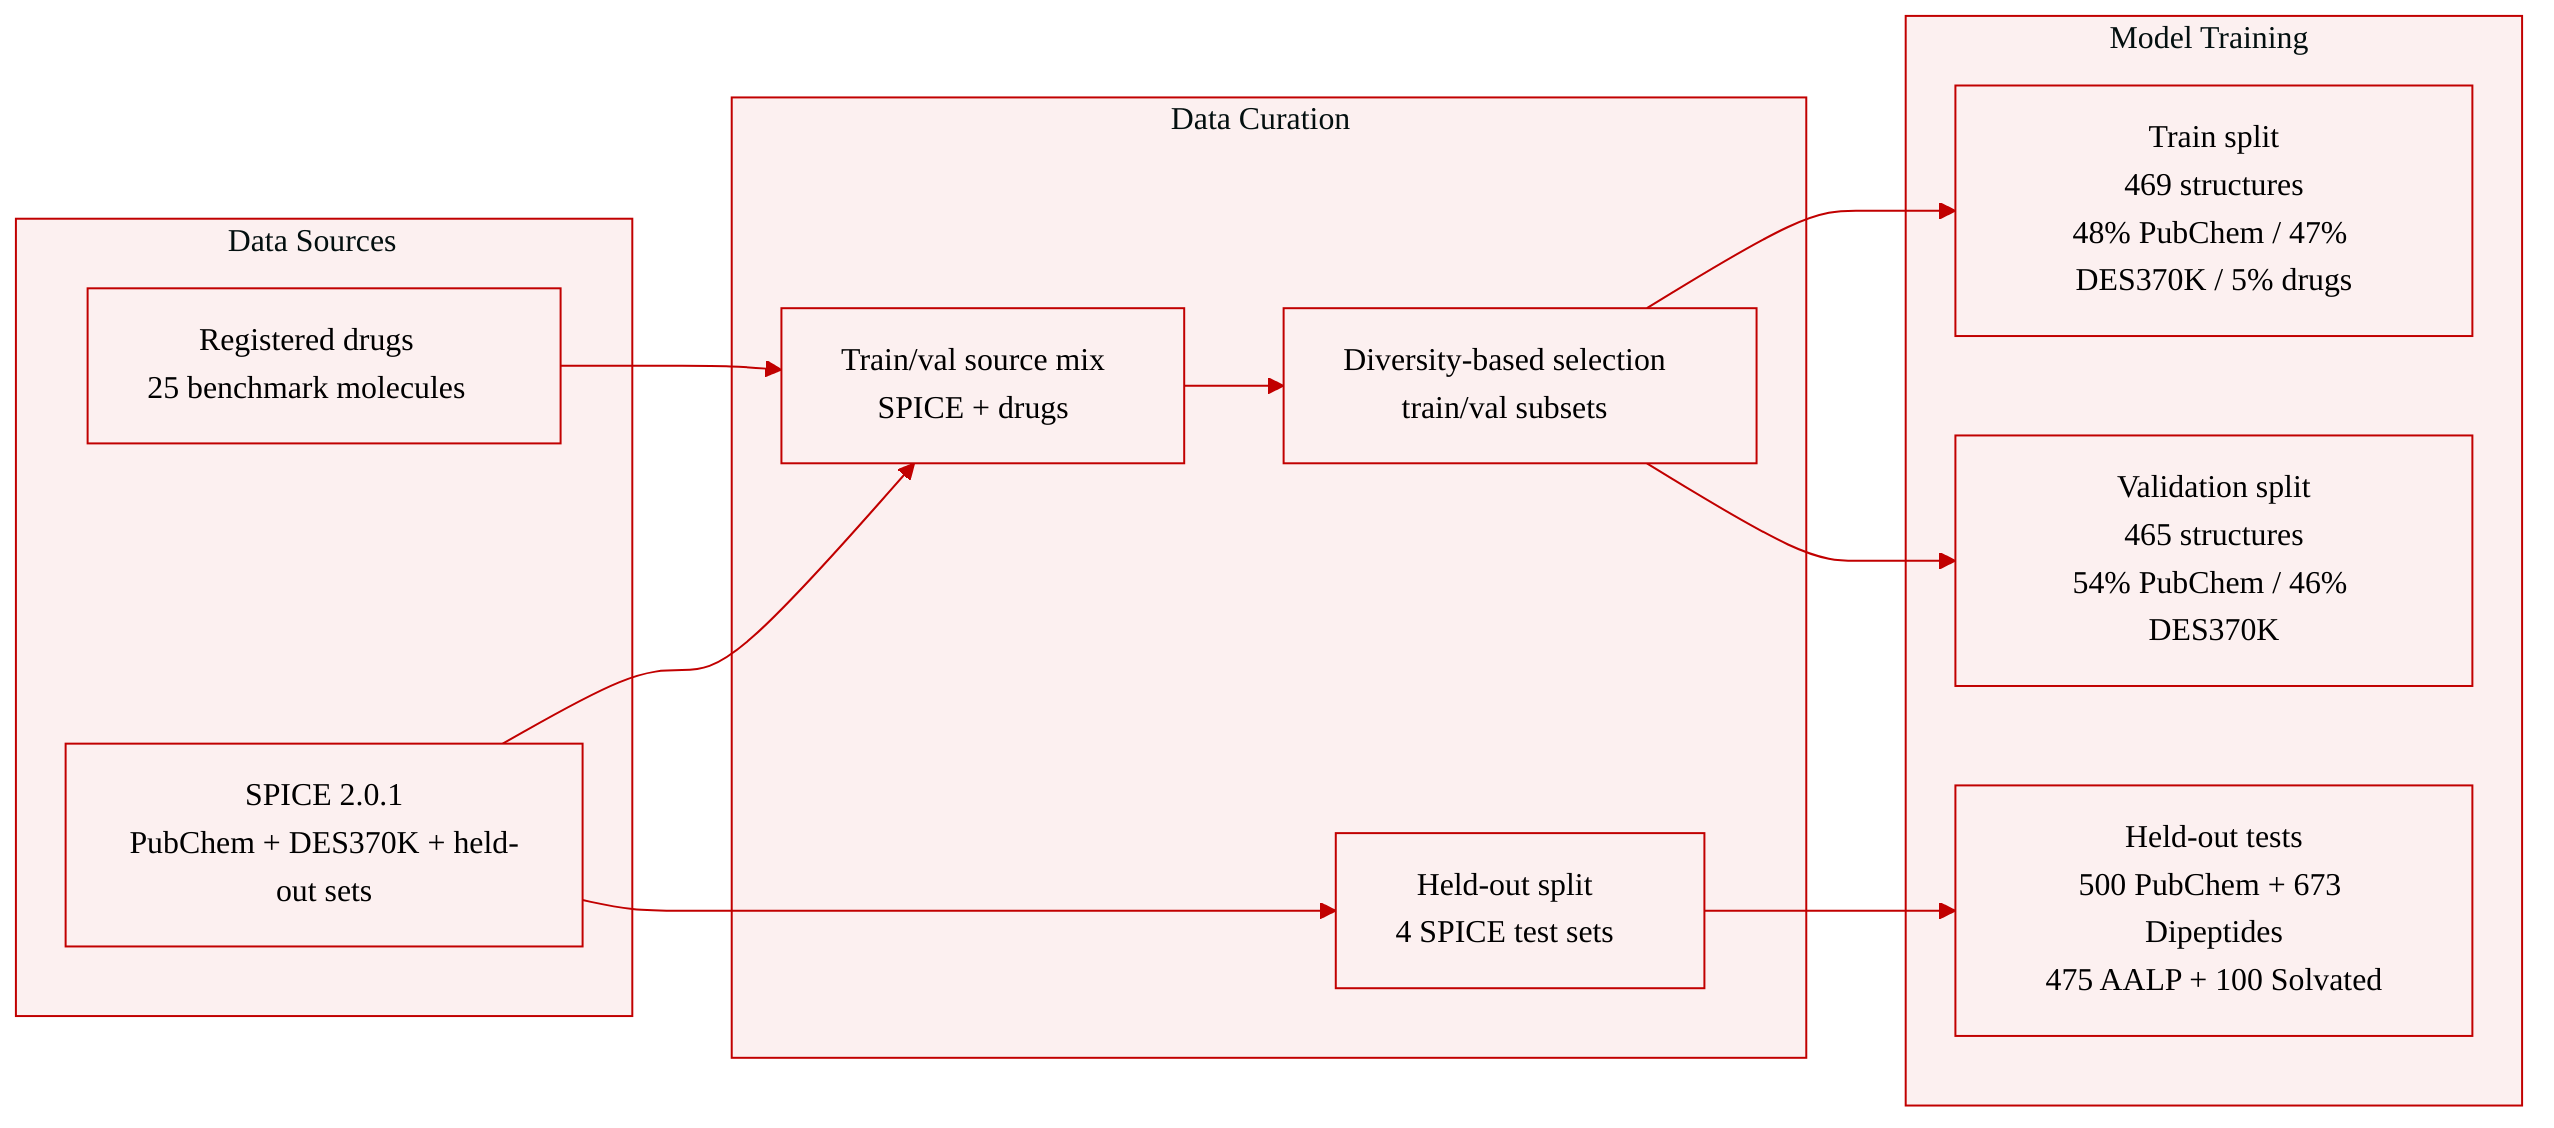
The paper focuses on geometry optimization for drug design. The authors use SPICE 2.0.1 as the main source of structures for training, validation, and evaluation.
Dataset composition and sources:
- Training set: 225 drug-like PubChem molecules, 219 DES370K dimers, and 25 registered drugs from a published optimizer benchmark, for 469 total structures.
- Validation set: 250 drug-like PubChem molecules and 215 DES370K dimers, for 465 total structures.
- Evaluation uses four held-out sets:
- 500 out-of-distribution PubChem molecules
- 673 Dipeptides structures
- 475 Amino Acid Ligand Pairs systems
- 100 Solvated PubChem systems
Key subset details:
- PubChem subset: drug-like molecules used for training, validation, and the out-of-distribution single-molecule test set.
- DES370K subset: dimers selected to improve optimization cost on noncovalent interactions; used for training and validation.
- Registered drugs: 25 structures from a published optimizer benchmark added to training.
- Dipeptides: single-molecule systems that test transfer to another chemical domain.
- Amino Acid Ligand Pairs: systems for noncovalent contacts, extending beyond the small DES370K dimers used during training.
- Solvated PubChem: complex multi-fragment systems where a drug-like solute relaxes with surrounding water molecules.
Processing and usage:
- The authors use diversity-based selection to choose the PubChem molecules and DES370K dimers for training and validation.
- By count, the training mixture is approximately 48% PubChem, 47% DES370K, and 5% registered drugs.
- By count, the validation mixture is approximately 54% PubChem and 46% DES370K.
- The provided section does not describe cropping or metadata construction details; it defers the detailed data preparation pipeline to Appendix A.
Method
The authors apply an autoresearch paradigm to automate the design of molecular geometry optimizers. The core objective is to minimize the number of interatomic force evaluations required to reach fixed convergence criteria, evaluated at the GFN2-xTB level. The convergence is determined by a five-criterion Gaussian-style test involving energy change, gradient norms, and displacement thresholds. The optimization cost is quantified using the per-molecule relative force-call ratio (Cper-mol), while the relaxation depth is measured by the mean relative energy recovery ratio (rˉ).
To initiate the evolutionary program search, the authors select Sella 2.5.0 as the baseline, having verified it requires the fewest force calls among 27 modern optimizer configurations. The codebase is consolidated into a single editable file to facilitate automated modifications. The autoresearch loop operates by having an agent repeatedly propose and apply edits to this file, followed by an automated evaluation on a fixed benchmark.
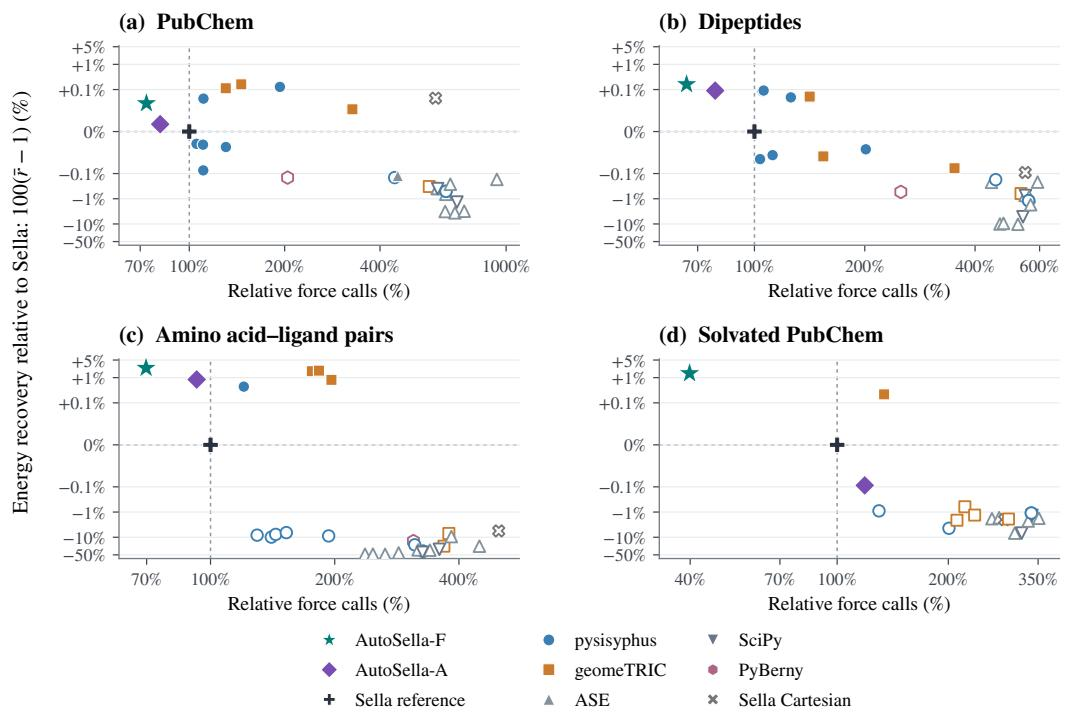
The authors leverage a comprehensive benchmark to evaluate the baseline and the evolved optimizers across diverse chemical domains, including drug-like molecules, dimers, and solvated systems. As shown in the figure below, the evolved AutoSella variants significantly reduce the relative force calls while maintaining or exceeding the energy recovery of the reference optimizer across all test sets.
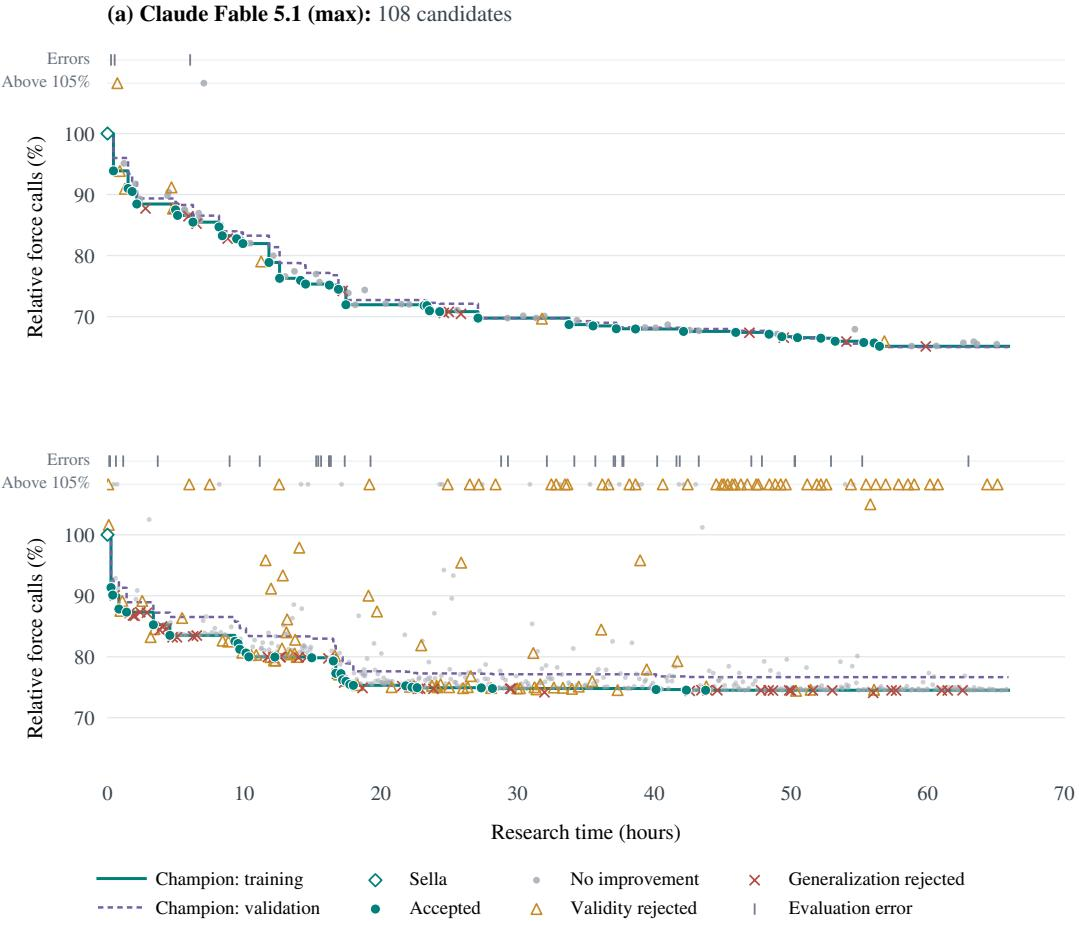
During each iteration, the agent edits the algorithm file and commits the change. An evaluator then scores the candidate on the training split, returning the relative force calls and energy recovery. Crucially, the agent receives a per-molecule table detailing relative force calls, energy differences, and convergence status for each structure. This granular feedback enables the agent to formulate chemically grounded hypotheses and target specific molecular mechanisms. The loop was executed independently for 66 active research hours using two distinct large language model agents.
To ensure robust improvements and prevent the agent from exploiting the convergence criteria, the authors implement a strict two-gate filtering workflow. First, a candidate must pass the validity gate on the training set. This requires the mean energy recovery to be at least 1 (rˉ≥1), the absence of evaluation errors, and a force-call cost strictly lower than the current champion by a small margin to filter out numerical noise. If the candidate passes this initial check, it proceeds to the generalization gate. Here, it is evaluated on a held-out validation split and must satisfy the exact same performance and stability requirements to replace the champion. This dual-gate mechanism effectively prevents overfitting to the training set and ensures that any accepted optimization genuinely generalizes to unseen molecules.
The progression of the autoresearch loop and the impact of the admission gates are clearly illustrated in the training dynamics. The following figure depicts the reduction in relative force calls over active research time, highlighting how the validity and generalization gates filter out suboptimal candidates and evaluation errors to steadily improve the champion optimizer.
Experiment
The evaluation tests the AutoSella optimizers on four held-out molecular datasets across GFN2-xTB and on the unseen GFN-FF and r2SCAN-3c potentials. AutoSella-F consistently lowers force-call cost while matching or improving energy recovery, including under DFT where savings reduce overall cost proportionally, whereas AutoSella-A generalizes less reliably on complex solvated PubChem systems. Analysis of the autoresearch process shows that the two LLM agents work at different rhythms but both propose, test, diagnose, and repair ideas, with ablation highlighting model Hessian and fragment handling as key contributors to the gains.
Across the held-out datasets evaluated on GFN2-xTB, AutoSella-F uses fewer force calls per molecule than the baseline while reaching comparable or lower final energies. AutoSella-A also reduces force-call cost relative to the baseline, though its savings are smaller and it records occasional optimization errors on some molecule sets. The energy recovery ratios remain above one for both variants on all reported blocks, indicating that the reduced cost does not come at the expense of energy fidelity. AutoSella-F is the cheapest method in every reported benchmark block, with relative per-molecule force-call costs consistently below the baseline. Both AutoSella variants achieve mean energy recovery ratios above one, meaning they converge to final energies at least as low as the baseline on average. AutoSella-F completes the reported test and dipeptide optimizations without optimization errors, while AutoSella-A records a small number of errors on two datasets.
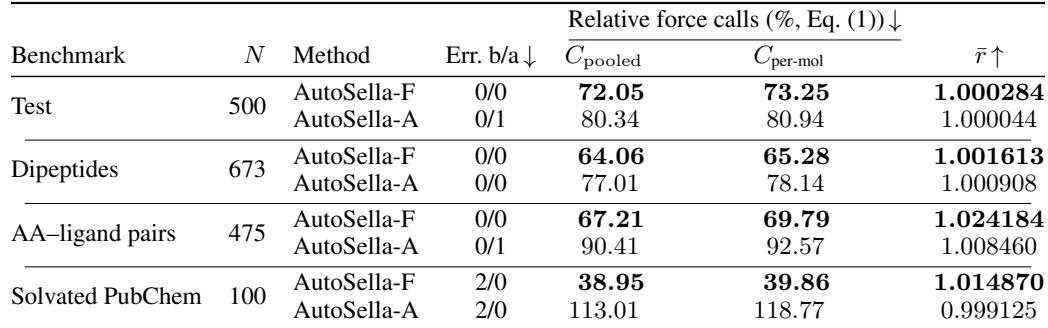
On the GFN-FF benchmarks, AutoSella-F consistently requires fewer force calls than AutoSella-A, and both evolved optimizers remain below the original Sella baseline. AutoSella-F also maintains energy recovery close to or slightly above baseline, while AutoSella-A shows slightly lower recovery on amino-acid ligand pairs. The reported DFT transfer results support the same pattern, with large savings for AutoSella-F and limited generalization for AutoSella-A on solvated multi-fragment systems. AutoSella-F uses a smaller fraction of baseline force calls than AutoSella-A across the GFN-FF test, dipeptide, and amino-acid ligand pair benchmarks. AutoSella-F keeps mean energy recovery at or above baseline on GFN-FF, whereas AutoSella-A falls slightly below baseline on amino-acid ligand pairs. In the DFT transfer results, AutoSella-F achieves its largest saving on Solvated PubChem by using less than half of Sella's force calls while recovering slightly more energy, while AutoSella-A requires more force calls than the baseline and recovers less energy.
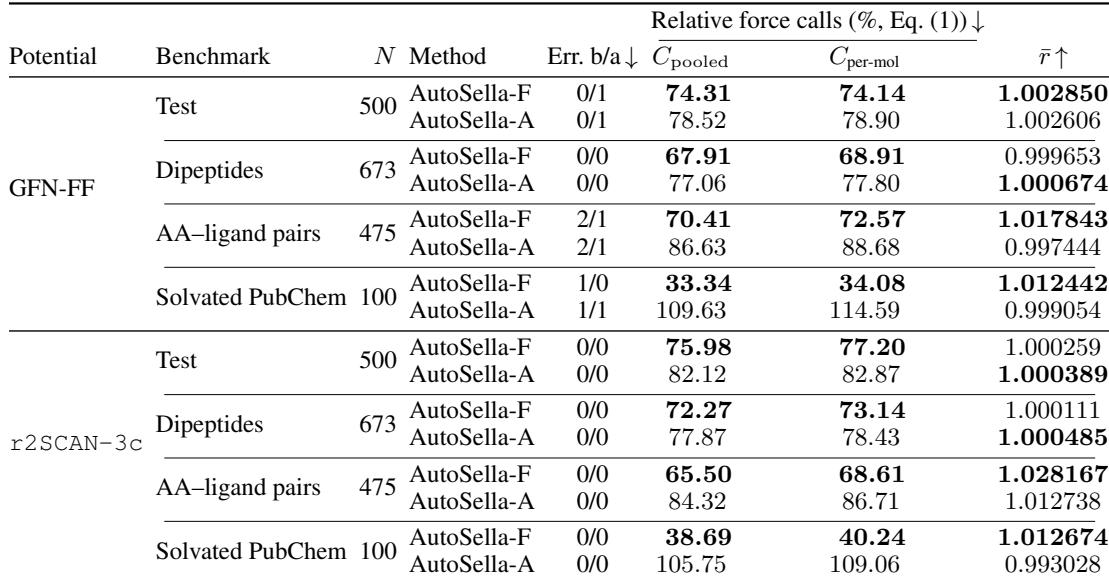
The experiments evaluate two evolved optimizers, AutoSella-F and AutoSella-A, against the Sella baseline across GFN2-xTB, GFN-FF, and transferred DFT benchmarks. AutoSella-F consistently requires fewer force calls per molecule while maintaining comparable or better final energies, and it completes the reported optimizations without errors. AutoSella-A also reduces cost in some settings but shows smaller savings, occasional optimization errors, and slightly lower energy recovery on certain amino-acid and solvated multi-fragment systems.