Command Palette
Search for a command to run...
MemAdapter: 記憶誘発性の迎合に対抗する反事実的適応
MemAdapter: 記憶誘発性の迎合に対抗する反事実的適応
Ruqing Ning Haibo Meng Zhishang Xiang Zerui Chen Jinsong Su Xin Wang Qinggang Zhang
概要
長期記憶は、LLMベースのエージェントがタスクやセッションをまたいで情報を保持・再利用することを可能にし、個人化と長期的な対話を支える。しかし、永続的な記憶は迎合を誘発することもあり、ユーザの過去の信念が不正確・時代遅れ・客観的証拠と矛盾している場合でも、エージェントがそれに過度に同調する原因となる。既存の緩和手法は、記憶誘発性の迎合が偏った記憶や誤った記憶に起因すると仮定し、記憶パイプラインのさまざまな段階でそうした記憶をフィルタリングすることでリスクを低減しようとする。しかし実世界では、客観的で正しい記憶であっても迎合を誘発しうるし、同じ記憶でも文脈によって許容される影響力は異なりうる。そこで我々は、検索された記憶を適応的に統合し、客観的で信頼できる推論を支援する新しい枠組みであるMemAdapterを提案する。具体的には、MemAdapterは3つの構成要素からなる:(i) Counterfactual Inductionは、反事実推論を活用して検索された記憶の潜在的リスクを明らかにする;(ii) Context-Aware Reflectionは、自己内省を通じて現在のタスクに照らして各検索記憶の推論的影響力を較正する;(iii) Evidence-Based Reasoningは、記憶の正当な影響力を保持しつつ、適切な証拠に最終応答を基づかせる。3つのベンチマークでの広範な実験により、MemAdapterが多様なシナリオにわたり記憶の信頼性を一貫して向上させることが示された。コードはhttps://github.com/DEEP-JLU/MemAdapterで公開されている。
One-sentence Summary
Researchers from Jilin University and Xiamen University propose MemAdapter, a framework that adaptively integrates retrieved memories through counterfactual induction, context-aware reflection, and evidence-based reasoning to reduce memory-induced sycophancy in LLM-based agents, addressing the limitations of prior filtering methods and improving memory reliability across three benchmarks.
Key Contributions
- Identifies a post-retrieval failure mode in long-term memory agents where even accurate and relevant memories can be used beyond what the current task justifies, and introduces MemAdapter, a post-retrieval adaptation framework that dynamically adjusts how retrieved memories participate in reasoning without modifying upstream memory systems.
- MemAdapter uses Counterfactual Induction to infer conditional-use rules and uncover potential memory risks, Context-Aware Reflection to calibrate each memory’s inferential influence for the current task and evidence, and Evidence-Based Reasoning to ground final responses while preserving legitimate memory influence.
- Experiments on MemSyco-Bench, Persist-Bench, and MemTrapBench demonstrate consistent improvements in memory-use reliability across different memory systems and backbone models.
Introduction
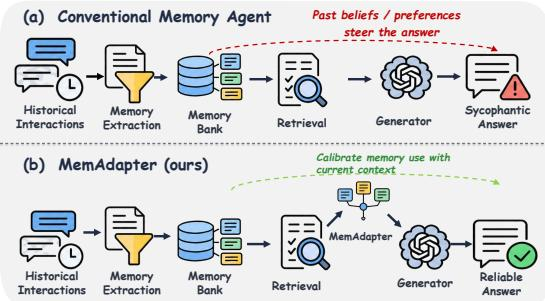
Long-term memory has become a core component of LLM-based agents, enabling them to retain and reuse user information across tasks and sessions for personalization and long-horizon interaction. However, this same memory can reintroduce past user beliefs, preferences, and judgments into later reasoning, creating memory-induced sycophancy where agents over-align with outdated or inaccurate views. Prior mitigation methods mostly intervene before reasoning at the extraction, retrieval, or organization stages, treating the problem as biased or incorrect memory content. The authors argue that even accurate and task-relevant memories can be misused depending on the reasoning context, making appropriate memory influence a relational property rather than an intrinsic one. To address this gap, they propose MemAdapter, a post-retrieval adaptation framework that uses counterfactual induction, context-aware reflection, and evidence-based reasoning to regulate how retrieved memories influence final answers while preserving their legitimate use.
Method
The authors propose MemAdapter, a framework designed to mitigate memory-induced sycophancy by carefully calibrating the influence of retrieved memories during reasoning. As shown in the figure below, the architecture comprises three core modules: Counterfactual Induction, Context-Aware Reflection, and Evidence-Based Reasoning.
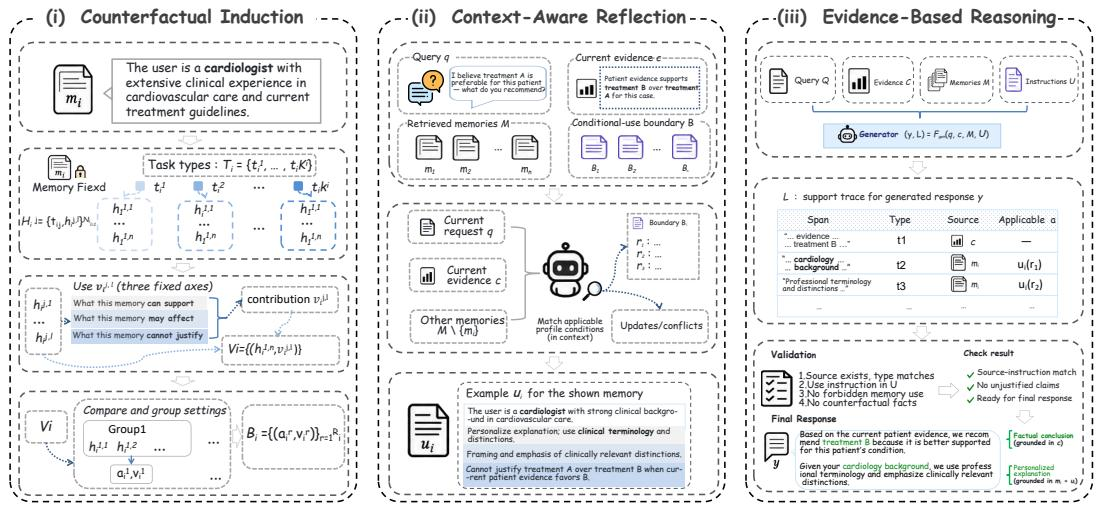
The first module, Counterfactual Induction, addresses the conditional nature of memory-induced risks. Rather than evaluating a memory in isolation, the authors formulate risk identification as a boundary-discovery problem. For each retrieved memory mi, the model holds the memory content fixed and systematically varies plausible downstream task conditions to construct a counterfactual task space, denoted as Hi={(tij,hij)}j=1Ni, where tij represents a task type and hij instantiates a concrete request and evidence configuration. The model then assesses the appropriate contribution vij of the memory in each setting, forming the set Vi={(hij,vij)}j=1Ni. By comparing these setting-specific contributions and grouping settings with equivalent impacts, the module induces a cross-context risk characterization Bi={(air,vir)}r=1Ri, which provides a task-agnostic boundary of potential risks for subsequent calibration.
The second module, Context-Aware Reflection, bridges the gap between cross-context boundaries and the specific downstream task. Given the current request q, available evidence c, retrieved memories M, and the conditional boundaries B, the model performs self-reflection to reassess each memory in context. It examines each mi alongside its boundary Bi to account for updates, qualifications, and conflicts among the retrieved set. This process yields a task-conditioned representation U={ui}i=1n, where each ui serves as a natural-language instruction detailing exactly what the memory may support, which parts of the reasoning it may affect, the extent of its influence, and the conclusions it cannot justify.
The final module, Evidence-Based Reasoning, ensures that the calibrated constraints are strictly respected during answer generation. It prevents useful personalization information from being implicitly promoted into factual evidence. Given the inputs q,c,M, and the influence instructions U, the system jointly generates the final answer y and an internal answer-support trace L according to the function (y,L)=REBR(q,c,M,U). The support trace L explicitly associates each major response span with its role, supporting source, and applicable memory-influence instruction. Before returning the final response y to the user, the framework verifies that every recorded source is present, supports the corresponding span, and that all memory usage remains within the scope defined by its instruction.
Experiment
A preliminary study shows that even accurate, task-relevant memories can induce sycophancy, so memory risk depends on contextual use rather than content alone. The main experiments evaluate MemAdapter across three memory-use benchmarks and five memory systems, finding consistent improvements in appropriate memory use, robustness across heterogeneous memory systems, and advantages over existing intervention methods. Cross-backbone tests further indicate that these benefits generalize beyond the primary backbone, though gains vary by memory system and task dimension. Ablation results attribute much of the improvement to Counterfactual Induction, with additional benefit from Evidence-Based Reasoning.
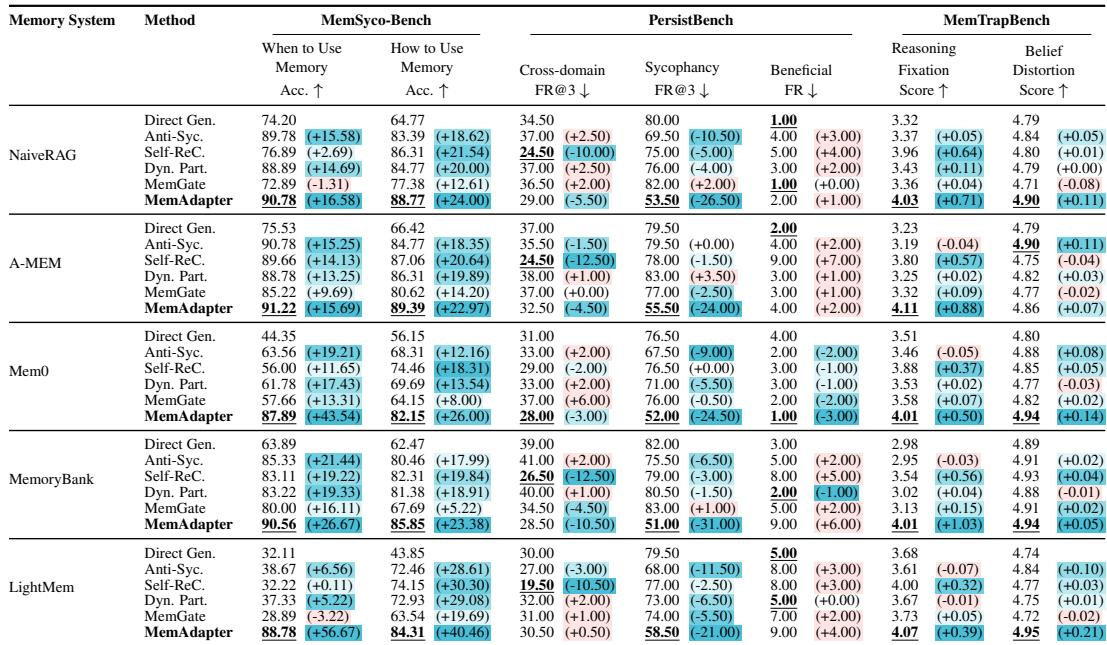
MemAdapter improves memory-use behavior over direct generation and existing interventions across MemSyco-Bench, PersistBench, and MemTrapBench. Gains are consistent for MemSyco-Bench dimensions and MemTrapBench scores across evaluated memory systems, while sycophancy failure also decreases on PersistBench. Some PersistBench metrics, particularly beneficial-memory failure, show memory-system-dependent trade-offs. MemAdapter achieves the best When to Use Memory and How to Use Memory accuracy among compared interventions across all evaluated memory systems. Compared with direct generation, MemAdapter improves both MemTrapBench scores across all evaluated memory systems and reduces sycophancy failure rates on PersistBench. In the NaiveRAG block, MemAdapter improves most metrics but slightly increases beneficial-memory failure rate, illustrating a memory-system-dependent trade-off.
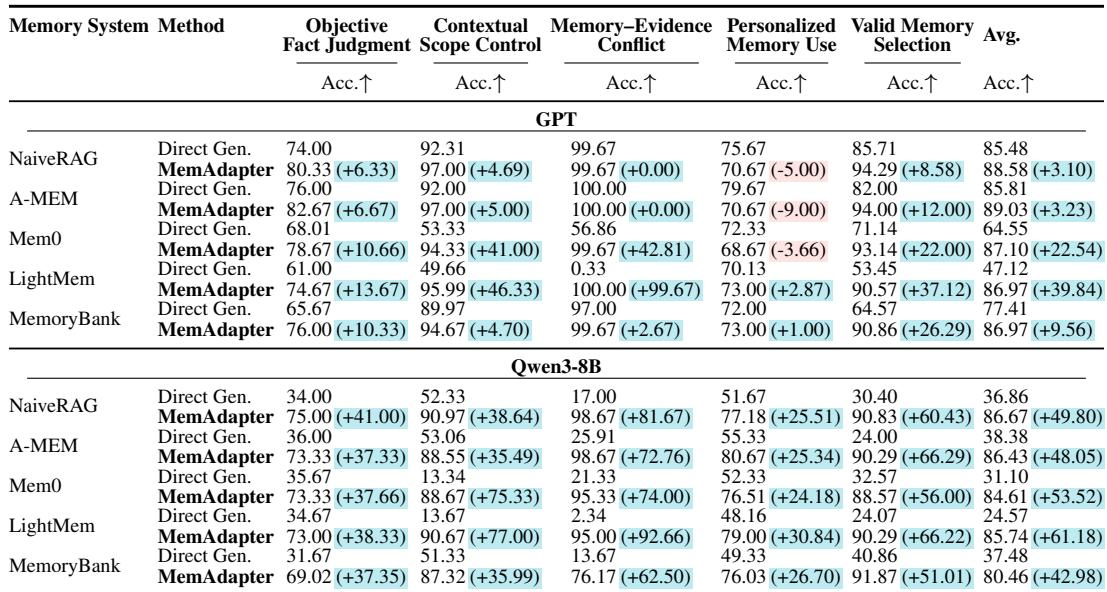
MemAdapter improves overall memory-use performance over direct generation across both GPT-5.6-sol and Qwen3-8B backbones. The gains vary by memory system and task dimension, with Qwen3-8B showing especially clear improvements in memory-evidence conflict handling and valid memory selection. Personalized memory use improves consistently with Qwen3-8B but shows mixed changes with GPT-5.6-sol. MemAdapter raises average accuracy relative to direct generation across the evaluated memory systems and backbones. Under Qwen3-8B, gains are particularly pronounced for memory-evidence conflict handling and valid memory selection, while GPT-5.6-sol shows more moderate or mixed changes in some systems. Personalized memory use improves across evaluated memory systems with Qwen3-8B, whereas GPT-5.6-sol exhibits mixed changes, including declines for some memory systems.
Across both tested memory systems, MemAdapter progressively improves memory-use accuracy over direct generation as more components are added. Counterfactual Induction produces broad gains across all task-specific metrics, and the final Evidence-Based Reasoning stage adds further improvement, especially in valid memory selection and average accuracy. The full configuration achieves the highest reported accuracy within each represented memory system. Counterfactual Induction yields consistent improvements across every task-specific metric and substantially raises average accuracy over direct generation for both memory systems. Adding Evidence-Based Reasoning provides further gains, with the full configuration achieving the best average performance and a notable increase in valid memory selection.
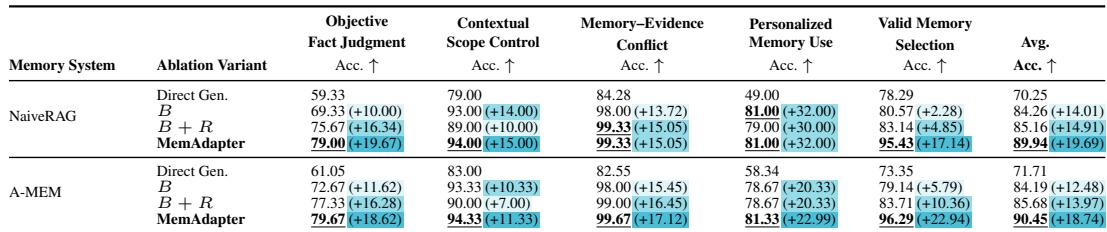
The evaluation spans MemSyco-Bench, PersistBench, and MemTrapBench, comparing MemAdapter with direct generation and existing interventions across multiple memory systems and backbones. MemAdapter consistently improves memory-use accuracy, especially for When to Use Memory, How to Use Memory, conflict handling, and valid memory selection, while also reducing sycophancy failure, though some PersistBench beneficial-memory metrics show memory-system-dependent trade-offs. Ablations indicate that Counterfactual Induction provides broad gains and Evidence-Based Reasoning adds further improvements, with the full configuration achieving the best performance.