Command Palette
Search for a command to run...
長期地平のワークエージェントのための検証可能環境のスケーリング
長期地平のワークエージェントのための検証可能環境のスケーリング
概要
ワークエージェントはデジタル成果物を対象に動作し、専門的な知識集約型業務を実行するため、長期地平の相互作用と信頼できる検証を支える訓練環境を必要とする。しかし、手作業で構築した環境は、環境のスケーリングを阻むほど過大なエンジニアリング負荷をともない、一方、合成手法はワークスペースの複雑さ、現実性、または事実に根ざした検証可能性を犠牲にする。このギャップを埋めるため、我々は WORKFORGE を提案する。これは、実世界の資源から検証可能なワークエージェント環境を構築するためのスケーラブルな合成フレームワークである。専門家ワークフローに始まり、WORKFORGE はまず各ワークフローに必要な資源、意思決定、成果物を特定する。次に、関連する実世界のファイルを取得し、ワークスペースとして整理する。WORKFORGE はワークスペースを検査し、その内容に関する具体的で検証可能な事実を抽出する。これらの事実的アンカーが、そのワークスペースでサポート可能なタスクの種類と、その結果を検証する方法を固定する。したがって、WORKFORGE は、これらの事実的アンカーから、各タスクの指示、解決計画、および相補的なプログラム的検証器と意味的検証器を直接導出し、検証が観察可能なワークスペース証拠に対して追跡可能に保つ。さらに、我々は40の専門ドメインにわたって16.7Kの検証可能環境を構築し、ワークスペース全体で60種類のファイル形式をカバーした。Qwen3.5-35B-A3B-Base を事後訓練すると、GDPval が 45.5 から 73.6 に、APEX Score が 5.0 から 21.3 に向上し、同時に Qwen3.5-27B が非常に競争力のある性能を達成し、強力な競合を上回ることが可能になる。我々の分析は、提案手法の有効性を確認し、データ量と相互作用地平の双方において一貫したスケーリング挙動が得られることを明らかにする。
One-sentence Summary
Tencent and Fudan University introduce WORKFORGE, a scalable synthesis framework that avoids costly handcrafted or oversimplified synthetic setups by converting expert workflows, retrieved real-world files, and workspace-derived factual anchors into 16.7K verifiable work-agent environments spanning 40 professional domains and 60 file types, enabling Qwen3.5-35B-A3B-Base post-training to improve GDPval from 45.5 to 73.6 and APEX Score from 5.0 to 21.3 while helping Qwen3.5-27B achieve highly competitive results.
Key Contributions
-
WORKFORGE is introduced as a scalable framework that constructs verifiable work-agent environments from real-world resources by profiling expert workflows, retrieving relevant files, and organizing audited workspaces whose observable facts anchor task specifications, solution plans, and verification criteria. It derives each task’s instructions, plans, and complementary programmatic and semantic verifiers from these factual anchors, keeping verification tied to workspace evidence.
-
The framework instantiates 16.7K verifiable environments across 40 professional domains, with workspaces collectively covering 60 file types and rich cross-file dependencies. These environments support long-horizon interaction and produce supervision for agent post-training.
-
Fine-tuning Qwen3.5-35B-A3B-Base on the resulting trajectories improves GDPval from 45.5 to 73.6 and APEX from 5.0 to 21.3 across five benchmarks, while Qwen3.5-27B reaches competitive performance. Controlled analyses show consistent gains as data volume and interaction horizons increase.
Introduction
Autonomous agents are moving large language models from conversational assistants toward digital workers that complete professional workflows across files and tools. This shift matters because real deliverables depend on authentic workspaces with complex file dependencies, so training environments must expose realistic friction and verifiable feedback. Prior environment synthesis often relies on synthetic or mock resources, creating toy workspaces with limited diversity and cross-file relationships, while ungrounded evaluation can introduce hallucinated or unsupported requirements. The authors introduce WORKFORGE, a scalable framework that builds verifiable work-agent environments from real-world digital resources by grounding task specifications and verifier rubrics in observable workspace facts. The authors leverage expert workflows as blueprints, retrieve and profile real resources to recover file roles, dependencies, and factual anchors, and then generate tasks plus programmatic and semantic checks for reliable trajectory collection. The framework yields 16.7K environments across 40 domains, and fine-tuning Qwen3.5-35B-A3B-Base on these trajectories improves performance on several agent benchmarks.
Dataset
-
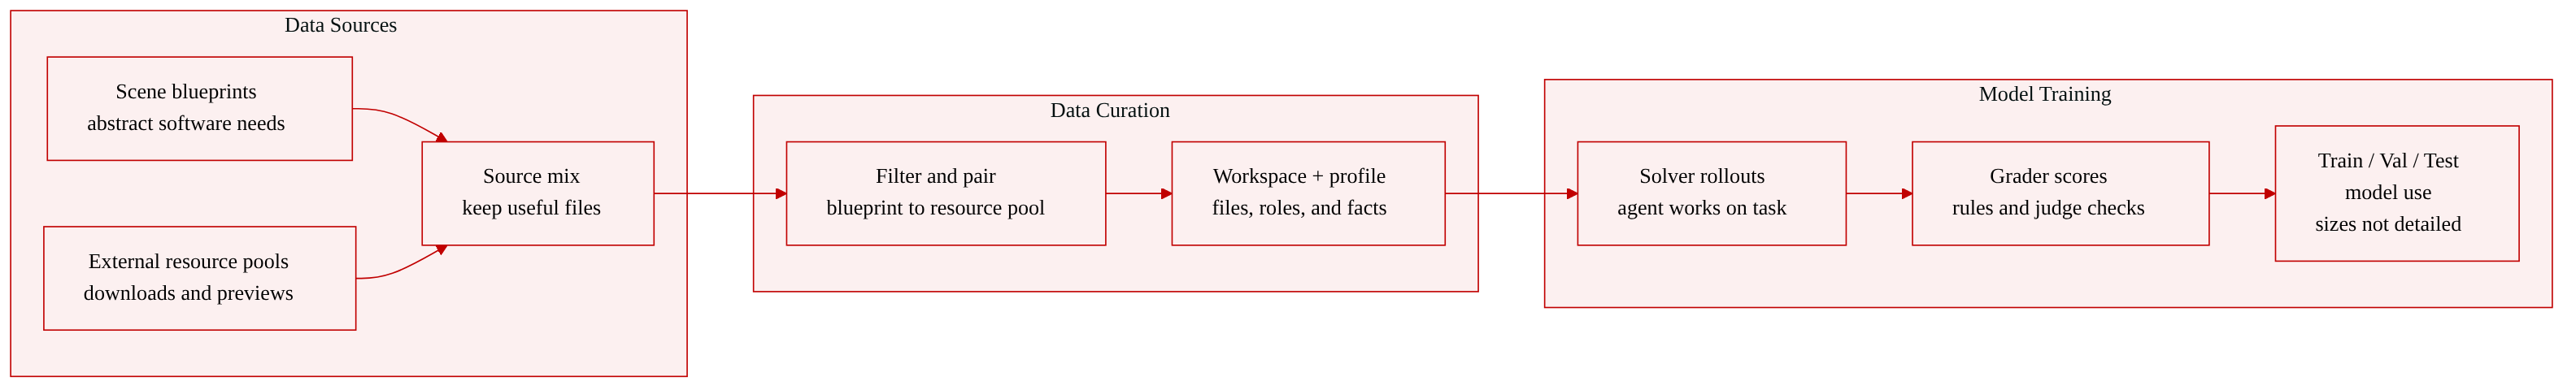
The authors describe a synthesized agentic dataset built from scene blueprints that are expanded into concrete software workspaces.
-
Each scene blueprint is mapped to multiple environments by acquiring distinct resource pools from external sources. An acquisition agent searches, reads, downloads, and previews resources to keep only relevant artifacts and associate them with the abstract requirements of the blueprint.
-
Each retained environment contains a workspace realized from one nonempty resource pool. The workspace preserves the original file organization of the selected pool, and the number of retained environments per blueprint is denoted by K_j.
-
Each workspace is paired with an environment profile. The profile summarizes the domain, file roles, and possible task directions; records observable workspace facts; and stores artifact schemas and statistics. These profiles provide factual anchors for task construction and verification.
-
The dataset instance used for agent evaluation includes the visible workspace, task instructions, trajectory records, output artifacts, programmatic scores, semantic scores, and model configuration. Trajectories are produced by letting a solver agent interact with the workspace until it submits deliverables or reaches an execution limit.
-
After rollout, programmatic and semantic graders evaluate the final workspace and submitted outputs. Complete execution records are retained as scored trajectory data, linking agent behavior to verifiable outcomes.
-
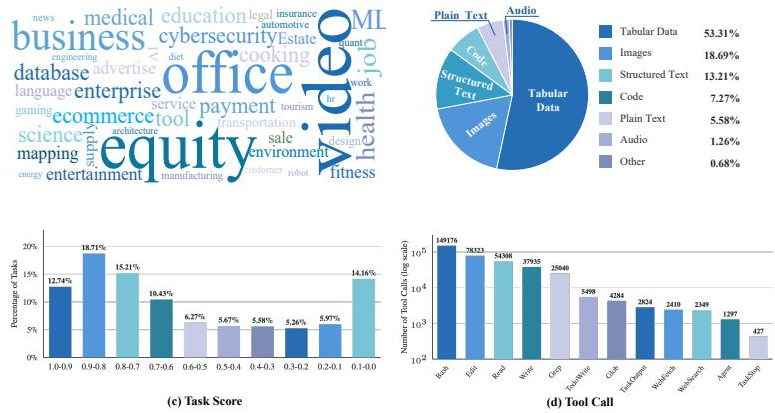
The paper refers to corpus-level scalar statistics, domain coverage, file types, task scores, and tool-call distributions in its reporting, but the provided excerpt does not specify exact subset sizes, training splits, mixture ratios, cropping rules, or metadata schema values.
Method
The authors introduce WORKFORGE, a framework designed to translate professional workflows into realistic and verifiable agent environments. This approach ensures that agent environments scale without sacrificing authenticity. The overall framework operates through a four-stage pipeline, as illustrated in the figure below.
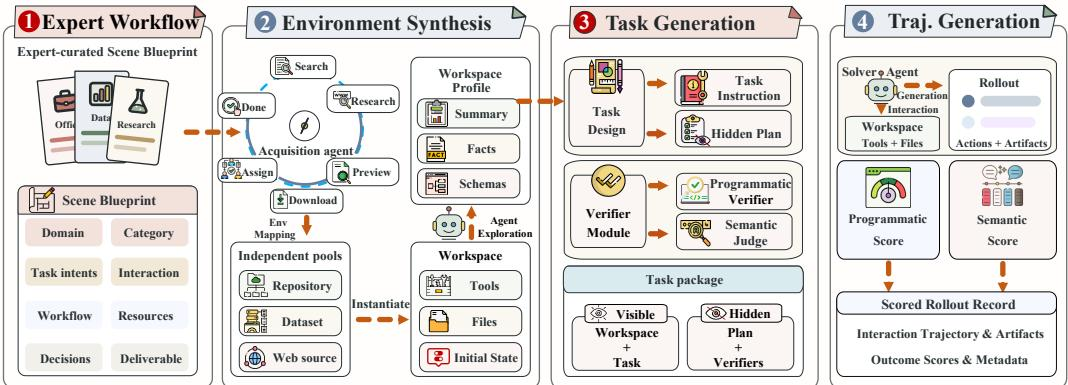
Workflow Specification To generate sophisticated professional tasks, the authors engage domain experts to distill their workflows into reusable Scene Blueprints. These blueprints identify dependencies between initial conditions, domain-specific operations, and final deliverables. A collection of M blueprints is defined as B={bj}j=1M, where each blueprint bj=(Wj,Oj,Rj,Dj) specifies the workflow context Wj, the expected deliverable Oj, required sources and dependencies Rj, and domain-specific decisions Dj. Each blueprint serves as a seed connecting expert intent to task generation.
Environment Synthesis This stage integrates environment mapping and environment profiling to instantiate each blueprint into a concrete workspace. For a scene blueprint bj, the stage produces a set of environments Env(bj)={(Wjk,Pjk)}k=1Kj.
Environment mapping expresses the one-to-many relationship between a blueprint and its concrete environments. An acquisition agent iteratively searches for sources and downloads resources to form distinct resource pools {Rjk}k=1Kj. The workspace is realized as Wjk=ϕRjk(bj).
Environment profiling defines the description accompanying each environment. The profile Pjk=(Ujk,Fjk,Ajk) includes a summary Ujk of the domain and file roles, workspace facts Fjk, and artifact schemas and statistics Ajk. This profile supplies factual anchors for task construction and verification.
Task Generation Task generation produces executable task packages with aligned requirements and verification criteria.
Task Design combines the scene blueprint and environment profile to specify the professional objective. The task designer jointly generates the visible instruction qjk and the hidden solution plan hjk:
(qjk,hjk)=(ftask(bj,Pjk),fplan(bj,Pjk))Verifier Design translates these requirements into an atomic rubric set Vjk=Vjkprog∪Vjksem. Programmatic criteria check final artifacts Yjk to produce a score Sjkprog. Semantic criteria configure an LLM judge Gjksem to assess open-ended requirements, producing a normalized score Sjksem. The resulting task package separates visible inputs from hidden components:
Tjk=visible(Wjk,qjk),hidden(Pjk,hjk,Fjk,Vjk,Gjkprog,Gjksem)Trajectory Generation Trajectory generation turns the static task package into observed agent behavior. For each task package Tjk, a solver agent πθ receives only the visible pair (Wjk,qjk) and interacts with the workspace. This rollout process is denoted as:
(τjk,Yjk)=Rollout(πθ;qjk,Wjk)where τjk records ordered messages and tool interactions, and Yjk denotes output artifacts. After execution, the graders evaluate the final workspace and artifacts to produce programmatic and semantic scores. The complete execution is retained as a scored trajectory record zjk=(τjk,Yjk,Sjkprog,Sjksem,μjk). The resulting corpus exhibits diverse professional domains, file types, and tool usage patterns, as summarized in the figure below.
Experiment
The experiments evaluate WORKFORGE-trained agents on several work-agent benchmarks against proprietary, large open-source, and smaller open-source baselines, while ablations examine the effects of training harness, verification signals, and workspace authenticity. Overall, the results show that the proposed training pipeline produces strong generalist work agents, with the smaller model performing well among sub-100B baselines and the larger model approaching frontier capability, especially on tasks requiring complex workspace exploration and evidence integration. Further analyses indicate that broader real-world data, longer interaction trajectories, aligned evaluation harnesses, and hybrid verification each contribute to more sustained tool use, better planning, and higher-quality professional deliverables.
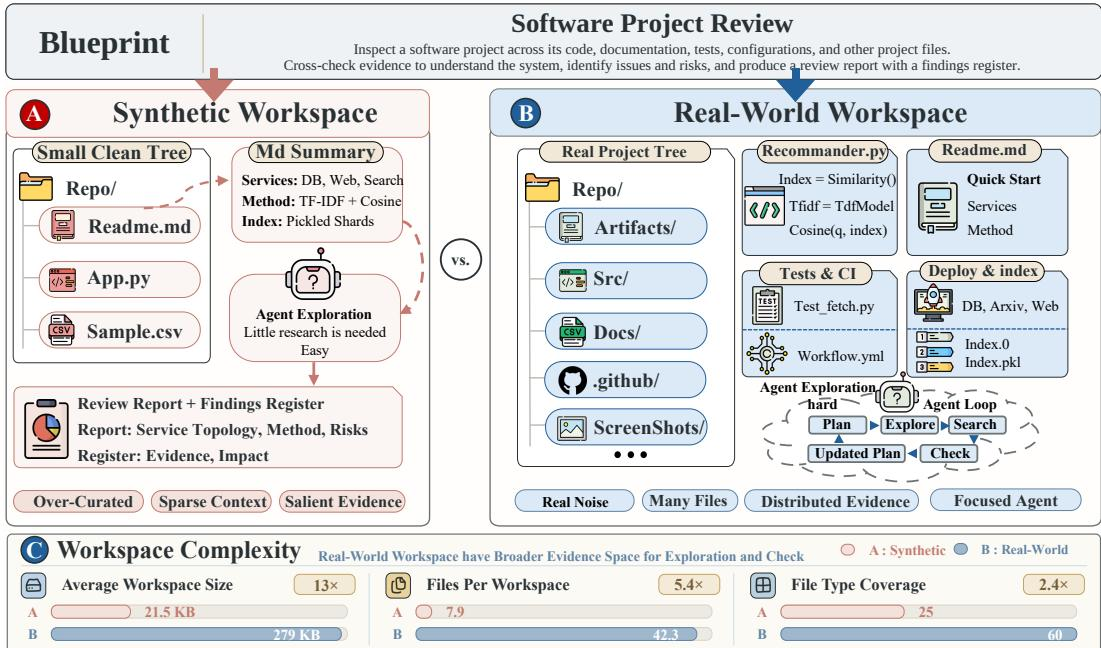
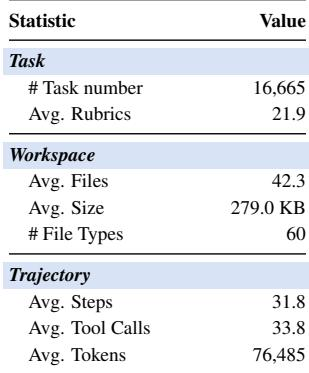
WORKFORGE provides a large collection of tasks with multiple evaluation rubrics per task and heterogeneous workspaces containing many files and file types. It also records trajectories that include tool interactions, output artifacts, and programmatic and semantic scores. These task, workspace, and trajectory dimensions support analysis of agent behavior and scaling studies. The dataset includes a large number of tasks with multiple rubrics per task. Workspaces are file rich and diverse, averaging many files and many file types. Trajectory records capture ordered agent interactions, output artifacts, and evaluation scores. Real world acquisition enlarges workspace scale and heterogeneity, providing a richer artifact and evidence space for agents.
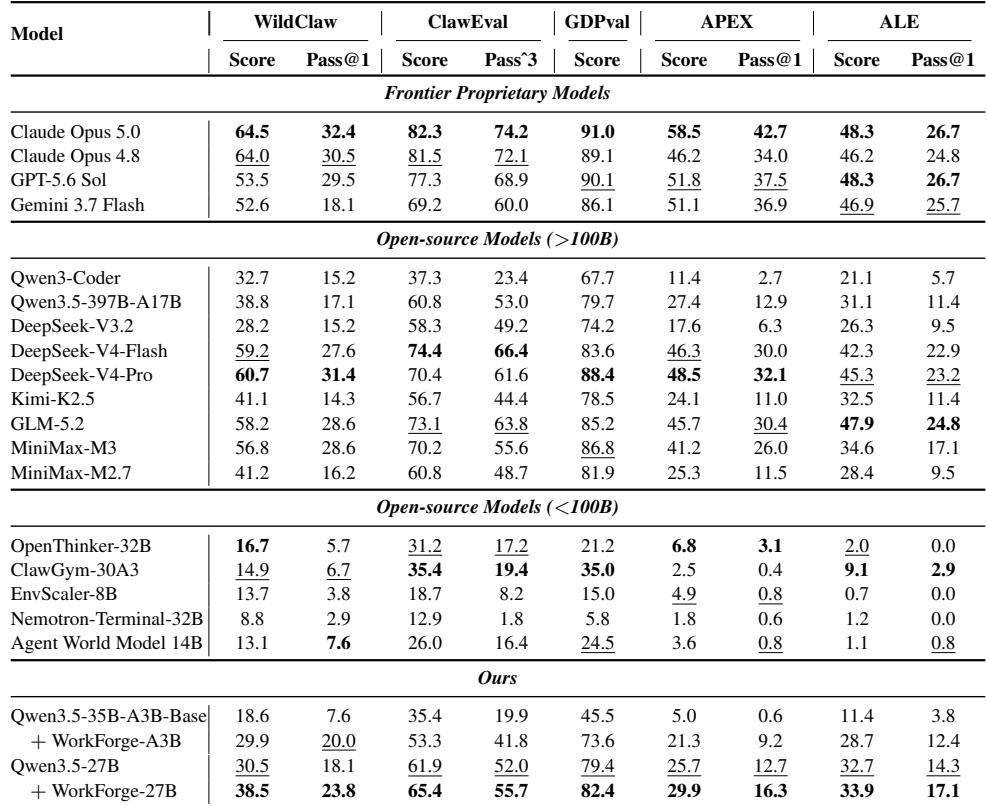
WORKFORGE-A3B is competitive across agent capability benchmarks, with especially strong gains over prior specialized sub-100B models on GDPval and continued strength under strict pass-rate metrics. WORKFORGE-27B also improves a larger open model across WildClaw, ClawEval, GDPval, APEX, and ALE, reaching frontier-like GDPval performance with far fewer parameters. WORKFORGE-A3B surpasses prior specialized sub-100B baselines by a large margin on GDPval while staying competitive on WildClaw, ClawEval, APEX, and ALE. WORKFORGE-27B improves across all five benchmarks and narrows the gap to frontier systems such as Claude and GPT on GDPval.
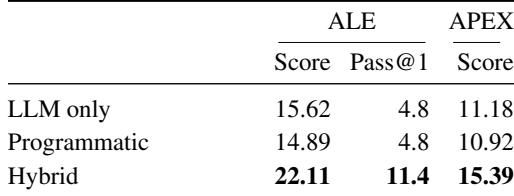
Hybrid trajectory selection combines LLM-based quality verification with programmatic checks and performs better than using either signal alone. This suggests that verification signals from both exact workspace states and content quality provide more useful supervision for selecting training trajectories. Hybrid verification produces the strongest results across the reported metrics. LLM-only and programmatic-only selection remain similar and fall below the combined method.
The experiments evaluate WORKFORGE’s dataset design, model capability on agent benchmarks, and trajectory selection strategies. The dataset’s many tasks, rubrics, diverse workspaces, and detailed trajectory records support analysis of agent behavior and scaling trends. WORKFORGE-trained models show competitive or improved performance across agent evaluation suites, with especially strong gains on GDPval and reduced gaps to frontier systems. Hybrid trajectory selection using both programmatic and semantic verification outperforms either signal alone, indicating that combining workspace-state checks with content-quality evaluation provides better supervision.