Command Palette
Search for a command to run...
4DCodeBench:動的シーンの逆グラフィックスにおけるエージェントのベンチマーク
4DCodeBench:動的シーンの逆グラフィックスにおけるエージェントのベンチマーク
Ruihong Shen Žiga Kovačič Peter Kulits Xingrui Wang Zizhang Li Joshua B. Tenenbaum Alan Yuille Jieneng Chen Jiajun Wu
概要
本稿では、コード生成による4D逆グラフィックスのためのベンチマークである4DCodeBenchを紹介する。これは、エージェントがビデオから動的シーンを実行可能なグラフィックスプログラムとして再構築するものである。これを達成するためには、エージェントは視覚的観察をシーン構造とダイナミクスのコンパクトな表現に変換し、複雑な挙動を再現するための物理シミュレーションなどの抽象化を実装する必要がある。この能力を評価するために、我々は実世界のビデオのセットを厳選し、変形、流体の流れ、破壊などの多様な物理現象を網羅する合成シーンを構築した。最先端モデルの広範なベンチマークを行った結果、強力な静的再構築能力が、必ずしも複雑なダイナミクスの信頼性の高い再構築にはつながらないことが判明した。4DCodeBenchは、コードを通じて世界のダイナミクスを解釈できるエージェントへの進歩を追跡するためのテストベッドを提供する。ベンチマークはgithub.com/4DCodeBench/4DCodeBenchで公開している。
One-sentence Summary
Researchers from the Max Planck Institute for Intelligent Systems and MIT introduce 4DCodeBench, a benchmark for 4D inverse graphics via code generation that tasks agents with reconstructing dynamic scenes from video as executable graphics programs across deformation, fluid flow, and fracture, and their extensive benchmarking of frontier models shows that strong static reconstruction capabilities do not yet translate into reliable dynamic reconstruction, providing a testbed for tracking progress toward agents that interpret world dynamics through code.
Key Contributions
- Introduces 4DCodeBench, a benchmark for 4D inverse graphics through code generation, where agents reconstruct dynamic scenes from real-world videos and synthetic scenes as executable graphics programs, covering physical phenomena such as deformation, fluid flow, and fracture, with rendering in Blender while remaining simulator-agnostic.
- Formalizes the reconstruction pipeline as generating executable code that exposes geometric states over time and renders them with specified camera, lighting, and materials, requiring execution without access to the reference video, thereby testing both static appearance and dynamic abstraction.
- Extensive benchmarking of frontier models shows that strong static reconstruction does not reliably transfer to dynamic reconstruction, revealing a persistent gap, and automated rankings closely agree with human preferences, providing a testbed for tracking progress in 4D inverse graphics.
Introduction
Inverse graphics typically fits a predefined model to visual observations, but recovering an executable graphics program shifts model specification into the inference problem itself. Dynamic scenes make this harder because flow, fracture, and deformation involve shape and topology changes, and materials interact to affect each other’s motion. Prior benchmarks like 3DCodeBench and PhysCodeBench focus on static objects or text-based simulations, while VisPhyWorld and MPMWorlds reconstruct synthetic videos in 2D, and BVB handles static indoor scenes. These approaches often assume fixed camera motion or simplified dynamics, leaving real-world interactions and 3D ground truth underaddressed.
The authors introduce 4DCODEBENCH to evaluate 4D inverse graphics through code generation. Given a reference video, agents must write executable code that constructs the scene’s 3D geometry over time and renders it in Blender, with no restrictions on implementation approach, allowing keyframed or simulated dynamics. The benchmark includes 100 real videos and 100 synthetic scenes with 4D ground truth, and evaluates appearance, geometry, and dynamics separately. Across 18 frontier models, the authors find that reconstructing dynamics consistently lags behind appearance and static geometry, even when leading models adopt different strategies like analytic motion versus custom physics simulation.
Dataset
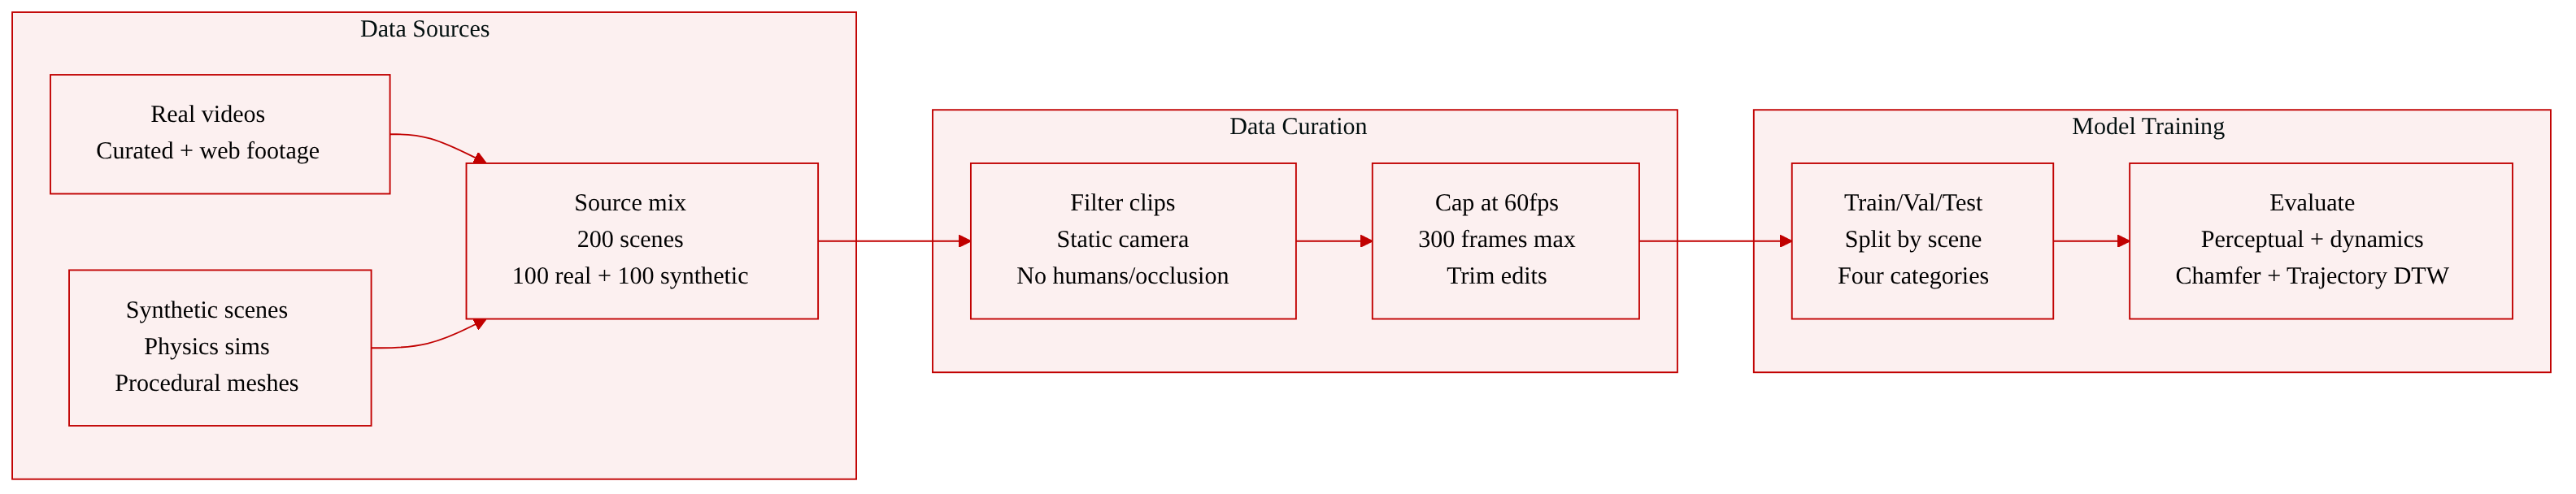
The authors introduce 4DCOD EBEN CH, a benchmark dataset composed of 200 scenes, split evenly between 100 real-world videos and 100 synthetic scenes built with physics simulations. This dual-source design serves complementary roles: real videos capture realistic appearance and complex dynamics but lack 4D ground truth, while synthetic scenes provide full ground-truth geometry and motion at every frame, enabling direct evaluation in 3D and 4D space.
Dataset composition and sources
- Real-world scenes are curated from existing physical-understanding, video-generation, and robotics datasets, supplemented with web-sourced footage.
- Selection criteria prioritize diverse physical behaviors, stationary cameras, limited occlusion, and continuous footage without cuts. Humans, animals, and visible hands are excluded to avoid reconstruction challenges.
- Synthetic scenes are constructed using existing physical simulators, with extensions where needed. Scenes use procedurally generated geometry alongside public meshes like the Stanford bunny and armadillo, designed by the authors to vary geometry, materials, initial conditions, and rendering settings.
Scene ontology and statistics
- Scenes are organized into four primary categories: rigid and articulated bodies, deformable solids, co-dimensional structures (cloth, rope), and flowing materials (grains, fluids).
- Each scene is further characterized by object count, material composition, and dynamics regime, distinguishing passive dynamics from externally driven motion like robotic manipulation.
- 83% of scenes contain multiple dynamic objects, and 66% contain multiple materials, including interactions such as rigid-deformable, rigid-fluid, and fluid-deformable coupling.
- Videos are capped at 60 fps, and real videos are capped at 300 frames. Higher source frame rates are temporally subsampled, while lower frame rates are retained.
Usage and evaluation
- The dataset supports evaluation across five metric families: Perceptual, 2D Dynamics, and 2.5D Geometry against the reference video, plus 3D Geometry and 3D Dynamics against the reference world for synthetic scenes.
- Video-reference evaluations use DINOv3 similarity for perceptual fidelity, Dynamic IoU for moving object coverage, and off-the-shelf models for optical flow, trajectories, and depth estimation on real videos.
- Synthetic scenes enable direct 3D evaluation, including Chamfer distance for static surface accuracy and both Lagrangian (Trajectory DTW) and Eulerian (EMD step) perspectives for motion comparison.
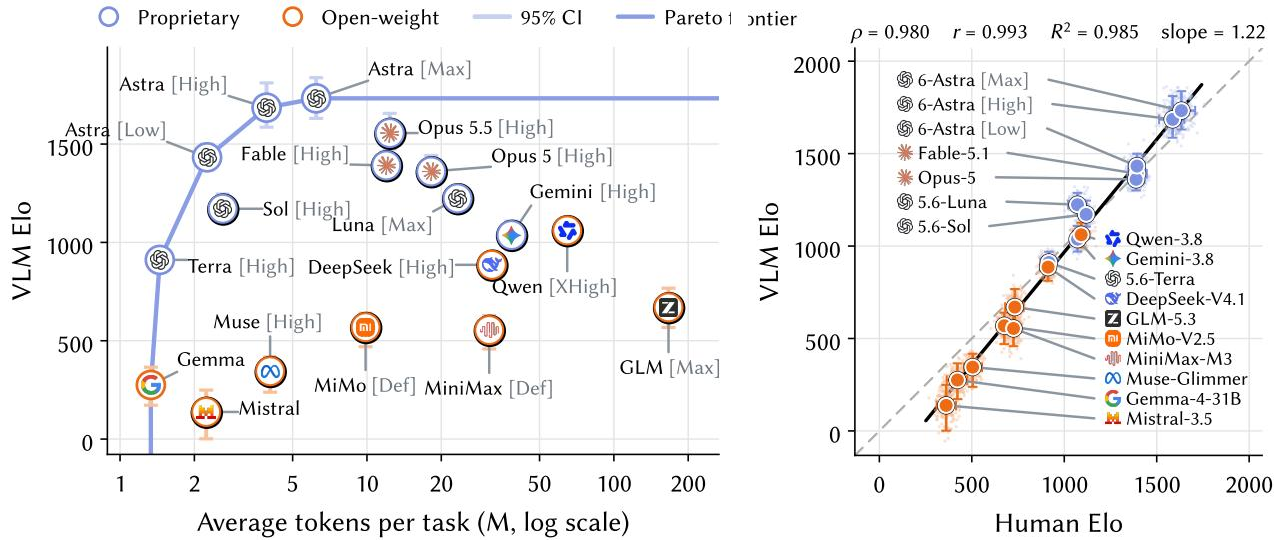
- A vision-language model serves as a judge for VQA tasks across four categories (initial state, final state, key events, contact) and pairwise comparisons, aggregated into an Elo rating using a Bradley-Terry model.
- Geometry diagnostics check structural defects like open boundaries, non-manifold edges, and object interpenetrations, reported separately from the Overall score.
Method
The authors frame 4D inverse graphics as a program synthesis problem. Given a reference video xref=(x0,…,xT−1) of a physical scene, an agent must produce executable graphics code Γ=(γ1,…,γm) that fully describes the scene’s 3D geometry and its temporal evolution. The formulation imposes no constraints on the number, organization, or roles of the individual programs; the only requirement is that executing Γ exposes a geometric state sΓ(t) at every evaluated timestep and renders that state in Blender through a rendering procedure RΓ:
Γ=A(xref),x^k=RΓ(sΓ(k/r)),k=0,…,T−1,where A(⋅) denotes the agent and r is the reference frame rate. The rendering procedure uses the camera, lighting, and materials specified by Γ, and the output must match the reference video’s resolution, frame count, and frame rate. Importantly, Γ must execute without any further access to xref. While the authors render in Blender, the code implementation is simulator-agnostic: dynamics can be keyframed or simulated with any tool, such as Taichi or Warp.
To evaluate this task, the authors construct a benchmark comprising both real-world videos and synthetic scenes that span a broad range of physical dynamics, including robotic manipulation, controlled physics demonstrations, and everyday activities. The scenes are organized into four primary categories: rigid and articulated bodies, deformable solids, co-dimensional structures such as cloth and rope, and flowing materials such as grains and fluids. Across these categories, the scenes exhibit collisions, deformation, flow, and fracture. The authors further characterize each scene by object count, material composition, and dynamics regime, distinguishing passive dynamics from externally driven motion, such as robotic manipulation or prescribed motion of rigid objects.
For the real-world component, videos are curated from existing physical-understanding, video-generation, and robotics datasets, supplemented with web-sourced footage. The selection emphasizes diverse physical behaviors while minimizing repeated scenarios, prioritizing stationary cameras, limited occlusion, and continuous footage without cuts or editing-induced discontinuities. Humans and animals are excluded, and visible hands are minimized, as reconstructing their detailed geometry and articulation introduces challenges beyond the focus on dynamics. Each clip is manually selected and reviewed for visual quality and temporal continuity.
For the synthetic component, the authors leverage existing physical simulators and extend their implementations where needed to support additional material models. Scenes are designed by combining procedurally generated geometry with publicly available meshes, such as the Stanford bunny and armadillo. The simulators are chosen to match each scene’s desired materials and interactions, and they are used to compute the objects’ geometry and motion over time. The scenarios deliberately vary geometry, material types and parameters, initial conditions, and rendering settings to create diverse reconstruction tasks. Authors with experience in physical simulation review each scene for numerical instability, unintended interpenetration, and other visible simulation artifacts.
Experiment
The evaluation constructs a benchmark of 200 scenes spanning real videos and synthetic simulations across rigid, deformable, co-dimensional, and flowing materials, then tests 18 multimodal coding models on reconstructing 4D worlds from monocular video. A suite of automated metrics covering perception, geometry, and dynamics aligns strongly with human pairwise preferences, validating its use for model comparison. Results show that all models struggle more with motion than appearance, that real and multi-material scenes are harder, and that increasing inference-time reasoning consistently improves a model's scores, while different models adopt varied strategies for implementing dynamics.