Command Palette
Search for a command to run...
Adaptive Reward Routing:前方過程RLによる音声・映像統合拡散のための動的マルチ報酬最適化
Adaptive Reward Routing:前方過程RLによる音声・映像統合拡散のための動的マルチ報酬最適化
Songlin Yang Xiaotong Zhao Jiacheng Zhang Zhe Wang Toyota Li Eric Liu Alan Zhao Anyi Rao
概要
マルチ報酬誘導型強化学習(RL)は、モダリティ固有の品質、クロスモーダルな意味的整合性、時間的同期など、複数の目的に沿って音声・映像統合拡散モデルを改善する有望な方法を提供する。しかし、その有効性は訓練中に変化する2つの量、すなわち報酬駆動型の更新をどこに作用させるべきか、競合する報酬をどのように調整すべきかに依存する。既存手法は固定されたルーティングと報酬重みに依存する傾向があり、変化するモデルの機能を追跡できない。これらの限界に対処するため、我々は、音声・映像統合拡散モデルの前方過程RL(すなわちDiffusionNFT)中に、更新箇所と報酬調整を同時に適応させるAdaptive Reward Routingを提案する。本手法は2つの構成要素からなる。(i) クロスモーダル影響誘導ルーティング(更新の局所化):我々は、変化するクロスモーダル影響の効率的な代理として双方向クロスアテンション応答を用い、追加のモデル介入なしに、トークン認識損失を動的に再重み付けし、クロスモーダル層にわたる勾配をスケーリングする。(ii) 選好保存型モダリティ認識再重み付け(報酬の調整):我々は事前定義された重みを選好事前情報として保持し、ウォームアップ後に分岐固有の報酬勾配相互作用を残差補正として用いる。これにより、支配的な報酬が弱いながらも不可欠な目的を抑制することなく、変化する競合を解決する。広範な実験により、強力なRLベースラインと比較して、モダリティ品質、意味的一貫性、音声・映像同期における一貫した改善が示される。アブレーションとメカニズム解析により、適応的更新ルーティングと報酬調整の相補的な利点がさらに検証される。
One-sentence Summary
Researchers from Tencent Video and The University of Hong Kong propose Adaptive Reward Routing, a method that jointly adapts update locations and reward coordination during forward-process RL (DiffusionNFT) for joint audio-video diffusion models via cross-modal influence-guided routing and preference-preserving modality-aware reweighting, thereby improving modality quality, semantic consistency, and audio-video synchronization over strong RL baselines.
Key Contributions
- Adaptive Reward Routing is a dynamic credit-assignment method for multi-reward reinforcement learning in joint audio-video diffusion models that adapts both where reward-based updates are applied and how competing reward signals are coordinated during forward-process RL.
- The method introduces cross-modal influence-guided routing, which uses bidirectional cross-attention responses to dynamically reweight token-aware losses and scale gradients across crossmodal layers, and preference-preserving modality-aware reweighting, which keeps predefined reward weights as priors and adds branch-specific reward-gradient corrections after warm-up.
- Experiments with dual-stream LTX and unified JavisDiT++ backbones show consistent improvements in modality quality, semantic consistency, and audio-video synchronization over strong RL baselines, while ablations and mechanism analyses validate the complementary benefit of adaptive update routing and reward coordination.
Introduction
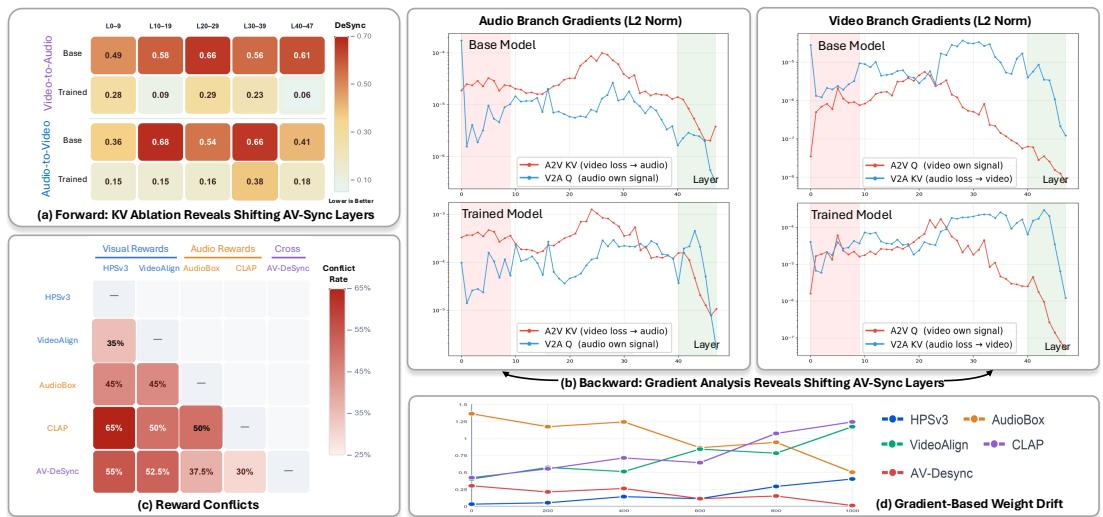
The authors address post-training of joint audio-video diffusion models, where generated content must simultaneously satisfy modality-specific quality, cross-modal semantic alignment, and temporal synchronization. Reward-guided diffusion RL is appealing because multiple reward signals can express these requirements, but prior work relies on static update routing or fixed reward weights that become stale as the model evolves and reward conflicts shift. The authors propose Adaptive Reward Routing, which dynamically localizes reward-driven updates using bidirectional cross-attention responses and adapts reward coordination as residual corrections to user-defined preference weights. Experiments show consistent improvements in modality quality, semantic alignment, and audio-video synchronization across different backbones.
Method
The authors propose Adaptive Reward Routing, a forward-process reinforcement learning framework designed for the reward-guided post-training of joint audio-video diffusion models. This method addresses multi-modal and multi-reward optimization by dynamically adapting both reward priorities and routing locations.
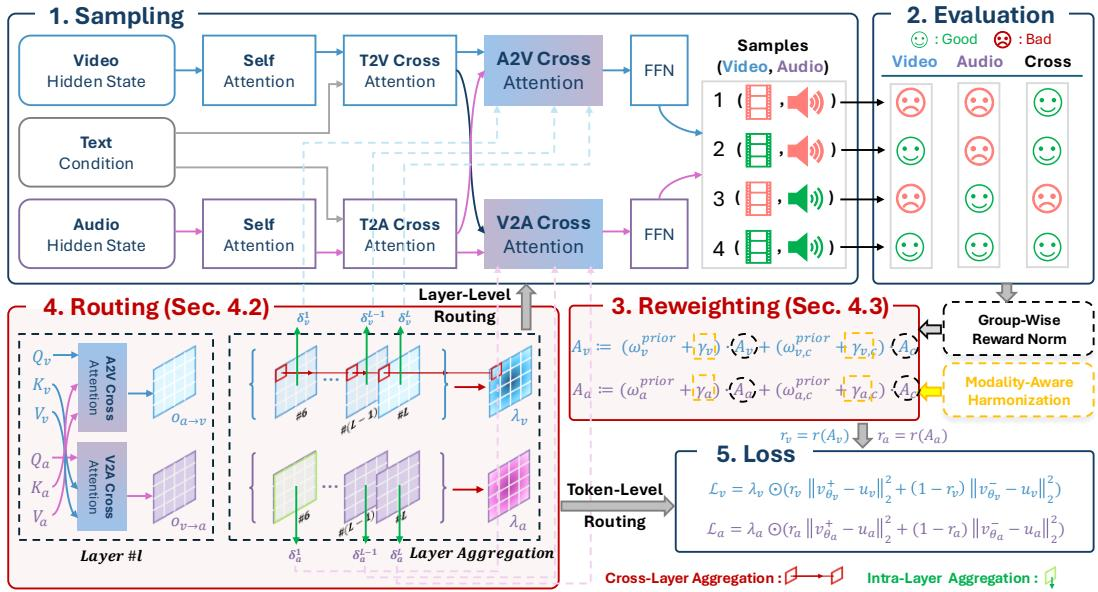
The overall pipeline consists of five sequential stages: sampling, evaluation, reweighting, routing, and loss computation. During the sampling phase, the base model processes separate audio and video streams under a shared timestep. These streams exchange information through bidirectional cross-attention mechanisms, specifically audio-to-video and video-to-audio pathways, allowing the model to predict joint velocity fields. The generated samples are then evaluated using a suite of video, audio, and cross-modal rewards.
To effectively combine these diverse rewards, the framework employs a Preference-Preserving Modality-Aware Reweighting module. Instead of relying solely on predefined static weights or purely gradient-based coefficients, the authors combine both approaches. Each reward is probed through its corresponding modality branch. After an initial warm-up phase, a smoothed conflict-aware coefficient provides a residual correction to the prior weights. This ensures that the prior preferences establish a nonzero floor, while the residual term dynamically adapts to current gradient conflicts. The reweighted rewards are aggregated to compute a separate advantage Am for each modality branch m∈{v,a}.
Following reweighting, the framework applies Cross-Modal Influence-Guided Routing to determine where the optimization updates should act. This routing operates at two distinct levels. At the token level, the model measures the directional influence of cross-modal attention by evaluating the pre-gate response norms. These responses are averaged over intermediate-to-late denoising timesteps and normalized to produce positive loss weights λm,i for individual tokens. At the layer level, the same responses are averaged across tokens to compute a layer score. This score is converted into a soft detachment coefficient that scales the backward gradient of the cross-attention keys and values. Consequently, strongly influential layers retain more gradient flow, while weakly coupled layers are increasingly detached, without altering the forward pass values.
Finally, the training objective integrates these adaptive mechanisms. The token routing weights are applied to a negative-aware loss function:
ℓm,i=rmwm++ε∥vθ,m,i+−um,i∥22+(1−rm)wm−+ε∥vθ,m,i−−um,i∥22where rm is the optimality probability derived from the branch advantage, and wm± represents the detached mean absolute residual of the corresponding policy. The final loss combines the policy losses from both the audio and video branches and regularizes them toward a fixed reference policy using a Kullback-Leibler divergence term. This comprehensive design ensures that the optimization process respects user preferences while dynamically resolving multi-modal conflicts.
Experiment
The experiments evaluate adaptive reward routing on LTX-2 and LTX-2.3 audio-video diffusion backbones using a VGGSound-derived training set and the JavisBench benchmark. The main results show that the proposed method improves audio-video quality, text consistency, cross-modal consistency, and synchronization more effectively than fixed reward coordination, conflict-aware aggregation, and static multimodal routing baselines. Ablations confirm that token-level and layer-level routing are complementary, and that preference-preserving reward coordination addresses distinct failure modes. Additional validation demonstrates that the cross-modal influence proxy reliably identifies functionally important layers and tokens, while a frozen routing map becomes stale during training.
Under the reported LTX-2 comparisons, the proposed method improves substantially over the base model and existing baselines across visual quality, audio quality, text alignment, audio-visual consistency, and synchronization. GDPO and MARBLE offer partial gains but can sacrifice synchronization or text alignment. The complete model achieves the strongest overall balance, with leading scores across the reported metrics and the lowest desynchronization score. The proposed method attains the highest visual quality, audio quality, text consistency, audio-visual consistency, and JavisScore among the compared LTX-2 configurations, while also achieving the lowest desynchronization score. GDPO alone improves visual quality relative to the base model but increases desynchronization, showing that reward optimization without the full approach can sacrifice audio-visual timing. OmniNFT substantially improves audio-visual consistency and synchronization over earlier baselines, and the proposed method further improves these alignment metrics and overall quality.
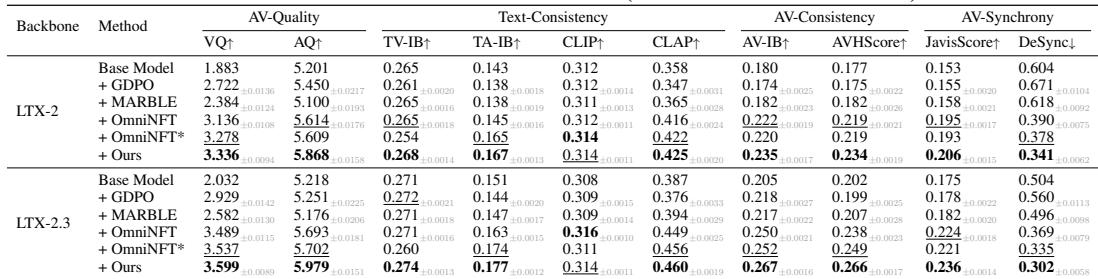
In the LTX-2 backbone ablation, combining token weighting and layer scaling yields the strongest routing-only configuration, improving audiovisual quality, semantic consistency, and synchronization while reducing desynchronization. The isolated reward-coordination chain shows that branch-aware balancing, residual mixing, and warm-up progressively improve overall balance, with warm-up notably raising audio quality and lowering desync. Routing and weighting address complementary failure modes, and the complete model performs best overall. Token weighting and layer scaling are complementary: their combination produces the strongest routing-only results across quality, consistency, and synchronization metrics. Among isolated reward-coordination variants, adding warm-up to branch-aware balancing and residual mixing achieves the best audio quality and lowest desynchronization, though intermediate gains are not monotonic across every metric.
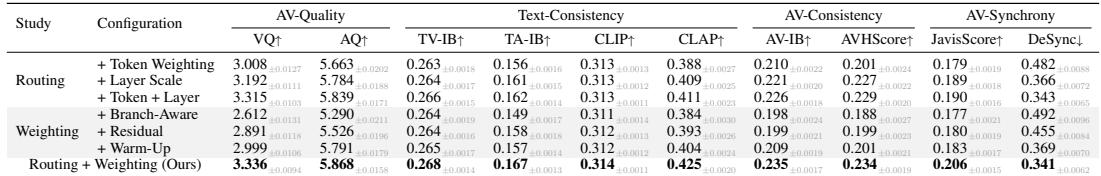
The experiments evaluate the proposed method against LTX-2 baselines and ablations, showing consistent improvements in visual quality, audio quality, text alignment, audio-visual consistency, and synchronization while achieving the lowest desynchronization score. Baseline methods such as GDPO and MARBLE offer partial gains but can sacrifice synchronization or text alignment, and OmniNFT improves consistency and synchronization but remains below the complete model. Ablations indicate that token weighting and layer scaling are complementary for routing, while branch-aware balancing, residual mixing, and warm-up progressively improve overall balance, with warm-up especially raising audio quality and reducing desynchronization.