Command Palette
Search for a command to run...
WanPE:現代のテキスト動画生成のための映画的プロンプト強化に向けて
WanPE:現代のテキスト動画生成のための映画的プロンプト強化に向けて
概要
動画生成は、映画的な脚本をテキスト空間で執筆することから始まり、その後ピクセルとして具現化される。現代の動画生成器が30秒規模に拡張され、複雑な条件に忠実に従うようになるにつれて、テキストプロンプトが制作を大きく方向付け、マルチショットのシーケンスにわたって動作、カメラ軌道、照明、音響がどのように展開するかを計画する。本論文では、105万本の実世界動画で学習された397Bパラメータのプロンプト強化モデルWanPEを提案する。WanPEは、動画に基づく逆構築(video-grounded reverse construction)によってショットレベルの映画的計画を定式化し、Semantic-Consistency GRPO(SC-GRPO)を用いて、ショット間および時間経過にわたってユーザ要件を忠実に保持する。この能力をベンチマークするために、意図の粒度が異なる5秒から30秒の長さを対象とし、約11K件のブラインド一対比較評価によって裏付けられた人手注釈付きテストベッドWanPEvalを構築した。Wan3.0の動画生成器を駆動する際、WanPE-397Bは生のユーザプロンプトに対する人間の選好を5〜15秒では10.66〜18.84ポイント向上させ、30秒のアリーナでは50.86ポイントという劇的な向上をもたらす。アブレーション研究により、逆構築は順方向の書き換えよりも明確に優れており、SC-GRPOはモデル規模にわたって意味的忠実性を頑健に保持することが示された。最終的にWanPEは、5〜15秒では評価したすべての商用サービスを上回り、30秒ではSeedance 2.5と競合する性能を維持する。
One-sentence Summary
Researchers from Nanjing University, Wan Team, Alibaba Group, and colleagues propose WanPE, a 397B-parameter prompt enhancement model trained on 1.05M real-world videos to generate shot-level cinematic plans through video-grounded reverse construction and Semantic-Consistency GRPO, which on the WanPEval benchmark improves Wan3.0 preference over raw prompts by 10.66 to 18.84 points at 5-15 seconds and by 50.86 points at 30 seconds.
Key Contributions
- The paper presents WanPE, a 397B-parameter prompt enhancement model trained on 1.05M real-world videos, reframing prompt enhancement as scalable cinematic planning that orchestrates actions, camera choreography, audio, and narrative across shots and time before pixel rendering.
- The approach learns realized cinematic structure through video-grounded reverse construction and applies Semantic-Consistency GRPO to preserve user requirements across shots; ablations show reverse construction outperforms forward rewriting and SC-GRPO improves semantic consistency by 18.6 to 23.3 points across model scales.
- The paper introduces WanPEval, a human-annotated benchmark covering 5 to 30 second generations with about 11K blind pairwise assessments. When powering Wan3.0's video generator, WanPE-397B improves human preference over raw user prompts by 10.66 to 18.84 points at 5 to 15 seconds and 50.86 points at 30 seconds, transfers across downstream video generators, and leads all evaluated commercial offerings at 5 to 15 seconds while remaining competitive with Seedance 2.5 at 30 seconds.
Introduction
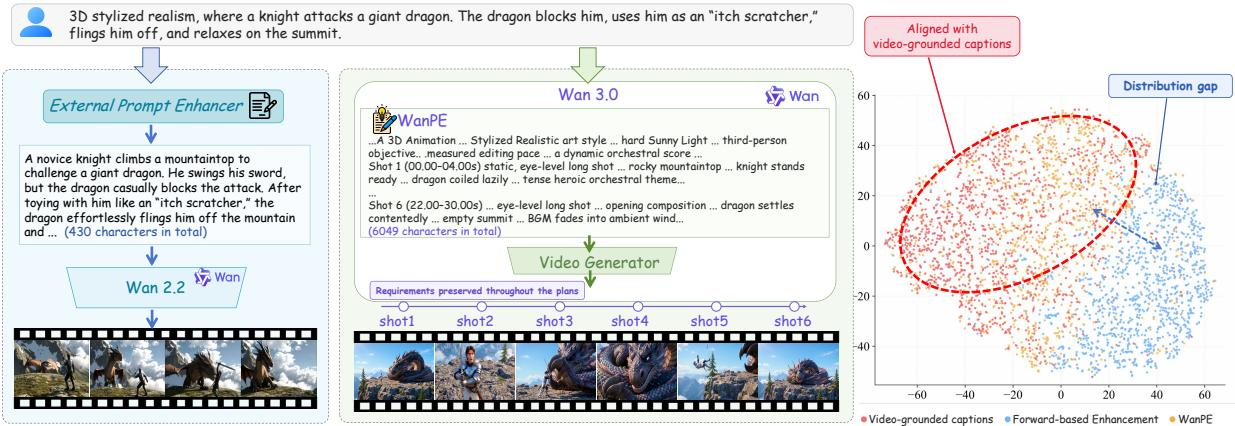
Recent text-to-video systems such as Wan3.0 and Seedance 2.5 can now generate up to 30 seconds of cinematic-quality video, which shifts prompt enhancement from cosmetic detail enrichment toward full production planning across actions, camera work, lighting, dialogue, sound, and shot transitions. Prior enhancers mostly rely on forward rewriting from short user requests into richer descriptions, but this creates a training-inference mismatch with video-grounded captions and often fails to preserve user requirements consistently across a multi-shot plan. The authors introduce WanPE, a cinematic planning prompt enhancer trained on 1.05 million real-world videos. Instead of forward rewriting, WanPE uses reverse supervision by deriving hierarchical cinematic conditions from videos and reconstructing compatible user requests, then applies SC-GRPO with a nine-dimensional reward to reduce omissions, alterations, binding errors, and temporal inconsistencies. The approach is evaluated with 4B to 397B model variants on WanPEval, a human-annotated benchmark spanning 5 to 30 second generation tasks.
Dataset
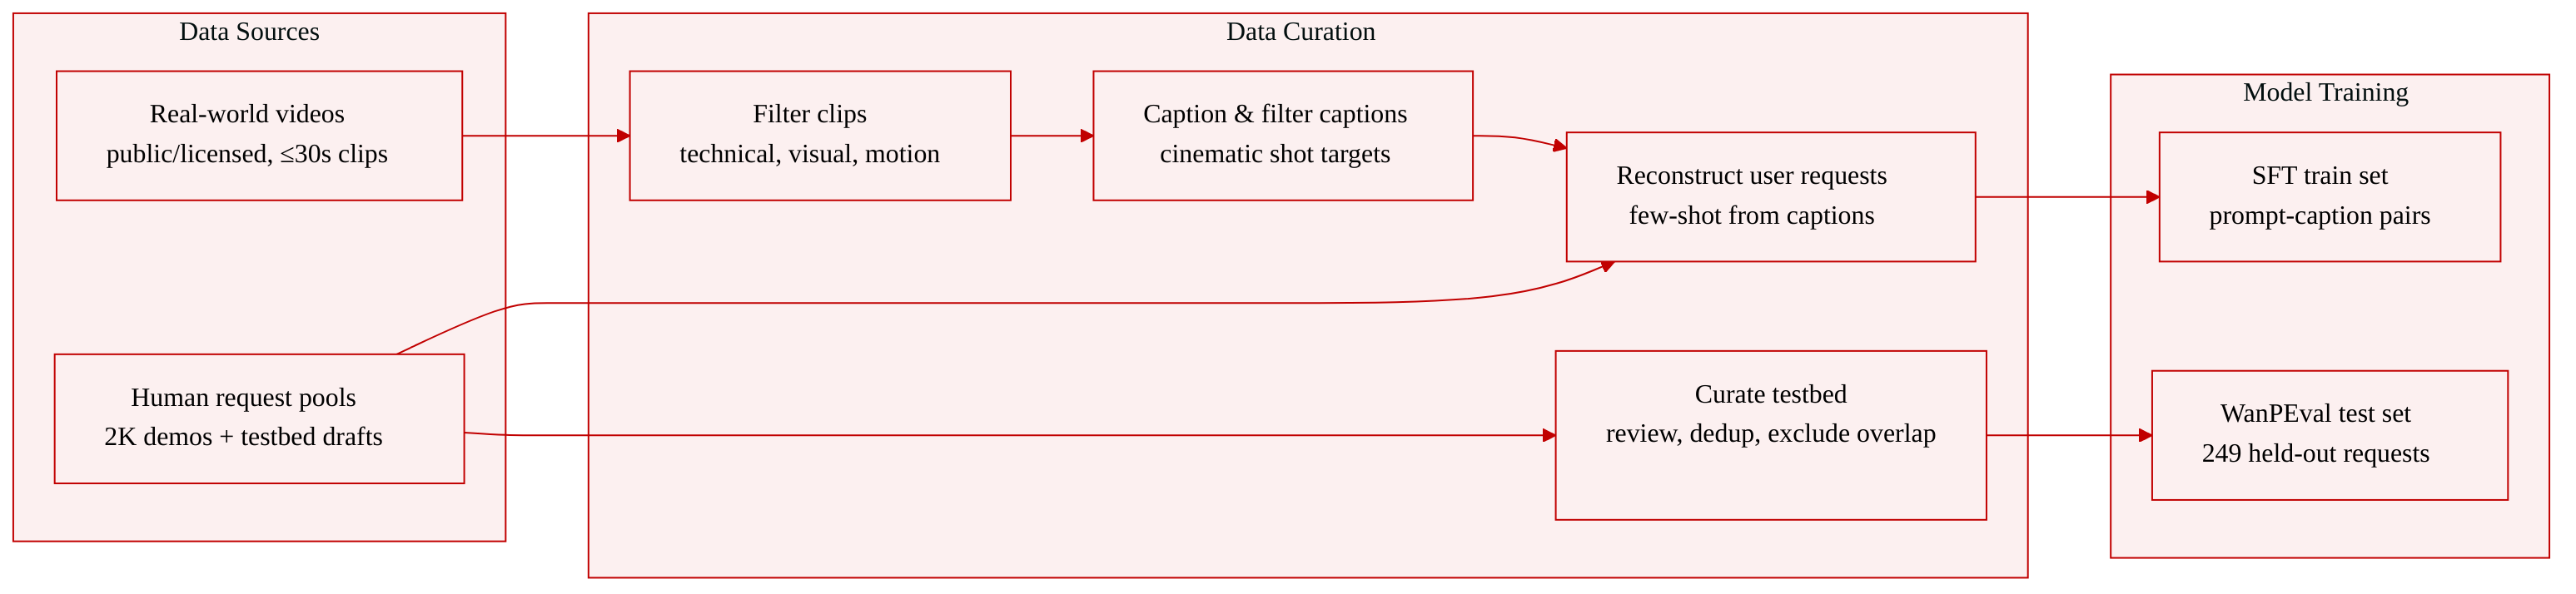
The authors use two dataset components: a video-grounded supervised fine-tuning set and a human-annotated evaluation testbed.
Video-grounded SFT dataset
- Sources and scale: The authors collect real-world videos that are publicly available or licensed. Long-form videos are segmented into clips of at most 30 seconds and filtered through multiple stages for technical validity, visual quality, and motion quality. After filtering, the dataset contains about 1.05M clips spanning ten content dimensions.
- Captioning and metadata construction: A multimodal video captioner processes each curated clip with category-specific instructions. It produces a cinematic target with a video-level summary and temporally ordered shot-level descriptions with timestamps. Shot descriptions can include composition, subjects, actions, lighting, camera movement, transitions, dialogue, music, and sound effects.
- Caption filtering: Captions are retained only if they pass checks for structural completeness, timestamp validity, and consistency with the source video.
- User-request reconstruction: For each video-grounded caption target, the authors reconstruct a natural user request via few-shot prompting with GPT-5.4. Demonstrations are sampled from a pool of 2K human-written requests across ten content categories, using five demonstrations per example. The reconstructed request is constrained to contain only requirements supported by the caption, preserving semantic compatibility.
- Usage: The resulting prompt-caption pairs form the SFT dataset. The prompt enhancer is fine-tuned to maximize the likelihood of each cinematic target given its reconstructed user request. The excerpt does not report train/dev/test splits or mixture ratios for this SFT stage.
WanPEval testbed
- Sources and scale: Human annotators write practical text-to-video requests across diverse topics, stratified by duration from 5 to 30 seconds and by granularity from high-level intents to detailed shot-level instructions. The curated testbed contains 249 requests.
- Curation rules: Requests are reviewed for semantic clarity, internal consistency, and temporal feasibility. Duplicates are removed, and requests that overlap with SFT or SC-GRPO training data are excluded.
- Usage: WanPEval is a held-out testbed used for text-level semantic evaluation and expert video evaluation. Each method generates one video per request, and the authors apply a semantic consistency reward plus anonymous pairwise human preference evaluation.
Method
WanPE is a prompt enhancement policy πθ placed before a text-to-video generator Gϕ. The authors formalize the role of WanPE as follows. Given a natural-language user request x∼pu, the enhancer produces a textual cinematic condition
y∼πθ(⋅∣x),and the video generator uses y to synthesize a video
v^∼Gϕ(⋅∣y).A valid condition y must preserve all semantic and instructional constraints in x. The set of valid conditions is defined as
Ysem(x)={y∣c(y)=1, ∀c∈C(x)},where C(x) is the set of user-specified constraints and c(y)=1 indicates that y satisfies constraint c without omission, alteration, or contradiction.
The authors further require the enhancer output to align with the conditioning distribution of the video generator. Since Gϕ is trained on real-world videos paired with video-grounded captions, the target distribution is the video-grounded caption distribution pvg restricted to semantically valid conditions:
p∗(y∣x)=Z(x)pvg(y)I[y∈Ysem(x)].The training objective is to minimize the KL divergence to this target distribution over user prompts:
θ∗=argθminEx∼pu[DKL(p∗(⋅∣x)∥πθ(⋅∣x))].This formulation captures two requirements that are central to the WanPE method: semantic preservation of user requirements and distributional alignment with video-grounded captions. To exploit the longer conditioning capacity of modern video generators, WanPE organizes textual conditions as hierarchical cinematic plans containing a video-level summary and temporally ordered shot descriptions.
Video-Grounded Supervised Fine-Tuning
The first training stage is supervised fine-tuning on prompt-condition pairs constructed in reverse order. A conventional approach would start from a user request x and enrich it into a cinematic description y. However, the authors argue that this makes the target distribution follow the rewriting procedure rather than the video-grounded caption distribution pvg.
WanPE therefore reverses the pair-construction process: it first obtains y by captioning a real-world video, and then derives a compatible user request x from y.
For real-world video collection, long-form videos are segmented into clips of at most 30 seconds and filtered for technical validity, visual quality, and motion quality. For each curated video clip vi, a multimodal video captioner fcap produces a cinematic target
yi=fcap(vi;si),where si is a category-specific captioning instruction. The resulting target yi describes the video hierarchically, with a video-level summary and temporally ordered shot-level descriptions with timestamps. Each shot specifies composition, subjects, actions, lighting, camera movement, transitions, dialogue, music, sound effects, and their progression over time. Captions are retained only if they pass structural completeness, timestamp validity, and source-video consistency checks.
To reconstruct a natural user request xi from a video-grounded target yi, WanPE uses an LLM with few-shot prompting. The demonstrations are sampled from a pool of human-written requests across content categories. Formally,
xi=fLM(yi;Ei),where Ei contains sampled demonstrations. The reconstruction prompt requires xi to contain only requirements supported by yi, ensuring that yi∈Ysem(xi), while the demonstrations guide the language and specificity toward natural user requests.
The resulting SFT dataset consists of pairs {(xi,yi)}i=1N. WanPE finetunes the prompt enhancer by minimizing the negative log-likelihood of each video-grounded cinematic condition given its reconstructed user request:
LSFT(θ)=−N1i=1∑Nlogπθ(yi∣xi).This stage teaches the enhancer to transform natural user requests into video-grounded cinematic plans that capture the joint organization of elements across shots and time.
Semantic-Consistency GRPO
The second stage strengthens long-range semantic fidelity through Semantic-Consistency GRPO, or SC-GRPO. This stage applies group relative policy optimization with a semantic-consistency reward that penalizes omissions, alterations, incorrect subject-action-dialogue bindings, and temporal inconsistencies across shots.
For training data construction, human annotators write text-to-video prompts for videos up to 30 seconds. Videos are generated with the Wan3.0 generator conditioned on outputs from the SFT enhancer. Annotators identify prompts whose generated videos do not adequately realize the requested content. These challenging cases are combined with diverse human-written prompts to form the SC-GRPO training set.
The semantic reward uses Qwen3.7-Max as a text-only evaluator. Given a user request x and a generated condition y, it evaluates whether y preserves the constraints in C(x) across nine dimensions: style, subjects, actions, dialogue, sound, camera, lighting, spatial relations, and scene. The evaluator penalizes omitted, weakened, altered, or contradictory requirements, incorrect subject-attribute and speaker-dialogue bindings, action and shot ordering errors, and cross-shot conflicts. Semantically equivalent paraphrases and compatible elaborations are accepted.
For policy optimization, WanPE samples G conditions from the current policy for each prompt and standardizes their rewards into group-relative advantages A^g. The optimization objective is
JSC−GRPO(θ)=EG1g=1∑GTg1t=1∑Tg(min{ρg,tA^g,clip(ρg,t,1−ϵ,1+ϵ)A^g}−βKg,t),where Tg is the output length, ρg,t is the probability ratio between the current and old policies, and Kg,t is a KL penalty relative to the SFT reference. This objective encourages the enhancer to produce conditions with higher semantic consistency while remaining close to the reference distribution learned during SFT.
Experiment
The evaluation uses WanPEval, a human-annotated benchmark covering diverse durations and request granularities, with expert pairwise video preference judgments and Bradley-Terry scoring. Overall comparisons show WanPE improves downstream video quality over no prompt enhancement and leading systems, with benefits growing as generation duration increases. Ablations indicate reverse-constructed video-grounded supervision outperforms forward rewriting and forward-target SFT, and WanPE's cinematic plans transfer to other generators after format adaptation. SC-GRPO further improves semantic consistency and downstream preference across model sizes.
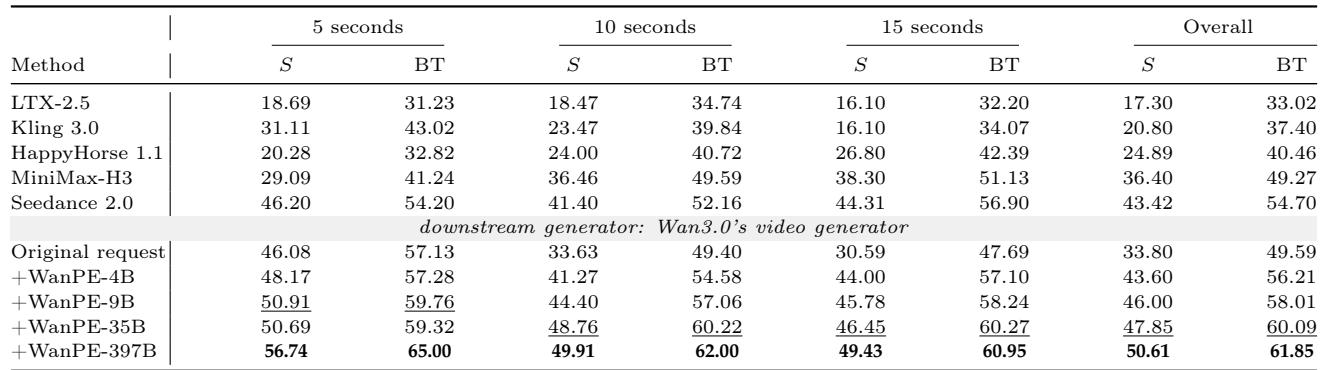
WanPE-397B ranks first in both expert preference and Bradley-Terry scores across the 5, 10, and 15 second durations. Seedance 2.0 is the strongest non-WanPE system in the comparison, while LTX-2.5 and Kling 3.0 receive substantially lower scores overall. WanPE-397B leads all reported systems on both metrics at every duration in the 5 to 15 second subset. Seedance 2.0 is the strongest competitor among the listed baselines, with a clear overall lead over MiniMax-H3. LTX-2.5 records the lowest overall expert preference and Bradley-Terry scores among the compared systems.
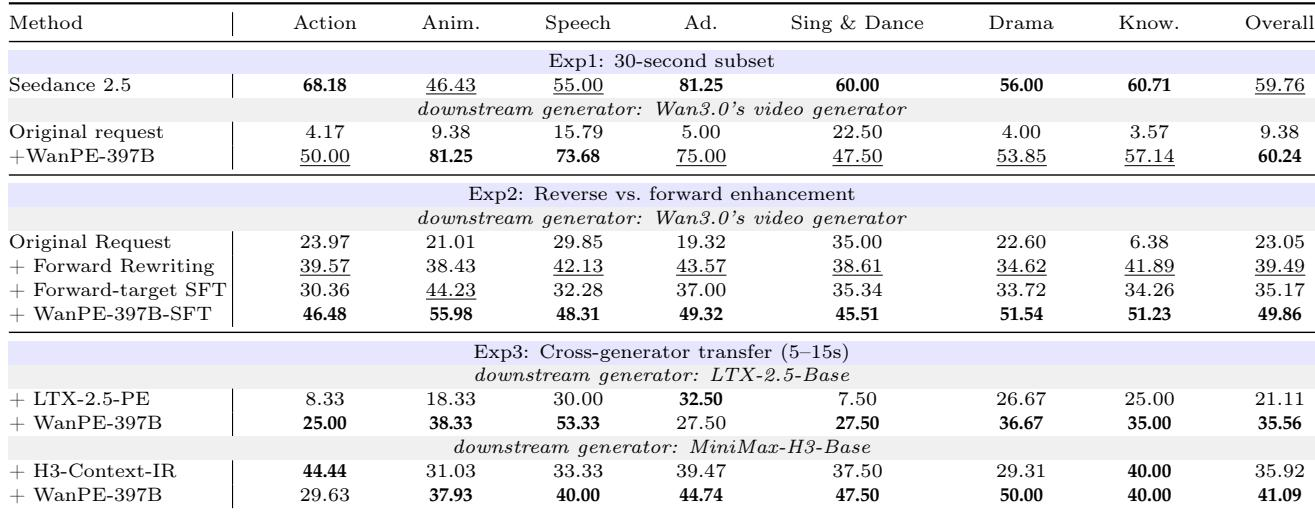
WanPE-397B is competitive with Seedance 2.5 on the 30-second subset, with a large advantage over unenhanced requests and particularly strong animation and speech scores. Reverse-constructed video-grounded supervision clearly outperforms forward rewriting and forward-target SFT, leading across all content categories. Format-adapted WanPE-397B also tops native enhancers when transferred to LTX-2.5 and MiniMax-H3. On the 30-second subset, WanPE-397B slightly edges Seedance 2.5 overall and improves dramatically over the original-request baseline. WanPE-397B leads Seedance 2.5 on animation and speech, while Seedance 2.5 remains stronger on action and singing and dance. Video-grounded reverse-constructed supervision outperforms forward rewriting by a wide margin and ranks first in all seven content categories. Format-adapted WanPE-397B surpasses native prompt enhancers on both LTX-2.5 and MiniMax-H3, with a larger boost on LTX-2.5.
SC-GRPO improves semantic consistency over the SFT baseline at every evaluated duration, with the largest gain at 5 seconds, and substantially raises perfect-output rates while cutting failures. These improvements transfer to downstream video generation, where expert preference increases from 42.70 to 49.69, with gains across all seven content categories. The strongest downstream benefits appear in knowledge, singing and dance, and speech. SC-GRPO adds about 15 to 25 points of semantic consistency over the SFT baseline across evaluated durations, with the largest gain at 5 seconds. Relative to the SFT baseline, SC-GRPO raises perfect outputs by roughly 32 points and lowers failures by roughly 29 points. SC-GRPO improves downstream expert preference across all content categories, with larger gains in knowledge, singing and dance, and speech.
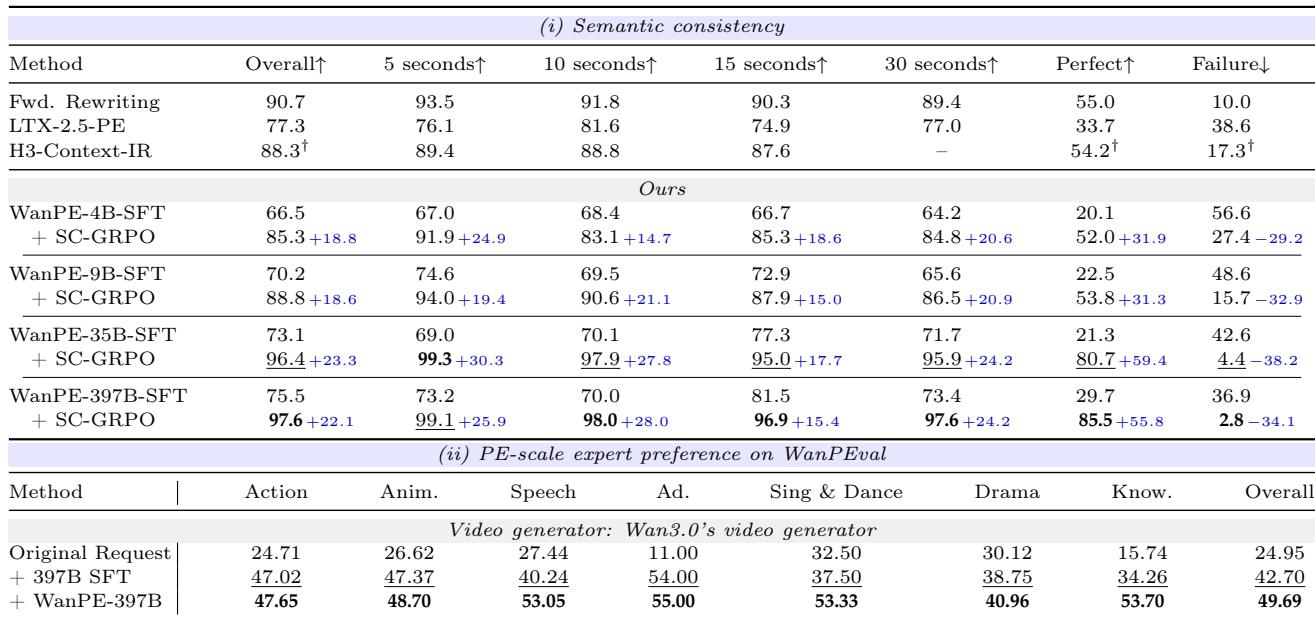
The experiments compare WanPE-397B with baseline prompt enhancers and video generation systems across 5, 10, 15, and 30 second durations, and evaluate SC-GRPO against an SFT baseline. WanPE-397B leads all compared systems on 5 to 15 second outputs and is competitive with Seedance 2.5 on 30 second outputs, with video-grounded reverse-constructed supervision outperforming forward rewriting and transferring well to LTX-2.5 and MiniMax-H3. SC-GRPO improves semantic consistency and downstream video generation quality over SFT across all durations, with the largest gains in knowledge, singing and dance, and speech.