Command Palette
Search for a command to run...
OMNIVCHAT: ネイティブ音声・映像対話の合成・ベンチマーク・訓練
OMNIVCHAT: ネイティブ音声・映像対話の合成・ベンチマーク・訓練
概要
我々はOmniVChat(Omni Video Chat)を、ユーザとオムニモデルとの間のネイティブな音声・映像対話のタスクとして定義する。OmniVChatでは、オムニモデルはユーザからの音声と映像を同時に直接受け取り、テキストを返す。ユーザのクエリは音声と映像に埋め込まれており、独立したテキスト質問、外部キャプション、音声認識を伴わない。直接的な音声・映像入力は、知覚的手がかりを保持しながら、外部レイテンシと計算量を削減する。しかし、OmniVChatの研究は、データの入手可能性と評価という2つの制約に直面している。自身のデバイスを使用する人々の記録は乏しい。さらに、良い応答は多くの場合、ユーザの周囲環境、表情、近くの物体を考慮する必要があり、そのような応答は多様な表現で示されうるため、キーワード一致による応答品質の評価は信頼できない。エージェントシステムと映像生成の最近の進歩により、理解を目的とした対話生成が現実的になっており、これは合成対話を訓練と評価に用いることを意味する。そこで我々は、単一ターンおよび複数ターンの音声・映像対話を合成するマルチエージェントデータエンジンであるOmniVChat-Studioを提案する。我々は合成対話を用いて、5つの能力カテゴリにわたりオムニモデルの基本的対話能力を評価するベンチマークOmniVChat-Benchを構築する。また、OmniVChatにおける応答の正確性、効率性、スタイルを同時に目標とする強化学習の報酬設計であるOmniVChat-RLを提案する。合成対話上でQwen3-Omni-InstructをOmniVChat-RLによって訓練すると、OmniVChat-Benchおよび人間が記録したOmniVChat-Bench-Humanの両方で性能が向上する。これらの向上は報酬設計の有効性を裏付け、訓練と評価における実世界の対話への転移を示している。
One-sentence Summary
Researchers from The Chinese University of Hong Kong, Alibaba Group, Shanghai Jiao Tong University, and other institutions propose OmniVChat-Studio, a multi-agent data engine for synthesizing audio-visual dialogues, along with OmniVChat-Bench for evaluating five ability categories and OmniVChat-RL, a reinforcement learning reward design that jointly targets reply correctness, efficiency, and style; training Qwen3-Omni-Instruct with OmniVChat-RL on synthesized dialogues improves its performance on both OmniVChat-Bench and the human-recorded OmniVChat-Bench-Human.
Key Contributions
- The paper introduces OmniVChat-Studio, a multi-agent data engine that synthesizes single-turn and multi-turn native audio-visual dialogues at scale using subcategory configurations and a text corpus, generating data for OmniVChat training and evaluation.
- It presents OmniVChat-Bench, an evaluation benchmark spanning five ability categories and 17 subcategories, with tiered rubrics and large language model scoring that assess whether responses use the user's language and meet progressively harder criteria.
- It proposes OmniVChat-RL, a reinforcement learning reward design that combines rubric-based reply correctness with efficiency and style terms; fine-tuning Qwen3-Omni-Instruct on 5,600 synthetic dialogues raises OmniVChat-Bench from 0.465 to 0.652 and the human-recorded OmniVChat-Bench-Human from 0.402 to 0.632 while reducing mean reply length from 79 to 36 words.
Introduction
The authors introduce OmniVChat, a task in which an omni model directly receives simultaneous audio and video from a user and returns text, without a separate text query, ASR, or captioning pipeline. Direct audio-visual input matters because it reduces external latency and computation while preserving acoustic and visual cues such as prosody, emotion, and facial expression. Prior work is constrained by scarce open-source device-recorded data and by evaluation difficulty, since keyword matching and rule-based methods cannot reliably score rich multimodal replies. As a result, many systems rely on ASR cascades, which add latency, transcription errors, and discard subtle vocal affect. To address these gaps, the authors propose OmniVChat-Studio, a controllable multi-agent data engine for synthesizing native audio-visual dialogues; OmniVChat-Bench, a rubric-based evaluation benchmark; and OmniVChat-RL, a reinforcement learning reward design that jointly targets reply correctness, efficiency, and style. Fine-tuning Qwen3-Omni-Instruct with this reward on synthetic dialogues improves performance on both synthetic and manually recorded benchmarks.
Dataset
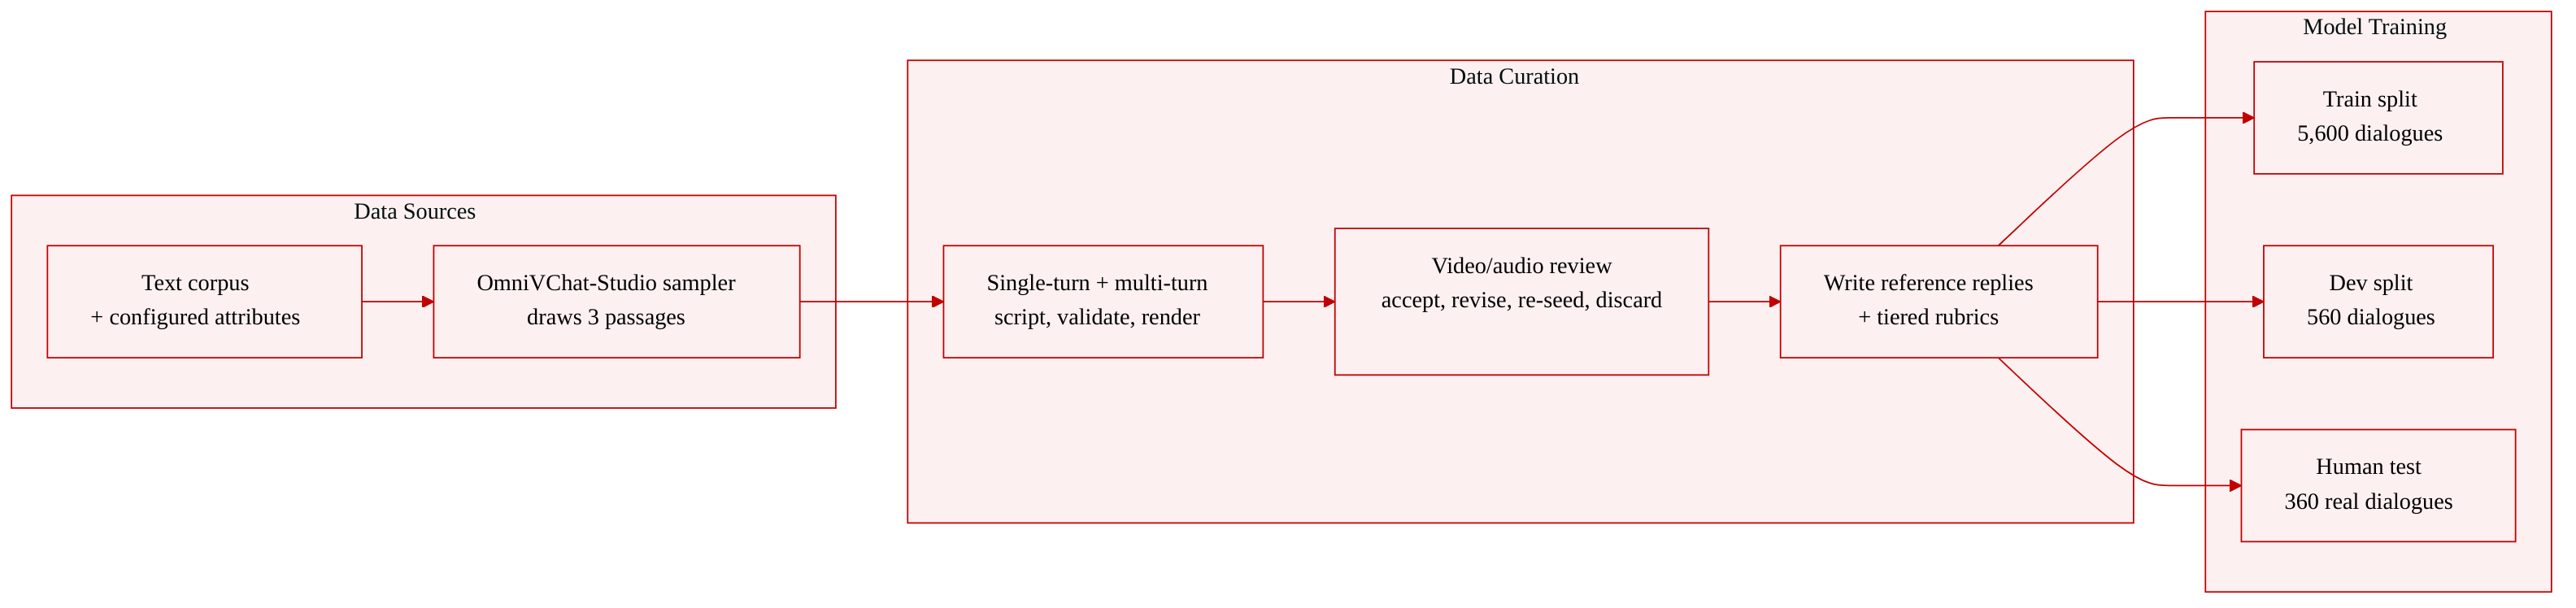
The authors use OmniVChat-Studio, a multi-agent data engine, to synthesize audio-visual dialogue data from a text corpus.
-
Sources and output schema:
- Input: a large text corpus plus configured attribute values; the sampler draws three passages by default.
- Output: rendered audio-visual clips, reference replies, and tiered rubrics for scoring.
- Completed single-turn instances are 1080P clips with 44.1 kHz stereo audio.
-
Benchmark composition:
- OmniVChat-Bench has 2,800 synthesized instances: 2,550 single-turn and 250 multi-turn.
- It covers 17 subcategories, 22 scenario domains, and five ability categories.
- Language split: 1,766 English dialogues (63.1%) and 1,034 Chinese dialogues (36.9%).
-
Dataset subsets:
- OmniVChat-Bench-Train: 5,600 synthesized training dialogues plus 560 development dialogues; development scores select checkpoints.
- OmniVChat-Bench-Human: 360 human-recorded single-turn dialogues, held out for real-world transfer evaluation only.
-
Construction and filtering:
- Agent roles are Director, Renderer, Reviewer, and deterministic Validator; flexible modules are customized per subcategory while fixed modules stay unchanged.
- The single-turn pipeline samples passages, writes and validates scripts, renders clips, reviews videos, and writes grounded reference replies and rubrics.
- Validation checks script format, timing, and rule violations.
- Video Review compares rendered content with the accepted script using captions, seven-part quality reports, and focused Q-A evidence. Runs can be accepted, revised, re-seeded, or discarded.
- Audio checks identify clicks and abrupt endings for repair; human inspectors follow a set procedure to confirm that clips show the intended dialogue.
- Multi-turn construction links earlier clips, audio, or final frames as media placeholders and adds joint planning, plan review, per-turn prompt generation, and prompt review.
-
Ability categories and rubric scoring:
- The five evaluated categories are Dialogue-State and Link Perception, Multimodal Entity Alignment, Model Self-Awareness, Anti-Hallucination, and Emotion Recognition.
- Each instance includes a reference reply and a tiered rubric. Tier 0 checks language without points. Later tiers earn credit only when all earlier tiers are complete.
- OmniVChat-Bench reports Subcategory Mean, which first averages within each of the 17 subcategories and then across them.
- In multi-turn evaluation, all models receive the same earlier clips and reference replies, and only the final reply is scored.
Method
The authors introduce OmniVChat-Studio, a multi-agent data engine that synthesizes native audio-visual dialogue data from a text corpus. The system produces rendered audio-visual clips, corresponding reference replies, and scoring rubrics. It comprises two main subsystems: a single-turn subsystem and a multi-turn subsystem.
As shown in the figure below:
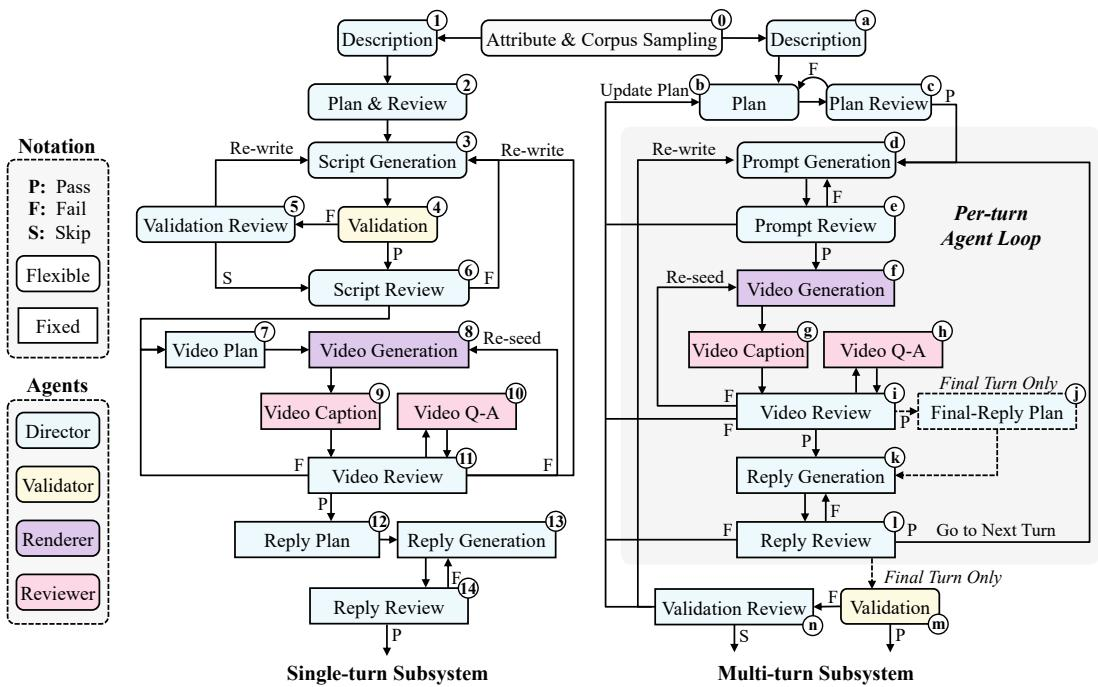
The framework relies on four distinct agents to execute the synthesis pipeline. The Director handles all text-based input and output tasks. The Renderer transforms accepted prompts and media references into synchronized audio-visual clips. The Reviewer examines the rendered content, generates captions and quality reports, and answers focused questions when additional evidence is required. The deterministic Validator checks structured scripts or dialogue records against configured rules, returning either a pass or a list of violations. The architecture distinguishes between Flexible modules, which are customized with subcategory-specific prompts, and Fixed modules, which remain unchanged across all categories.
The single-turn subsystem synthesizes one-turn dialogue data through a sequential pipeline. It begins with Attribute and Corpus Sampling to select attribute values and text passages. The Director then develops a rough storyline and refines the key audio-visual scene details. Script Generation creates a structured, timed script, which is evaluated by the Validator. If violations occur, Validation Review decides on necessary corrections. Once the script is accepted, Video Plan prepares the rendering prompt, and the Renderer executes Video Generation to produce the clip. The Reviewer generates a Video Caption and quality report. Video Review compares the rendered content against the script, optionally triggering Video Q-A for focused evidence. Finally, Reply Plan and Reply Generation produce the reference reply and tiered rubric, which are finalized by Reply Review.
The multi-turn subsystem manages dependencies across sequential turns. Unlike the single-turn flow, it separates the planning phase into Plan and Plan Review to expand the storyline into a joint plan specifying every turn and selecting earlier media references. Instead of a single script generation step, it employs a per-turn agent loop. Prompt Generation writes rendering prompts for each turn using media identifiers as placeholders, followed by Prompt Review to check media links. The loop iterates through video generation, captioning, and review for each turn. Only on the final turn does the system execute the Final-Reply Plan, Validation, and Validation Review to complete the sequence.
To optimize the model's dialogue capabilities, the authors present OmniVChat-RL, a reinforcement learning framework targeting reply correctness, efficiency, and style. The base model is the Thinker component of Qwen3-Omni-30B-A3B-Instruct, trained using Group Sequence Policy Optimization (GSPO). For each input x, the sampling policy draws N replies. The advantage Ai is calculated by subtracting the group mean reward from each reply's total reward. The objective function maximizes:
J(θ)=E[N1i=1∑Nmin(qi(θ)Ai,clip(qi(θ),1−εlo,1+εhi)Ai)]The full-reply probability ratio qi(θ) is normalized by the reply token count to reduce length dependence. The total reward R(y) combines four components:
R(y)=r(y)+λfmtf(y)+λeffe(y)+λstys(y)Here, r(y) is the correctness reward based on the rubric. f(y) is a binary format term ensuring a valid reply structure without thinking tags. The efficiency reward e(y) promotes concise wording. It is derived from the raw efficiency score:
ρ(y)=max{w(y),1}r(y)where w(y) is the counted reply length. The final efficiency reward normalizes ρ(y) within the sampled group, assigning 0 to the lowest value and 1 to the highest. The style reward s(y) is a binary score confirming adherence to natural speech and grammar criteria. The weights are set to λfmt=0.5, λeff=0.1, and λsty=0.5, with correctness weighted at 1.
Experiment
The authors introduce OmniVChat-Bench, a synthetic benchmark with 2,800 single-turn and multi-turn dialogues that evaluates five basic dialogue abilities through tiered rubrics, and OmniVChat-RL trains on a reward combining rubric correctness, style, efficiency, and format. Training improves held-out synthetic and recorded dialogue scores while producing shorter, more efficient, and more style-compliant replies. Compared with released systems and ablations, OmniVChat-RL leads in efficiency and style while maintaining strong correctness, and removing the efficiency or style reward reveals a trade-off between correctness, reply length, and style.
Reported closed-source models show distinct leaders across overall rubric score, recorded human dialogue score, efficiency, and style. Gemini-3.5-Flash leads on average rubric performance, Gemini-3.7-Flash leads on recorded human and efficiency, and Gemini-3.1-Pro leads on style, indicating synthetic rank does not determine recorded human rank. Doubao Seed 2.0 Lite trails on overall and recorded human averages but remains competitive on multi-turn dialogues. Gemini-3.5-Flash has the highest overall mean rubric score among closed-source models, while Gemini-3.7-Flash leads recorded human dialogue scores and credit per thousand words. Gemini-3.1-Pro achieves the highest style pass rate but has a notably lower MSA score, showing style and category ability can diverge. Doubao Seed 2.0 Lite records the lowest overall mean and recorded human score in the closed-source group, yet its multi-turn score is competitive with higher-ranked systems. Efficiency varies widely across closed-source models, with leaders earning substantially more rubric credit per thousand words than lower-efficiency systems. Qwen3.5-Omni-Plus generally falls below the Gemini models on overall mean and recorded human scores but still attains a high style pass rate.
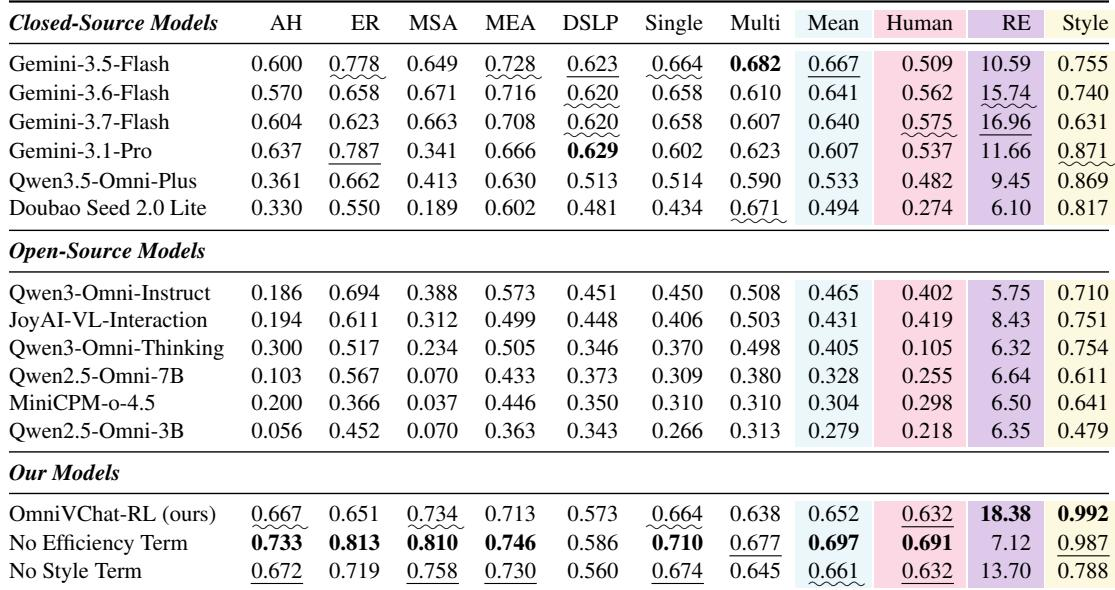
The evaluation compares closed-source models on rubric-based scores, recorded human dialogue quality, efficiency, and style. No single model leads across all dimensions: Gemini-3.5-Flash performs best on overall rubric score, Gemini-3.7-Flash leads on recorded human score and efficiency, and Gemini-3.1-Pro leads on style but shows a lower MSA score, indicating that style and category ability can diverge. Doubao Seed 2.0 Lite trails on overall and recorded human averages yet remains competitive on multi-turn dialogues, while Qwen3.5-Omni-Plus achieves a high style pass rate despite lower overall scores.