Command Palette
Search for a command to run...
個人化正則化PageRankのための加速局所アルゴリズム
個人化正則化PageRankのための加速局所アルゴリズム
Baojian Zhou
概要
局所PageRankアルゴリズムは、グラフサイズに依存しない計算量でスパースな近似を求める。本論文では、正則化付き個人化PageRankに対し、加法的目的精度ε_objを達成する決定論的アルゴリズムを提案し、その局所計算量がŌ(1 / (ρ √α))であることを示す。ここでαは遅延テレポーテーションパラメータ、ρは正則化パラメータである。精度は対数多項式因子としてのみ現れる。この計算量限界は、解の候補やグラフ全体の前処理なしに、発見、近傍の繰り返し走査、数値更新、証明、出力の全工程を包含する。本アルゴリズムは、次数でスケーリングされたボックス制約と質量上限によって制約された加速補正を、正則化連続変形と組み合わせる。同一の漸化式に対する二つのエネルギーが、目的関数の収束と座標を活性化する応答を制御する。選択フローに基づく議論により累積走査体積を抑え、スパース閾値報告機構がその限界を実現する。また、有理数入力に対する有界算術演算の実装についても規定する。第二の乱択アルゴリズムは、サポート安全な閾値バッチを用いる。ブロックコレスキー分解とチェビシェフ多項式に基づく議論によりバッチの深さを抑え、保証付きSDDソルバにより、期待計算量Õ(V_ min{k_, α^{-1/2}})を達成する。ここでk_とV_は最適サポートの濃度と次数体積である。両手法は、対応する加速された次数正規化PPR近似を導く。同時期の2026年9月のCui, Wei, Yangのプレプリントも同様の乱択計算量スケールを達成しているが、我々の主たる差異は、対数多項式のオーバーヘッドのみでSDDオラクルを用いない、決定論的な局所加速にある。
One-sentence Summary
Researchers from Fudan University propose a deterministic local algorithm for regularized personalized PageRank achieving additive accuracy εobj in Oˉ(1/(ρα)) work via regularization continuation and accelerated corrections constrained by a degree-scaled box and mass cap, without SDD oracles or graph-wide preprocessing, and a randomized variant with expected work O~(V∗min{k∗,α−1/2}).
Key Contributions
- A deterministic local algorithm for regularized personalized PageRank achieves additive objective error ε_obj with work Ō(1/(ρ√α)), where α is the teleportation parameter and ρ the regularizer, and the accuracy enters only polylogarithmically; the method requires no graph-wide preprocessing or supplied solution support and includes a bounded-arithmetic implementation for rational inputs.
- A randomized local algorithm uses support-safe threshold batches and certified SDD solves to achieve expected work Õ(V_* min{k_, α^{-1/2}}), where k_ and V_* are the optimal support's cardinality and degree volume, matching the randomized scale of concurrent work without an SDD oracle.
- Both algorithms imply an accelerated degree-normalized PPR approximation through an explicit regularization-bias and objective-error conversion, and the deterministic method provides the principal distinction of deterministic local acceleration with only polylogarithmic overhead.
Introduction
Local personalized PageRank algorithms compute sparse relevance scores without accessing the whole graph, but accelerating them while preserving locality is challenging. Prior work either uses momentum-based updates that can activate vertices far outside the optimal support and incur high-degree scans, or solves a sequence of restricted problems whose cost multiplies with the number of support discoveries. The authors present two new algorithms for regularized personalized PageRank that overcome these obstacles. A deterministic continuation method achieves the accelerated work bound of Õ(1/(ρ√α)) with only polylogarithmic overhead and no need for a nearly-linear SDD oracle. A randomized threshold-batching method attains an expected work bound of Õ(min{1/ρ², 1/(ρ√α)}), adapting to the optimal support size while also providing a Las Vegas certification. Both results translate into a degree-normalized PPR approximation with the same accelerated complexity.
Method
The authors formulate the problem as a regularized PageRank (RPPR) objective on an unweighted, undirected graph. Given a seed distribution s (typically a point source eν), a teleportation parameter α∈(0,1], and a regularization strength ρ>0, the RPPR problem minimizes
Fρ(x)=21⟨x,Qx⟩−⟨b,x⟩+αρ∥D1/2x∥1,where Q=21+αI−21−αD−1/2AD−1/2, b=αD−1/2s, and A,D are the adjacency and degree matrices. The unique minimizer xρ∗ yields a sparse vector whose support volume is at most 1/ρ. The standard personalized PageRank (PPR) vector is π=D1/2x0∗, where x0∗=Q−1b is the unregularized solution. Accuracy is measured either in objective gap Fρ(x)−Fρ(xρ∗)≤εobj or in degree-normalized PPR error ∥D−1/2(x−x0∗)∥∞≤εppr. The algorithms operate under a local access model: they start only with the seed label and can query degrees and adjacency lists of discovered vertices; total work counts all adjacency inspections, degree queries, arithmetic operations, and output words.
The core of the method consists of two complementary local algorithms, both producing a nonnegative vector x satisfying the RPPR objective tolerance and supported inside the optimal support. The deterministic algorithm uses a continuation strategy that halves the regularization parameter across stages. At each stage, a diffuse-source correction problem is solved on an explicit convex set Kr={u:0≤u≤4rω,ω⊤u≤mr}, where ω=D1/21 and mr is the residual mass. An accelerated recurrence, parameterized by a curvature μc=θ2 with θ chosen so that θ2≤α, iterates
ykqkzk+1ξk+1=1+θξk+θzk,=χzk+θyk−θQyk−h+λrω,=ProjKr(qk),=χξk+θzk+1,where χ=1−θ, λr=αr, and h is the current residual source. The projection onto Kr is computed exactly via a finite threshold search on a balanced tree of key densities, enabling sparse updates that touch only the kinetic support and its boundary. A key analytical contribution is a cumulative kinetic volume bound: the total degree volume of all projected iterates over a stage is O(K/r), where K is the number of iterations. Combined with accelerated convergence (K=O(α−1/2log(1/τ))), the total work per stage is O(1/(rα)). Summing over the halving schedule gives the overall deterministic work O(1/(ρα)).
The randomized algorithm adopts a different philosophy: it builds the optimal support incrementally through safe active-set expansion. Starting from the seed, it repeatedly solves the restricted linear system xU=QUU−1(cρ)U on the current active set U (where cρ=b−αρω) and examines the boundary slacks. Any boundary vertex with a sufficiently negative slack is guaranteed to belong to the optimal support (Theorem 7) and is added in a batch. The slack condition is local: for j∈/U, wjU/dj=αρ−2dj1−α∑i∈N(j)∩Uyi, requiring only adjacency scans of U. A local objective certificate (Lemma 9) uses the KKT subgradient to bound the objective gap from the active set and its boundary, without needing the whole graph.
To limit the number of batch expansions, the algorithm employs a threshold ϑ: a vertex is admitted only if its exact residual exceeds ϑ, while all remaining optimal support coordinates have residual at most ϑ. A spectral depth analysis (Theorem 20) shows that after J=O(α−1/2log(1/εobj)) batches, the restricted solution on the discovered face achieves the desired objective accuracy. The analysis uses a block Cholesky decomposition of the optimal support and Chebyshev approximation to separate a rapidly decaying seed contribution from a threshold-induced error. Each face solve is performed by a randomized nearly-linear SDD solver on the supplied principal submatrix, with independent retries to control failure probability. The expected total work is O(V∗min{k∗,α−1/2}), where V∗ and k∗ are the volume and size of the optimal support; this is bounded above by O(1/(ρα)) in the worst case. The algorithm can also return a subsolution satisfying 0≤x≤xρ∗ and 0≤b−Qx≤2αρω.
For the final PPR task, a two-stage completion is used. First, either algorithm computes an RPPR solution with ρ=εppr/3, yielding an approximate support U whose volume is at most 3/εppr. Then the exact principal PPR system QUUuU=bU is solved on that support to the required Euclidean accuracy. Because the support already captures the essential mass, the degree-normalized error between the resulting vector and the true PPR is bounded by εppr. The second stage can use deterministic preconditioned conjugate gradient or a randomized SDD solver, both running in time O(vol(U)/α), preserving the overall O(1/(εpprα)) work bound. All steps are local, require no global preprocessing, and count every adjacency inspection and arithmetic operation explicitly.
Experiment
The paper develops deterministic and randomized local algorithms for regularized PageRank (RPPR) and personalized PageRank (PPR) that operate with only local graph access and no preprocessing. The deterministic method guarantees an objective gap within O(1/(ρα)) work, while the randomized Las Vegas algorithm adapts to the support size and volume, achieving expected work O(V∗min{k∗,α−1/2}). Both approaches produce sparse outputs that satisfy semantic PPR accuracy and can generate ACL-compatible residual certificates or approximate support envelopes for subsequent linear-system solves, with all support admissions deterministically certified.
The comparison shows how local RPPR algorithms trade off work and output guarantees. Earlier methods scale with support size, volume, or internal nonzeros, while the new Algorithm 1 achieves a support-independent bound of Õ(1/(ρ√α)), and Algorithm 2 matches the best accelerated active set bound in expectation, backed by a deterministic continuation theorem. Algorithm 1 is the only method whose work bound Õ(1/(ρ√α)) does not depend on the optimal support size, volume, or internal nonzeros, in contrast to all prior algorithms. Algorithm 2 attains the same Õ(V_* min{k_*, α^{-1/2}}) guarantee as the accelerated active set, but as an expected bound rather than with high probability, and the paper's main distinction is a deterministic continuation proof.
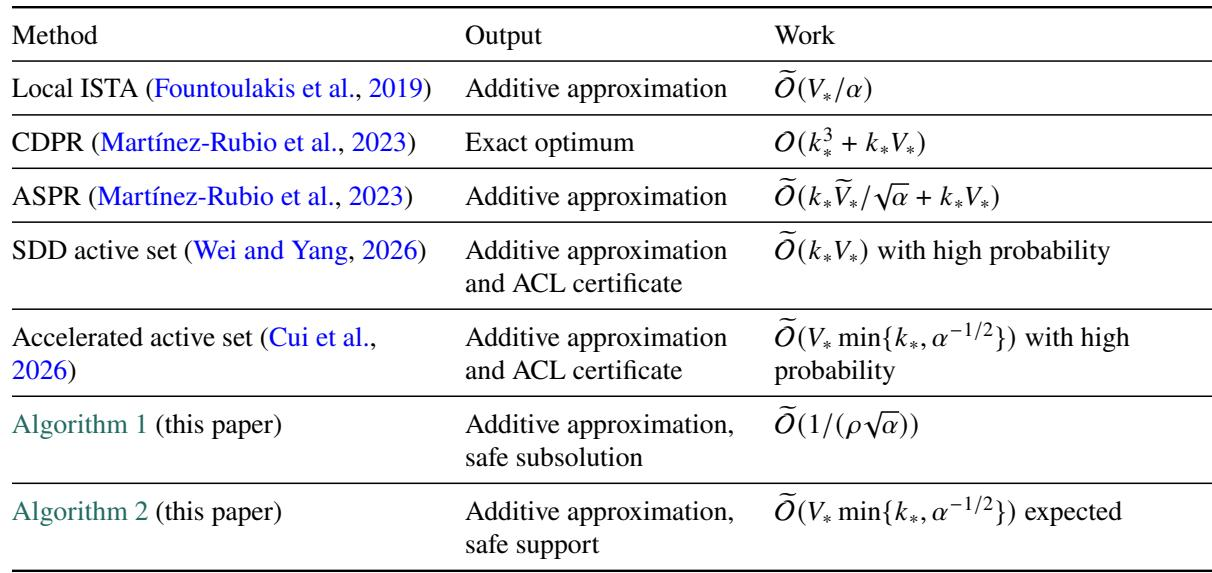
The evaluation compares local RPPR algorithms in terms of their work and output guarantees. Algorithm 1 stands out as the only method whose work bound does not depend on optimal support size, volume, or internal nonzeros, achieving a support-independent guarantee. Algorithm 2 matches the best accelerated active set bound in expectation, with the key contribution being a deterministic continuation proof rather than a high-probability analysis.